
DoomAI Nodes
DoomAI Nodes — ComfyUI pack: Flux1/Flux2/Krea2 samplers, LTX-2.5 and MiniMax H3 video, reference tools, prompt engine, save utilities.
Nodes (40)
Doom Action Prompter
Doom Constructor
A preset shelf for edit prompts — and you can add your own
Masked inpainting for Flux.1 without the plumbing
One loader for full-precision, GGUF, and a second MoE model — the 'wan' is in the name for a reason
Prompt in, latent out, shift handled for you
Flux.1 img2img with step control and a 'dynamic CFG' that isn't quite
Flux.2 edits with up to eight reference images — and the inputs grow as you connect them
Doom Flux2 Sampler
DoomFluxKontextPrompts is Doom Edit Prompts
Get an image's real dimensions — and force them into the divisibility your model needs
A batch image loader with two streams, filters, and three selection modes
One resize node for megapixels, exact sizes, scale, or long/short side
Sort your batch by width, aspect, or index — the routing node for the loader's metadata
Pairing a main image set with a style set
8 steps, CFG 1, fixed shift — the defaults do the work
Up to ten LoRAs, one node, and a master volume knob
The whole LTX-2.5 stack in one loader — diffusion, Gemma, two VAEs, upscaler, and a duration head
First frame + prompt = video with sound, in one node
A rendered markdown sticky note, and a 'Model Links' button that remembers where your files go
Everything MiniMax H3 needs to run
Doom MiniMax H3 Sampler
Doom Multi Prompt Loader
Doom Prompt Builder
Doom Prompt Save
Doom Random Prompt
Get your reference ready without the reference-node zoo
Doom Resolution From MP
The image saver that keeps your output folder from becoming a dump
From frames to an mp4 with sound, in one node
Doom Super Loader
Doom Text Enter
See what your prompt chain is actually outputting
Translate your prompts locally with Tencent's HY-MT models
The prompt vocabulary cheat sheet you keep forgetting to build
Pad an image to Flux's favorite resolution without the math
Get your original canvas back after an outpaint
Build Russian prompts from nine word categories
Twenty ready-made image-to-image commands, one dropdown
The same wordbook, under its old name
DoomAI Nodes
Custom node pack for ComfyUI: image samplers for Flux.1 / Flux.2 / Krea2, video generation for LTX-2.5 and MiniMax H3, reference tools, a prompt engine and save utilities — 40+ nodes, modern V3 API (io.ComfyNode), dark neon theme.
Features
- Modern models out of the box: Flux1 / Flux2 / Krea2 samplers with auto shift by resolution, LTX-2.5 loader + sampler (two-stage pipeline, latent upscale ×2, prompt enhancer, auto duration via the LTX duration head), MiniMax H3 loader + sampler (audio + video).
- All-in-one loaders:
DoomSuperLoader(checkpoint or diffusion model, VAE, up to 3 CLIPs, CLIP Vision, StyleModel, fp8/bf16), GGUF support. - Reference system:
Doom_ReferenceFree— image reference prep with crop, normalize, overlay, text layer, masks, outpaint padding. - Prompt engine: random prompts (wildcards +
lists/), multi-prompt loader, edit presets, builder, constructor, wordbook, prompt saver. - Save tools:
DoomSaveUltimate(reliable counter, date subfolders, PNG metadata, prompt logs, UI preview), video saver with audio. - Theme: category-colored nodes (Loader blue, Sampler purple, Utils green, Prompt amber) with white titles.
Installation
cd ComfyUI/custom_nodes
git clone https://github.com/PeterMikhai/DoomAI_nodes.git
Restart ComfyUI. No extra dependencies — everything runs on ComfyUI's own stack (torch, PIL, aiohttp).
Node list
Doom/Loader
| Node | Description | |---|---| | Doom Super Loader | Universal loader: checkpoint or diffusion model, VAE, up to 3 CLIPs, CLIP Vision, StyleModel, fp8/bf16/GGUF | | Doom Flux1 Loader (GGUF / WAN) | Auto FP/GGUF detection, MoE dual model, GGUF-CLIP | | Doom LoRA Stack | Up to 10 LoRA slots with weights | | Doom LTX Loader | LTX-2.5: diffusion + Gemma 4 CLIP + video VAE + audio VAE + latent upscaler + enhancer Gemma + duration head | | Doom MiniMax H3 Loader | H3: diffusion + Qwen3-VL CLIP + video VAE + audio VAE |
Doom/Sampler
| Node | Description | |---|---| | Doom Flux1 Sampler | Flux.1: prompt → latent, shift by resolution | | Doom Flux2 Sampler | Flux.2 (DiT 16×, schedule by seq_len) | | Doom Flux2 I2I Sampler | img2img / multi-reference (autogrow up to 8 refs, mask) | | Doom Flux1 Inpaint Sampler | Inpaint with noise_mask + concat latent | | Doom Flux1 Sampler Advanced | start/end step, dynamic CFG, denoise | | Doom Krea2 Sampler | Krea2 turbo (8 steps) / RAW, fixed shift 1.15, CFG 1.0 | | Doom LTX Sampler | LTX-2.5 i2v: first frame + prompt → video with sound, latent upscale ×2, prompt enhancer, auto_duration | | Doom MiniMax H3 Sampler | H3: refs + prompt → video + audio (CFG-distilled 1.0) |
Doom/Utils
| Node | Description | |---|---| | Doom Save Ultimate | Save with counter, date subfolders, metadata, prompt logs, UI preview | | Doom Save Video Free | Video encoder with audio (ffmpeg) | | Doom Image Loader / Router / Resize | Image batch load, conditional routing, resize (MP/W×H/crop/pad) | | Doom Get Image Size / Resolution From MP | Sizes and resolution math | | Doom Text Enter / Text Show | Text I/O | | Doom Index Pair Counter | One index → main/style pair | | Doom Reference Free | Reference image prep (JS widget, 4 slots) | | Flux Kontext Pad For Outpaint / Restore And Crop | Outpainting helpers |
Doom/Prompt
| Node | Description |
|---|---|
| Doom Prompt Save | Prompt saving with date, counter, metadata |
| Doom Random Prompt | Wildcards {a|b} + __file__, seed-reproducible |
| Doom Multi Prompt Loader | Sequential / random / shuffle modes |
| Doom Edit Prompts | Presets incl. modern models (H3/LTX/Krea2/Flux) |
| Doom Prompt Builder | Sectional prompt builder |
| Doom Action Prompter / Constructor / Wordbook | RU template tools |
Other
| Node | Description | |---|---| | Doom Markdown Note | In-canvas markdown notes with model-preset templates | | Doom Translate | Text translation | | Doom Save Video Free | ffmpeg video save with audio |
Workflows
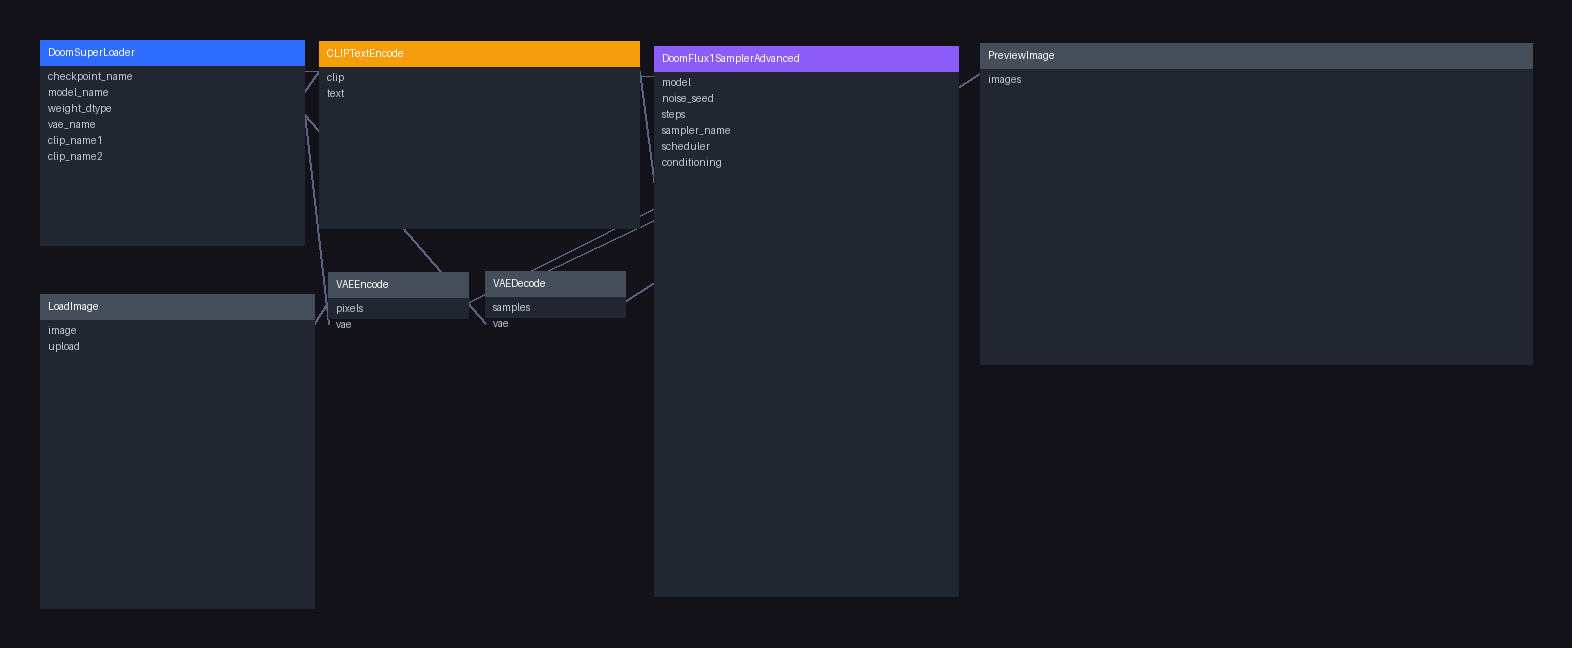
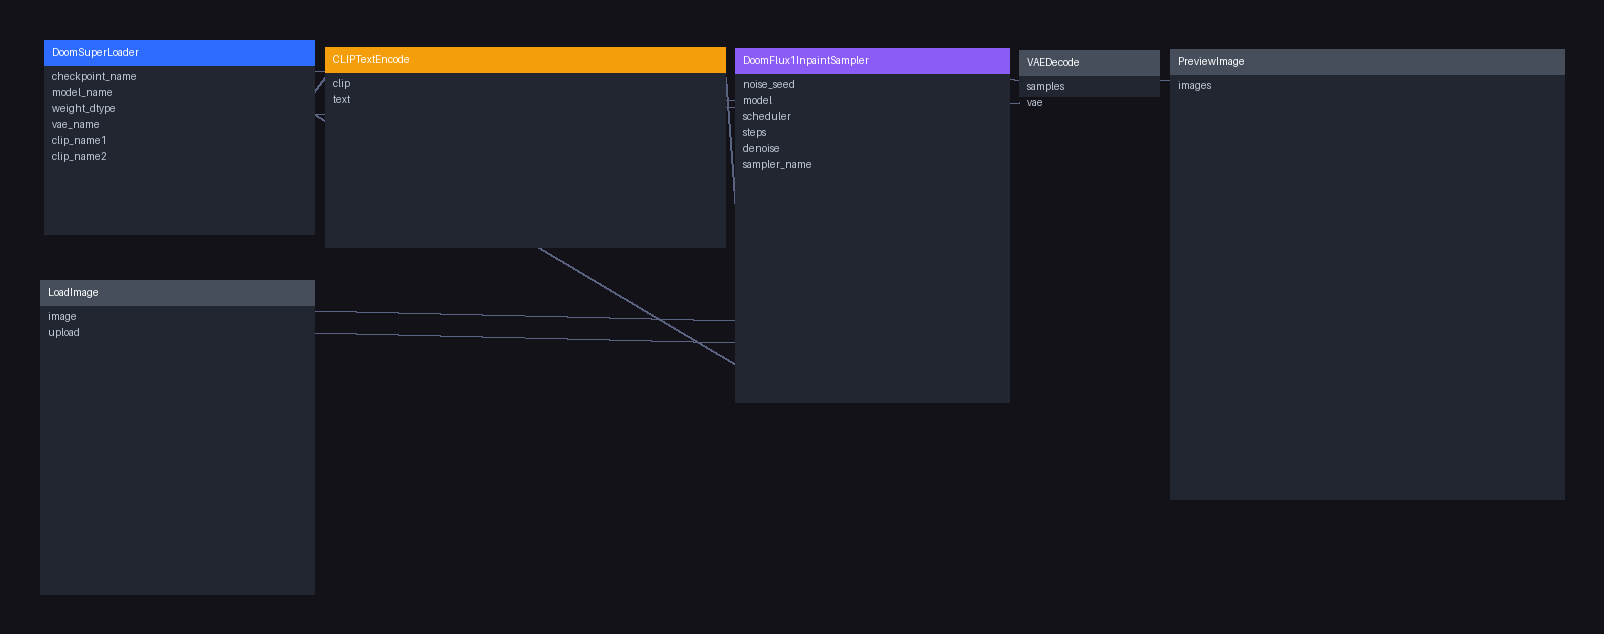
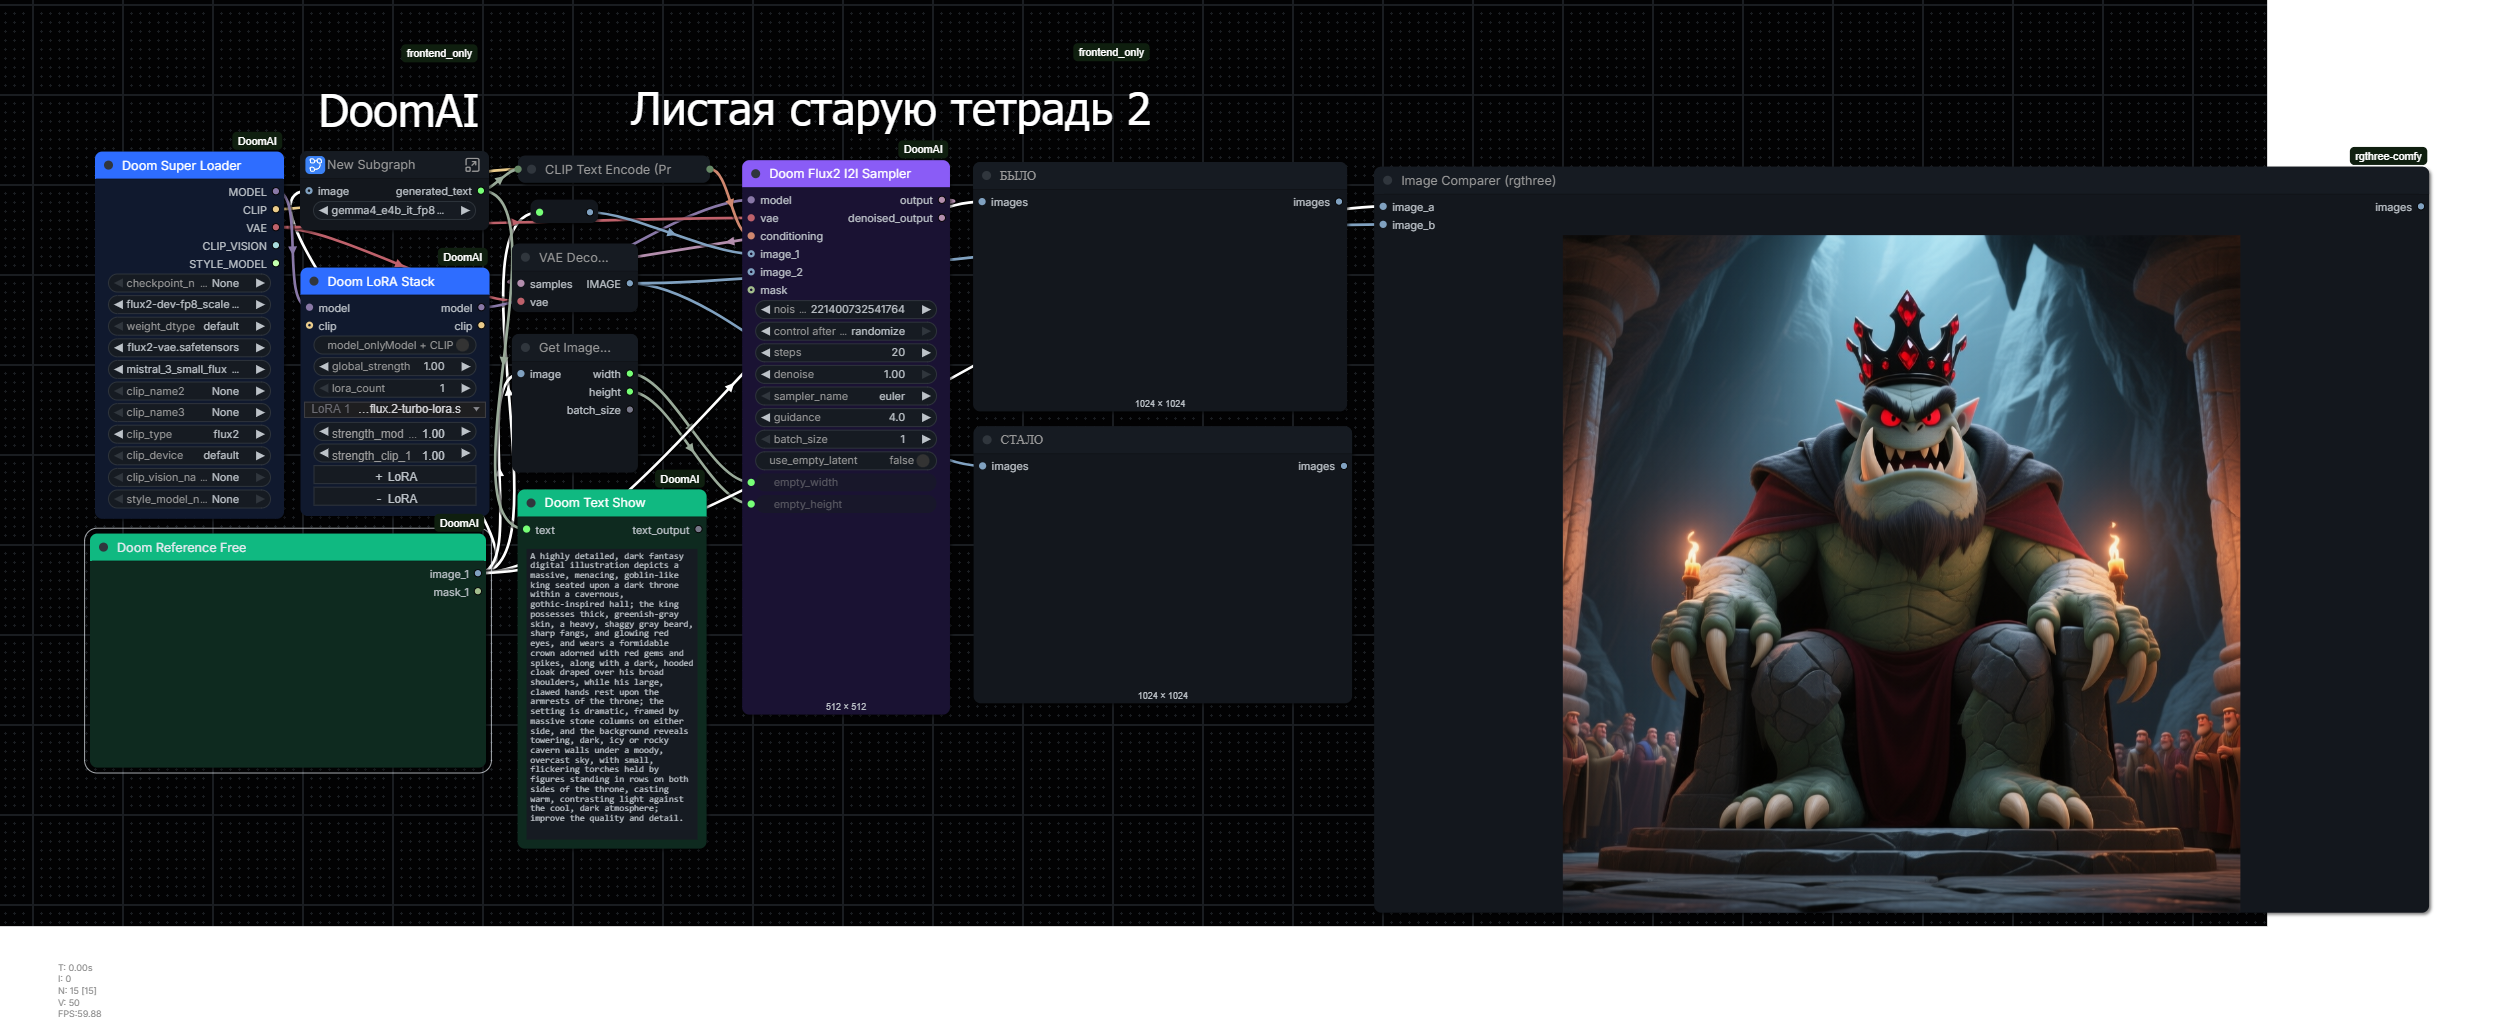
Ready-to-use examples in workflows/ — each has a JSON (open it in ComfyUI via Workflow → Open) and a PNG preview:
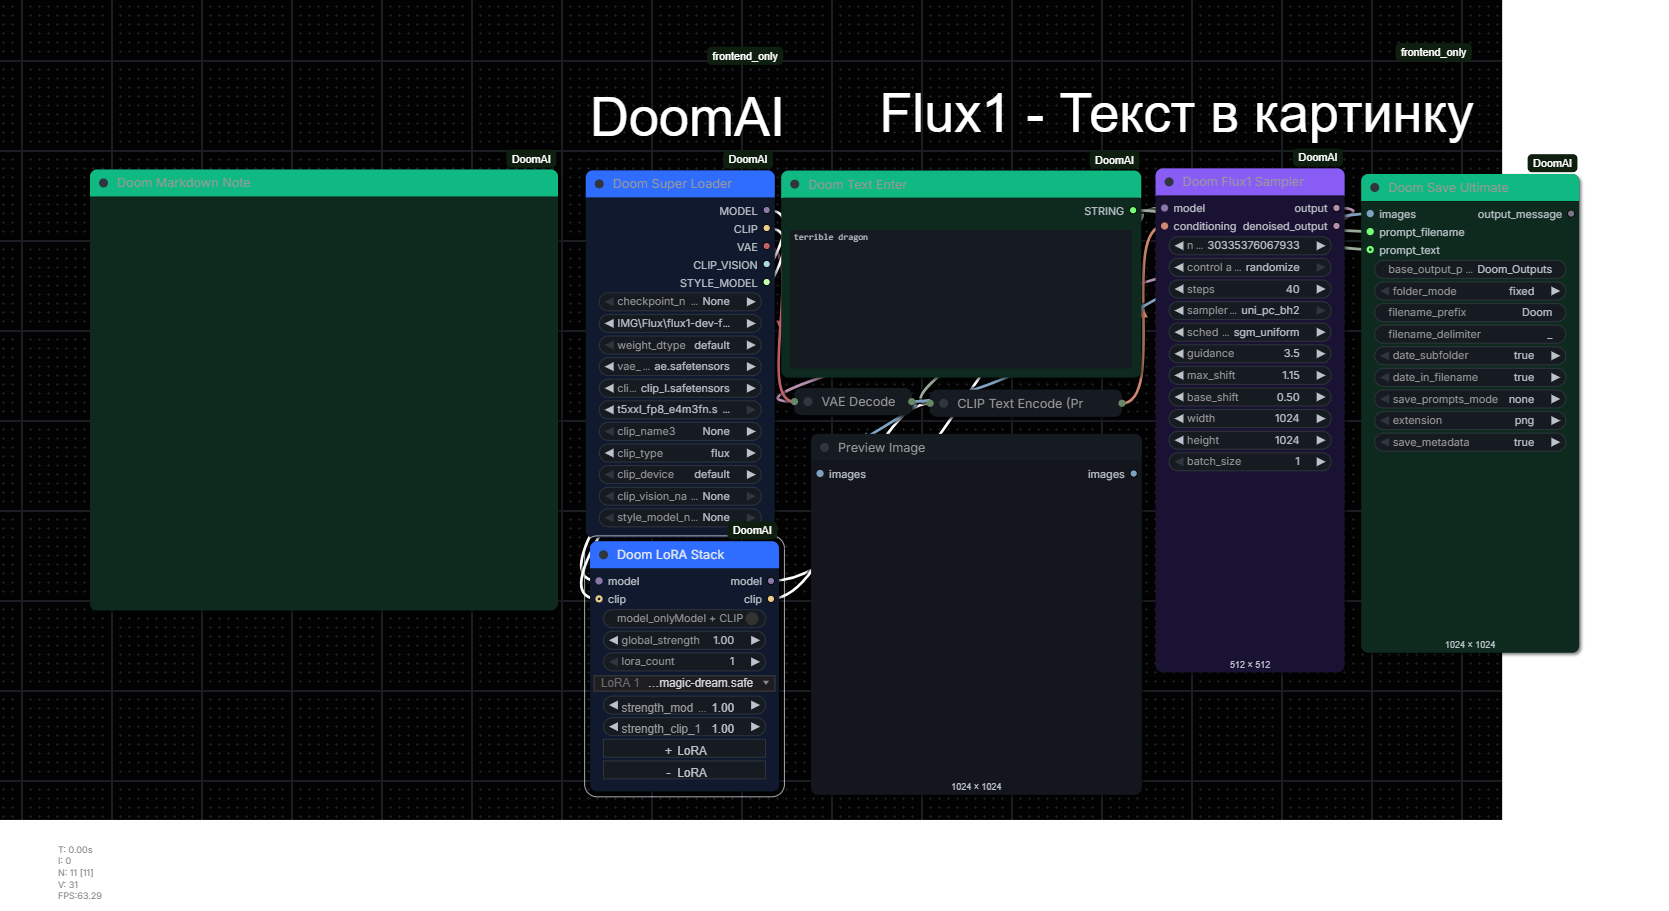
Flux.1 — text to image
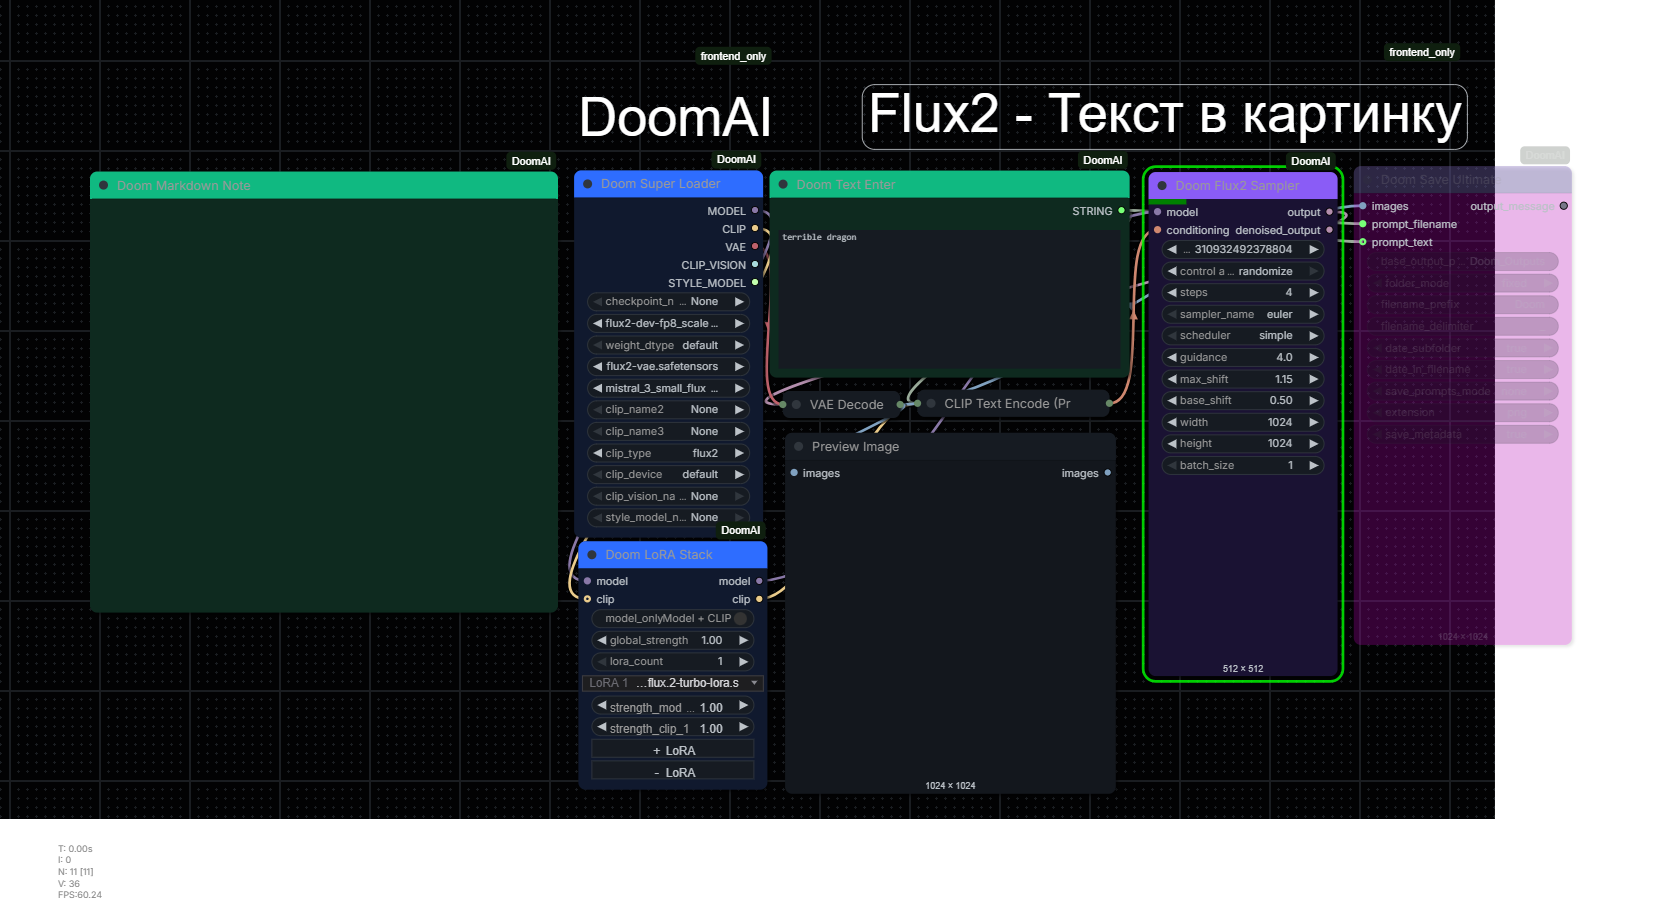
Flux.2 — text to image
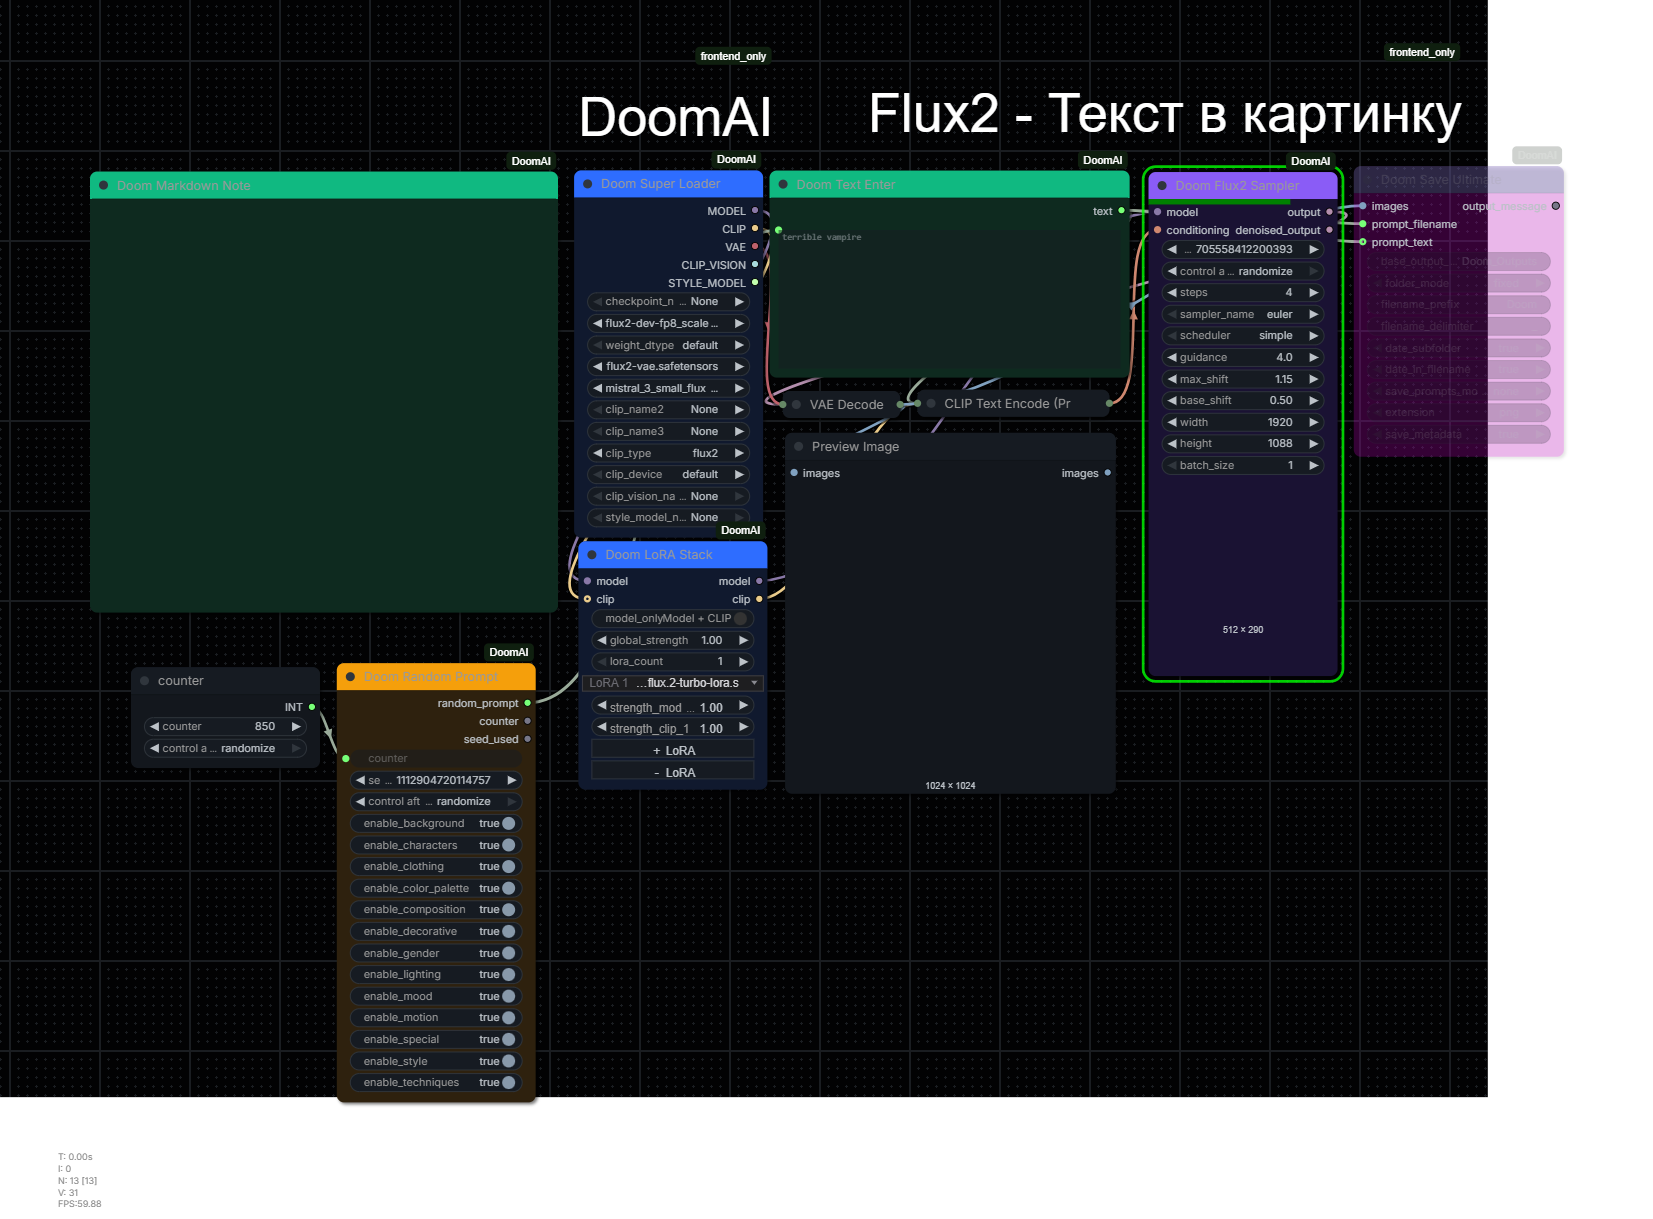
Flux.2 — random prompt (wildcards)
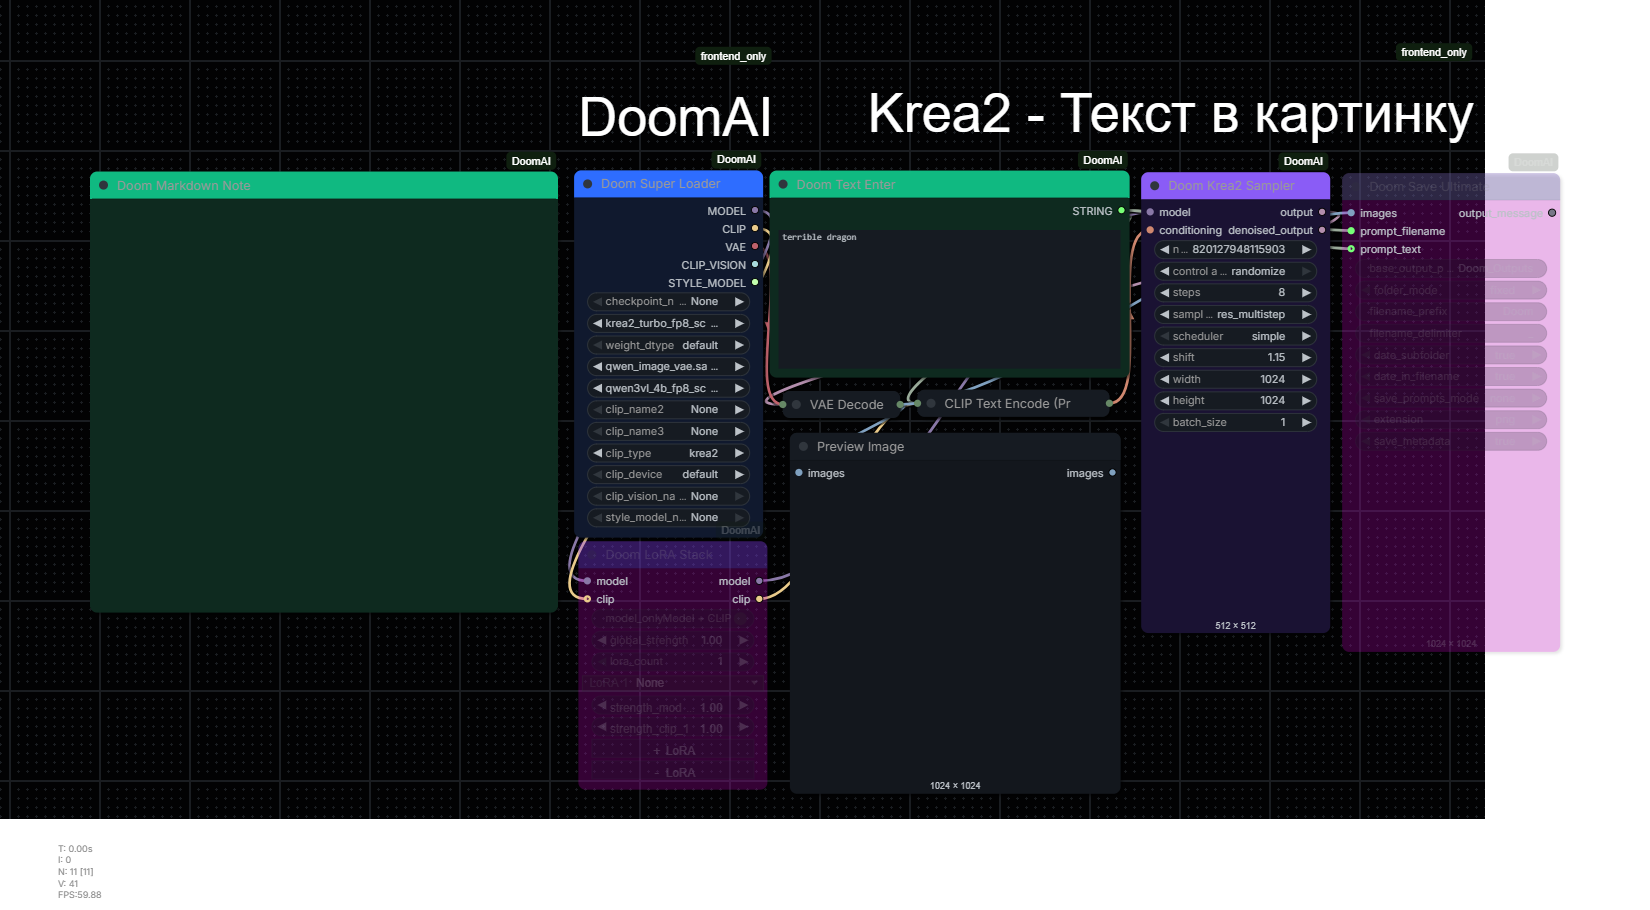
Krea2 — text to image
Flux.1 — img2img (Advanced sampler)
Flux.1 — inpaint
Flux.2 — I2I with image references
Note:
flux2_i2i_reference_pagesuses a subgraph prompt enhancer (CLIPLoader + TextGenerate) — requires ComfyUI with subgraph support (0.24+).
LTX-2.5 — image to video with sound
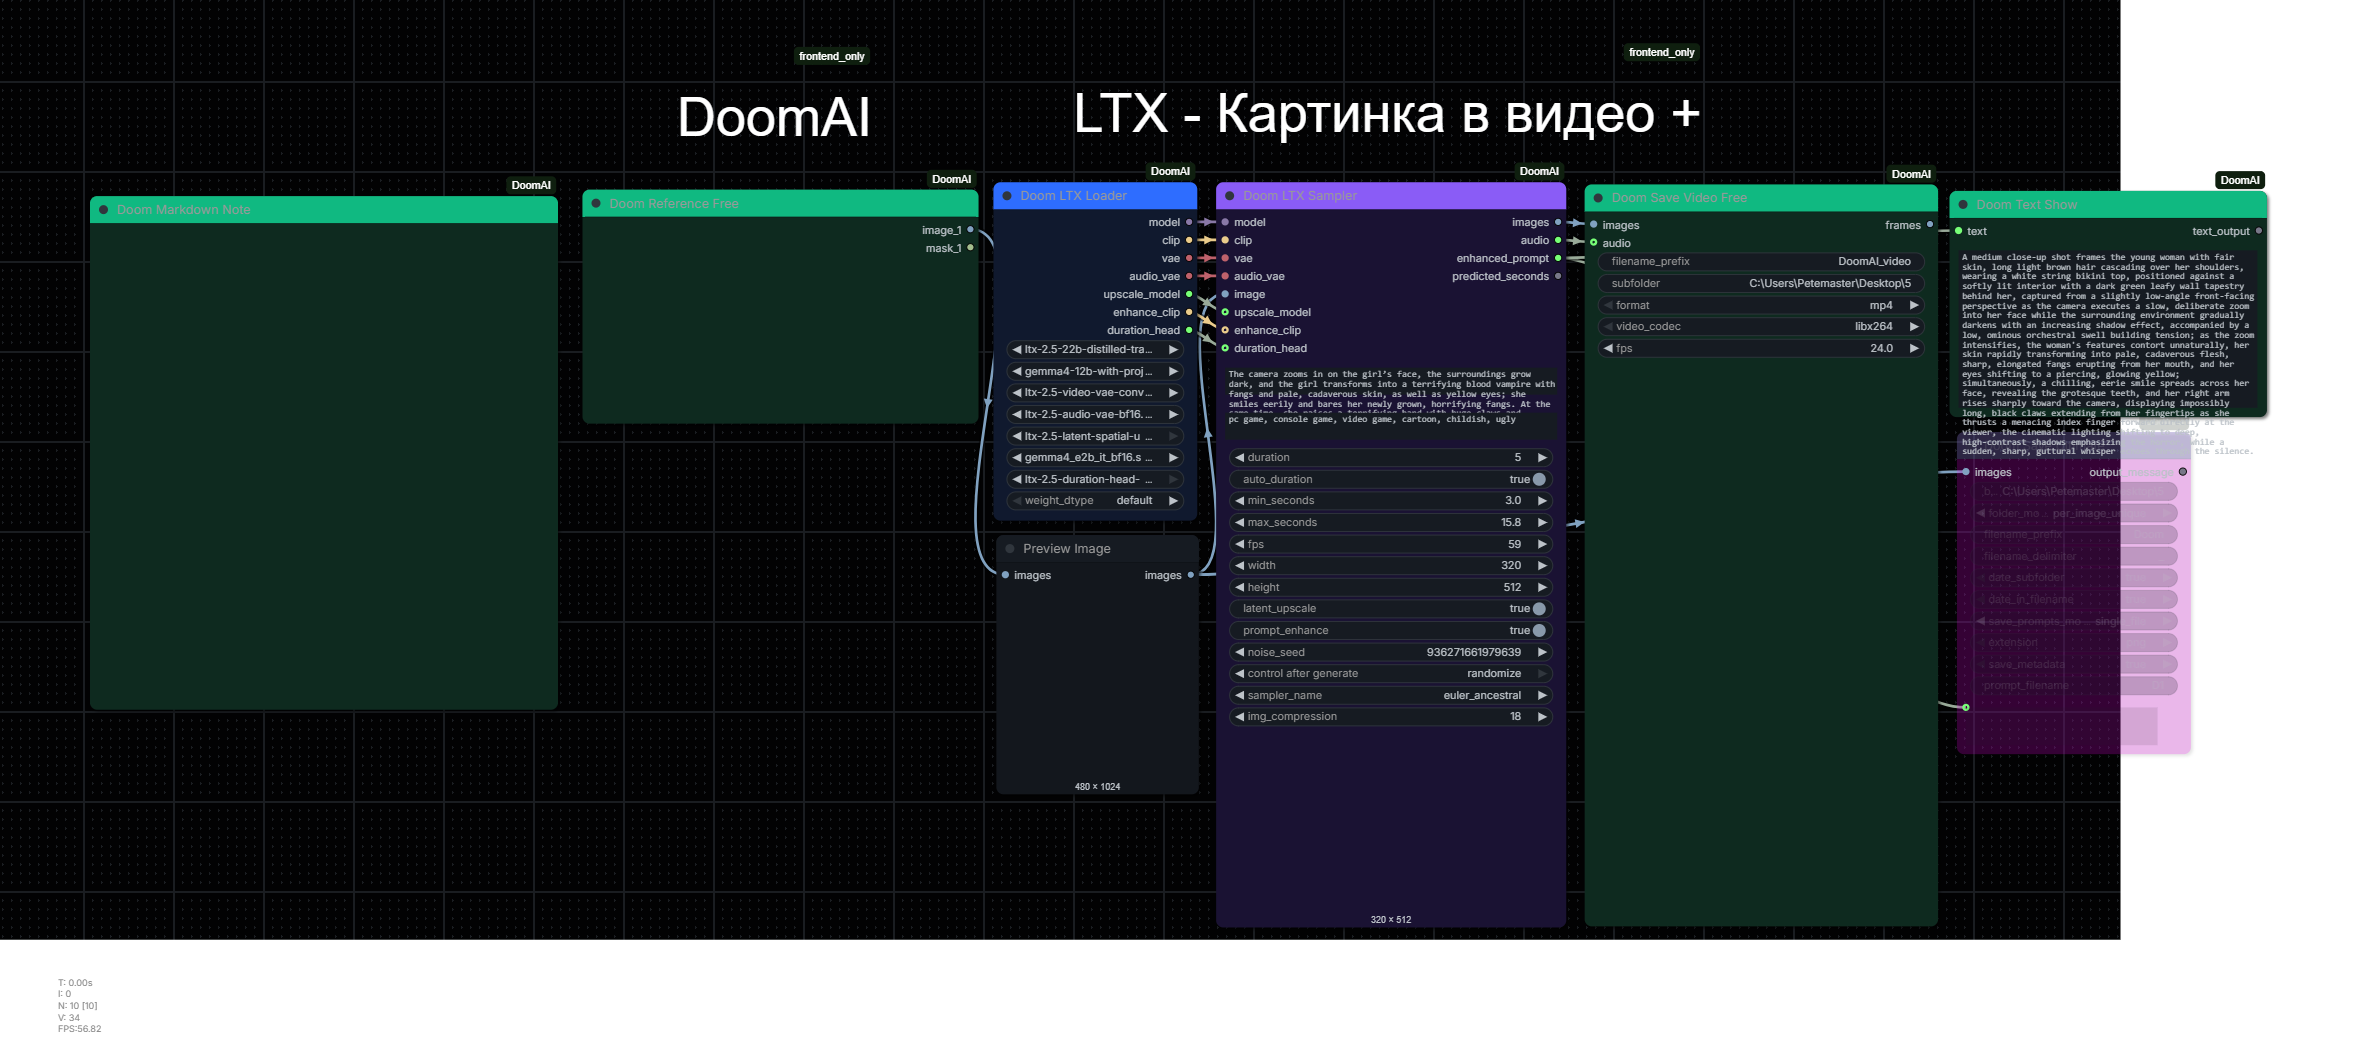
MiniMax H3 — image to video with sound
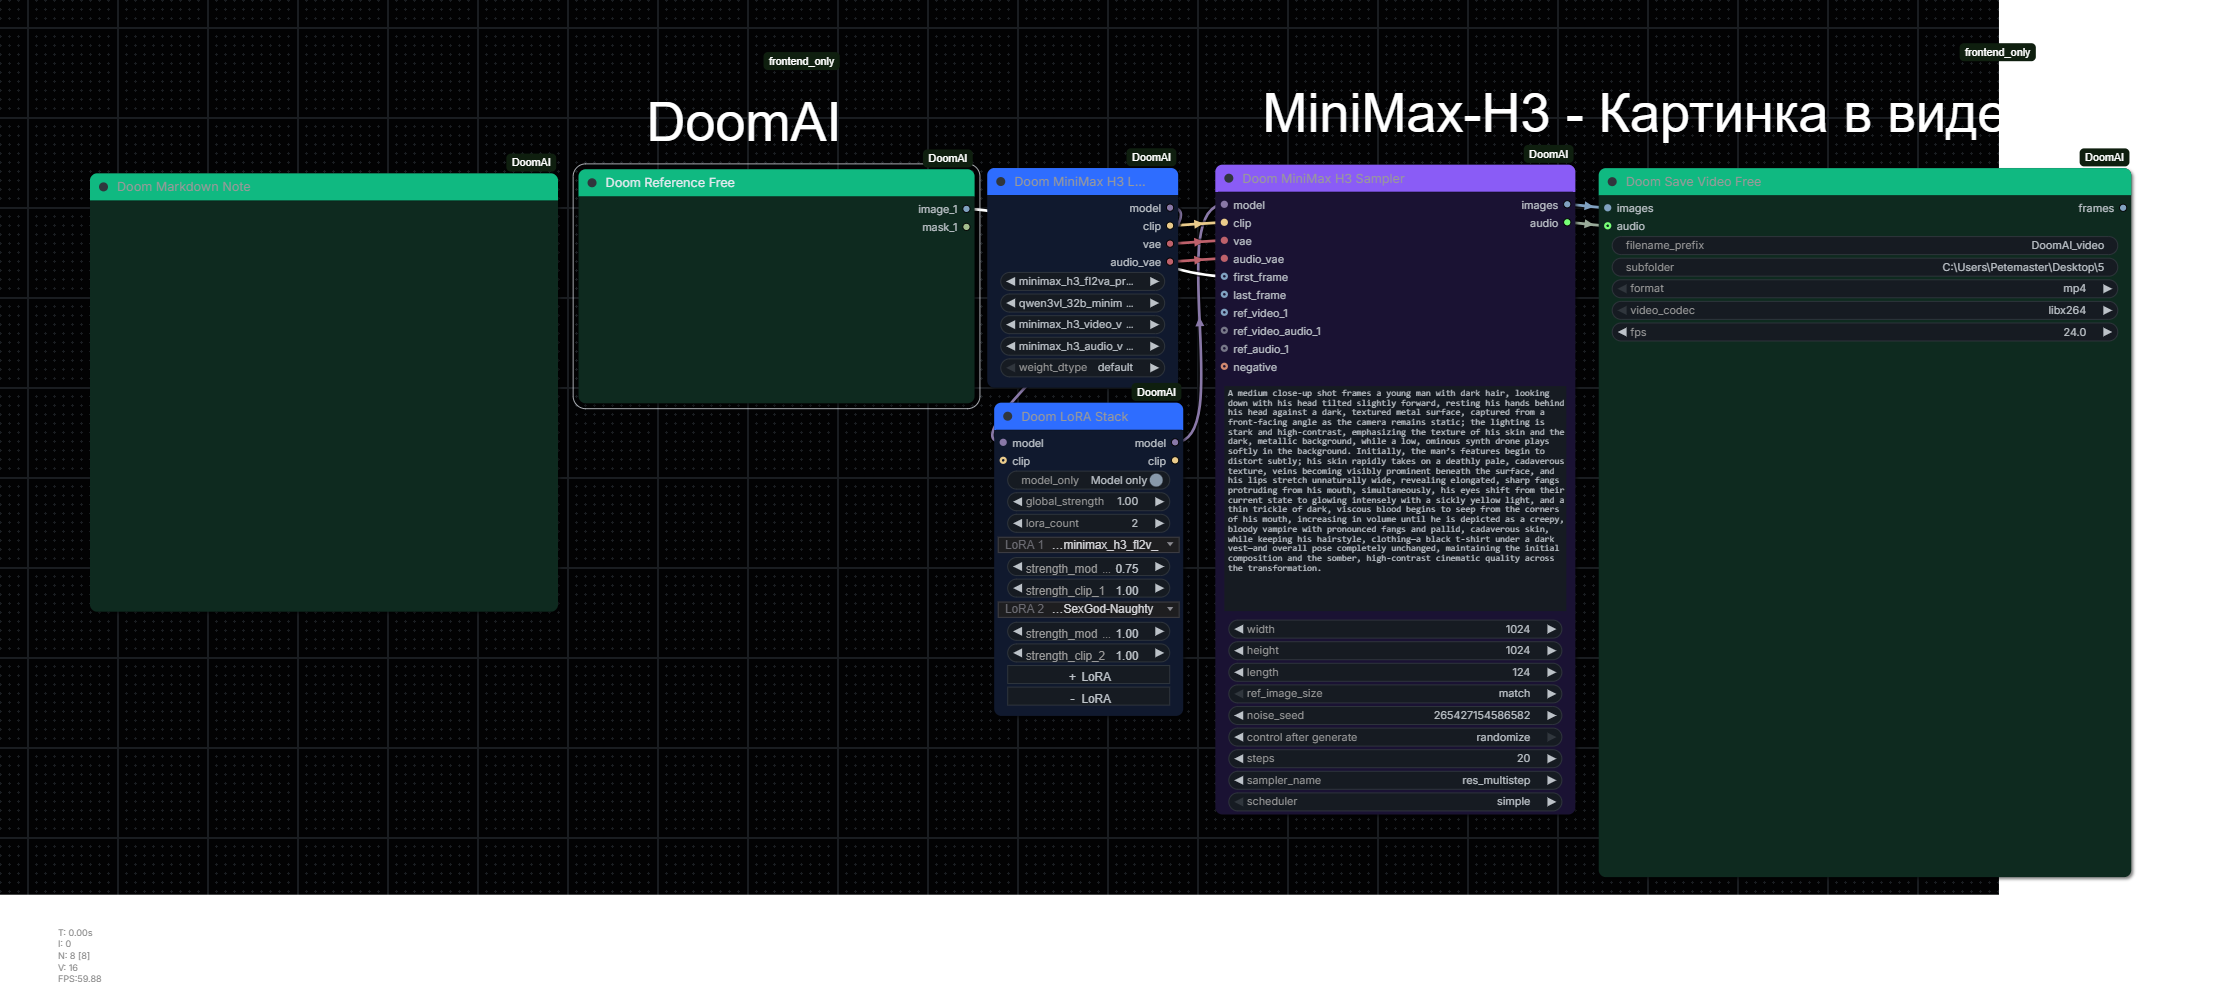
All workflows use the current node names — no legacy remapping needed.
Models
- Flux.1 / Flux.2 / Krea2: standard ComfyUI folders (
diffusion_models,text_encoders,vae) - LTX-2.5:
ltx-2.5-22b-distilled-transformer-comfy-int8-convrot.safetensors+ Gemma 4 CLIP + video/audio VAEs + upscaler (optional) +ltx-2.5-duration-head-bf16.safetensors→models/model_patches/for auto duration - MiniMax H3: H3 diffusion + Qwen3-VL + video/audio VAEs
Changelog
See CHANGELOG.md.
License
MIT — see LICENSE.
Znai nashih!