
MiniMax H3 LongMedia
Long-form MiniMax H3 video/audio generation for ComfyUI with unified clip planning, continuity, lip-sync, and adaptive low-VRAM execution.
Nodes (34)
The low-VRAM attention knob ComfyUI hides from you
Get your soundtrack into H3's latent space, properly
Find out which H3 transformer block ate your VRAM
See exactly what your first denoise step costs in VRAM
A health check for H3's weird two-stream latent
The honest way to do lip-sync in latent space
Where a long H3 run finally becomes video you can watch
Handing H3 the previous clip so the next one matches
The sampler that turns one H3 prompt into a whole long clip
The one node that decides what your H3 video will be
Blend a new video stream into an old clip without touching its audio
The other half of H3's low-VRAM story (the MLP half)
The tiny node that makes H3's two streams one
Grow a clip by opening the next one with the last one's ending
The guard that stops your refine pass from wrecking the seam
Cut your sigma schedule in two so the refine tail doesn't fight the base pass
A deprecated node that still does its job (if you have old graphs)
Swap one half of an H3 clip without regenerating the other
The deprecated video-swap node old graphs still load with
The guider that finally knows what the previous clip looked like
The no-noise pass that still remembers the seed
Splitting H3's joint video+audio latent into two editable streams
Joining H3 continuation segments without a visible seam
Keep the audio, regenerate the picture — H3 streams on separate dials
Turning off pinned memory so the huge H3 model can page itself
Putting ComfyUI's pinned-memory setting back where you found it
The engine that runs every H3 segment in a single sampling lifecycle
Turning frames into an H3 video stream the model can actually eat
Inpainting inside H3's video latent, not on the pixels
The post-run VRAM flush that tells you how much it clawed back
A SAMPLER wrapper that flushes VRAM before you run out, not after
Tell MiniMax H3 how to move the camera without the camera ending up in the shot
A prompt, duration and seed per clip
Restore long, low-quality video with MiniMax H3 — without VRAM scaling to the runtime
ComfyUI-MiniMax-H3-LongMedia
Production-oriented ComfyUI nodes for MiniMax H3 long-form video/audio generation, native reference editing, MultiClip planning, camera direction, fixed segmentation, lip-sync/redubbing, latent hi-res refinement, and adaptive low-VRAM execution.
Current release: 0.5.40
Main Nodes
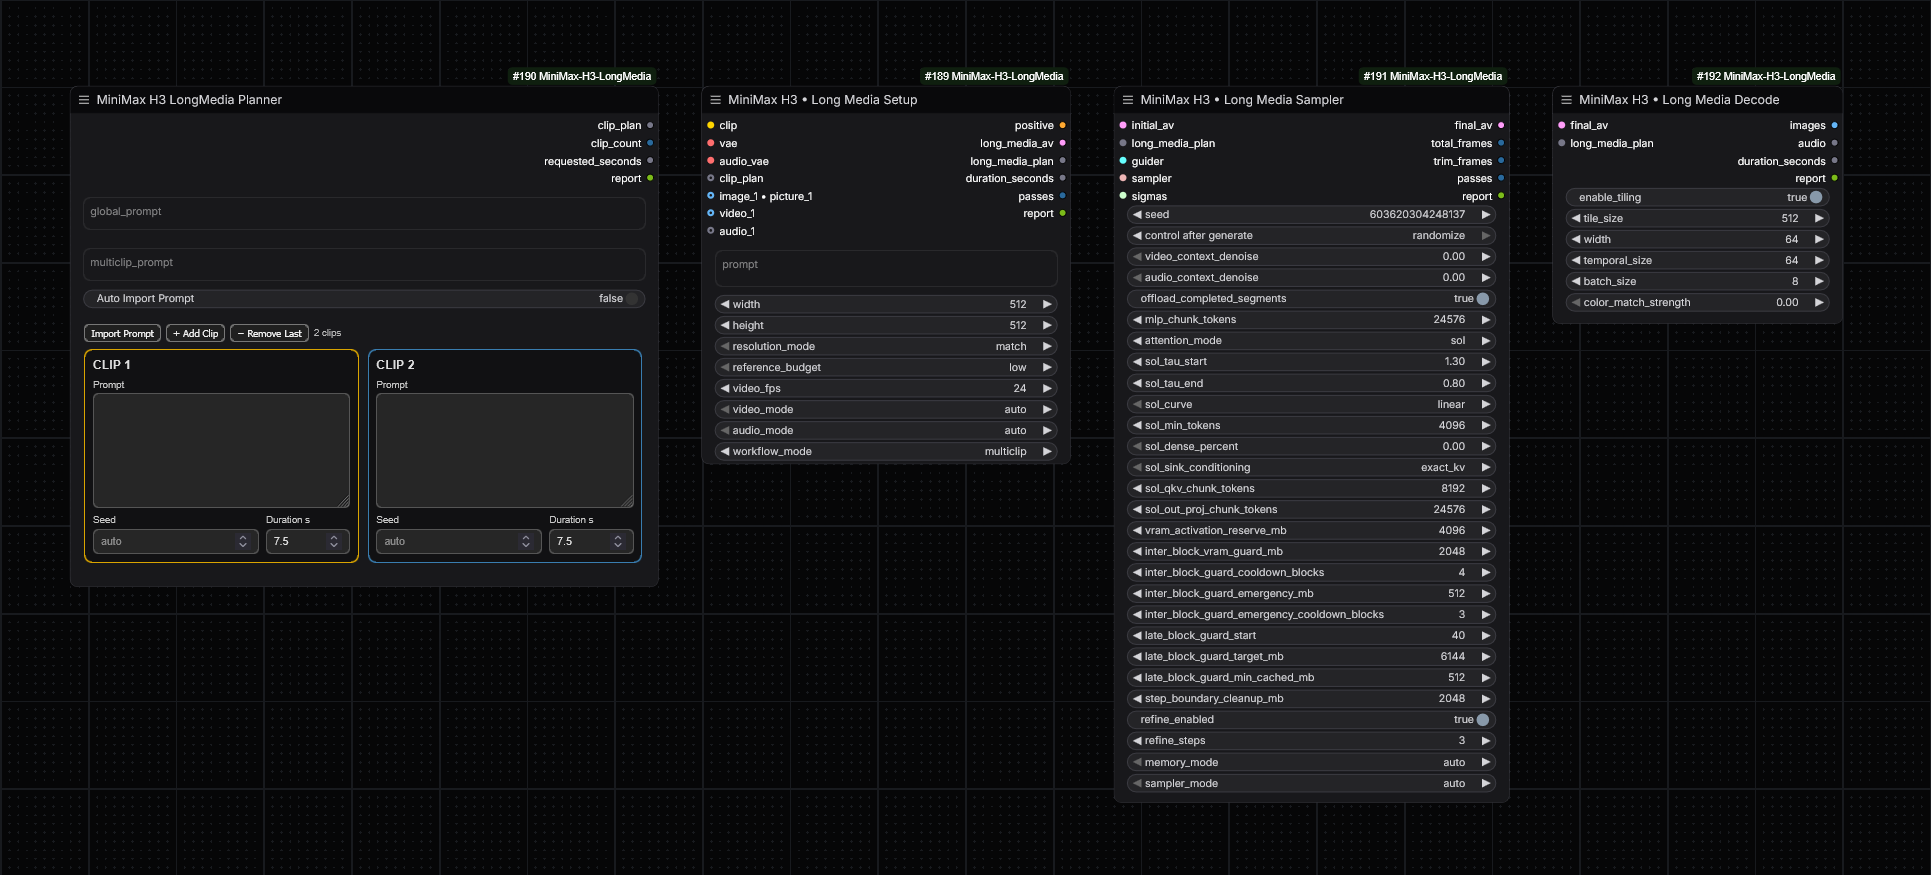
- MiniMax H3 • Long Media Setup
- MiniMax H3 • Long Media Planner
- MiniMax H3 • Long Media Cameras
- MiniMax H3 • Long Media Sampler
- MiniMax H3 • Long Media Decode
- MiniMax H3 • Long Media Video Reconstructor
Legacy internal MiniMaxH3LatentLab... class identifiers remain registered for workflow compatibility.
Installation
Install into:
ComfyUI/custom_nodes/ComfyUI-MiniMax-H3-LongMedia
or install the package from the Comfy Registry.
Package identity:
GitHub:             vizart-vj/ComfyUI-MiniMax-H3-LongMedia
Comfy PublisherId:  noise
Restart ComfyUI after installation/update.
Current Setup Model
New workflows use independent semantic controls:
control_mode
h3_mode
timeline_mode
duration_source
audio_mode
This is the main change in how the project should be understood compared with the public 0.4.40 documentation.
See Operating Modes.
H3 Conditioning
t2va
fl2va
ref2va
hybrid
video_ref_edit
Timeline
single
segmented
multiclip
Duration Ownership
auto
video
audio
manual
longest_input
duration_source controls timeline length only. It does not remove audio references or change final-audio policy.
video_ref_edit
Typical source-character replacement:
video_1 = source video frames
image_1 = replacement identity
audio_1 = source soundtrack or new dub
A Video input is an IMAGE batch and never contains soundtrack data.
For preserve-style modes, Video1+Audio1 can be presented as a native paired source-performance reference while Audio1 also owns the target timing/output waveform.
For audio_mode=lip_sync, Audio1 is intentionally independent from Video1's original facial performance so completely new dialogue or singing can drive the replacement character.
Audio2/Audio3 remain prompt-addressable references for music, percussion, bass, ambience, or other semantic timing. In video_ref_edit, they are conditioning references only; Audio1 remains the sole preserved/passthrough source soundtrack.
See Audio Modes and video_ref_edit.
MultiClip + Cameras
Recommended connection:
Long Media Planner
        ↓ clip_plan
Long Media Cameras
        ↓ clip_plan
Long Media Setup
Use:
timeline_mode = multiclip
Planner owns diegetic scene/action prompts, durations, names, and optional seeds. Cameras owns framing, rig/lens, movement, speed, spatial relation, entity continuity, and transitions.
See:
Segmented Long Form
Use:
timeline_mode = segmented
for one continuous semantic movie split into fixed-duration internal units for VRAM/stability. It is not a storyboard scheduler.
See Fixed Segmentation Prompting.
Two-Stage H3 / Latent Hi-Res
The Long Media Sampler can:
- generate a low-resolution Stage-1 denoised x0;
- learned-upscale the video latent only;
- preserve the audio latent;
- rebuild target-grid conditioning;
- optionally run an independent same-seed fresh-noise high-resolution H3 pass.
Without Latent Hi-Res, the Refiner remains a continuous zero-noise low-sigma tail.
See Two-Stage Sampling, Latent Hi-Res and Refiner.
Sampler / Memory
Production starting point:
sampler_mode   = auto
memory_mode    = auto
attention_mode = auto
Keep ComfyUI Dynamic VRAM enabled.
Current memory-safety work includes exact Comfy Kitchen query streaming for structurally impossible fused-QKV workloads, repeat-run memory isolation, guarded native INT8 VBAR prefetch on constrained GPUs, and RAM-pressure-aware pinned host memory.
See Sampler, VRAM and Performance Guide.
FastH3 / FastVideo VSA
LongMedia includes isolated compatibility paths for supported H3ddle/PulpCut FastH3 VSA and Kijai FastVideo VSA packages.
These paths use strict structural detection and reset their runtime state when switching back to ordinary H3 checkpoints.
Loop Closure
Loop Closure returns the generated tail toward the opening macro-state in latent/H3 space. It is independent from conditioning/timeline mode and does not use an RGB crossfade as its primary mechanism.
Documentation
Start at docs/README.md.
Important guides:
- Operating Modes
- Audio Modes
- Two-Stage Sampling / Latent Hi-Res / Refiner
- Sampler / VRAM
- Architecture
- 0.5.40 changes since 0.4.40
Example Workflows
workflows/MiniMax-H3-LongMedia-SAFE-1080p-15s.jsonworkflows/MiniMax-H3-LongMedia-LatentUpscale-Detailer.json
Release workflows contain neutral media placeholders rather than user media or local preview paths.
See workflows/README.md.
Third-Party Code
This repository contains adapted third-party components under their respective licenses, including:
- Saganaki22/ComfyUI-sol-attn-derived code under Apache-2.0;
- MiniMax H3 latent-upscaler-derived code under Apache-2.0.
See THIRD_PARTY_NOTICE.md and THIRD_PARTY_APACHE_2_0.txt.
Release History
0.5.40 is the release consolidation after public v0.4.40.
Historical release notes remain in docs/ for compatibility/reference. They may use the old workflow_mode terminology.
License
See LICENSE.