
Open-H3 Regenerate 2K IC
ComfyUI nodes and workflows for Open-H3-Regenerate-2K-IC draft-to-2K video refinement
ComfyUI Open-H3-Regenerate-2K-IC
English | 简体中文
ComfyUI nodes and example workflows for NVlabs/Sana · Open-H3-Regenerate-2K/IC.
This repository contains both:
- Text-to-video example — text → 768P H3 draft → IC 2K refinement.
- Draft-to-2K example — existing 768P draft → IC 2K refinement.
- GitHub: https://github.com/slmonker/ComfyUI-OpenH3Regenerate2KIC
- Converted ComfyUI LoRA: https://huggingface.co/slmonker/Open-H3-Regenerate-2K-IC-ComfyUI
- Upstream weights: https://huggingface.co/Efficient-Large-Model/Open-H3-Regenerate-2K-IC
Demo videos
Each comparison shows the 768P draft on the left and the 2K IC result on the right. Click a preview to open the final MP4.
Demo 1
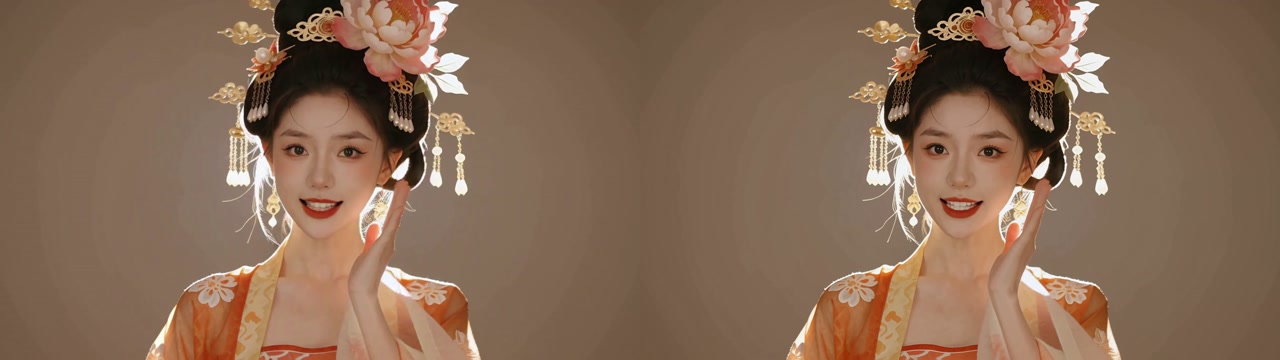
Demo 2
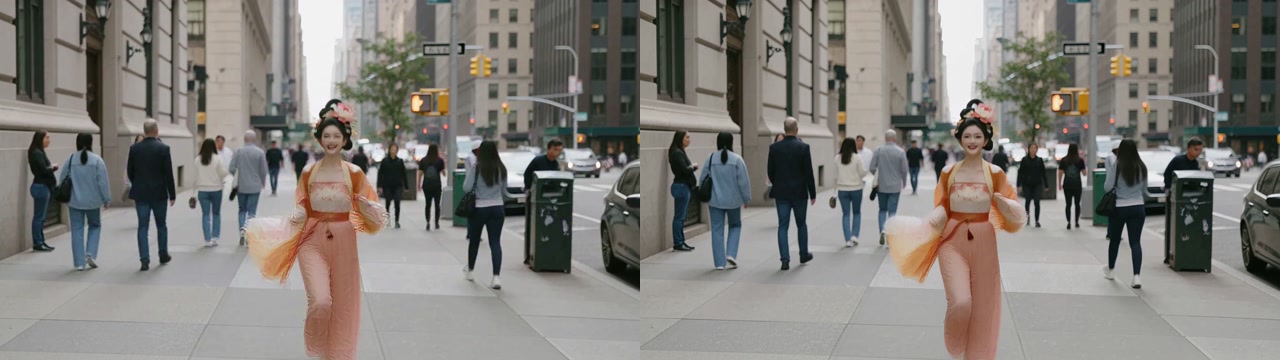
Demo 3
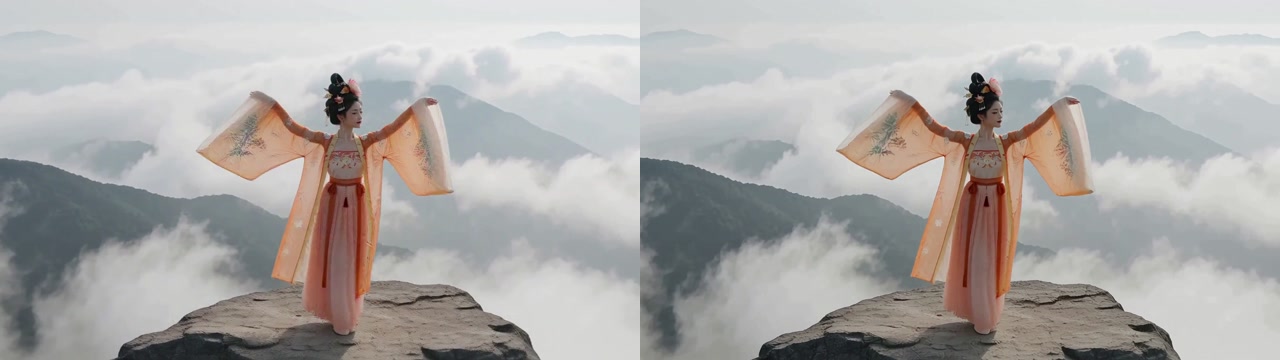
Examples
| Example | Workflow | Description |
|---|---|---|
| Text-to-video | workflows/regen2k_ic_T2VA.json | Generates a 1344×768 draft from text, then refines it to 2560×1440 |
| Reference-to-video | workflows/H3_regen2k_ic_Ref2va.json | Enhances a reference image into a 768P Ref2VA draft, then refines it to 2560×1440 |
| Draft-to-2K | workflows/open_h3_regenerate_2k_ic.json | Refines an existing 768P draft to 2560×1440 |
Text-to-video pipeline
Text prompt
  -> MiniMax-H3 Image-to-Video + DMAD 4-step LoRA
  -> 1344×768 / 124 frames / 24 fps draft
  -> decode draft video + draft audio
  -> draft becomes <Video 1> in Ref2VA
  -> official 3D latent upscaler
  -> HyperFlow + LMS Sharp + Open-H3 IC LoRA
  -> up3 3-step refinement
  -> 2560×1440 final video
The T2VA workflow uses one text node that feeds both stages:
- raw text into the H3 draft generator
- official enhancement prefix + the same text into the IC Ref2VA stage
Draft-to-2K pipeline
Existing 768P draft
  -> <Video 1> Ref2VA conditioning
  -> H3 VAE encode -> official 3D latent upscaler
  -> HyperFlow + LMS Sharp + IC LoRA
  -> up3 / up4 / hf8 sigma grid
  -> fast H3 VAE decode
  -> mux the draft's original audio
Contents
| Path | Purpose |
|---|---|
| nodes.py | Four ComfyUI helper nodes |
| workflows/open_h3_regenerate_2k_ic.json | Draft-to-2K UI workflow |
| workflows/open_h3_regenerate_2k_ic_api.json | Draft-to-2K API payload |
| tools/convert_ic_lora.py | Diffusers IC LoRA → ComfyUI generic LoRA |
| tools/build_workflow.py | Rebuild the draft-to-2K workflow |
| assets/silence_audio_124f.safetensors | Official fixed-silence latent for the IC audio rows |
| tests/test_nodes.py | Unit tests for preprocessing and sigma grids |
Nodes
Open-H3 IC · Prepare Draft (124f / 24fps)
- samples 124 frames at 24 fps
- cover-resizes and center-crops to 1344×768
- trims or pads audio using its real sample rate
- requires at least 113 real frames after resampling
Open-H3 IC · Official Prompt
Prepends the official enhancement task and preserves the source caption as
Scene description.
Open-H3 IC · Sigma Grid
| Mode | Sigmas |
|---|---|
| up3 | 0.834942, 0.696852, 0.468753, 0 |
| up4 | 0.923077, 0.834942, 0.696852, 0.468753, 0 |
| hf8 | 1.0, 0.99391, 0.984288, 0.966064, 0.923077, 0.834942, 0.696852, 0.468753, 0 |
Open-H3 IC · Compose Target Latent
Combines the upscaled target video latent with the official 124-frame silence
latent and pins the audio stream with noise_mask=0.
Installation
ComfyUI Manager
Search for Open-H3 Regenerate 2K IC in ComfyUI Manager, or install Registry ID comfyui-open-h3-regenerate-2k-ic.
cd ComfyUI/custom_nodes
git clone https://github.com/slmonker/ComfyUI-OpenH3Regenerate2KIC.git
Restart ComfyUI after installation.
The T2VA example also uses:
ComfyUI-LynnReal— attention/feed-forward helpersComfyUI-Spark-H3— Sol-Attn sparse attentionComfyUI-VideoHelperSuite—VHS_VideoCombine
The draft-to-2K example uses LynnRealH3VAELoader for the fast H3 VAE decoder.
Common models
Place these under ComfyUI/models/:
models/
├── text_encoders/
│   └── MiniMax-H3/qwen3vl_32b_minimax_h3_int8_convrot.safetensors
├── vae/
│   └── MiniMax-H3/
│       ├── minimax_h3_video_vae_fp16.safetensors
│       └── sol_h3_vae.safetensors
├── latent_upscale_models/
│   └── minimax_h3_latent_upscaler_3d_conv_v1_bf16.safetensors
└── loras/
    ├── minimax_h3_hyperflow_8step_v1.0_comfyui_bf16.safetensors
    ├── minimax_h3_lms_v1.0_r64.safetensors
    └── minimax_h3_open_regenerate_2k_ic_comfy_bf16.safetensors
Download the converted IC LoRA from:
https://huggingface.co/slmonker/Open-H3-Regenerate-2K-IC-ComfyUI
Load the IC LoRAs in this order:
- HyperFlow 8-step
- LMS Sharp
- Open-H3 Regenerate 2K IC
T2VA-only models
models/
├── diffusion_models/
│   └── minimax_h3_hybrid_fl2va_ref2va_b25-49-int8.safetensors/
│       └── minimax_h3_hybrid_fl2va_ref2va_b25-49-int8.safetensors
├── vae/MiniMax-H3/
│   └── minimax_h3_audio_vae_fp32.safetensors
└── loras/
    └── dmad_minimax_h3_4step_full_critic_comfy.safetensors
The hybrid FL2VA+Ref2VA checkpoint and DMAD LoRA come from the MiniMax-H3 / TaoMate-HD ecosystem. The hybrid checkpoint is not included in this repository.
Running the T2VA example
- Open
workflows/regen2k_ic_T2VA.json. - Edit T2VA prompt · edit this text once.
- Run the graph.
- The 768P draft preview and 2K final video are written under
ComfyUI/output/OpenH3/.
Default settings:
- draft: 1344×768, 124 frames, 24 fps, DMAD 4-step
- IC refinement:
up3, CFG 1, 2560×1440
Running the draft-to-2K example
- Put an existing 768P draft into
ComfyUI/input/. - Open
workflows/open_h3_regenerate_2k_ic.json. - Select the draft in Load Video.
- Enter the original prompt in Open-H3 IC · Official Prompt.
- Run the graph.
For 1080P, set both resolution-bearing nodes to 1920×1088. For 4K use
3840×2176, which is usually impractical on a 32 GB GPU.
Convert the official IC LoRA
python tools/convert_ic_lora.py \
  open_h3_regenerate_2k_ic_lora.safetensors \
  minimax_h3_open_regenerate_2k_ic_comfy_bf16.safetensors \
  --dtype bf16
Conversion details:
- q/k/v → fused
qkv_projwith block-diagonal B ff.net.0.projfrom Diffusers[value;gate]to ComfyUI[gate;value]- fused qkv
alpha = 3 × rank - output BF16
Released conversion:
- 312 source linear layers
- 208 ComfyUI modules
- 624 tensors
- zero missing base-model mappings
Validation
python -m unittest discover -s tests -v
The draft-to-2K workflow loads in ComfyUI and converts through graphToPrompt()
with zero input-schema errors. The converted LoRA was checked against
minimax_h3_ref2va_bf16.safetensors.
Notes
- Default clip length is 124 frames (about 5.17 seconds).
- The T2VA example keeps H3-generated draft audio in stage 1.
- The IC stage uses fixed silence internally and outputs the draft audio.
- 2K on 32 GB VRAM requires model offload / low-VRAM attention handling.
- This is a community implementation, not an official MiniMax product.
Acknowledgements
License
Node code is Apache-2.0. MiniMax-H3 weights and derivative assets remain subject
to the MiniMax-H3 Community License. See NOTICE.md.