
Looking Ahead for ComfyUI
Looking Ahead (TencentARC, Future Chunk Prediction) 1.3B text-and-image-to-video for ComfyUI: the official autoregressive KV-cache sampler, verified bit-exact against the official pipeline, with ComfyUI's own umT5 text encoder and Wan 2.1 VAE. Unofficial.
Looking Ahead for ComfyUI
Unofficial ComfyUI nodes for Looking Ahead (paper, code, weights), the Future Chunk Prediction (FCP) autoregressive video model from Tencent ARC Lab, Nanjing University and Zhejiang University. The pack runs the 1.3B text-and-image-to-video model (built on Wan 2.1): give it a start image and a prompt, and it generates the video in 3-latent-frame chunks with a KV cache, exactly like the official inference.
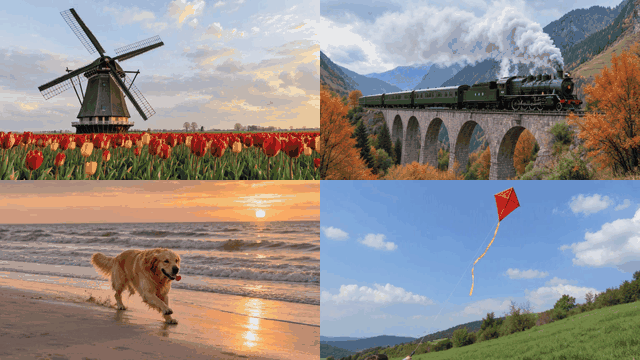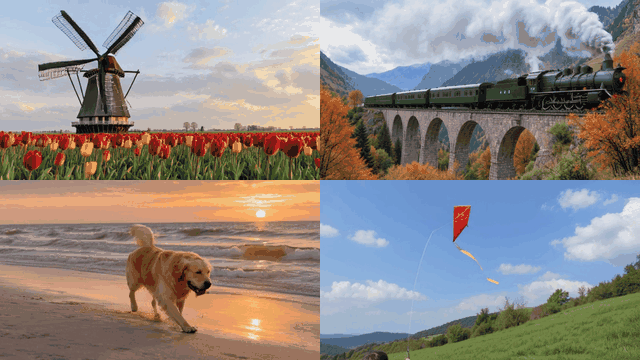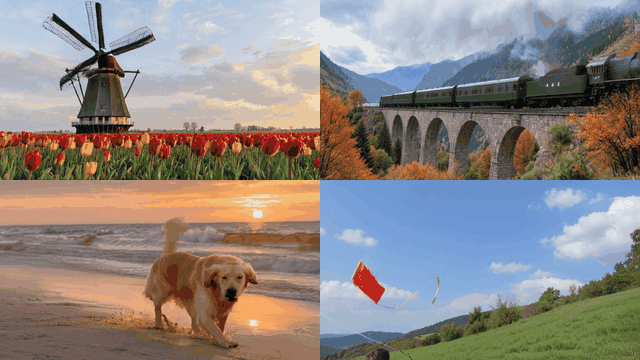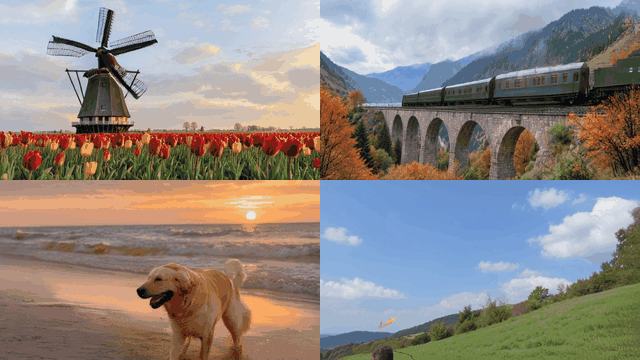
These four clips are each the first try at seed 42, at the default settings (768×432, 16 fps, 50 steps). They are shown as they came out, scaled down. The windmill turns and the train crosses the bridge. The dog runs along the beach, but loses the toy in its mouth. The kite is a miss: it falls out of the frame instead of climbing. The start images were made for this demo with MOSS-Image (Apache-2.0); prompts and details are in docs/images.
What is checked
- Sampler. Fed the official run's prompt embeddings, first-frame latent and noise, the node's sampler returns latents that
are bit-identical to the official
CausalDiffusionInferencePipeline(5 s, 768×432, seed 42, 50 steps, CFG 3.0, on an RTX 5090). CI repeats this comparison on every push, on CPU, with a tiny random model inside the official pipeline. One case fits in the training window; the other rolls the KV cache with the attention sink. - Start image. The start image goes through the official resize-and-center-crop. The pixels match exactly (tested), and ComfyUI's Wan 2.1 VAE encodes it to within 0.4 % (relative L2) of the official encoder.
- Text encoder. ComfyUI's umT5-XXL (Wan) gives the same token count as the official one. With the same weights it is closer to a float32 reference than the official bfloat16 path: 0.17 % against 2.1 %. The common fp8 file is 6–9 % from it.
- End to end. A real ComfyUI queue reproduces the official video, with the same scene, composition and motion. Frame PSNR is 28.7 dB with the official text-encoder weights and 28.0 dB with the fp8 file. The difference comes from the autoregressive sampler amplifying small input changes: the 0.4 % first-frame difference alone moves the output latents by 3.5 %, close to the 4.1 % of the whole run.
- Robustness. The same workflow queued twice gives bit-identical output. Interrupting stops sampling within a step, and the next prompt runs normally.
Details and numbers: docs/VERIFICATION.md.
Nodes
| node | what it does |
| --- | --- |
| Looking Ahead Model Loader | Loads model_ema.pt (FCP or the TF baseline) from models/looking_ahead as bfloat16 and drops the training-only branches. One model stays in RAM. |
| Looking Ahead Image to Video | Start image + positive/negative conditioning (umT5-XXL) + Wan 2.1 VAE → VIDEO (16 fps), IMAGE frames, LATENT and a JSON report. Seed, seconds (1–30), steps, CFG, shift and size; it frees VRAM from other models first, shows progress and can be interrupted. |
| Looking Ahead Unload | Frees the resident model. |
The text encoder and VAE are ComfyUI's own CLIPLoader (type wan) and VAELoader, so files you already use for Wan 2.1
work as they are.
Install
ComfyUI 0.42.1 or newer (V3 node API). No extra Python packages.
cd ComfyUI/custom_nodes
git clone https://github.com/hiroki-abe-58/ComfyUI-LookingAhead
Models
| file | folder | size | source |
| --- | --- | --- | --- |
| fcp_wan21_t2v_1.3b/model_ema.pt | models/looking_ahead/ | 8.0 GB | TencentARC/Looking-Ahead |
| umt5_xxl_fp8_e4m3fn_scaled.safetensors (or umt5_xxl_fp16) | models/text_encoders/ | 6.7 GB | Comfy-Org/Wan_2.1_ComfyUI_repackaged |
| wan_2.1_vae.safetensors | models/vae/ | 0.25 GB | Comfy-Org/Wan_2.1_ComfyUI_repackaged |
Keep the checkpoint in its fcp_wan21_t2v_1.3b folder. The teacher-forcing baseline (tf_wan21_t2v_1.3b/model_ema.pt,
5.7 GB, --tf in the script) loads and runs the same way (tested); use it to compare FCP against plain teacher forcing.
Do not download the whole Looking-Ahead repository: it also holds the 5B checkpoints (about 50 GB), which this pack does not
support yet.
Or let the script fetch exactly these files at pinned revisions and check their SHA-256 (run it with ComfyUI's Python):
python custom_nodes/ComfyUI-LookingAhead/tools/download_model.py --models-dir models --wan
Use
Load workflows/gui/looking_ahead_image_to_video.json, pick a start image, and write what should happen in the prompt.
The negative prompt in the workflow is the official default. The defaults are the released settings: 768×432, 16 fps, 5 s,
50 steps, CFG 3.0 and shift 5.0.
- Start image. It is resized to cover the frame and center-cropped, as in the official inference; content at the edges can be cut off.
- Length. The models were trained on 5-second clips. Longer outputs use the rolling KV cache with a 3-frame attention sink, as the official code does. Upstream does not guarantee quality beyond 5 s.
- Size. Other sizes run, but the model was trained at 768×432.
Speed and memory
RTX 5090, Windows 11, PyTorch 2.10 SDPA, 768×432:
| length | frames | sampling | peak VRAM (allocated) | | --- | --- | --- | --- | | 5 s | 80 | 210 s | 13.4 GiB | | 10 s | 160 | 515 s | 13.6 GiB |
Most of the VRAM is the KV cache (22 latent frames for the positive and negative prompts, about 10.5 GiB). PyTorch reserved
up to 15.8 GiB, so a 24 GB GPU is comfortable and 16 GB is borderline. The node frees other models from VRAM before it samples,
and moves its own model back to RAM afterwards unless keep_model_loaded is on. In system RAM the model takes about 2.8 GB
(bfloat16; the 8 GB checkpoint is memory-mapped while loading). During a run, Windows commit on this machine went from about
30 GB idle to 55–60 GB, with ComfyUI holding the text encoder and VAE as well.
Limits
- 1.3B text-and-image-to-video only. The 5B (Wan 2.2) models and video continuation are not supported yet.
- Batch size 1. CUDA GPU required.
- Attention runs on PyTorch SDPA. If FlashAttention 4 imports (Linux), it is used, as upstream does.
License
Apache-2.0 (LICENSE). Code from Looking Ahead (Copyright (C) 2026 Tencent, Apache-2.0) and Wan2.1/Wan2.2 (Alibaba Wan Team,
Apache-2.0) is vendored in looking_ahead_comfy/vendor. Each file and change is listed in
vendor/UPSTREAM.md; see NOTICE. The model weights are not included; they keep their
own licenses (Looking Ahead and Wan 2.1: Apache-2.0).
This is an unofficial integration. If you use the model, please cite the paper:
@misc{gao2026lookingahead,
  title         = {Looking Ahead: Modeling Future Evolution in Autoregressive Video Generation},
  author        = {Gao, Ruopeng and Huang, Yukun and Hu, Jiarui and Wang, Shuai and Hu, Wenbo and Shan, Ying and Wang, Limin},
  year          = {2026},
  eprint        = {2610.29989},
  archivePrefix = {arXiv},
  primaryClass  = {cs.CV},
  url           = {https://arxiv.org/abs/2610.29989}
}