
SDVN_Comfy_node
Image processing, segmentation, Florence PromptGen and AI API nodes for ComfyUI
Nodes (136)
Bundle several images into one list output
One dropdown, 184 curated model files
Pull one item out of a list, any type
One text box, four typed outputs
Bundle up to 10 inputs into one list
Duplicate one item into a list of N
A display node for literally any data type
Chatbot (SDVN)
Apply Kontext Reference (SDVN)
Redux image-prompting with masks and downsampling
Auto Generate (SDVN)
Pass through the first input that's actually connected
Boogu Edit TextEncoder (SDVN)
Compare two values, get a true/false to gate your flow
Paste a URL, get a loaded checkpoint
Pick a model from a curated list, it downloads and loads it
Pull a single text encoder from a URL
CLIP Text Encode (SDVN)
Your Reference Photos Go In Through the Text Encoder
Positive-only encoding with translate, styles, and dynamic prompts
CLIPVision Download (SDVN)
The whole ControlNet flow in one node
Fetch a ControlNet model straight into your graph
Crop to an aspect ratio without distorting anything
Generate with OpenAI's DALL-E 3 from inside ComfyUI
A lookup table that turns an input into a mapped output
DiffsynthControlNet Apply (SDVN)
Structural control the DiffSynth way
The half that reads your prompt
The segment node you actually wire into a real workflow
Load two text encoders for Flux, SD3 and friends
Build the per-block weight string without counting layers
Pick an aspect ratio, skip the pixel math
Exif check (SDVN)
Toggle whole workflow sections on and off
Flatten a transparent image onto a solid color
Filter List (SDVN)
Mirror or flip an image, horizontally or vertically
Float Slider (SDVN)
Florence PromptGen reads the image and hands you the prompt — no API key in sight
Nano Banana 2 in ComfyUI
Nano Banana Pro (4K, up to 14 refs)
Nano Banana inside ComfyUI
Read a mask's width and height as integers
Stop burning Colab hours after a run
Call Google's Imagen model from ComfyUI with your Gemini key
OpenAI's gpt-image models in ComfyUI
IC Lora Layout (SDVN)
Split IC-LoRA panels back out
Lightroom-style color grading in ComfyUI
Pause the run and pick which images continue
Transfer a color palette between images
Kill the too-clean AI look
ImageGallery (SDVN)
Per-color hue/saturation/lightness grading
Read a file's metadata, EXIF, and size by path
Build labeled comparison grids in ComfyUI
Turn one image into a batch of N
Image Scraper (SDVN)
Read width/height (with a max-size cap)
White Balance (SDVN)
Four inpaint nodes folded into one
Crop tight around a mask, inpaint at full res, stitch back clean
InstantIDModel Download (SDVN)
A drag-to-set integer input for ComfyUI
Flip a mask with one node, and know it's a one-liner
Pull an IPAdapter model from a URL, ready to apply
The tiny node that routes around silent failures
Bundle multiple ControlNet/Style presets into one Auto Generate input
KSampler (SDVN)
Fetch a latent-space upscaler from a URL
Load a model, or download one from a URL, in one node
Pick from a curated list or download on the fly
Pull prompts and parameters straight from a spreadsheet
Load Image (SDVN)
Pull a batch of images from a directory, random or in sequence
Grab one image out of a batch by index
One image loader for folders, URLs, Pinterest and Instagram
Pull an image straight from a link into your graph
A LoRA loader that can download the file for you
Load Lora Filter (SDVN)
Search or scrape Pinterest images straight into a workflow
Read prompts from a .txt file, one line at a time
Compare two values and branch your workflow
Paste multiple inpainted regions back into one image
Download a LoRA and apply it in one node
Read a LoRA's trigger words and training settings from its metadata
Fetch the Gemma text encoder for LTX-2 video
See your mask before you pay for the sampling
Resize and position a subject to sit neatly inside a frame
Split one mask into separate per-area masks
Turn a mask into a colored RGBA overlay
Turn a raw value into a friendly dropdown
A cascading dropdown, main category then sub-choice
Merge Flux (SDVN)
Block-weight merging for SD 1.5's 12 U-Net blocks
Block-weight merging for SDXL's 9 U-Net blocks
Pull one specific field out of an image's embedded metadata
Fp8-convert, strip, or repackage a model file on disk
Write a trigger word, credit, and cover image into a model file
Blend checkpoints (and extract LoRAs) with block control
Fetch a model-patch file straight from a URL
All three Google image tiers behind one dropdown
Alpha-blend two images with one opacity slider
Paint a mask onto an image so you can actually see it
Bundle your wires into one cable to tame a messy graph
Unbundle one value out of a Pipe In cable
Unpack an entire Pipe In bundle in one shot
Four text encoders in one node
The dedicated text encoder for Qwen-Image-Edit workflows
Encode a Qwen-Image-Edit prompt against up to three reference images
Batch out prompt variations with dynamic-prompt syntax
Drop the alpha channel when a node downstream can't handle it
Drop a Python function straight into your workflow
Force a branch to execute without wiring an output
The dropdown that decides how good your mask is
Type “cat”, get a mask — SAM 3.1 with three inputs and no GroundingDINO
Save an image, or a before/after pair
Write, append, or prepend a workflow's text output to a .txt file
One seed value shared across an entire workflow
The all-in-one SAM + GroundingDINO node
One text box, four possible types
A drag-to-set 0–1 float, for when typing decimals is annoying
A 0–100 integer slider for steps, batches, and percentages
Cut an image into overlapping tiles you can process one at a time
Reassemble a tiled image with the seams blended away
Grab a Redux-style model in one node
Stack curated style cards onto your prompt
Pick between two values with a boolean, wire type doesn't matter
Translate (SDVN)
Fetch a diffusion model file and pick its precision
One node for fit, resize, or scale, with an optional real upscale model
Resize in latent space with an optional upscale model
Fetch an ESRGAN upscaler from a URL, ready to use
Grab a VAE from a URL and load it in one node
Point a YOLOv8 model at an image, get a mask back
SDVN Comfy Node
Smart node set, supporting easier and more convenient ways to use ComfyUI
Overview
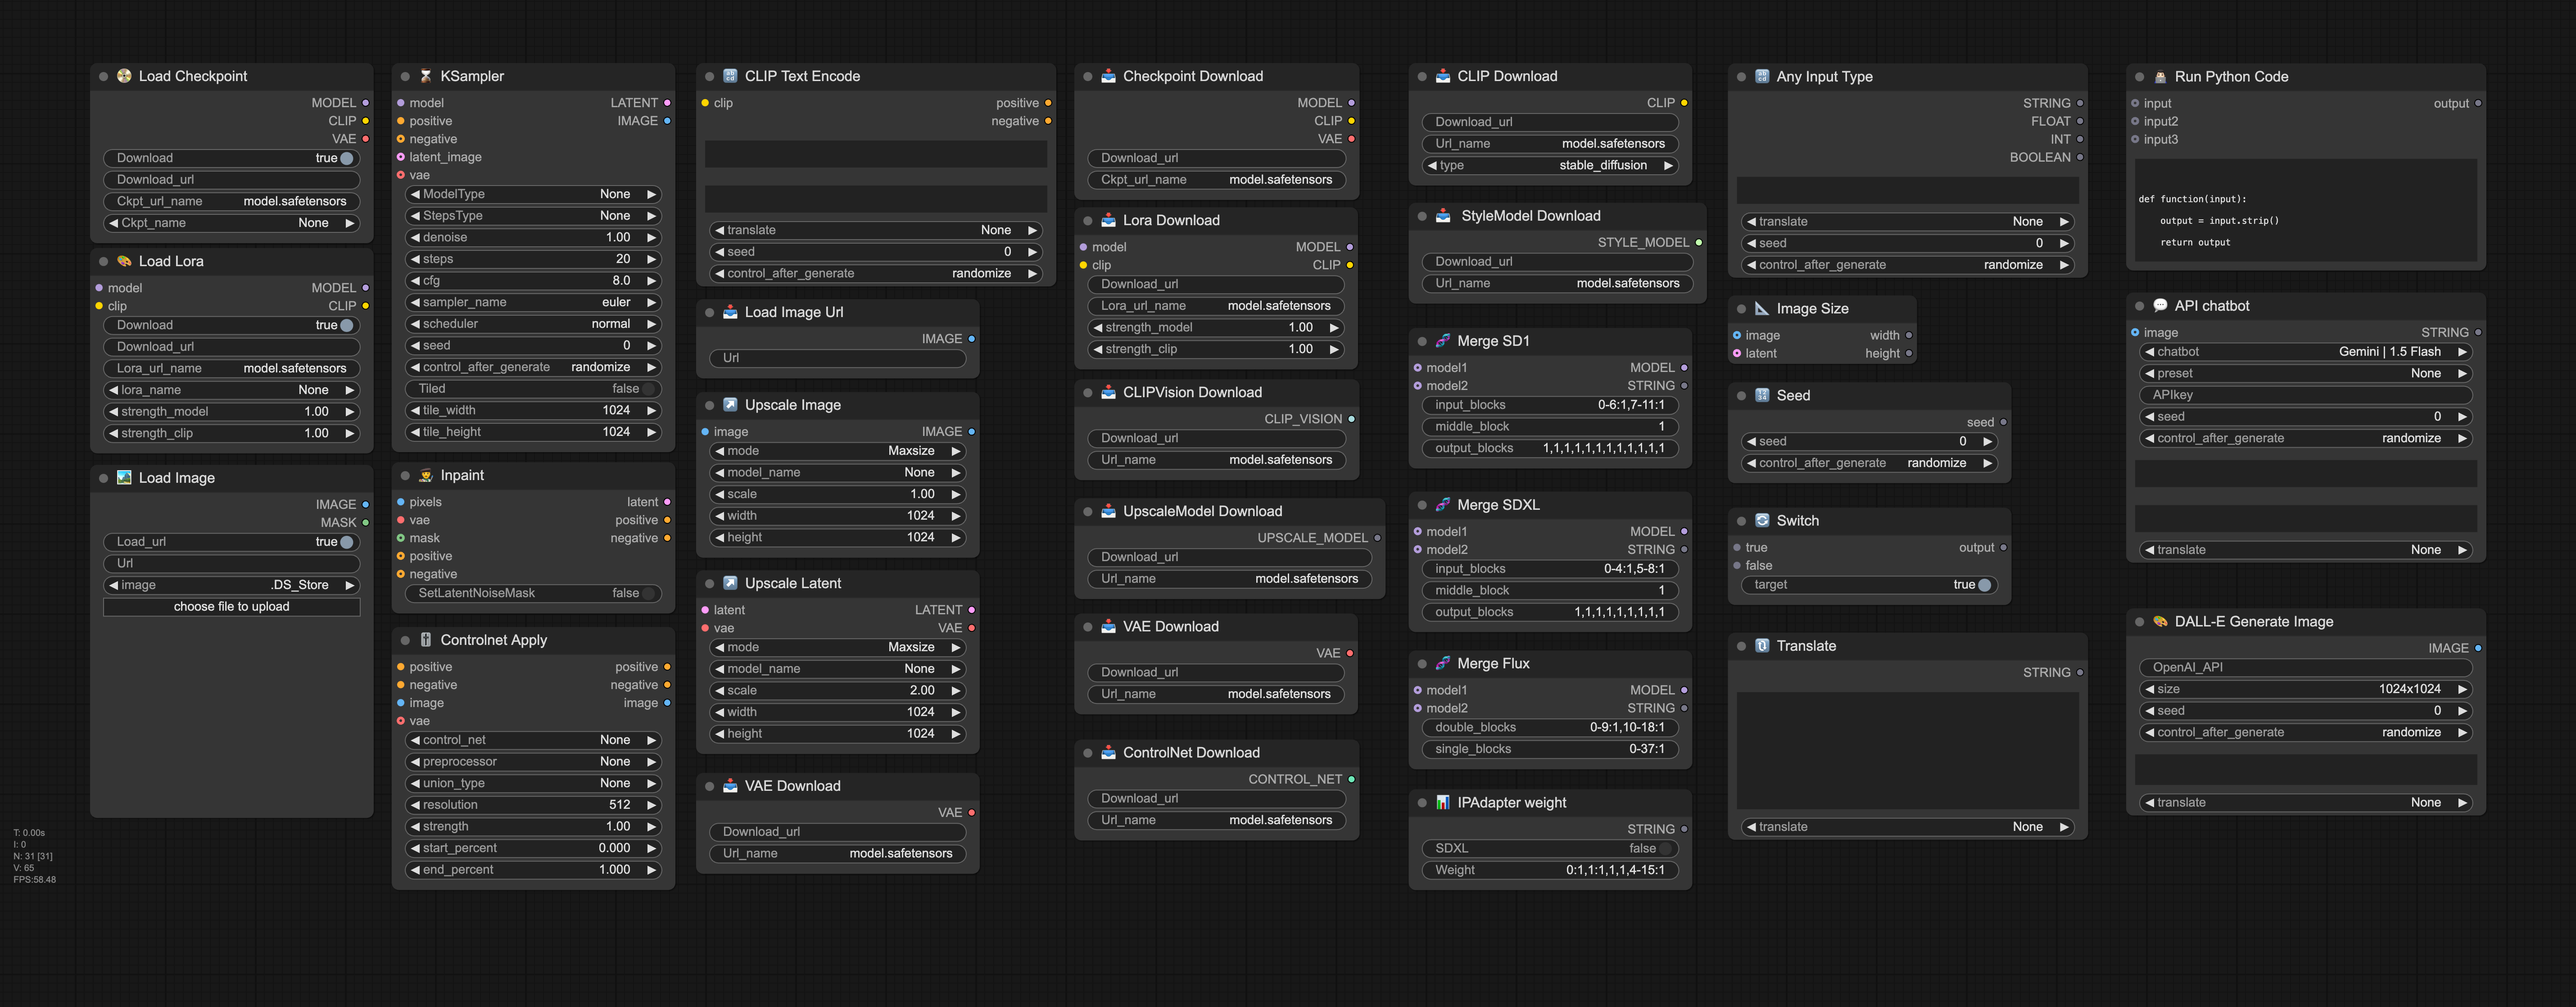
- A full toolkit of smart ComfyUI nodes covering loading/downloading, merging, masks, layouts, and API-based generation for SD15, SDXL, Flux, and more.
- Built-in conveniences: auto model-type detection (CFG/sampler/scheduler), translation + dynamic prompt support across text fields, ControlNet/Apply Style presets, and curated model/style libraries (
model_lib*.json,lora_lib.json,styles.csv). - Download helpers for checkpoints, LoRA, ControlNet, upscalers, IPAdapter/InstantID, and image sources (Pinterest/URL/Instagram) with aria2c acceleration when available.
- Utilities for metadata inspection/editing, streamlined wiring (Pipe/Switch/Any nodes), mask tools, and API nodes for Gemini, OpenAI, Hugging Face, and Deepseek.
- Workflow examples live in the
examplesfolder; preview images are inpreviewto quickly show what each node set does.
Todo
- [x] Workflow Example
- [x] Guide
- [x] Install
Quick start
- Clone into
custom_nodes, then install Python deps from the ComfyUI root:pip install -r custom_nodes/SDVN_Comfy_node/requirements.txt - macOS/Windows: install
aria2cmanually for download nodes. - (Optional) Rename
API_key.json.exampletoAPI_key.jsonand fill in keys; copymy_styles.csv.exampletomy_styles.csvto customize style presets. - Start ComfyUI — nodes appear under SDVN categories; recommended companion nodes are listed below.
Install
Install with simple commands:
cd <ComfyUI folder path>/custom_nodesgit clone https://github.com/StableDiffusionVN/SDVN_Comfy_node- From your ComfyUI root, install dependencies:
pip install -r custom_nodes/SDVN_Comfy_node/requirements.txt - For Windows or macOS machines, users are required to manually install
aria2cin order to use nodes that automatically download models.
Also you should install the following nodes to be able to use all functions:
Guide
- For all nodes with download: Supports direct download from civitai and huggingface with model address link and model download link
- For all dodes load photos with the URL: Automatically download photos to the url of the image. Can automatically search for the highest quality image with the Pinterest link . See also the support list
- For all nodes capable of entering the text: Support Google Translate and Dynamic Prompt function ((Wildcards folder: /ComfyUI/wildcards))
BaseNode
A collection of smart nodes that replace basic tasks, helping users build processes smarter and faster
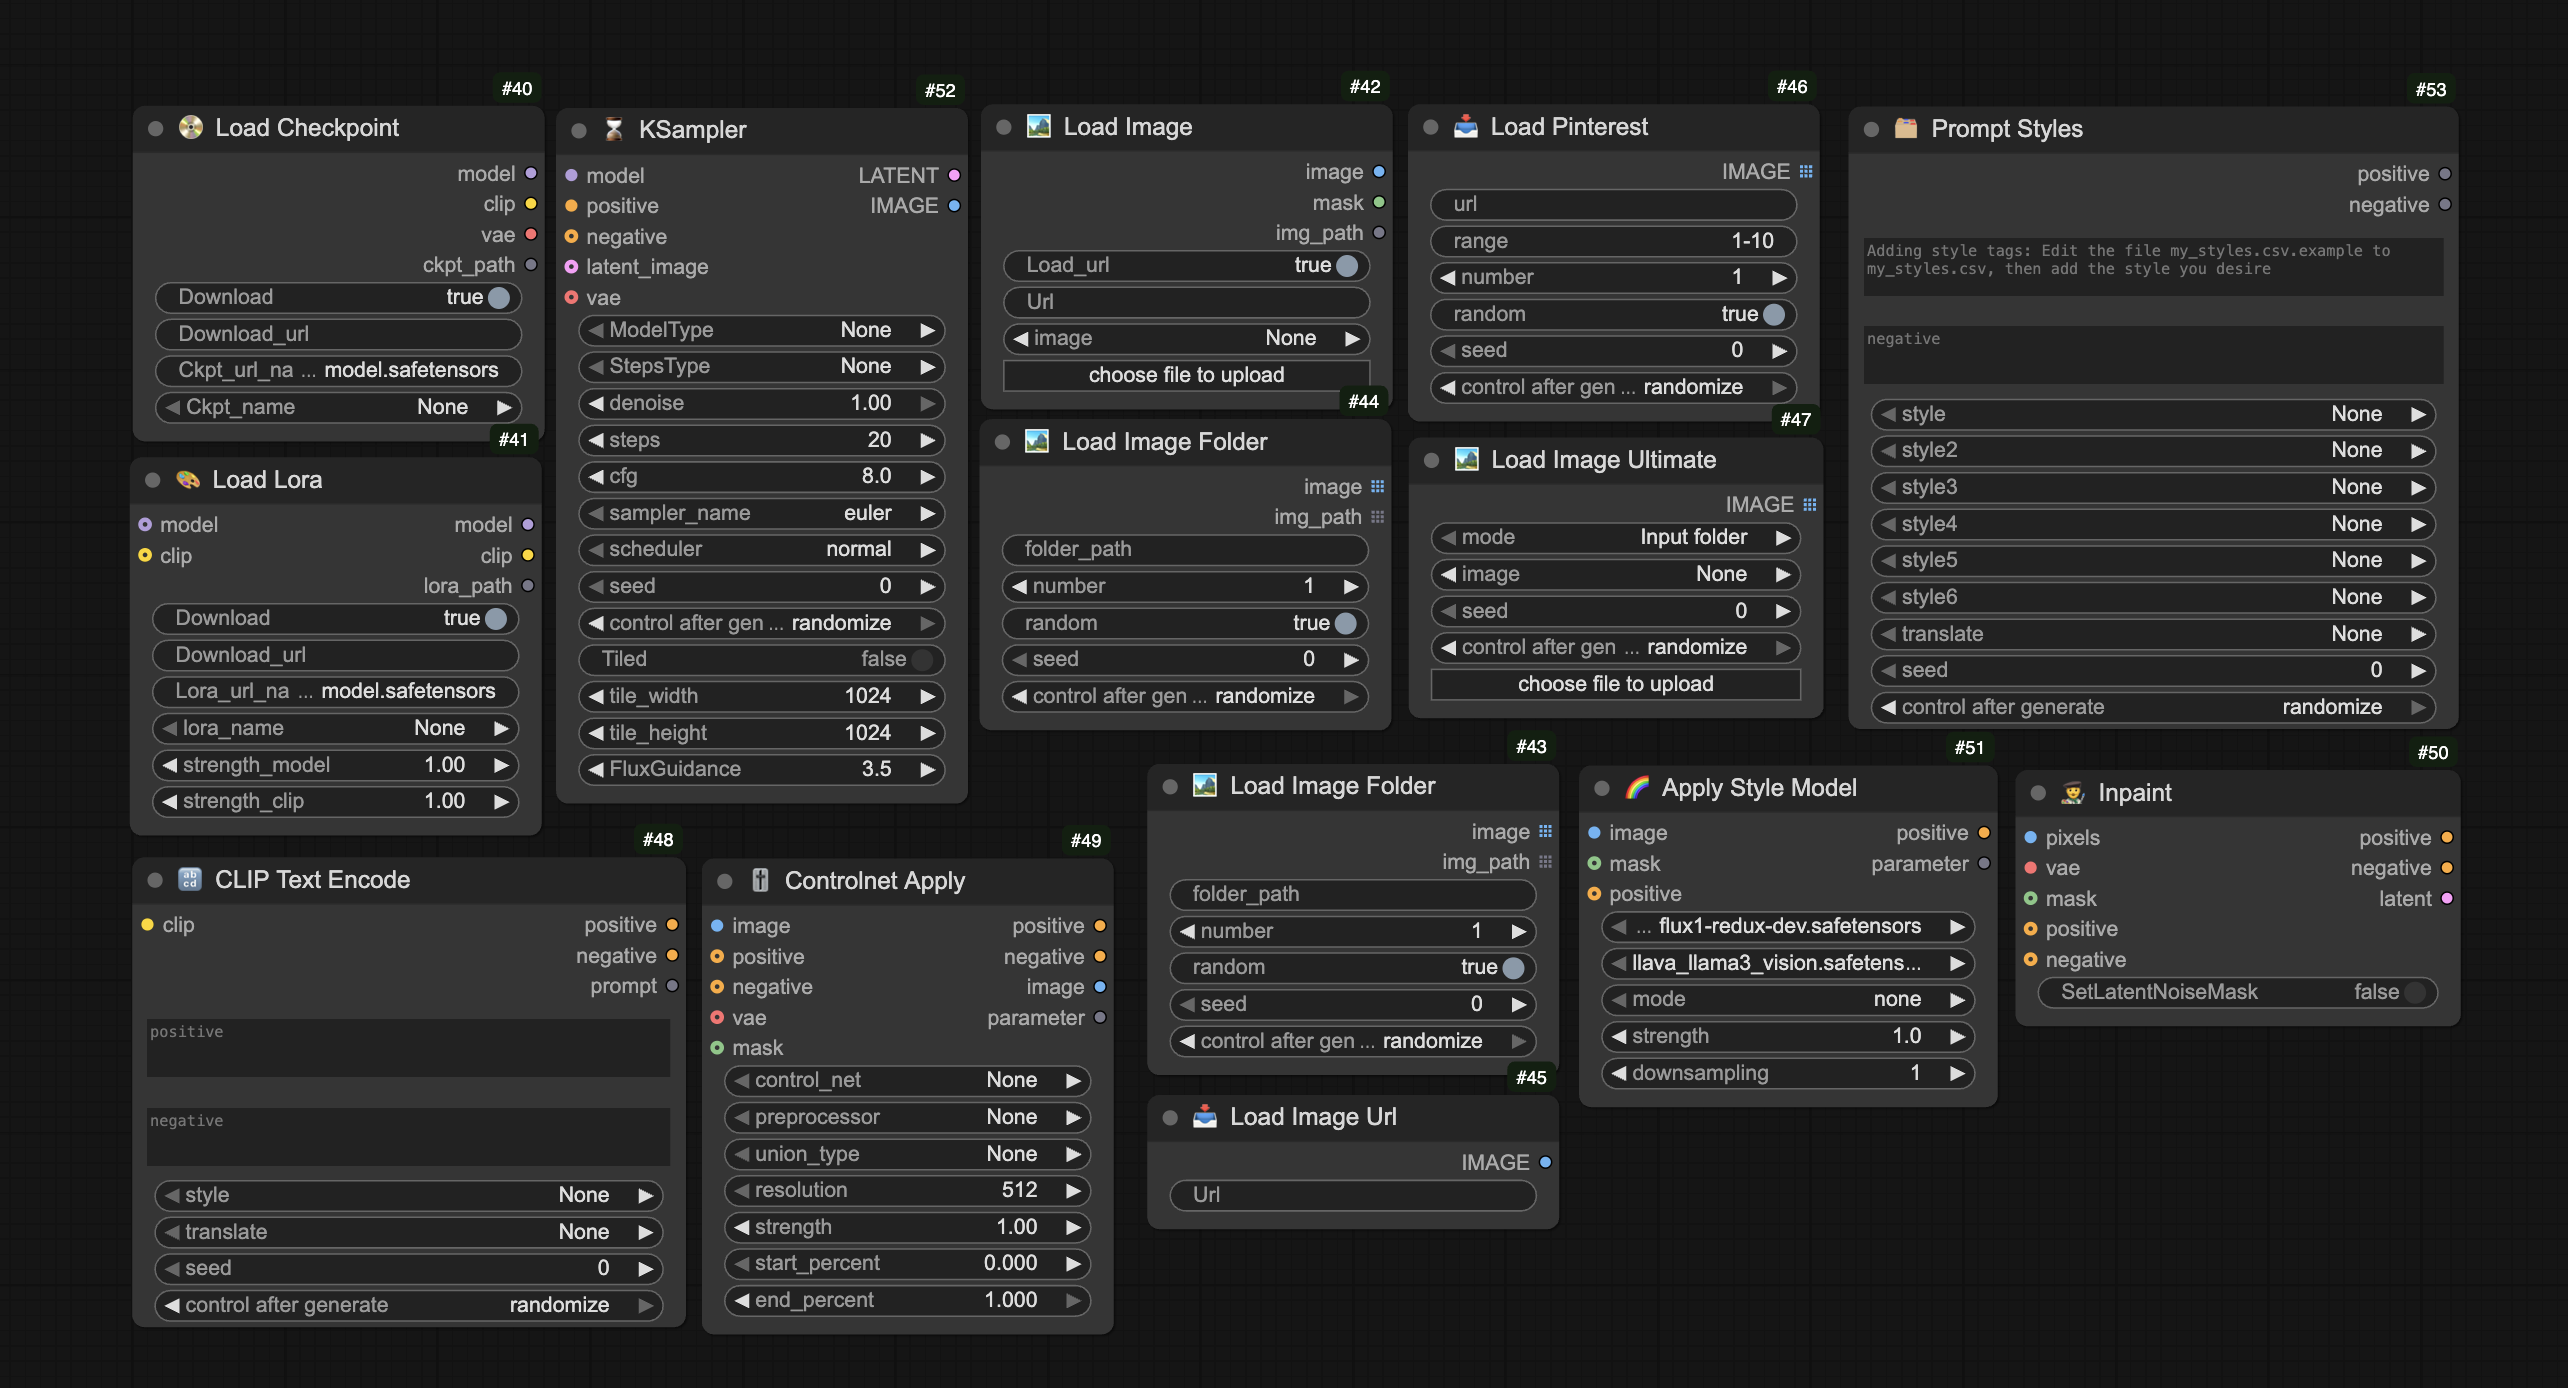
📀 Load checkpoint / 🎨 Load Lora
Supports 2 methods of loading checkpoint and downloading checkpoint directly for use.
- If you leave the Download_url information, checkpoint will be selected according to the Ckpt_name
- If you enter the checkpoint download url and leave the Download - True option, the checkpoint will be downloaded to checkpoints/loras folder and named Ckpt_url_name
Additionally, these two nodes support a curated list of commonly used checkpoints and LoRAs. If the models are not already available in the folder, they will be automatically downloaded.
🏞️ Load Image / 🏞️ Load Image Url
- Support 2 images download methods from input folders and URL links / Image Path
- Support sub-folders in the input folder
🏞️ Load Image Folder
- Load a list with number images from a folder.
- If random = True, the images will be completely random; otherwise, they will be a sequence of images that are adjacent to each other.
- If
number < 1, the entire folder of images will be loaded.
🏞️ Load Pinterest
Automatically search and download images from Pinterest. Images will be automatically downloaded to the input folder, organized into separate subfolders.
- Url:
-
Accepts any Pinterest image link (single image, board, board section, or profile page) (e.g., https://www.pinterest.com/...). If the link starts with a slash /, the prefix https://www.pinterest.com will be automatically added (e.g., /abc/vintage ⇨ https://www.pinterest.com/abc/vintage).
-
Accepts any keyword and will automatically search for images on Pinterest using that keyword.
-
- Range: Location – Number of images that will be downloaded to the input folder.
- Number: The number of images that will be loaded and returned. If random = True, the images will be randomly selected from the downloaded list; otherwise, the images will be selected based on their position determined by the seed.
🏞️ Load Image Ultimate
This is a powerful node that combines 5 different loading modes (Input Folder, Custom Folder, Pinterest, Insta, URL) to enhance flexibility in workflows. The options will automatically adjust based on the selected mode, and the usage is similar to the corresponding image loading nodes above.
🔡 CLIP Text Encode
- Simultaneously support both Positive, Negative
- Support Random ability with Dynamic Prompt (Request installed node Dynamicprompts)
- Support Translate function
- Support Style Card.
- Includes helper text encoders for advanced models: Qwen Edit Text Encoder / Plus and Kontext Reference (pass reference images/masks into conditioning/latent).
🗂️ Prompt Styles
- Supports easier prompt writing with pre-saved and curated style presets.
- You can add or edit style cards by renaming and modifying the file my_styles.csv.example to my_styles.csv.
🎚️ Controlnet Apply
Provide full option to use ControlNet in a single node (Request installed node Controlnet Aux)
- Can choose Controlnet Model, Preprocessor (Automatically detect Aux Preprocessor Aux Preprocessor + Add Invert Image option), Union Type
- Show preview pictures Preprocessor when running
- Supports automatic downloading of most popular ControlNet models for SD15, SDXL, and Flux.
- Supports direct usage with ControlNet Inpaint Alimama Flux.
- Supports exporting parameters for integration with the AutoGenerate node.
- Extras: Diffsynth Controlnet Apply and Diffsynth Union Lora Apply for users who work with Diffusynth workflows.
🌈 Apply Style Model
- Supports automatic downloading of style and CLIP models
- Supports working with masks, downsampling, and various crop modes (Note: these features may not work well with Redux 512). (See more in Redux Adv: https://github.com/kaibioinfo/ComfyUI_AdvancedRefluxControl)
⏳ Ksampler
Smart node with many quick options to support flexibly in many different cases, help minimize errors and more flexibility to use.
- Convert 2 options for negative and latent to optional.
- Without Negative, an empty clip will be replaced, now the way to connect to Flux will be in accordance with its nature - is not to use Negative
- Without Latent, an empty Latent image will be created according to the size of Tile Width and Tile Height
- ModelType: Automatically adjust CFG, Sampler name, Scheduler for different types of models (SD15, SDXL, SDXL lightning, SDXL hyper, Flux ...). Now it is not a headache when it is too much.
- StepsType: Automatically adjust Steps according to the model and by Denoise ( Steps = Standing Steps x Denoise). Helps optimize the accurate and fastest process
- Tiled: Automatically divide the tiled block by mixture of differenters to minimize GPU when running Ksampler, applied in case of large image size and baby denoise (Request installed node TiledDiffusion). In case there is no latent, size tile = tile_width/2, tile_height/2
- Support FluxGuidance
👨🎨 Inpaint
A comprehensive Inpaint support, consolidated from 4 Node Vae Encode, Latent Noise Mask, Vae Encode (For Inpainting), InpaintModelCondinging
- Vae Encode: If Mask = None
- Vae Encode (For Inpainting): If Postive or Negative = None
- Latent Noise Mask: If SetLatentNoiseMask = True
- InpaintModelCondinging: If SetLatentNoiseMask = False, all Image, Vae, Postive, Negative
Image
Smart node set, support for handling imaging tasks
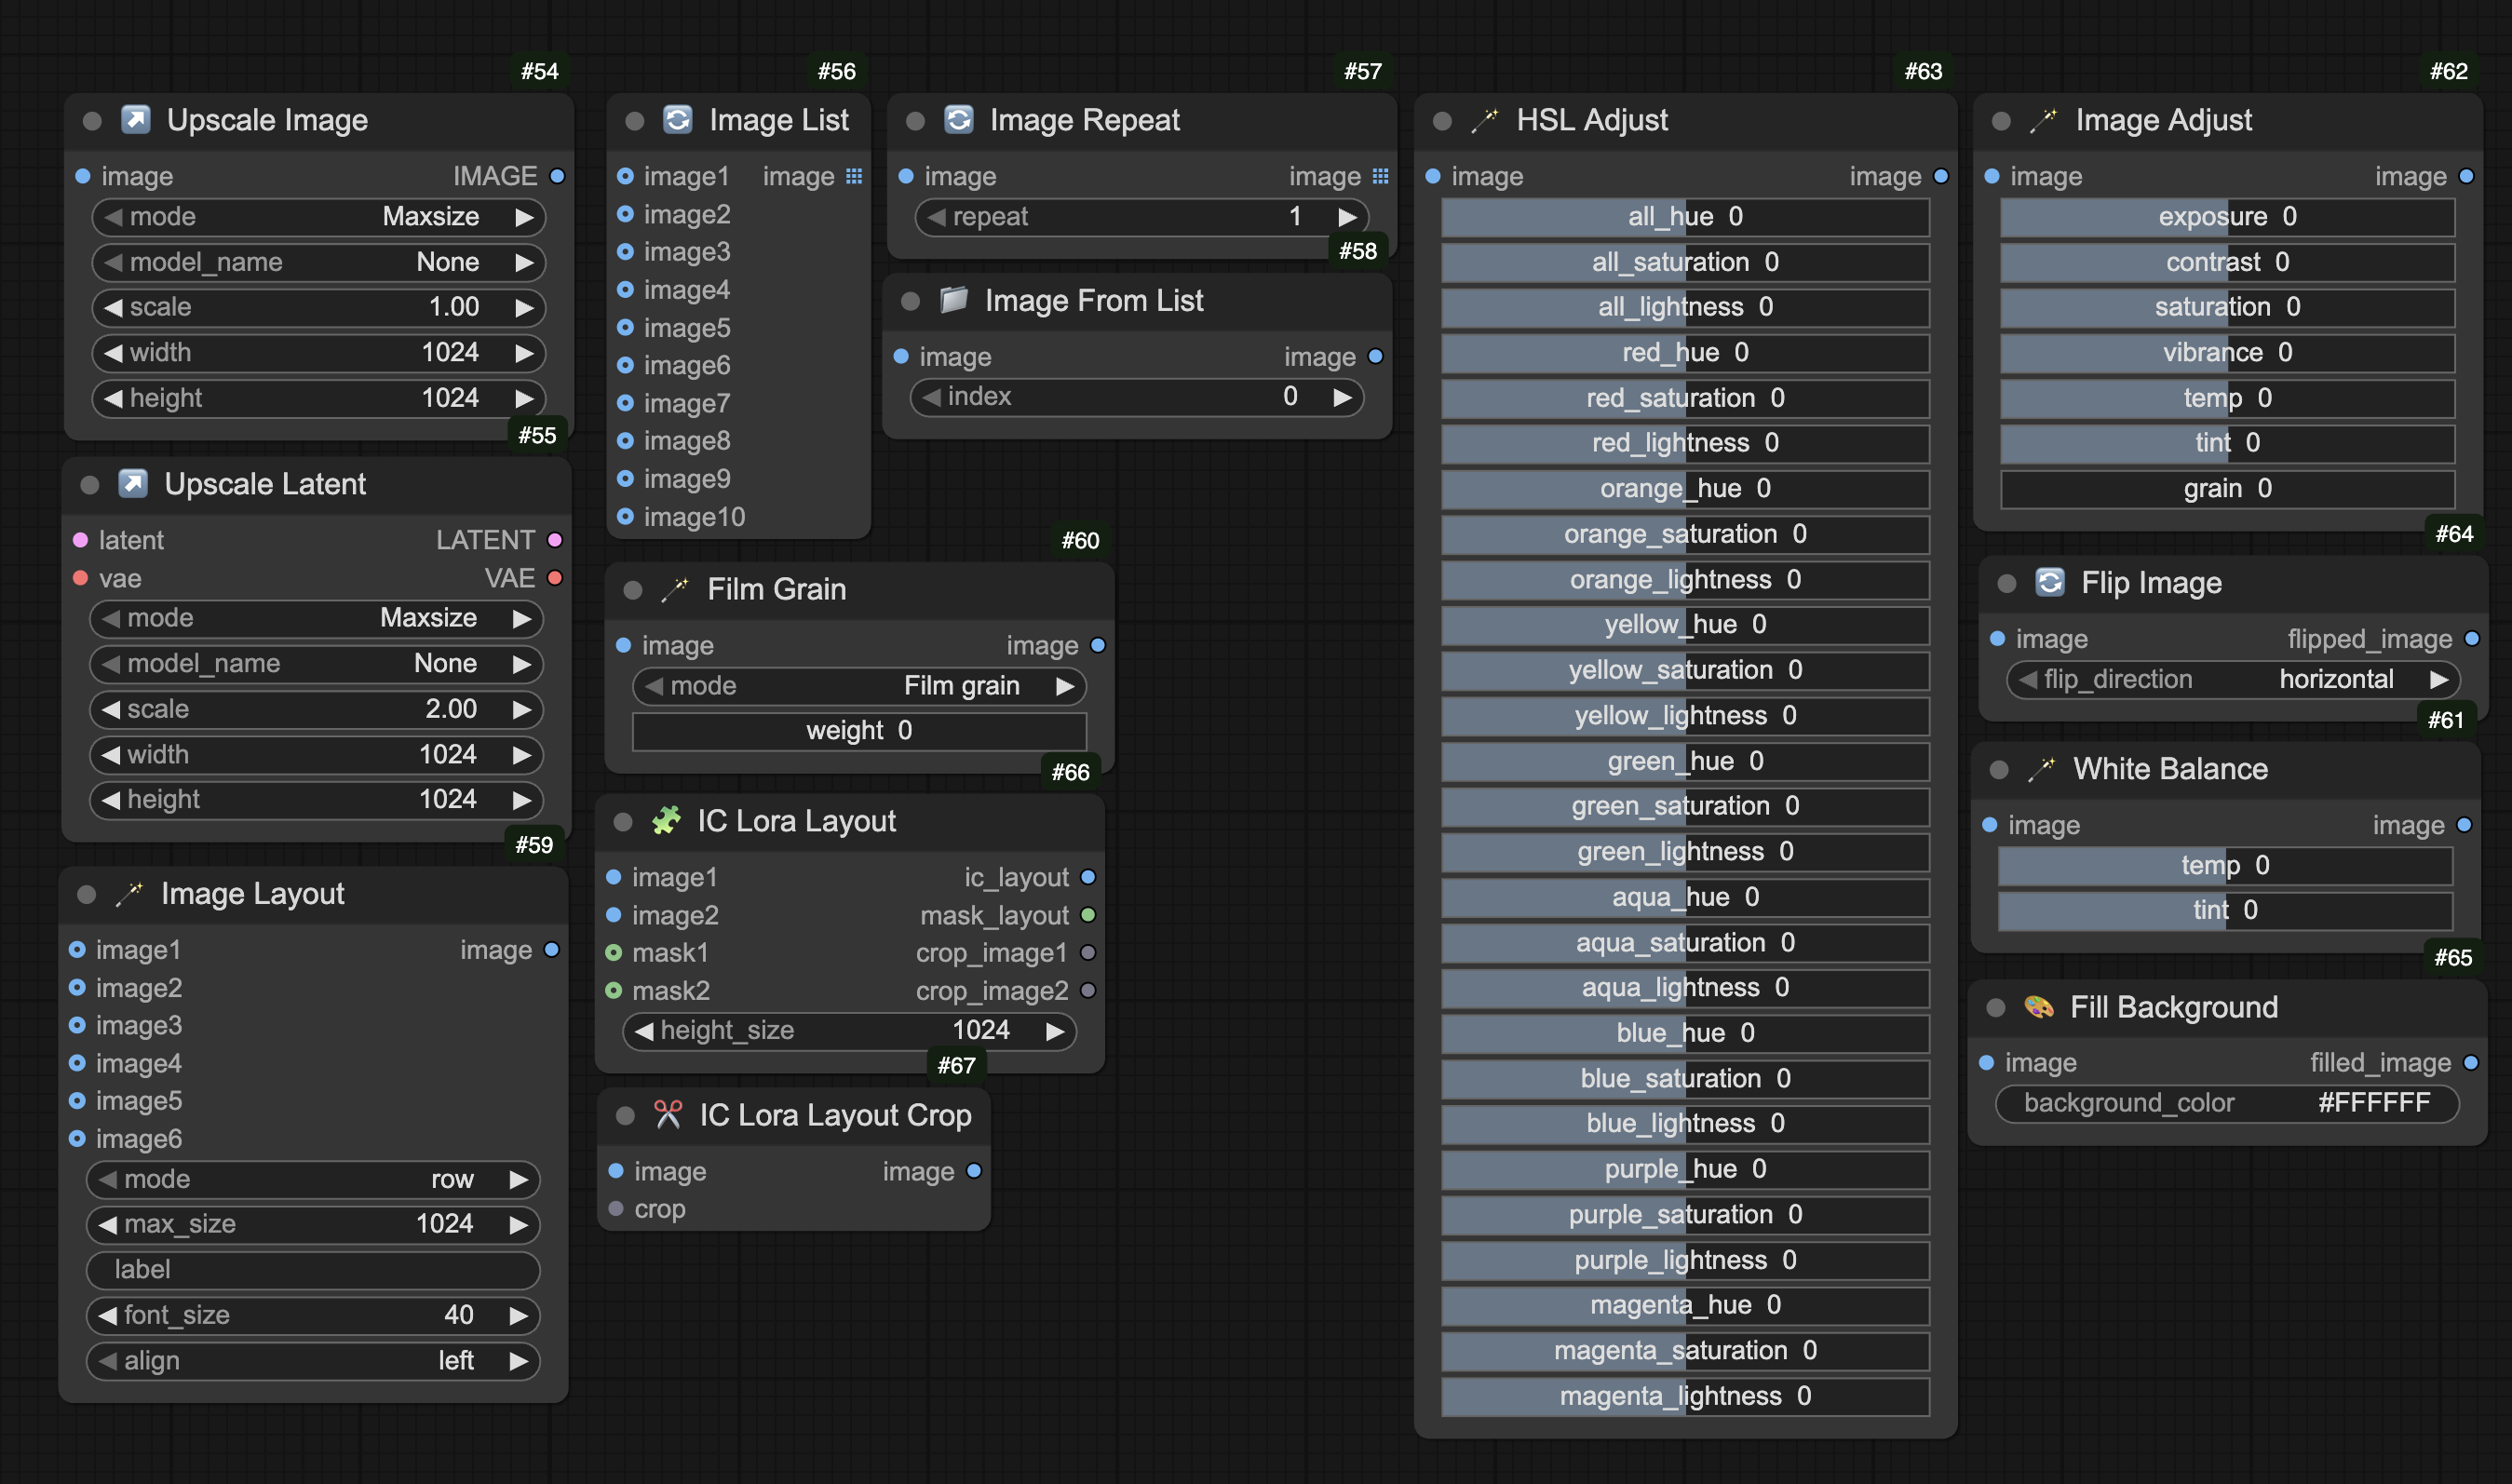
↗️ Upscale Image
Smart Resize and Scale image
- Maxsize mode: Automatically calculate and adjust the image size so as not to change the ratio and do not exceed the required size
- Resize mode: Automatically resize the required size
- Scale mode: Calculate the image size according to the *scale index
- Model_name options will use Model Upscale according to the option, helping to keep more details when upscale
- Supports automatic downloading of popular upscale models.
↗️ Upscale Latent
Similar to Upscale Image, but will add Vae Decoder and Vae Encoder to process Latent images, helping the process more neat.
🔄 Image List
Combine individual images into a list image
🔄 Image Repeat
Repeat an image to create a list.
📁 Image From List
Filter out a single image from the list at the specified index.
🪄 Film Grain / 🪄 HSL Adjust / 🪄 Image Adjust / 🪄 White Balance
Nodes for adjusting lighting, colors, and applying effects to images.
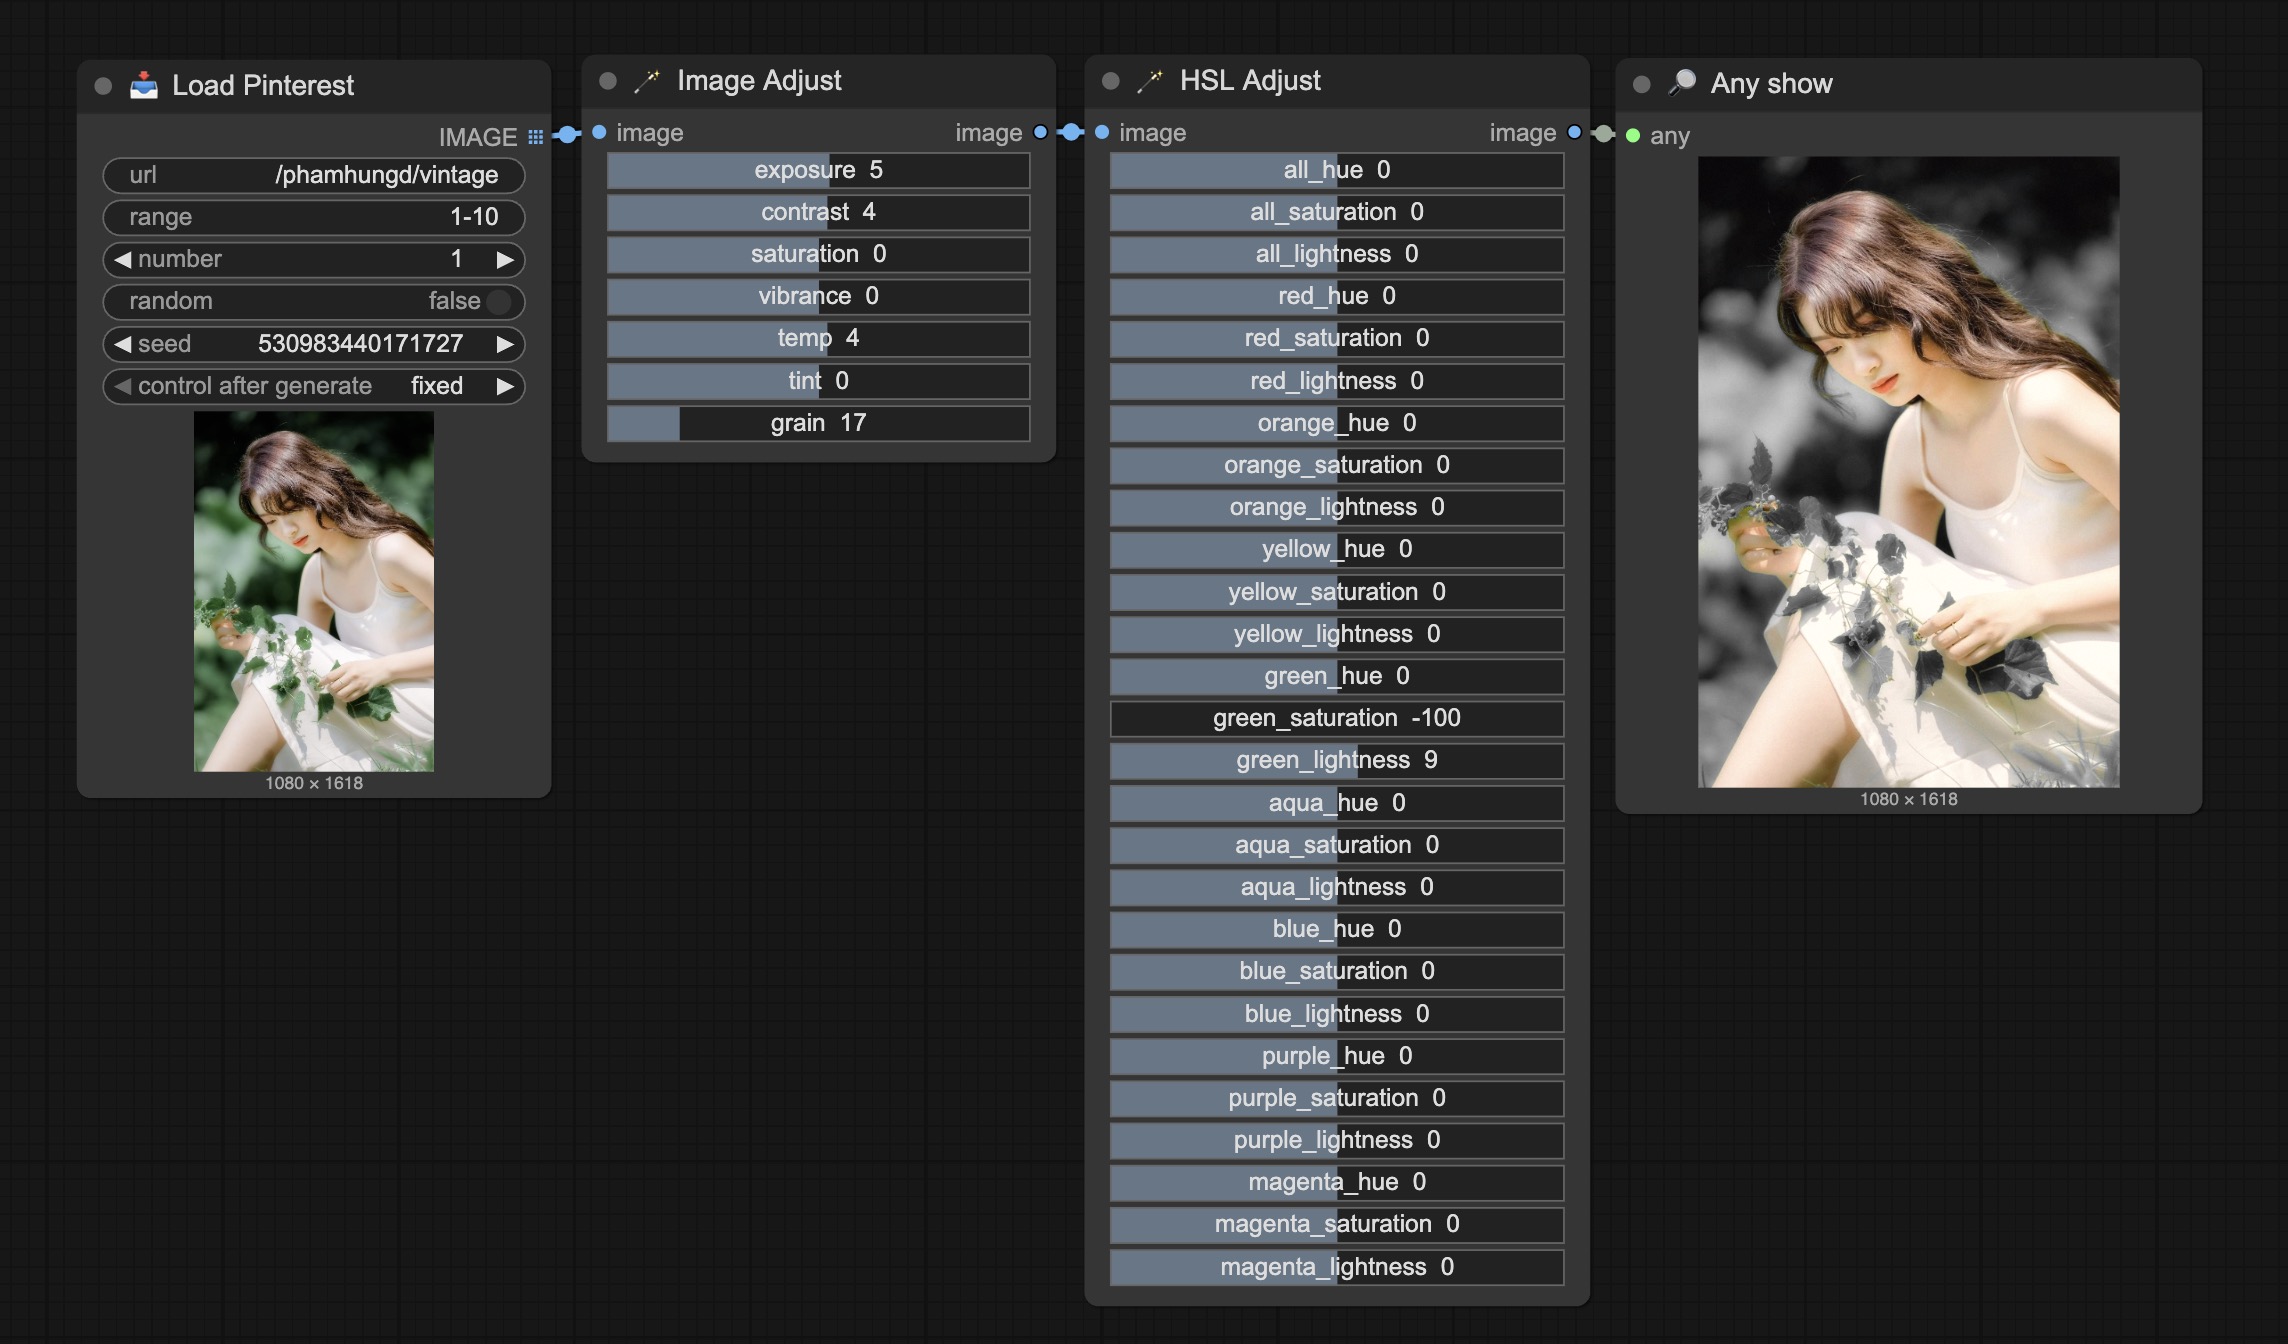
🔄 Flip Image
Flip the image horizontally or vertically.
🎨 Fill Background
Fill the transparent areas of an image (with an alpha channel) with a solid color.
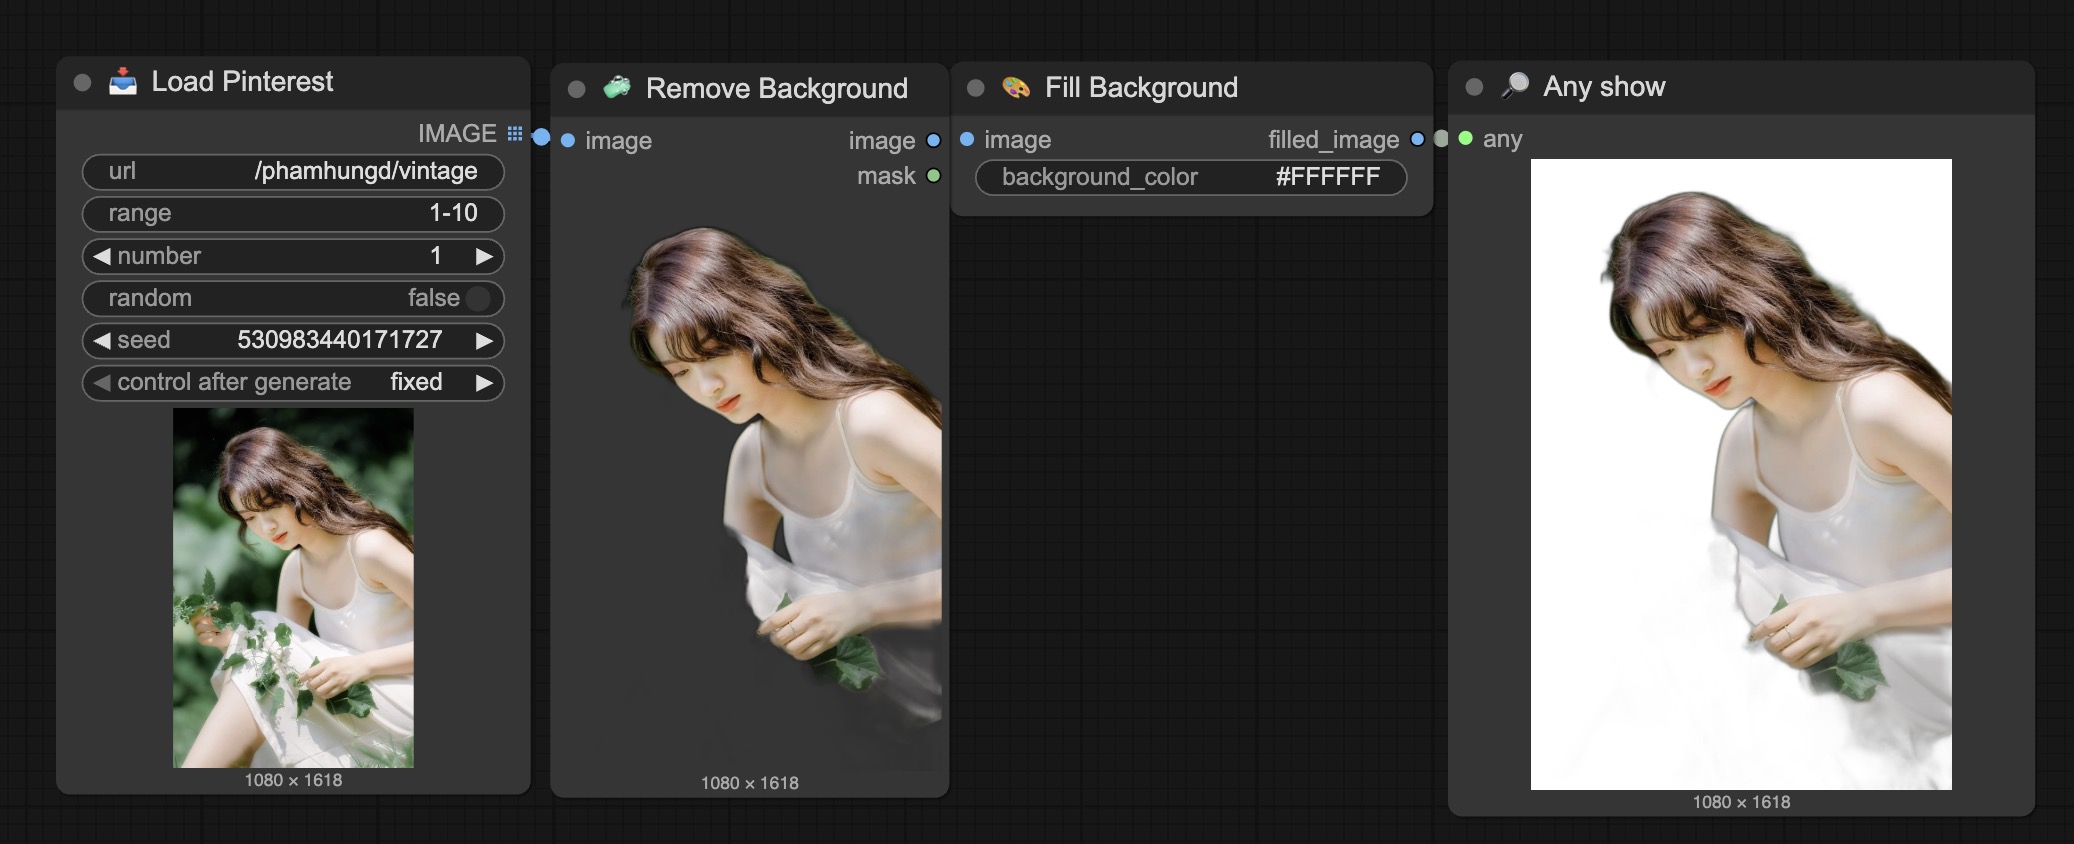
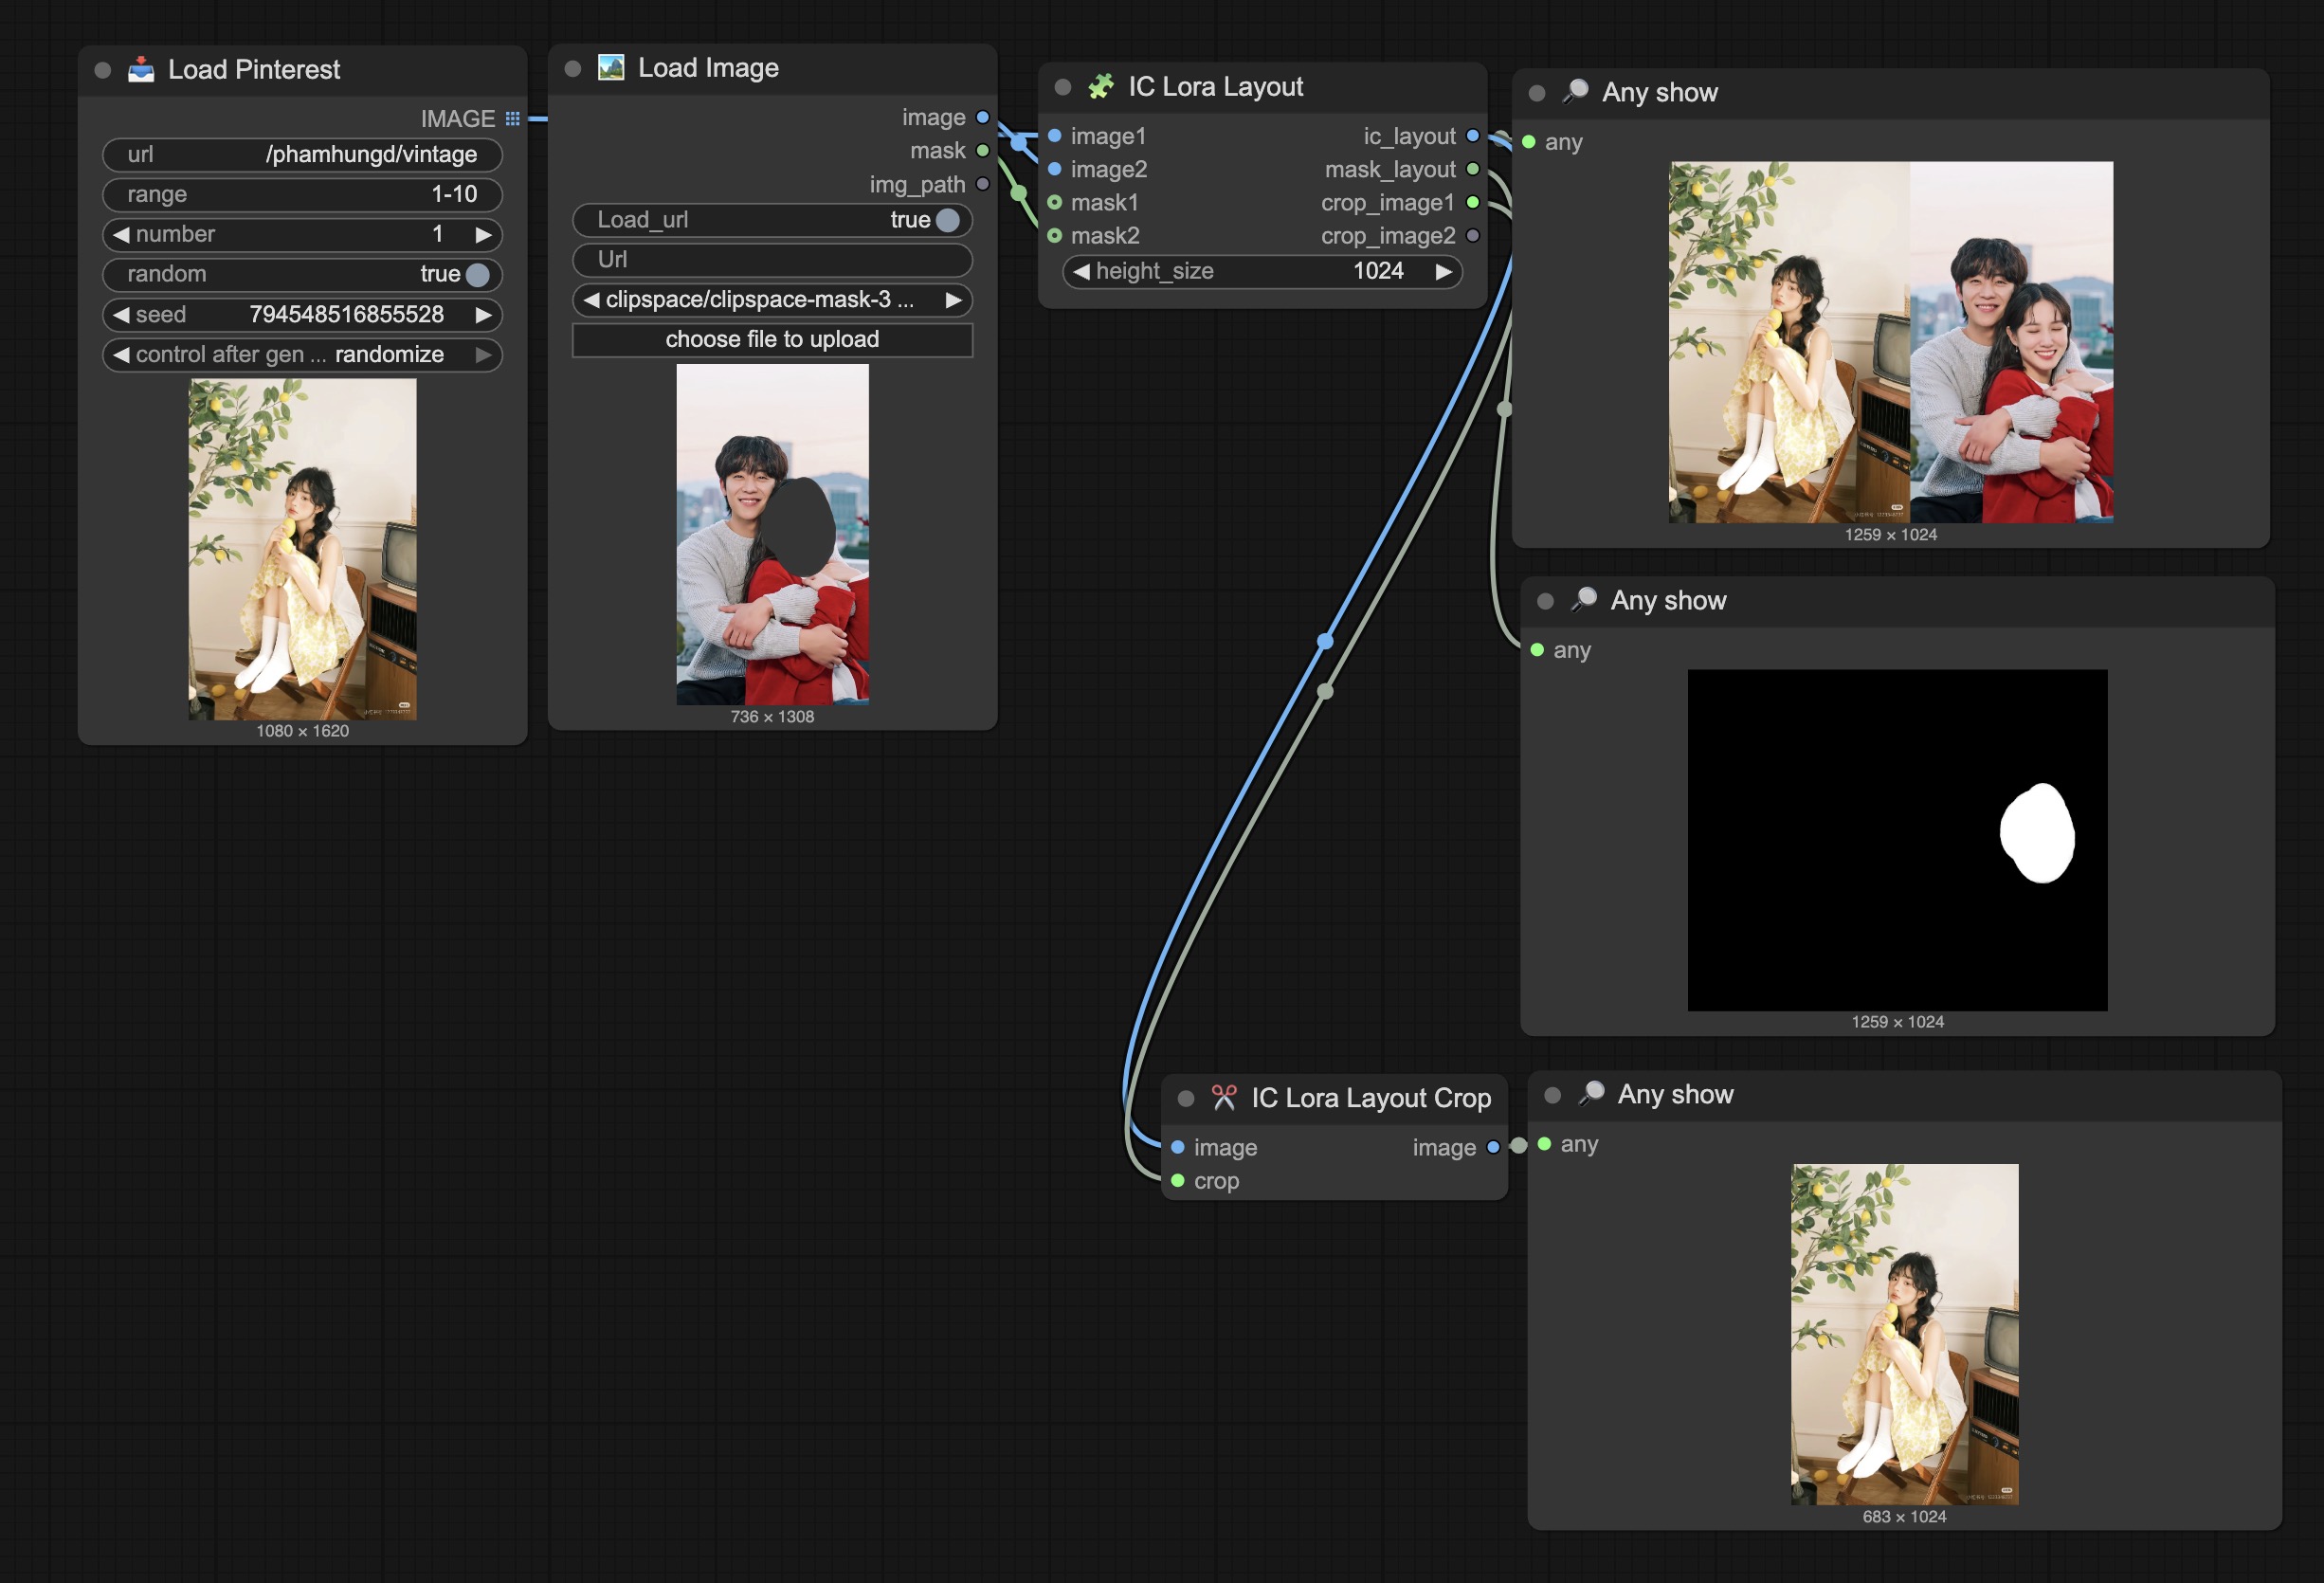
🧩 IC Lora Layout | ✂️ IC Lora Layout Crop
A set of nodes that supports layout creation and image cropping/splitting when used with IC Lora
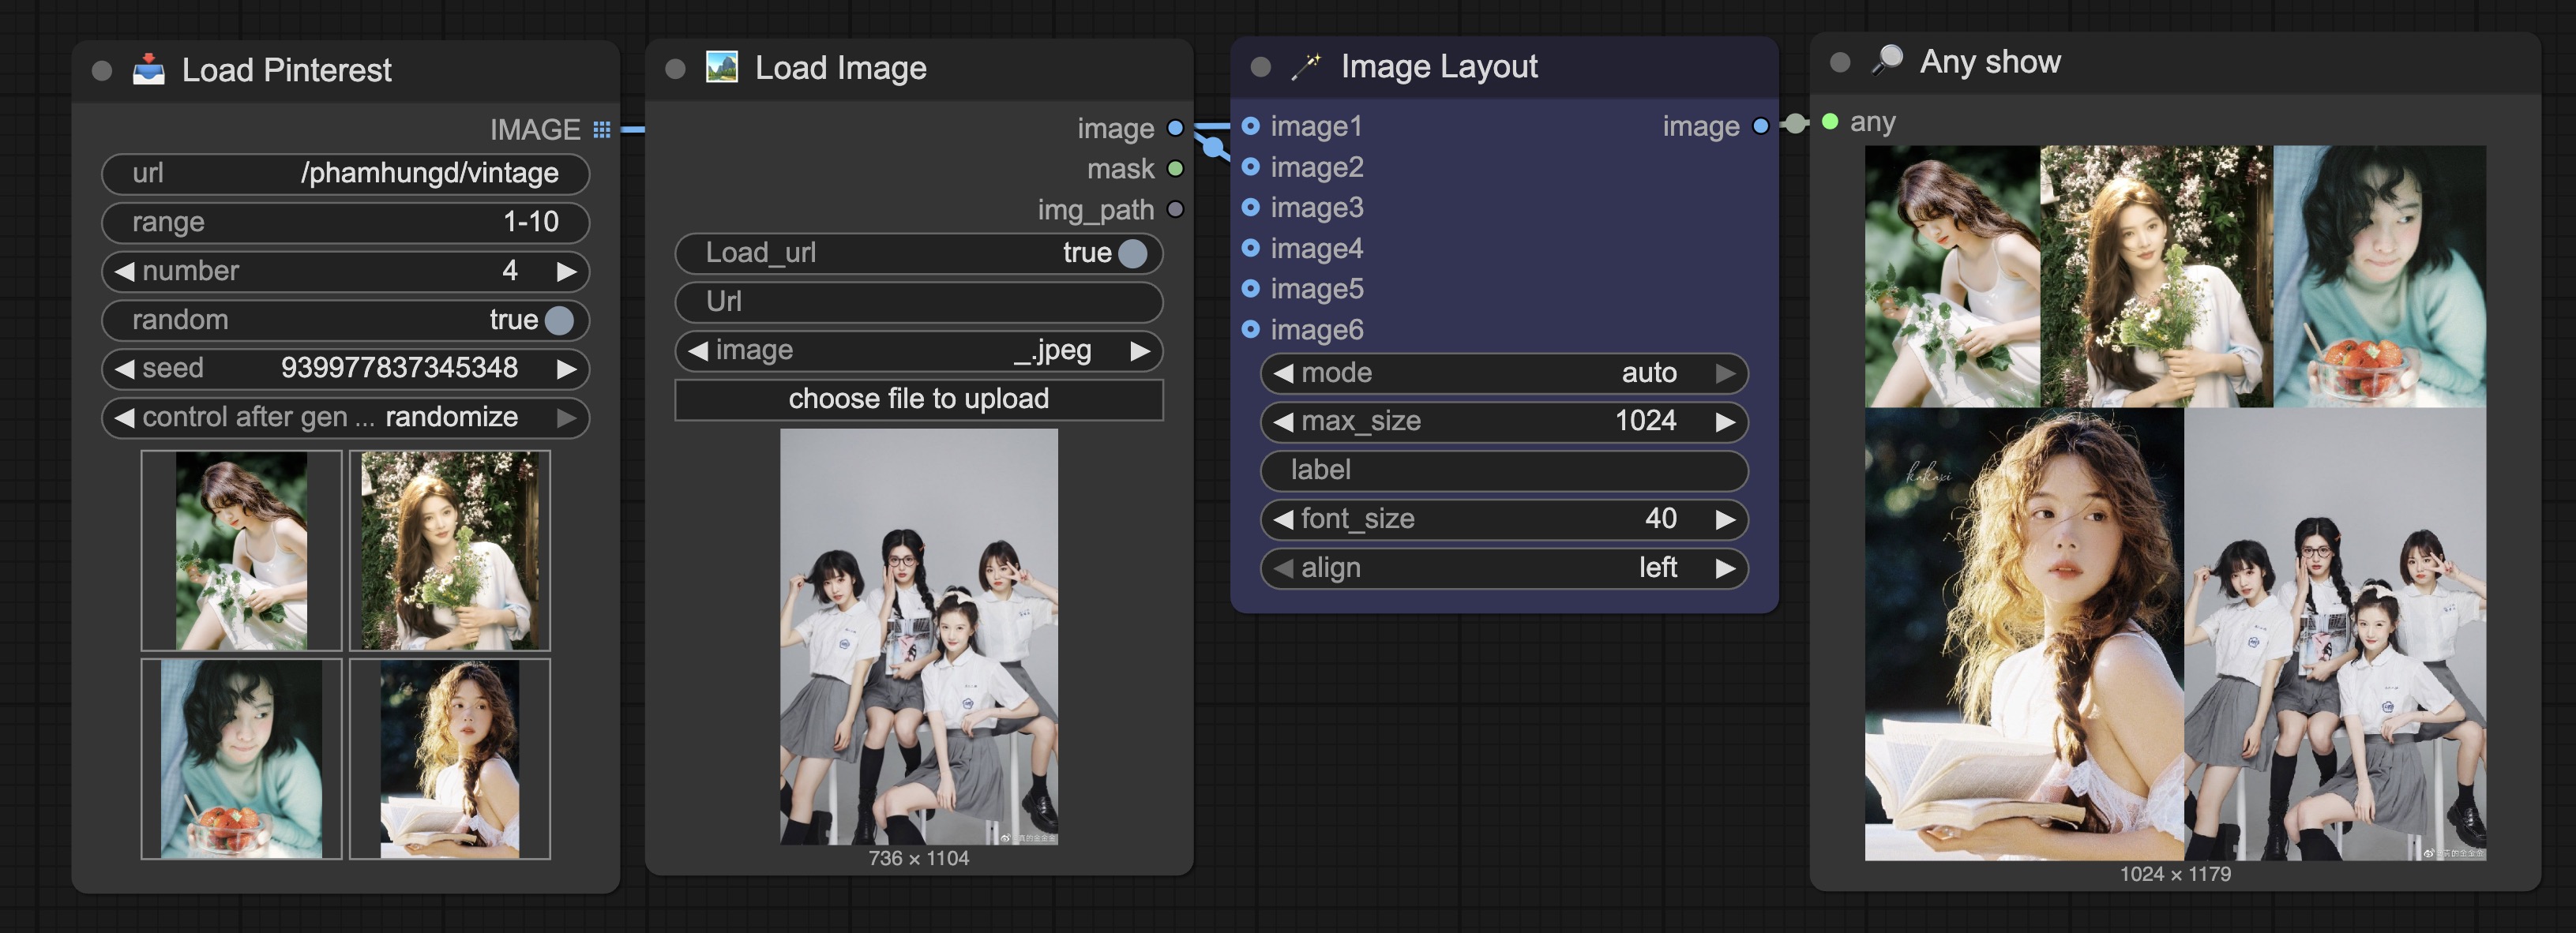
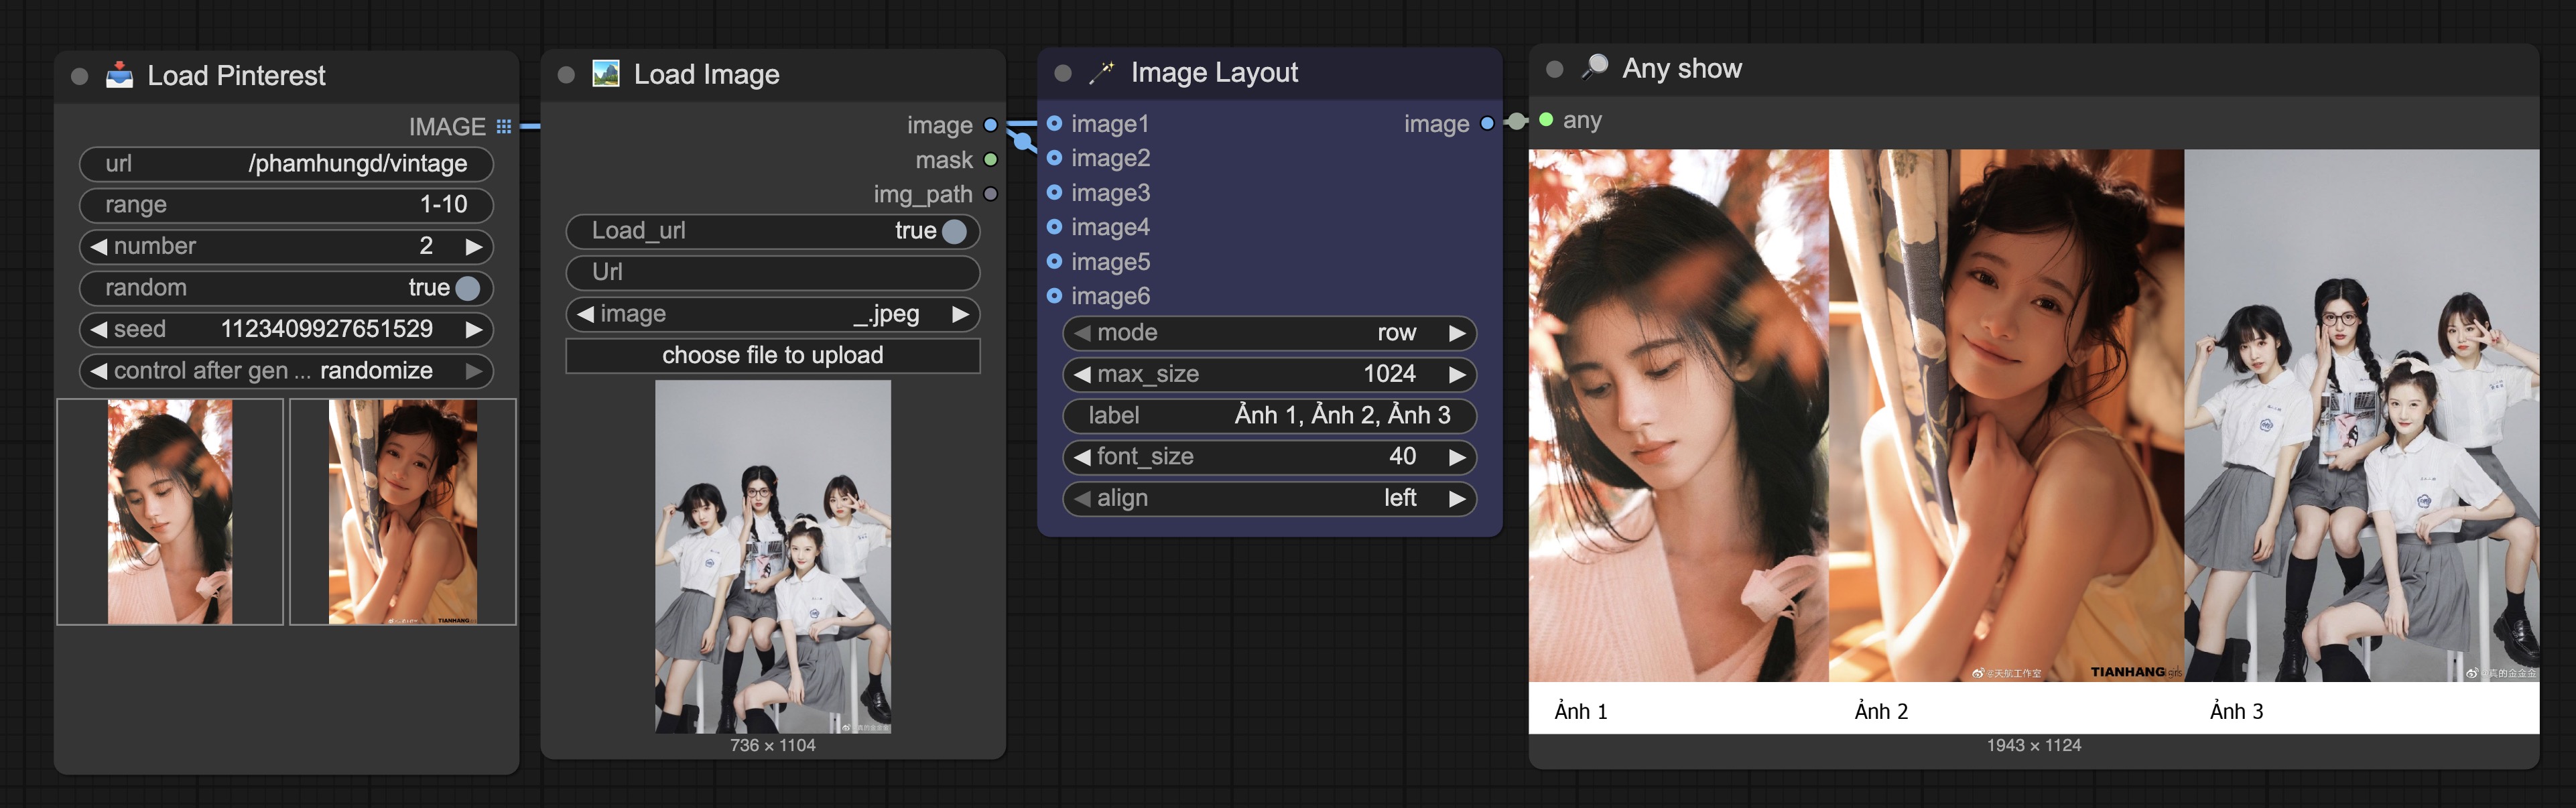
🪄 Image Layout
A node that intelligently arranges image layouts with various flexible modes, helping to create clearer previews within the workflow
⏬️ Image Scraper
- Download images from websites using gallery-dl.
✂️ Crop By Ratio | 🔄 RGBA to RGB | ⚡️ Empty Latent Ratio
- Utilities for cropping by aspect ratio, converting color mode, and creating blank latent images.
🧅 Overlay Two Images | 🎭 Mask → Transparent Color | 🧩 Overlay Mask Color on Image
- Blend images and visualize masks with custom colors.
🖼️ Save Image Compare
- Save before/after pairs side-by-side for quick QA within a workflow.
🖼️ Image Gallery
- Browse, paginate, and download/collect images (local or remote/pinterest/URL) into a gallery with temp caching.
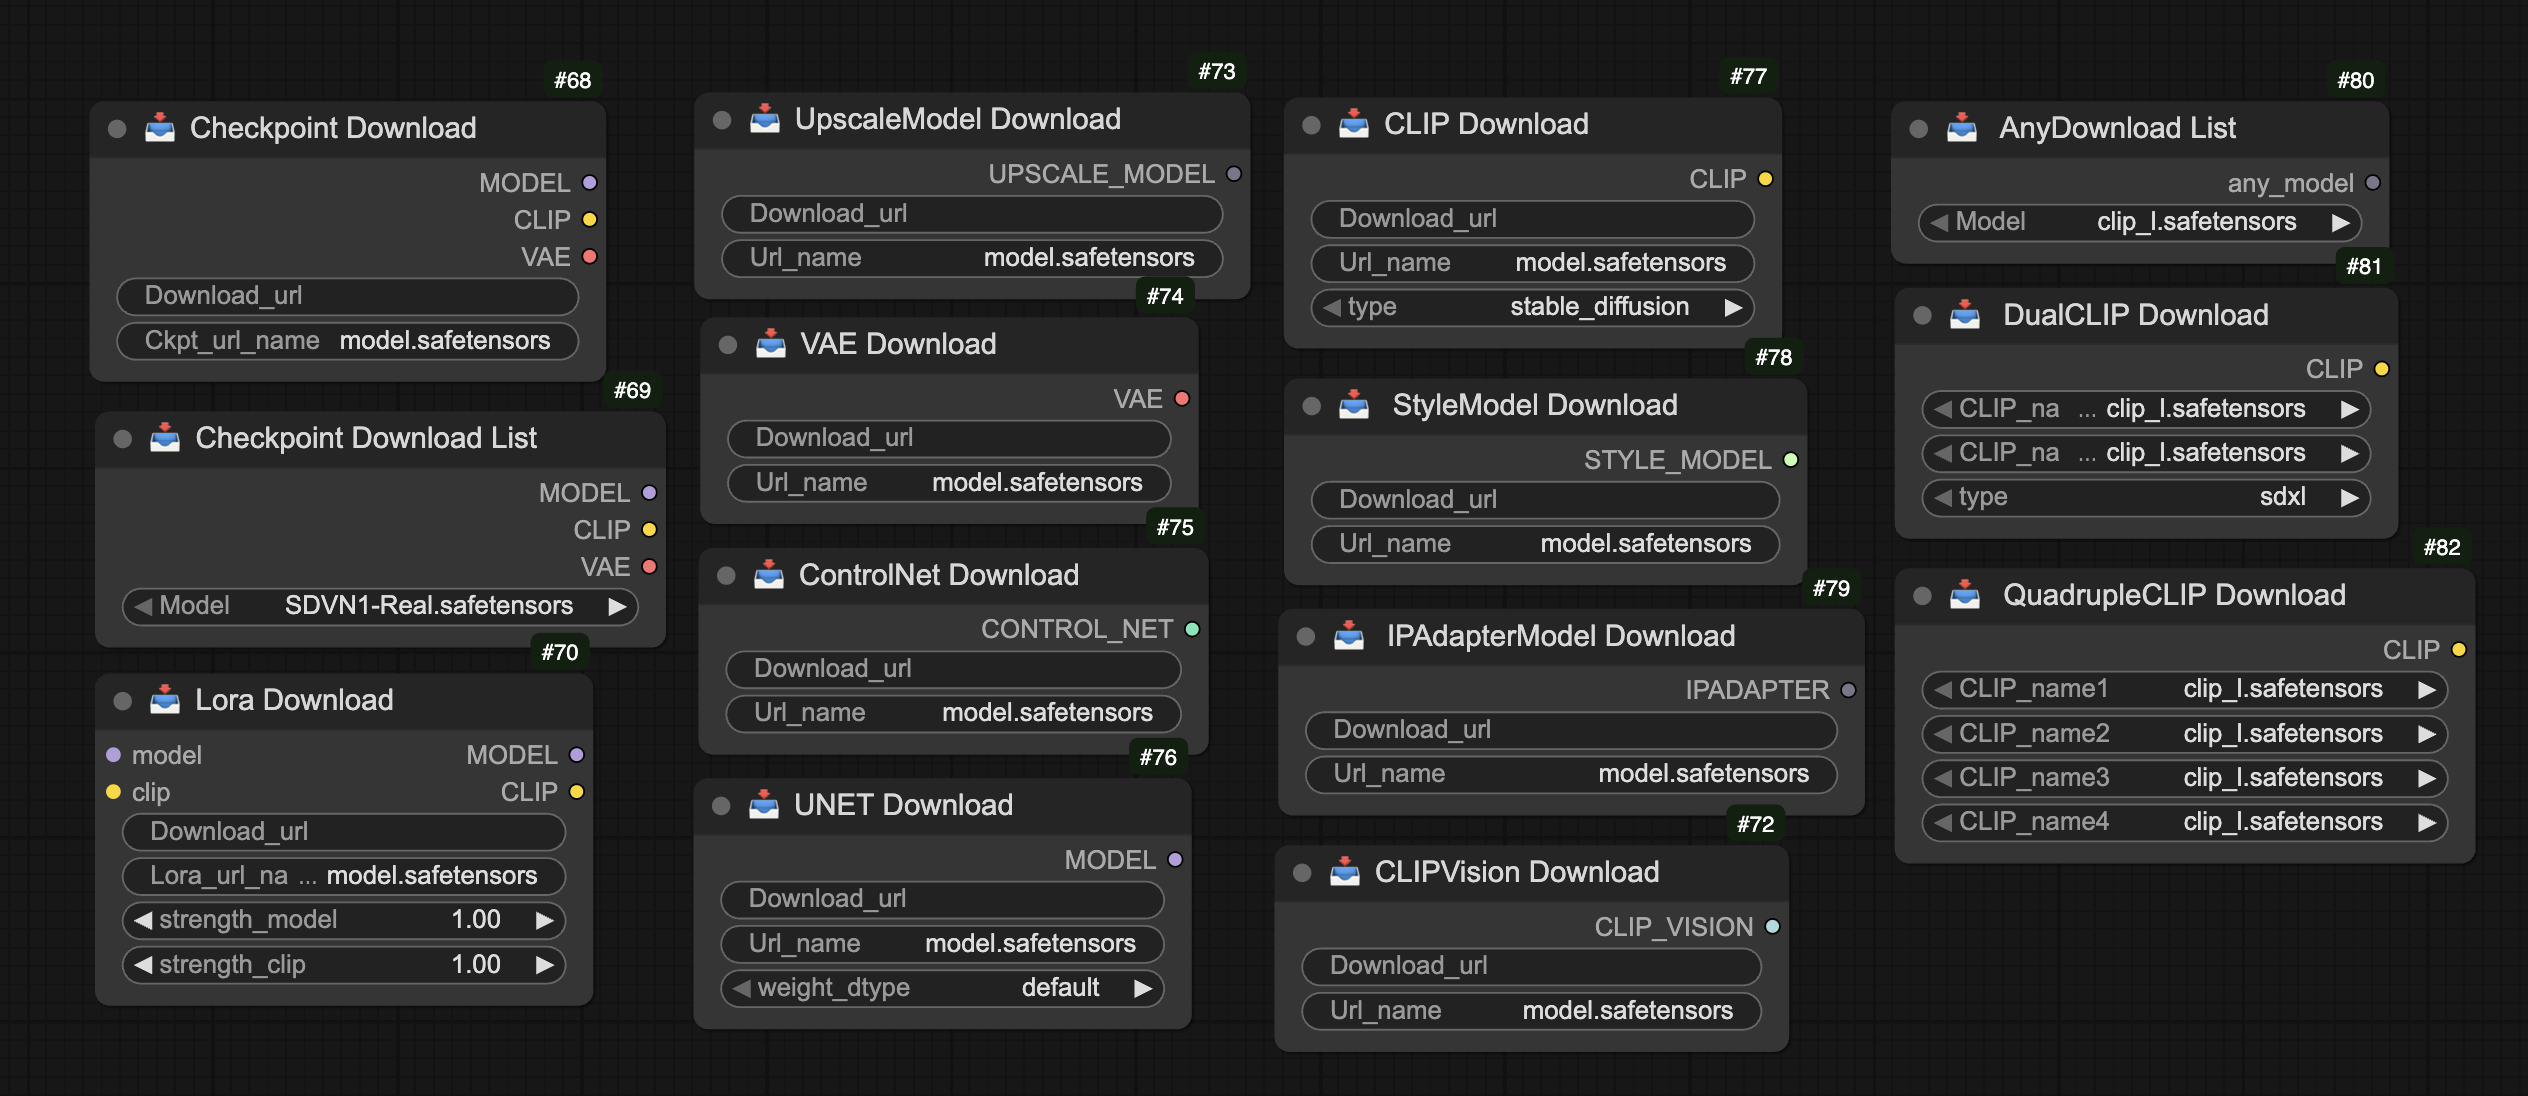
Download
The set of nodes supports downloading photos of models to the corresponding folder and directly used on Comfyui
- Supports direct download from civitai and huggingface with model address link and model download link
- Additionally, some nodes provide a list of popular models to make downloading them more convenient and faster.
- Includes download nodes for IPAdapter, InstantID, DualCLIP, QuadrupleCLIP and more.
- Extra download helpers: AnyDownload List, ModelPatch/UNET/CLIP/Style/CLIP Vision downloads, upscale model download, and VAE download.
Merge
Supports the smart and convenient way to adjust the Weight Model Block Model compared to the original nodes, inspiring more creativity. Refer more information at SuperMerge, Lora Block Weight
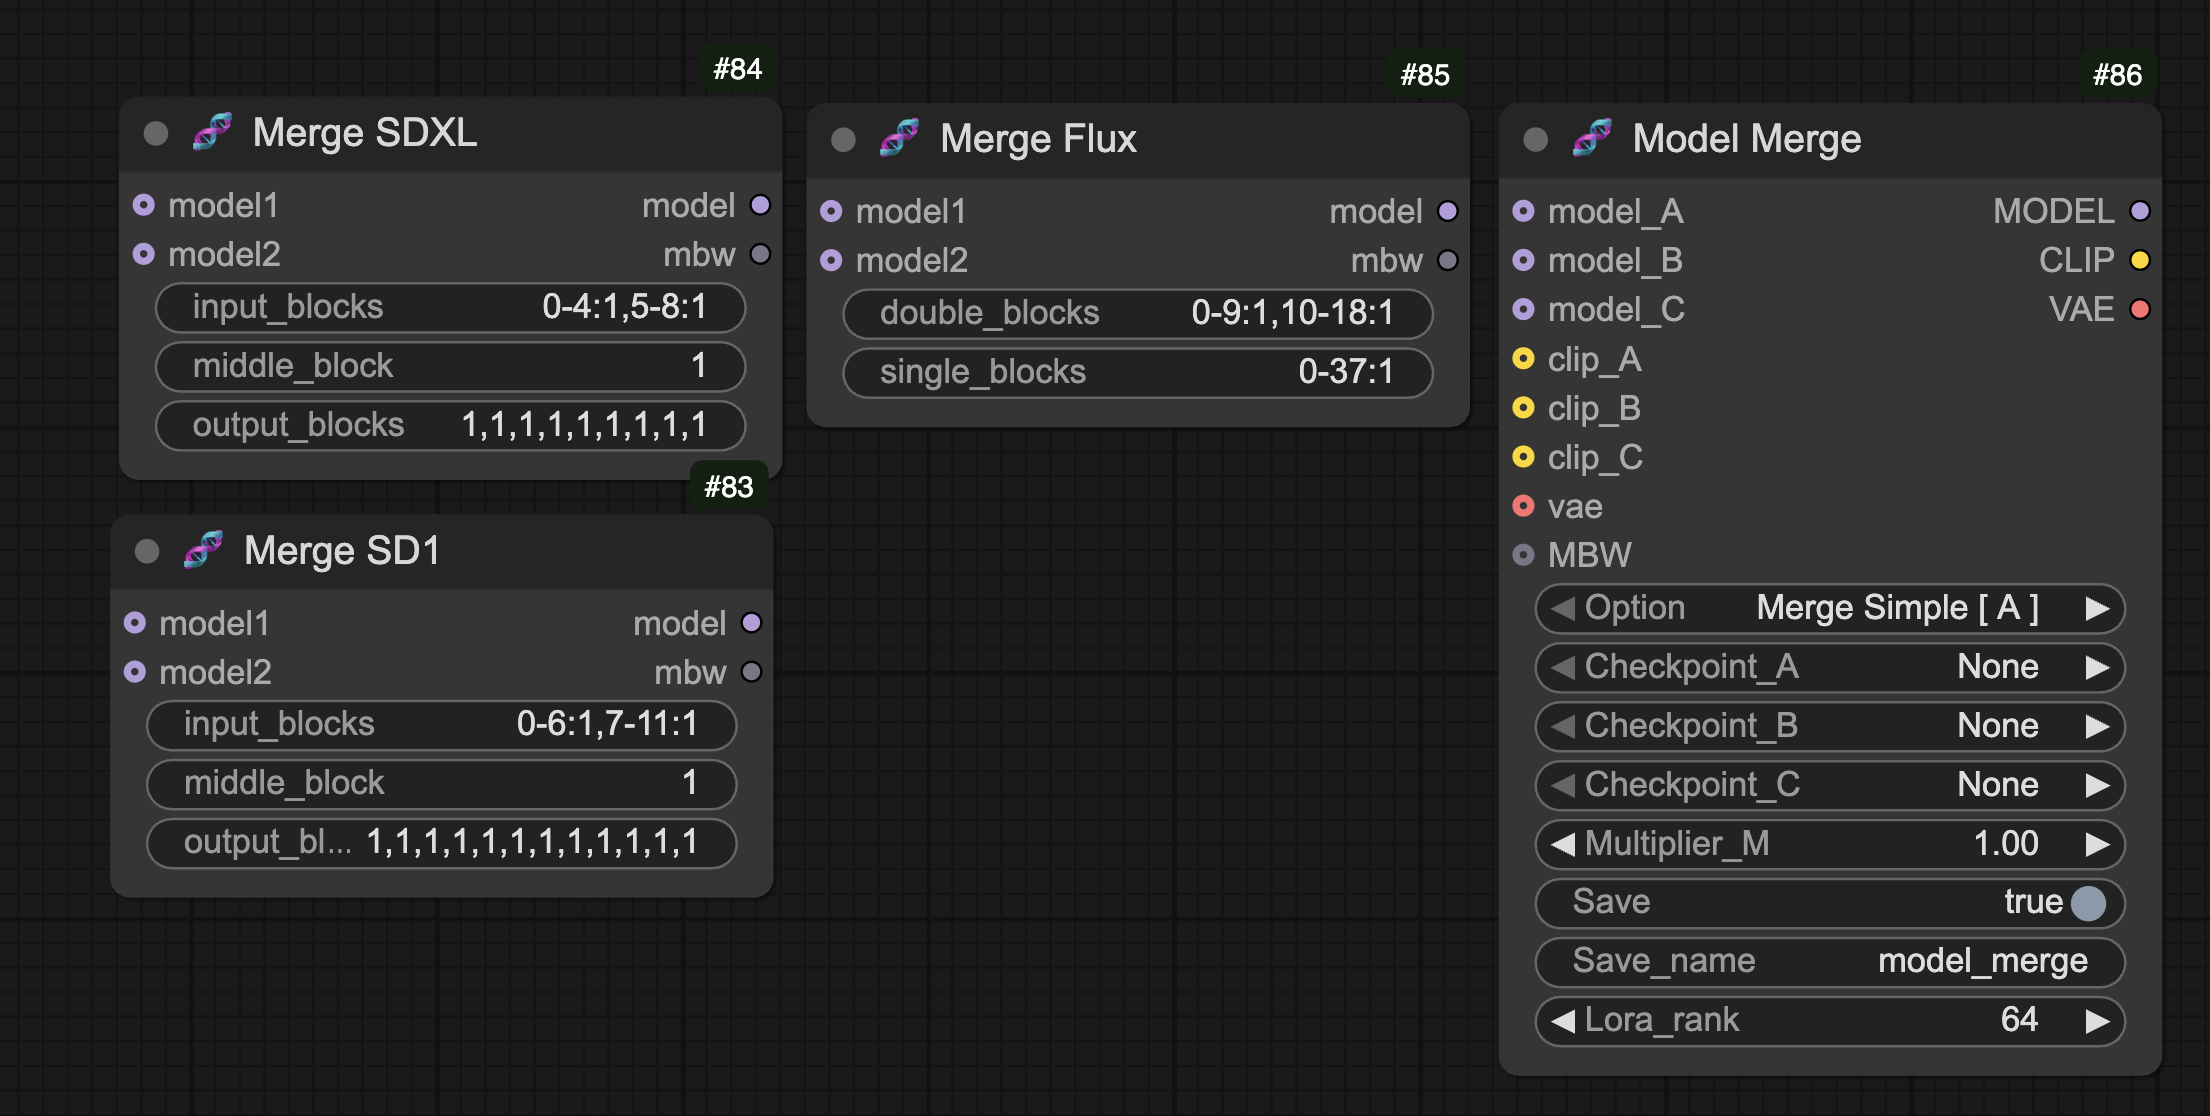
Support 3 types of syntax to adjust for each block
- The non -listed values will take the last block value
- {Block}: {Weight Block}
- Ex: SD15 has 12 blocks IN from 0-11
0:1, 1:1, 2:1, 3:1, 4:0, 5:1<=>0:1, 1:1, 2:1, 3:1, 4:0, 5:1, 6:1, 7:1, 8:1, 9:1, 10:1, 11:12:0, 3:1<=>0:1, 1:1, 2:0, 3:1, 4:1, 5:1, 6:1, 7:1, 8:1, 9:1, 10:1, 11:1
- Ex: SD15 has 12 blocks IN from 0-11
- {Weight Block}
- Ex: SDXL has 9 blocks IN from 0-8
0, 0, 0, 0, 1, 1<=>0:0, 1:0, 2:0, 3:0, 4:1, 5:1, 6:1, 7:1, 8:1
- Ex: SDXL has 9 blocks IN from 0-8
- {Range}: {Weight Block}
- Ex: Flux has 19 double blocks from 0-18
0-10:0, 11-18:1<=>0:0, 1:0, 2:0, 3:0, 4:0, 5:0, 6:0, 7:0, 8:0, 9:0, 10:0, 11:1, 12:1, 13:1, 14:1, 15:1, 16:1, 17:1, 18:1
- Ex: Flux has 19 double blocks from 0-18
- Combining 3 types of syntax
- Ex: SDXL has 9 blocks OUT from 0-8
0-3:0, 1, 6:1, 0<=>0:0, 1:0, 2:0, 3:0, 4:1, 5:0, 6:1, 7:0, 8:0
- Ex: SDXL has 9 blocks OUT from 0-8
🧬 Model Merge
- This node supports merging 2 or 3 checkpoints, extracting LoRA from 2 checkpoints — similar to the merge function in Automatic1111.
- Model Export saves merged results to disk with optional metadata edits.
Creative
The node set helps to create the process in a smart way
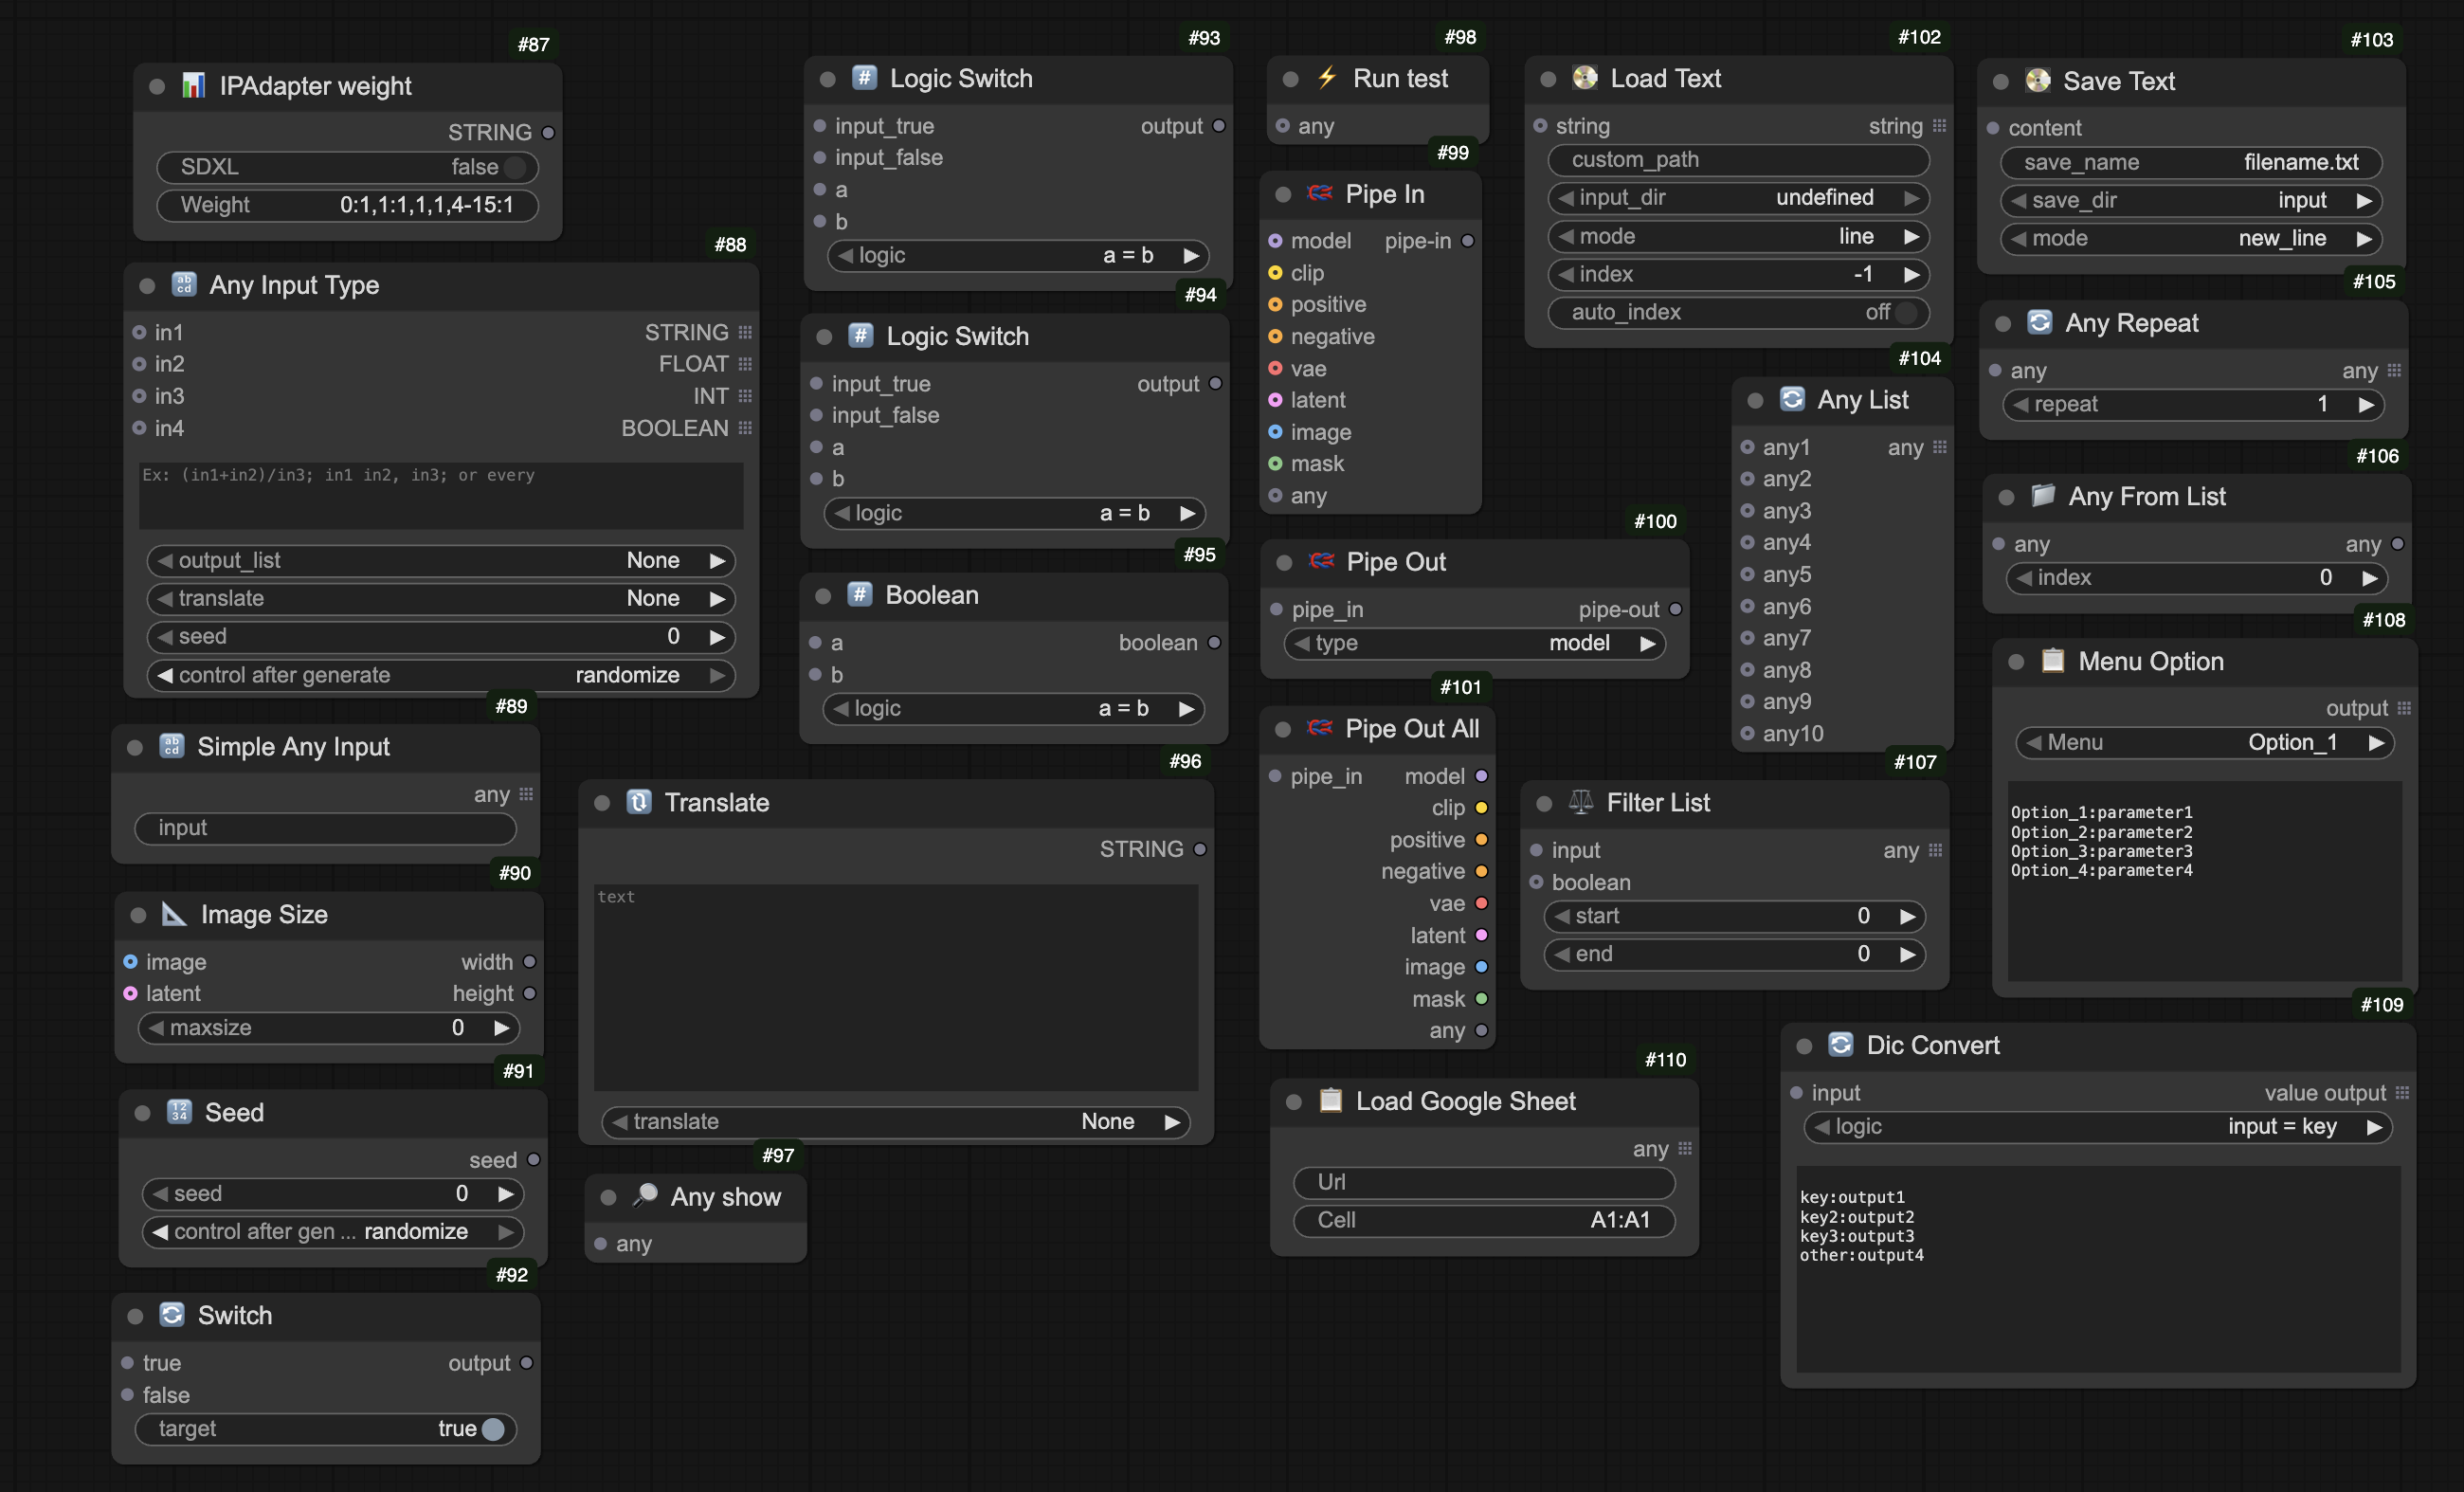
📊 IPAdapter weight
- Use the same syntax as the merge
🔃 Translate
- Support translate and Dynamic prompt
🔎 Any show
- A smart and flexible node that supports displaying any type of data, including image, string, int, float, bool, mask, and JSON.
⚡️ Run test
- A simple node used for testing workflows without returning any output.
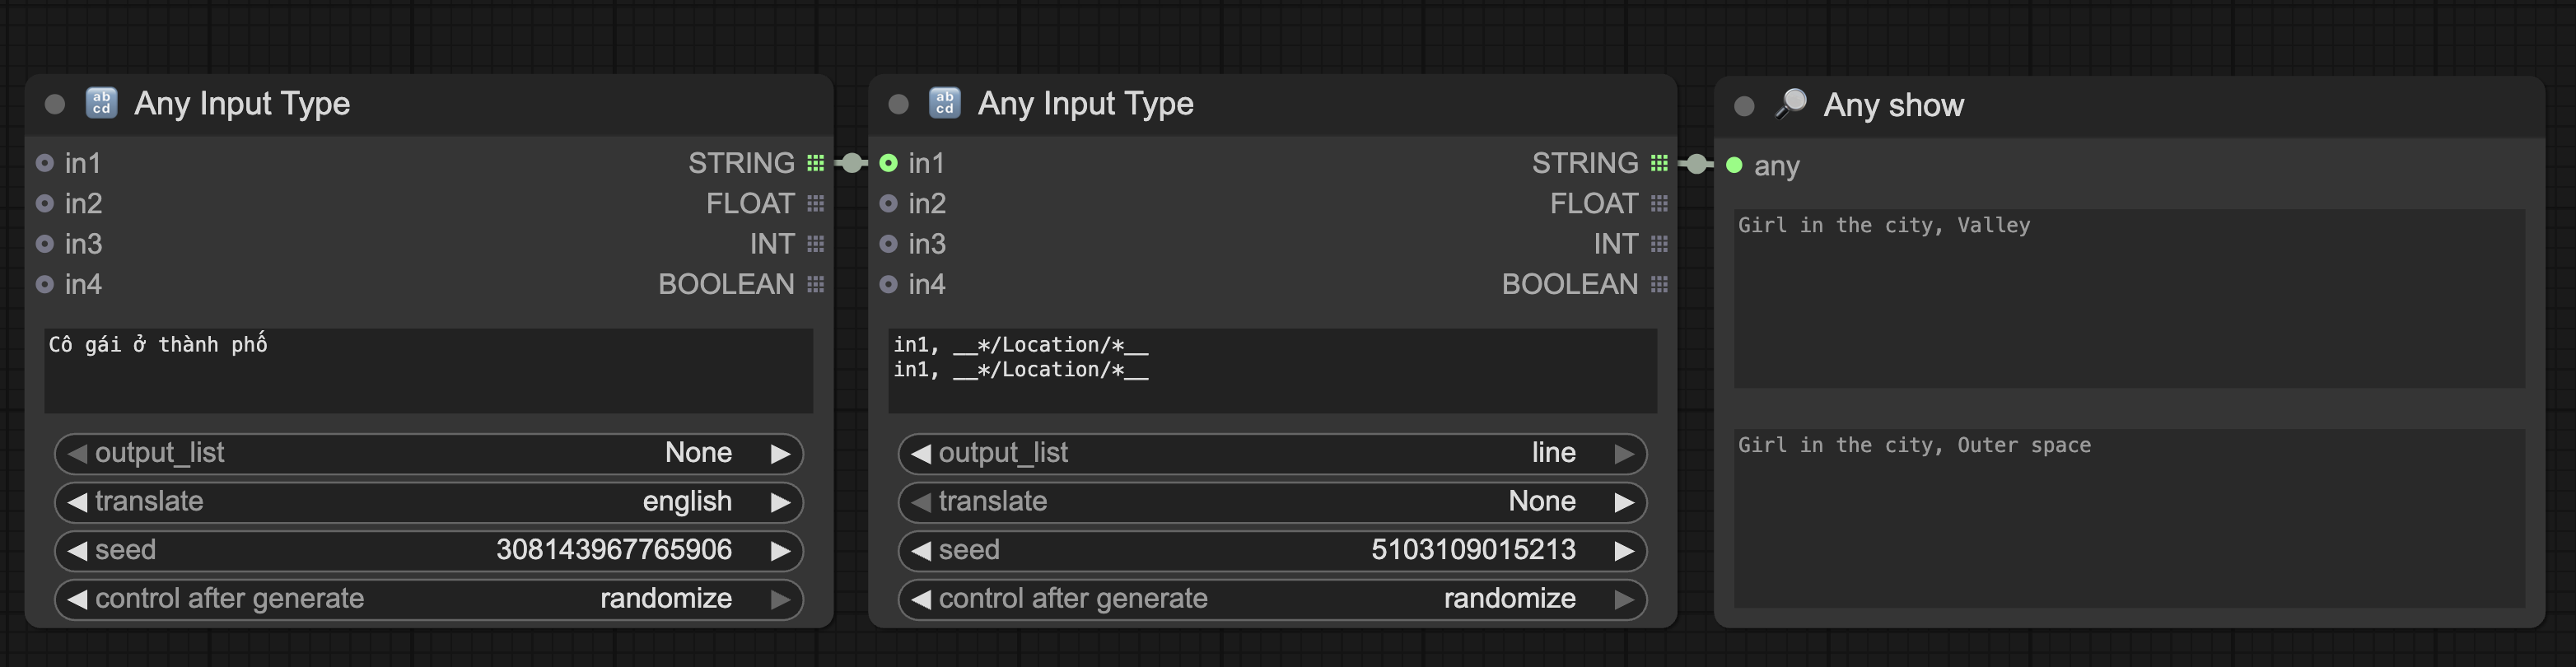
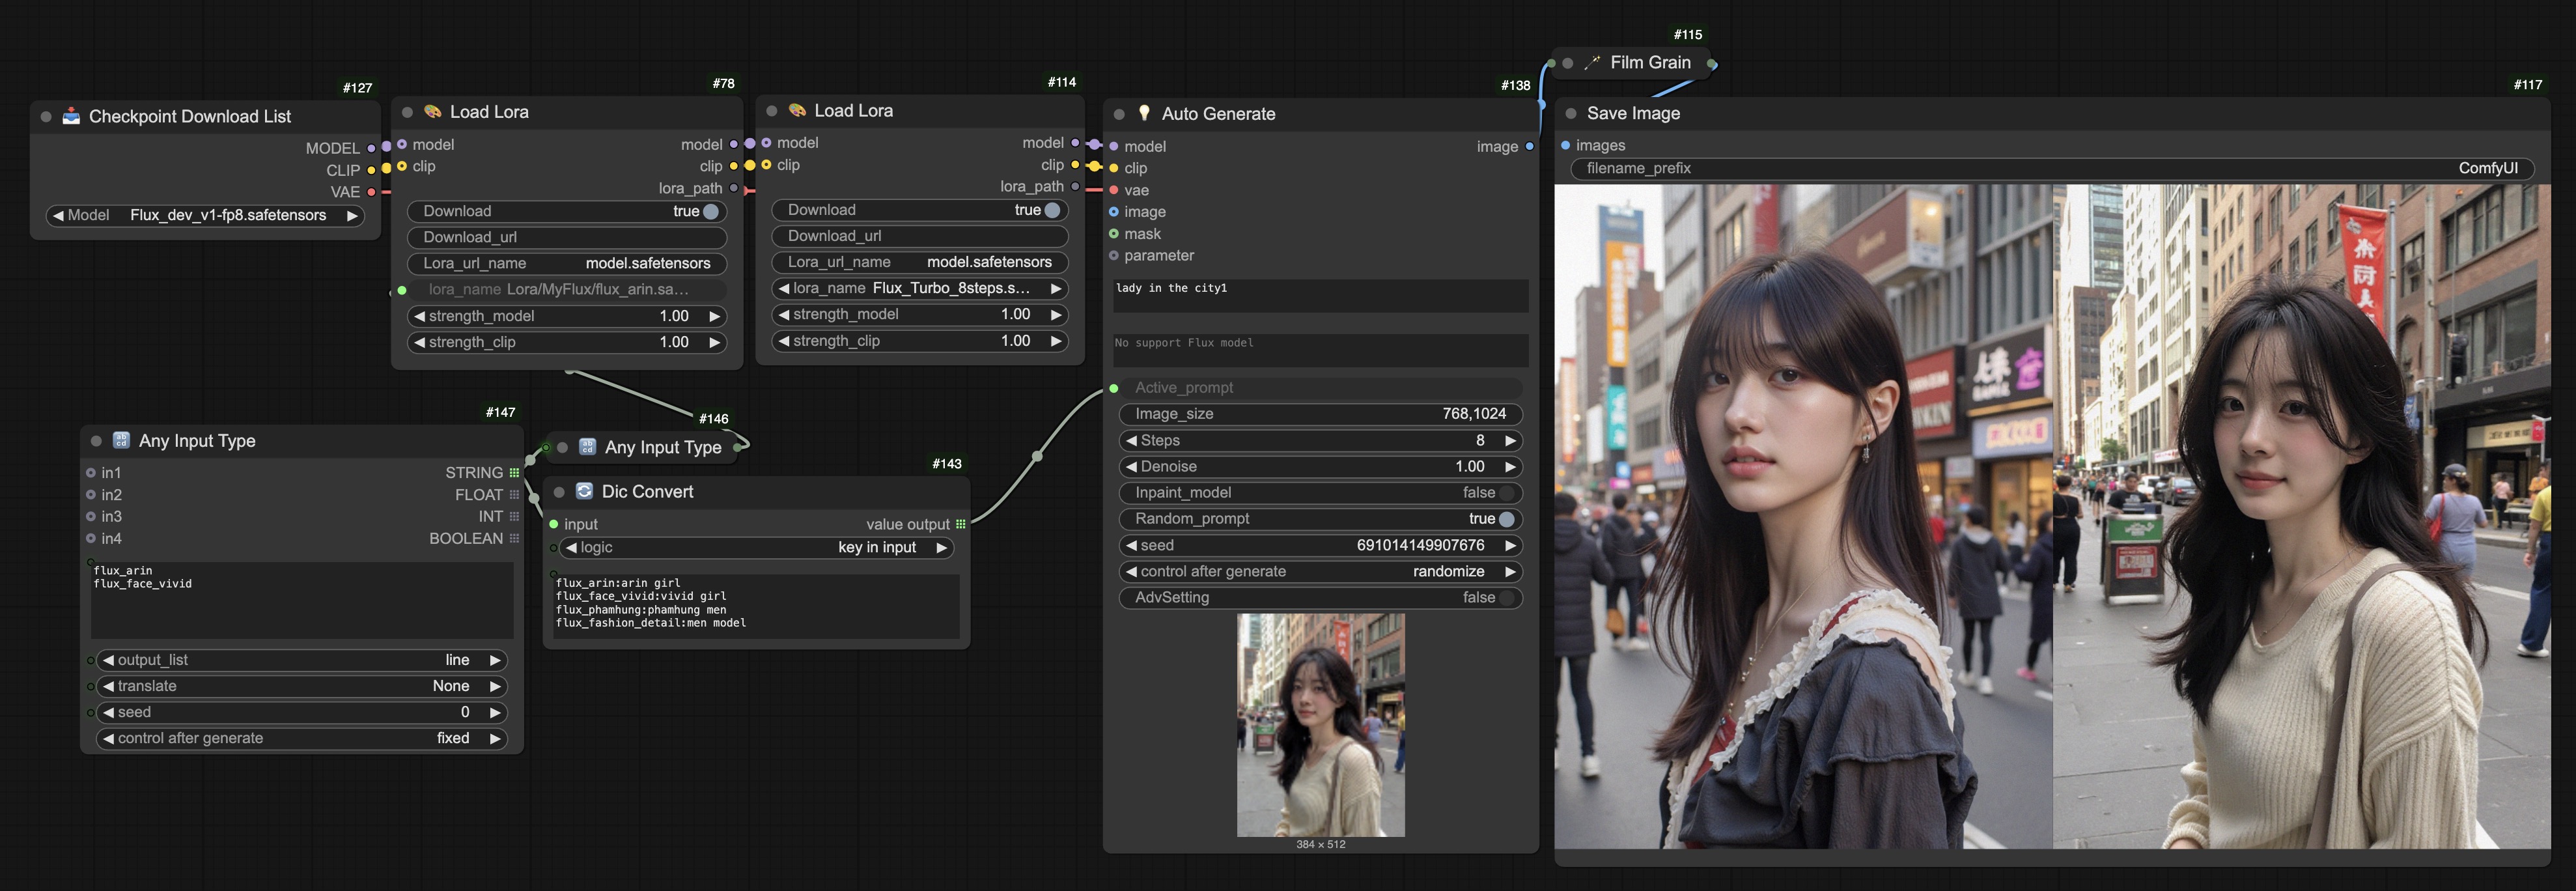
🔡 Any Input Type
- Support Math, Boolean input value (yes-no, true-false, 1-2)
- Support output list
- A powerful and flexible node for working with text or numbers, supporting various output modes. You can easily concatenate multiple text segments using representative keywords like in1, in2, in3.
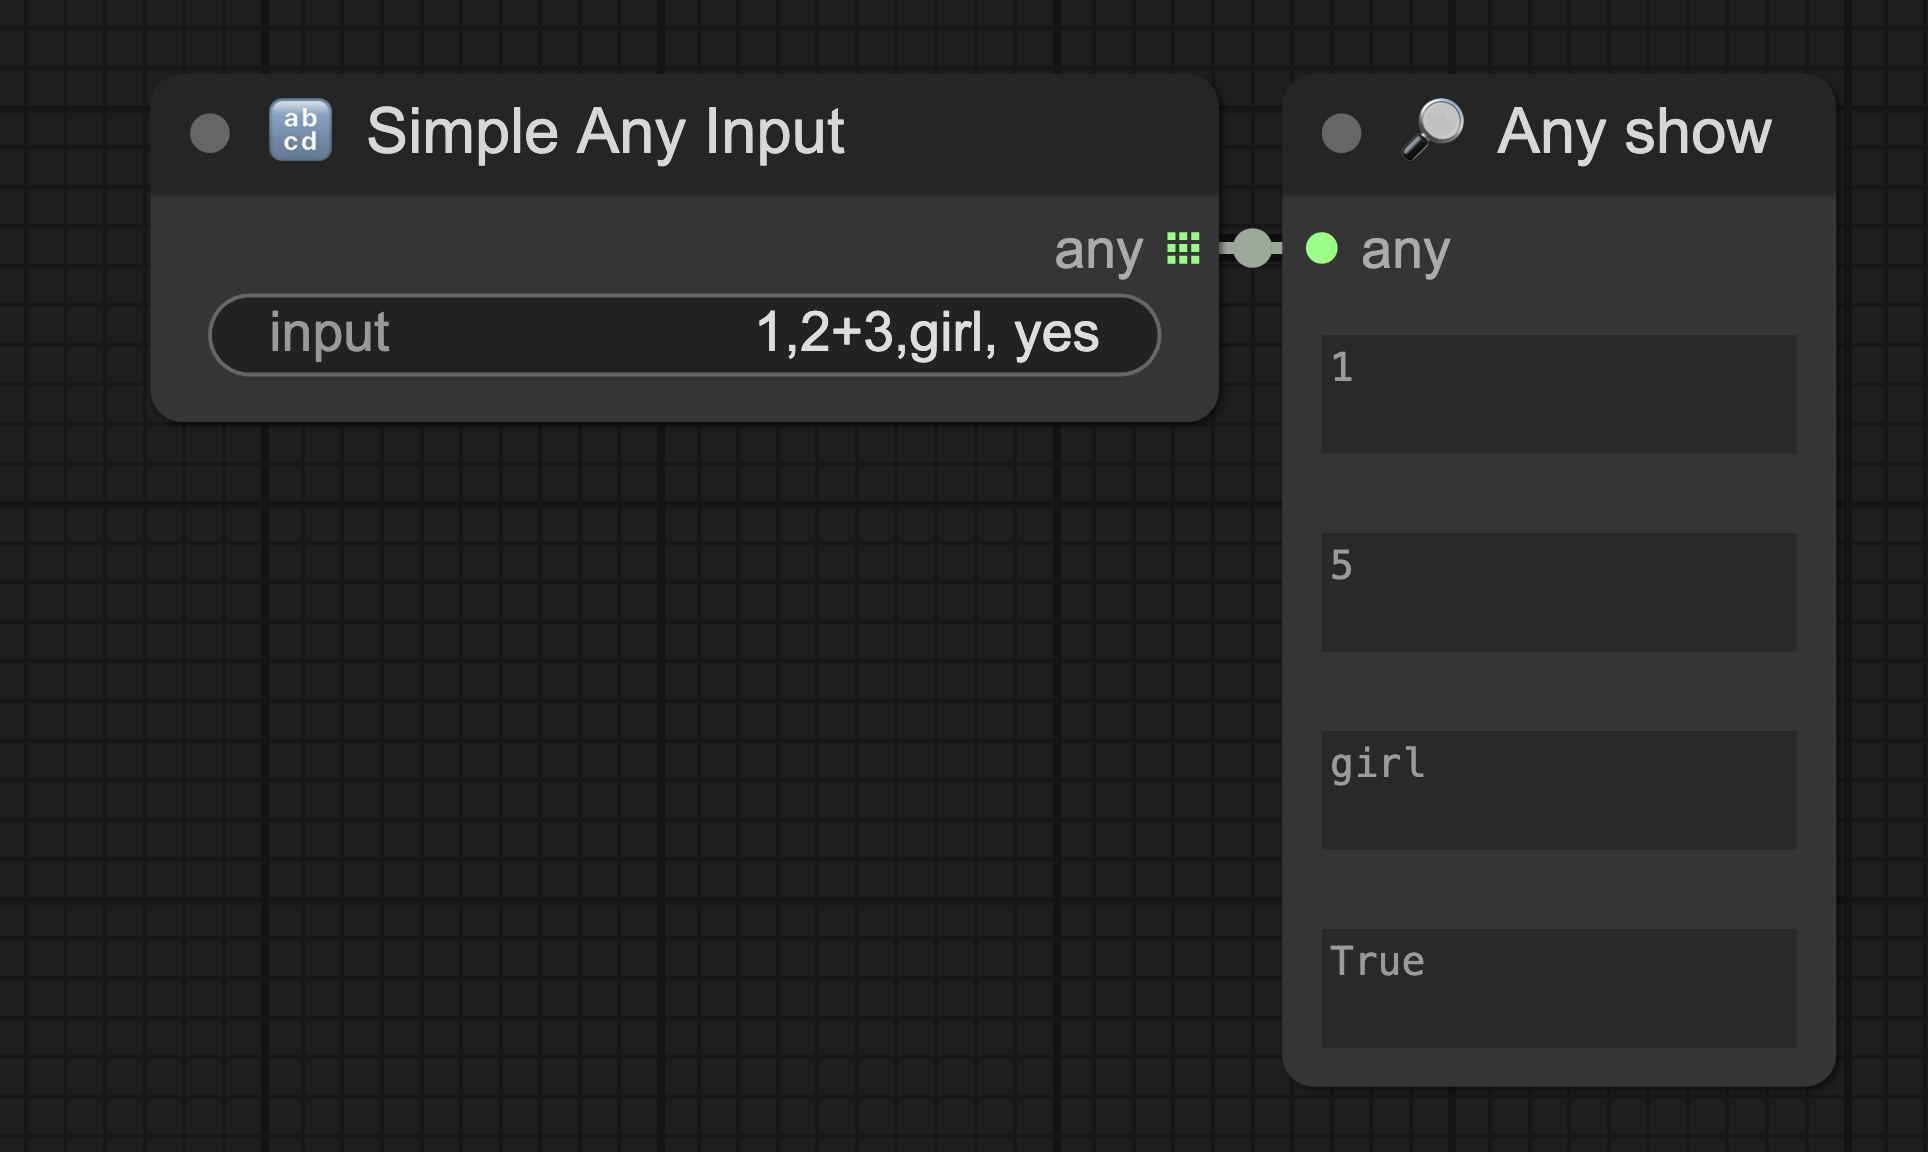
🔡 Simple Any Input
- A simpler version of Any Input Type — this node automatically converts input strings into STRING, FLOAT, INT, or BOOL formats. Commas (,) in the input string will act as separators, splitting the string into multiple parts and returning them as a list.
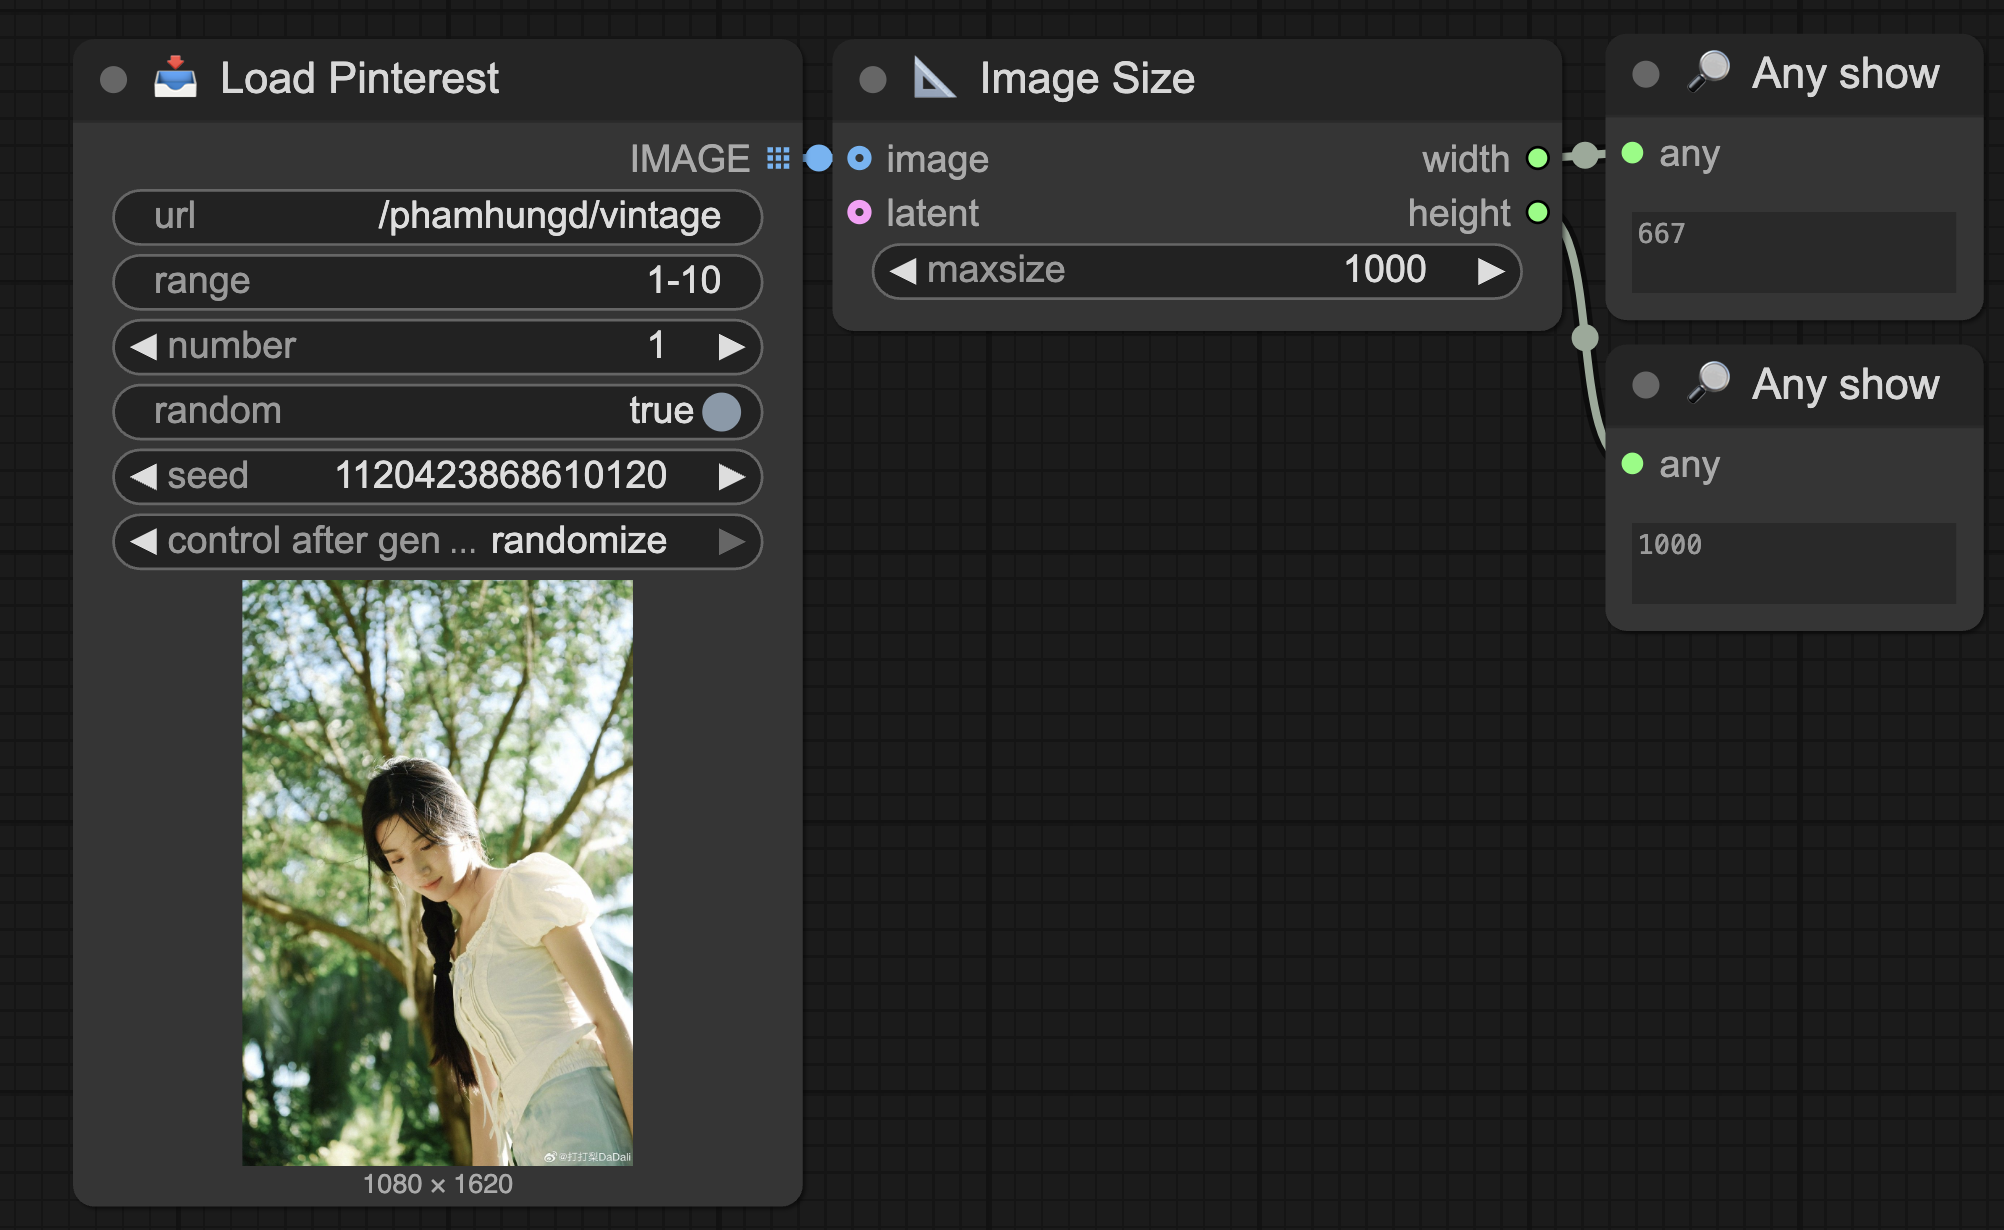
📐 Image Size
- A smart node for retrieving the width and height of an image (latent image). Additionally, you can define a maximum size using the maxsize value — the dimensions will not exceed this value and the aspect ratio will be preserved, If maxsize = 0, the image will retain its original dimensions.
🔢 Seed
- A node that supports INT input with options for randomization and variable adjustment, making it suitable for automated workflows.
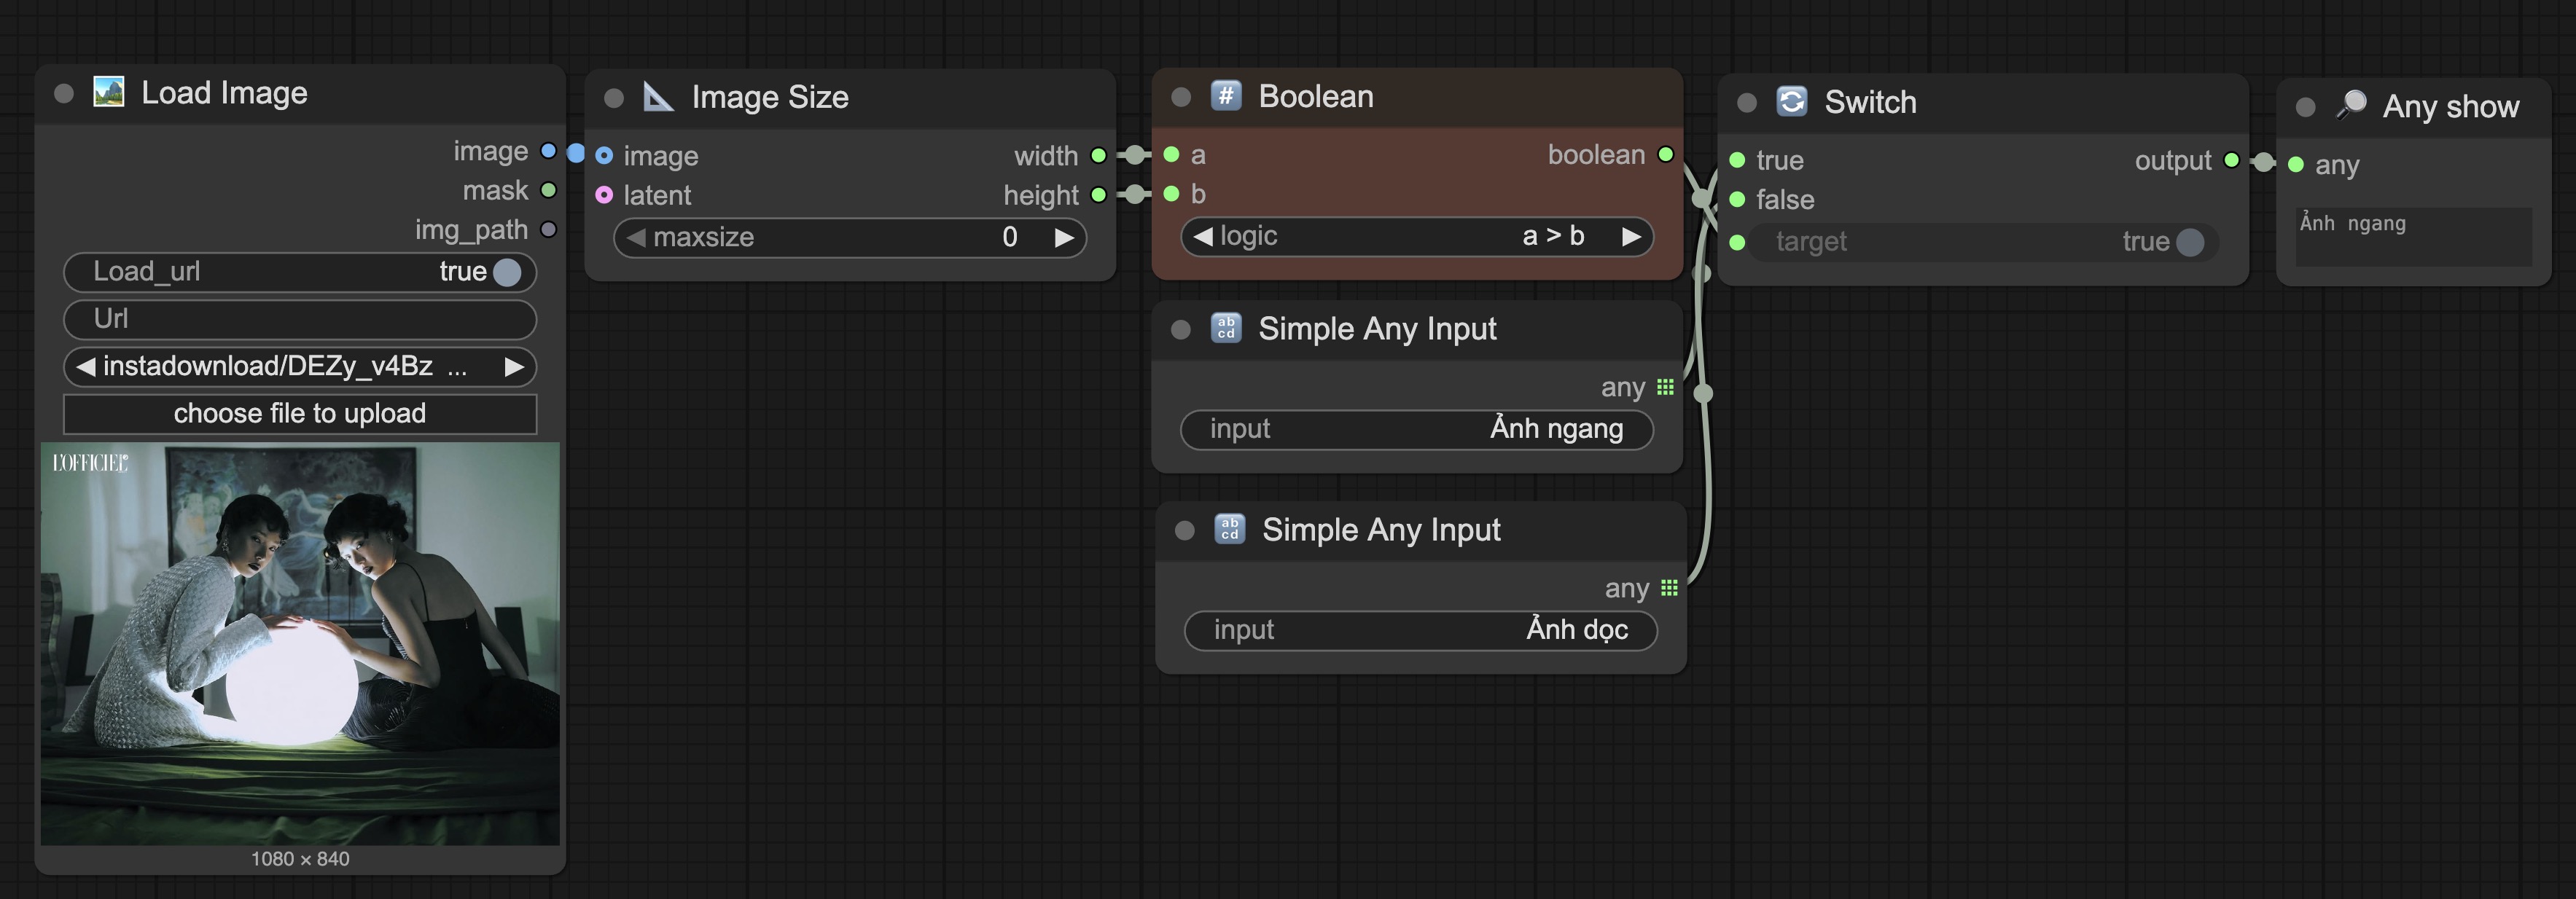
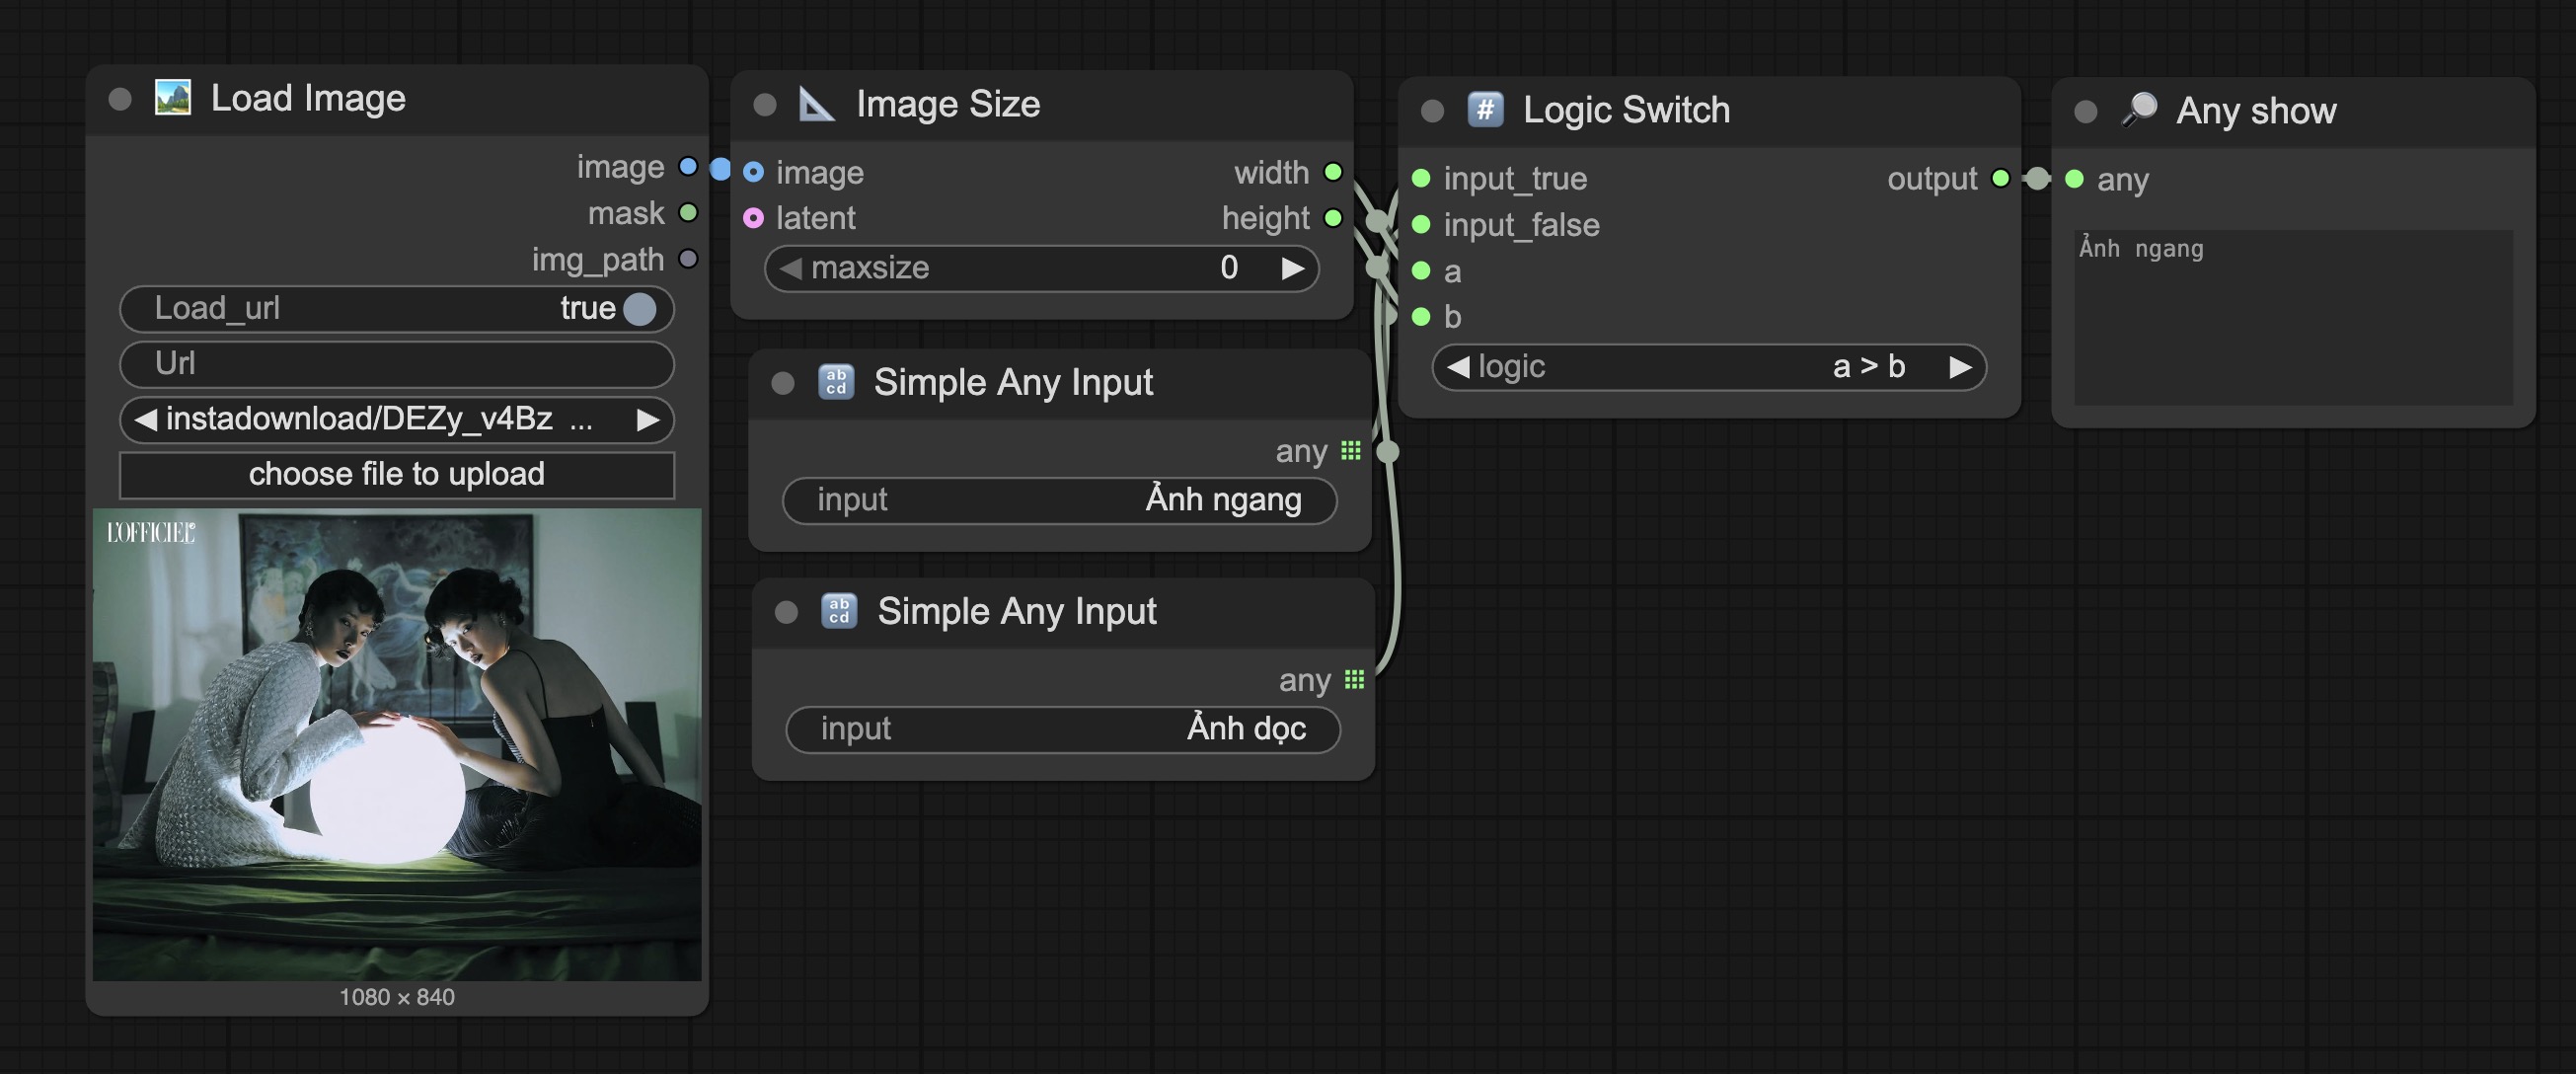
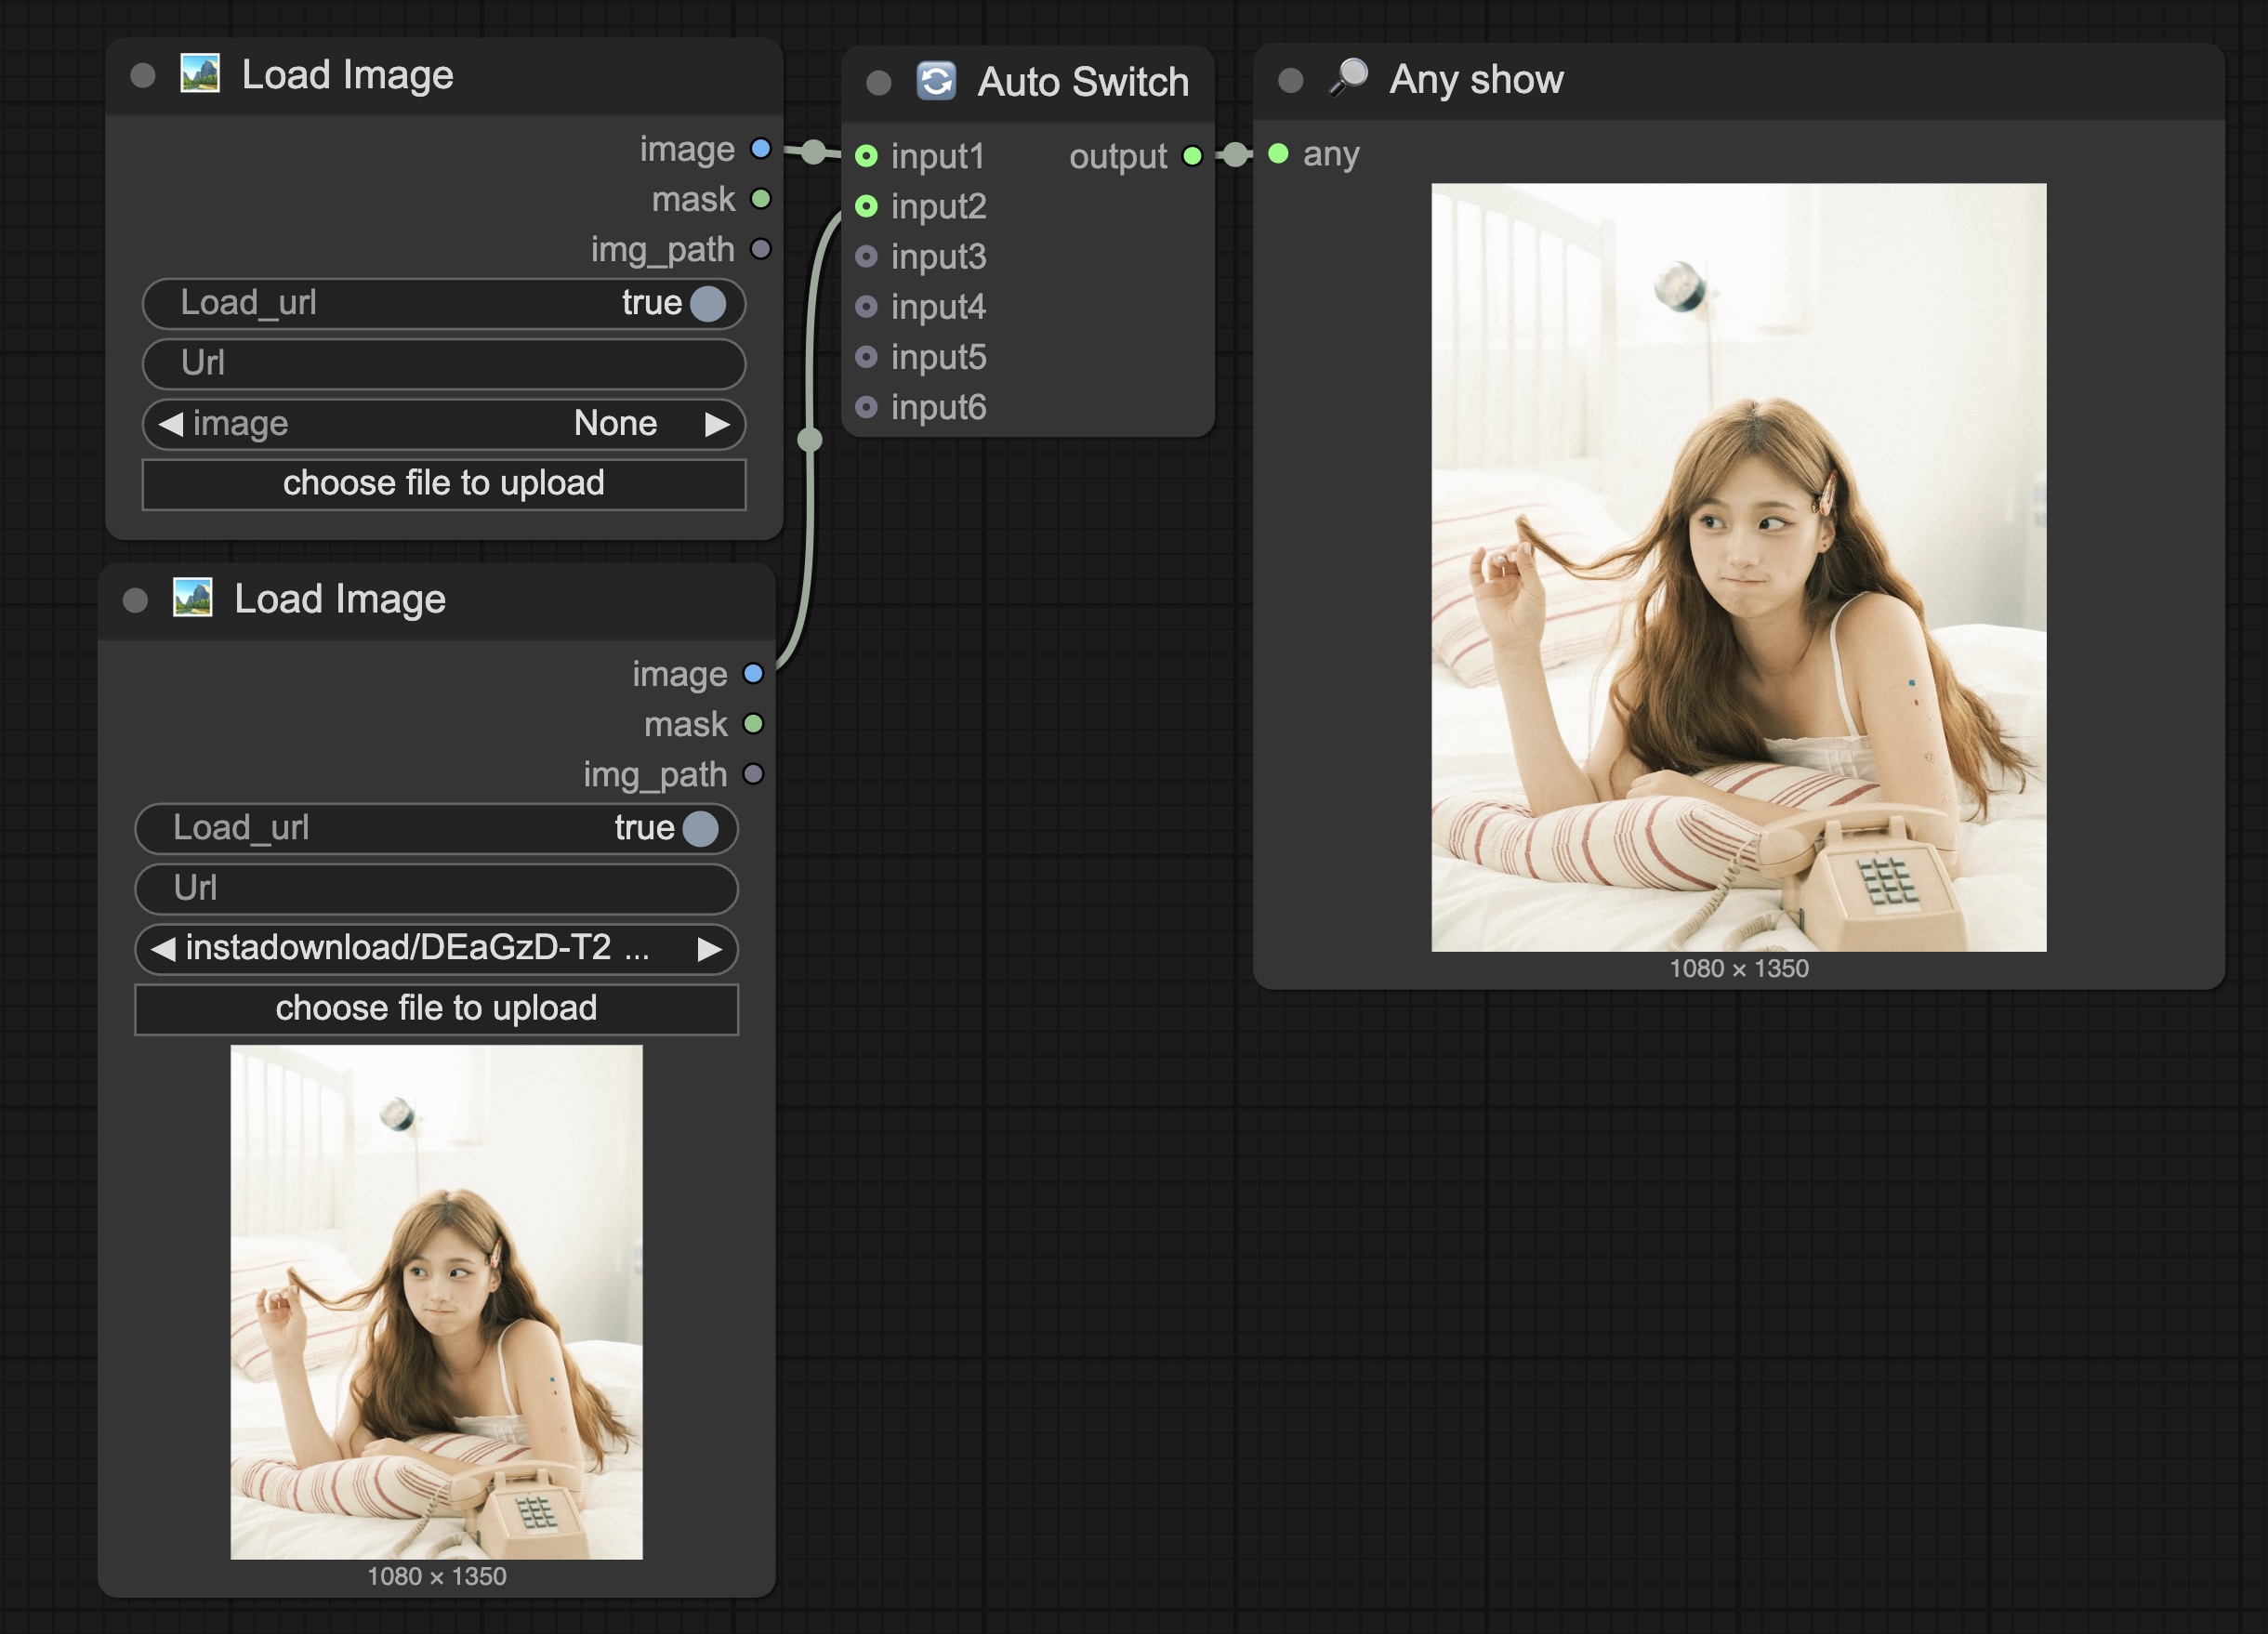
🔄 Switch | #️⃣ Boolean | #️⃣ Logic Switch | 🔄 Auto Switch
- A set of nodes that support flow-switching options, helping to automate workflows.
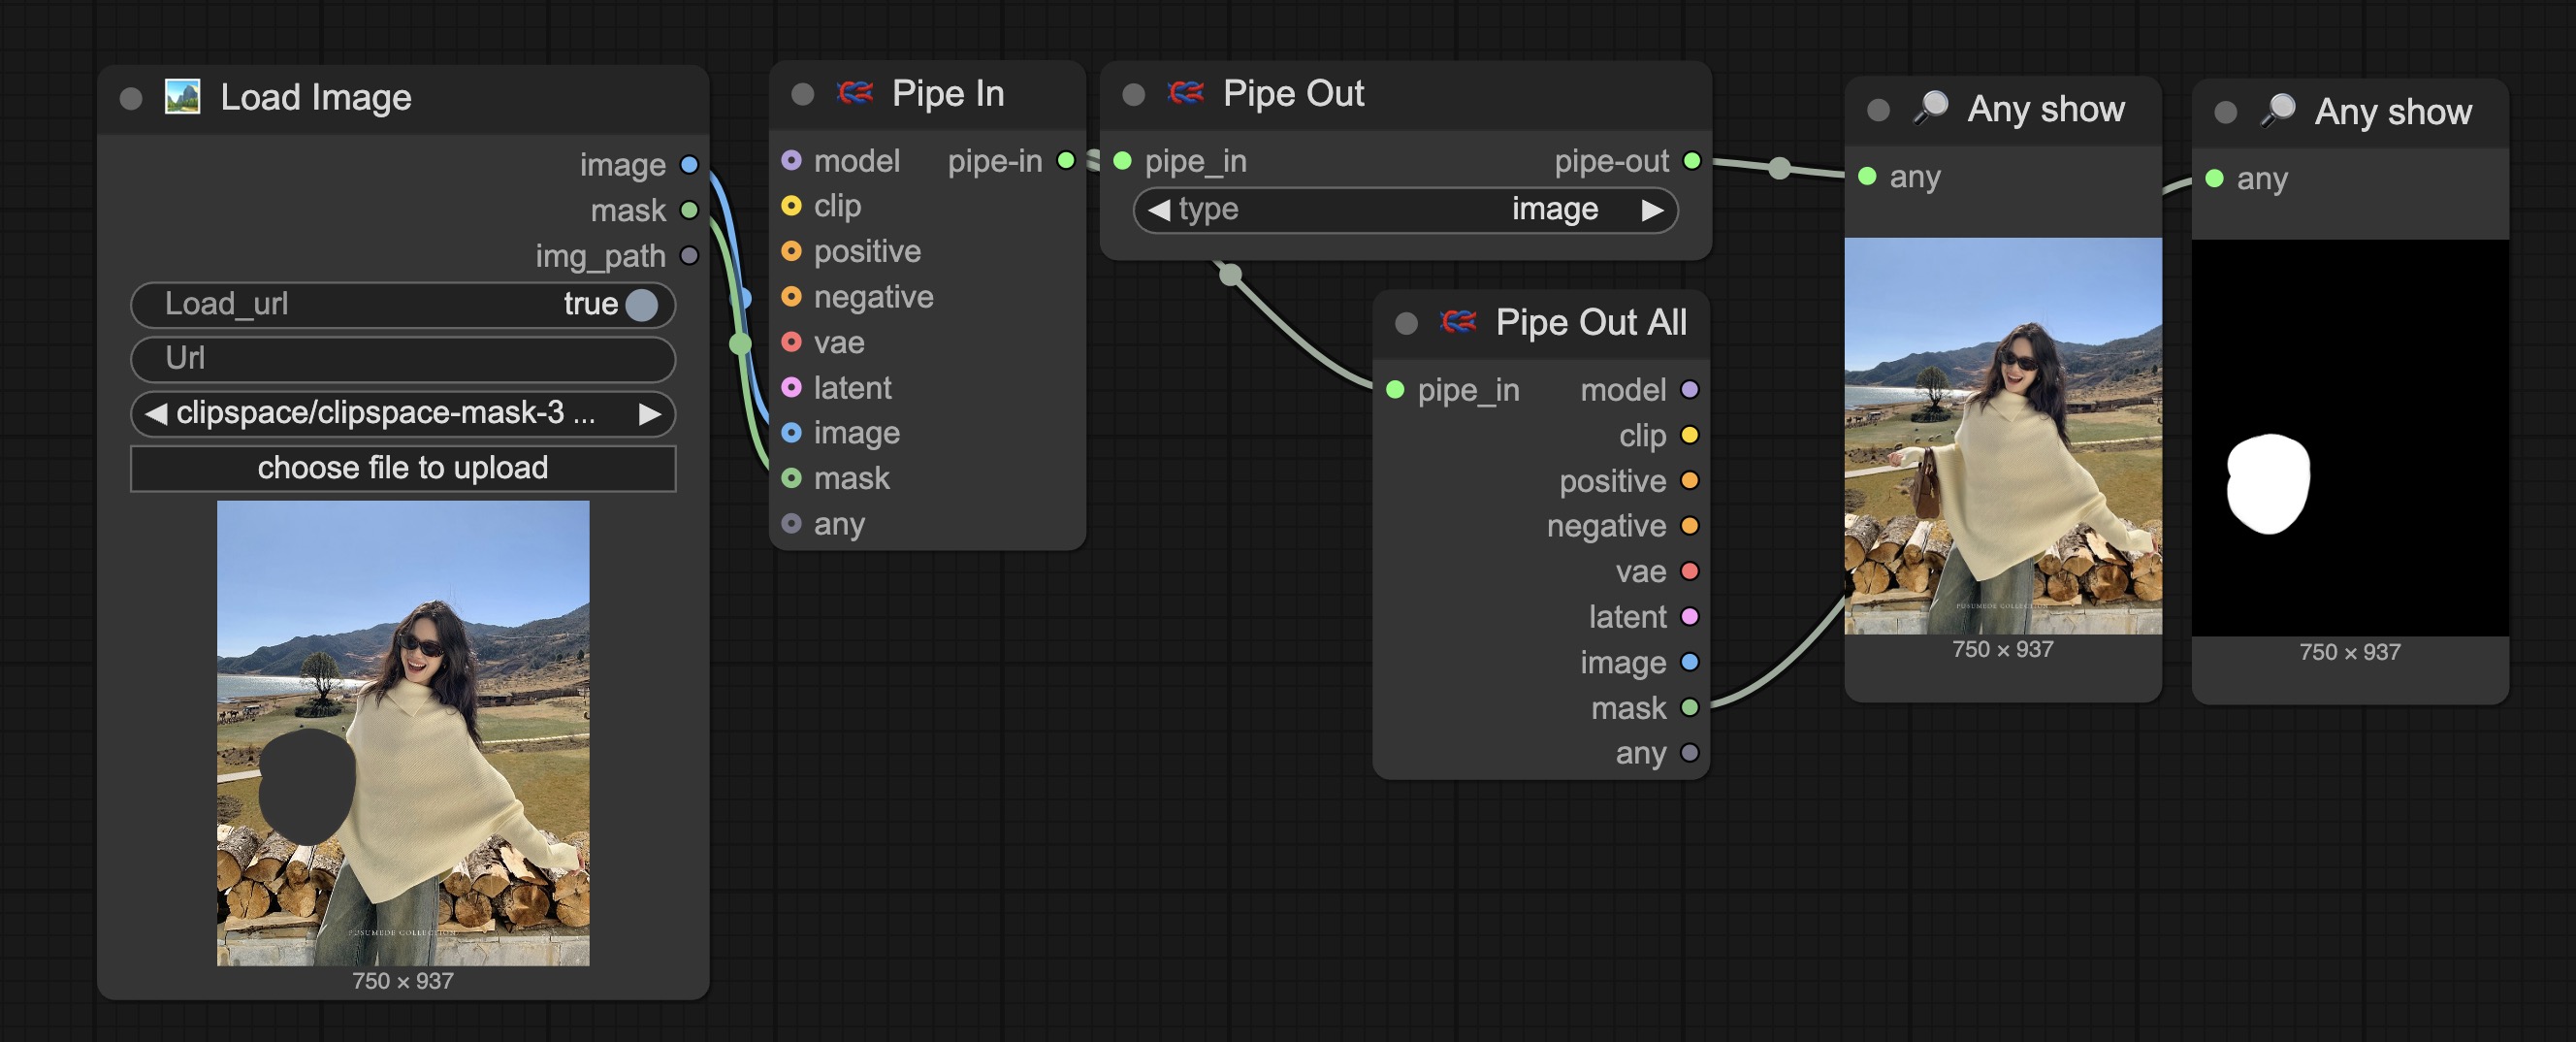
🪢 Pipe In | 🪢 Pipe Out | 🪢 Pipe Out All
- Nodes that help simplify, organize, and visually clean up the connections in your workflow.
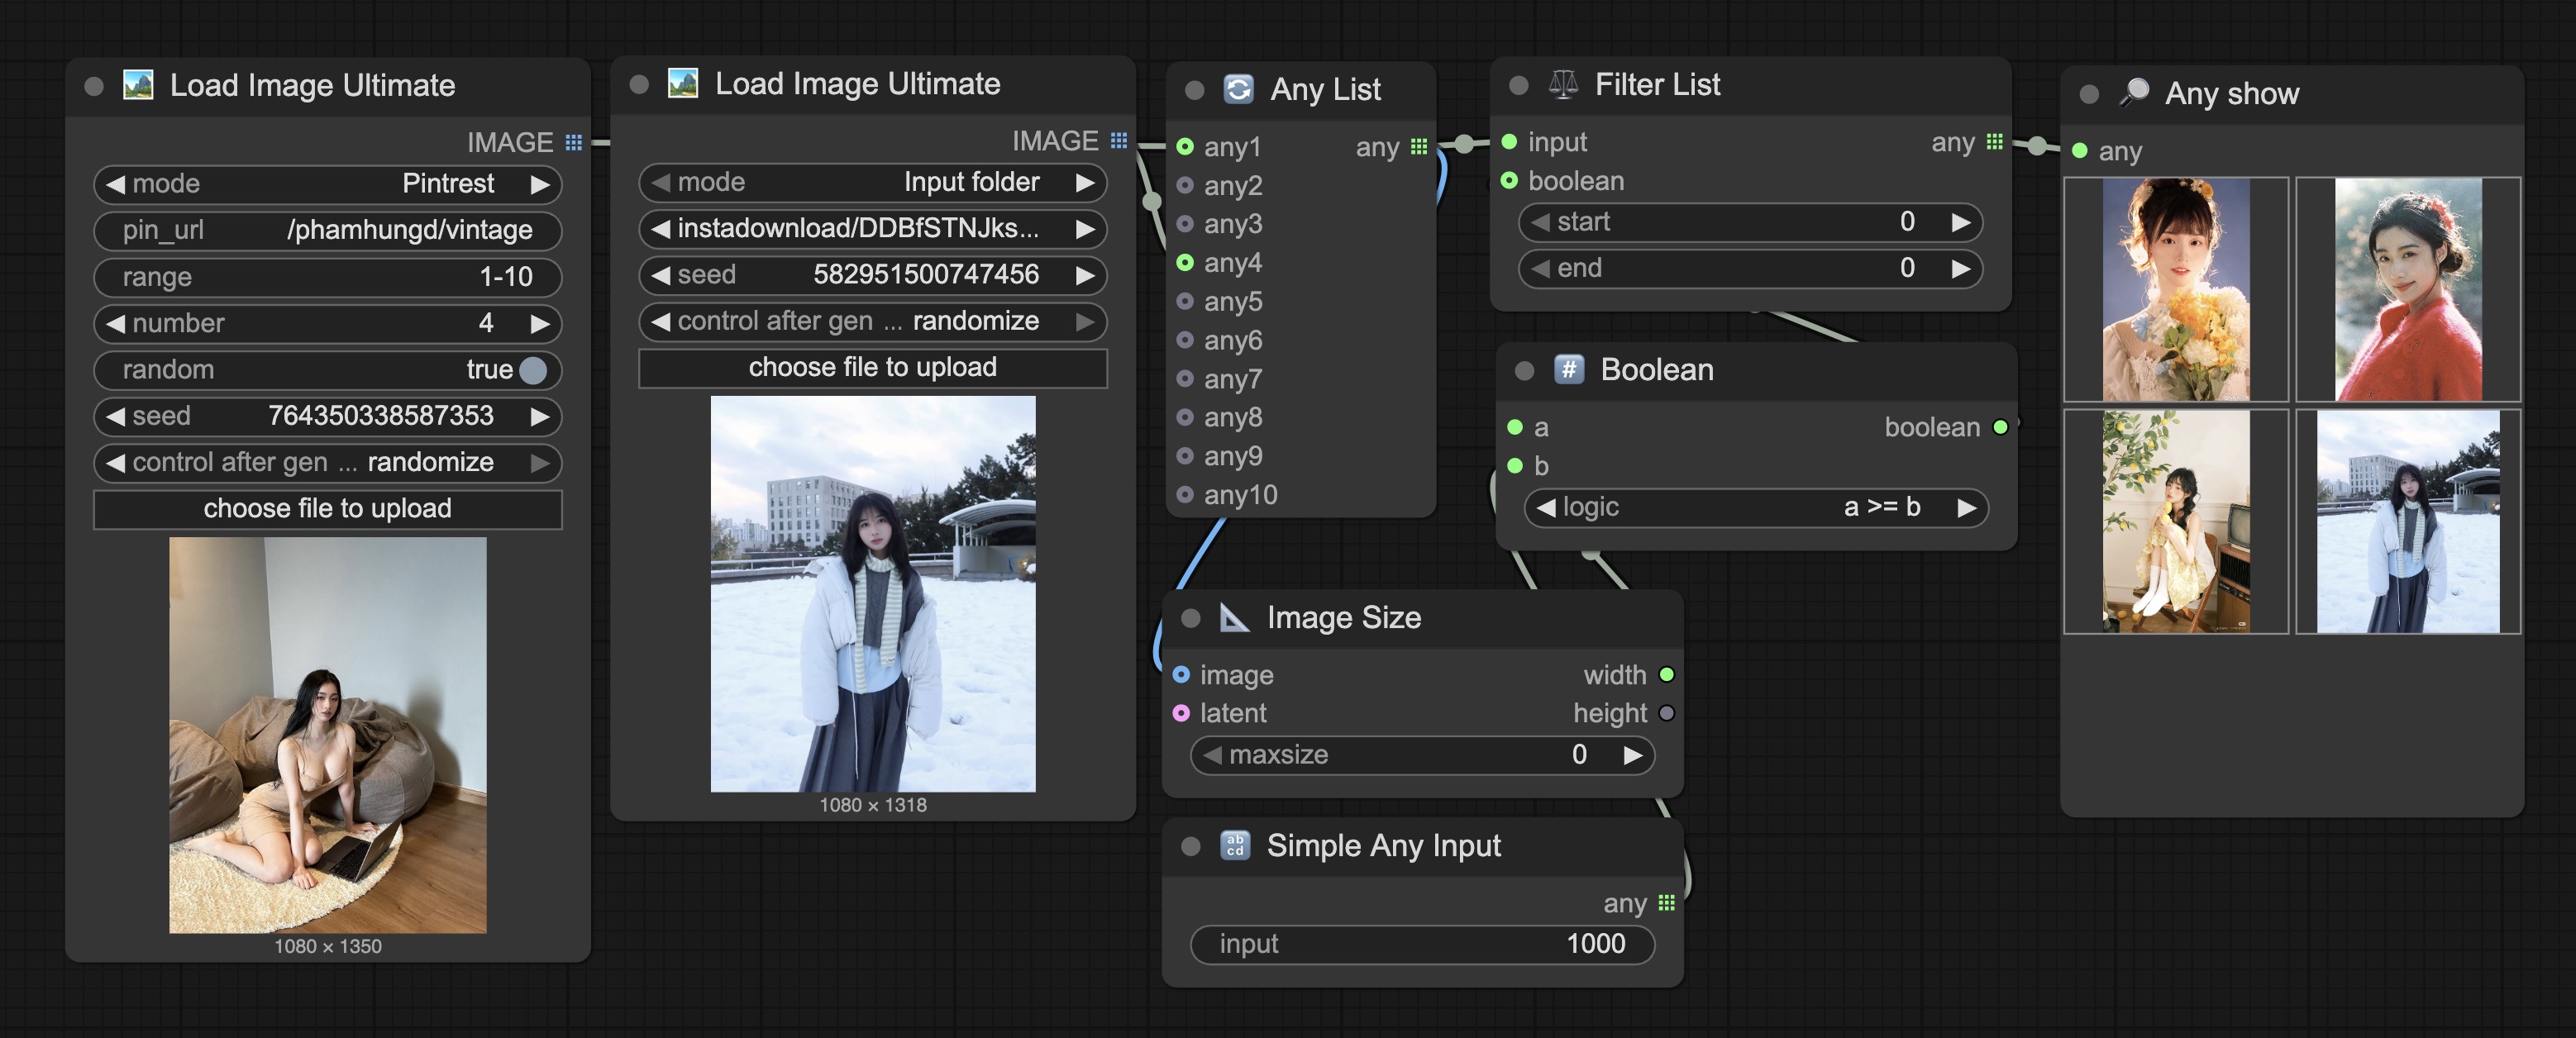
🔄 Any Repeat | 🔄 Any List
- A node that converts simple data items into a list.
⚖️ Filter List | 📁 Any From List
- Filter data within a list.
Example: A workflow to filter images with a width ≥ 1000px.
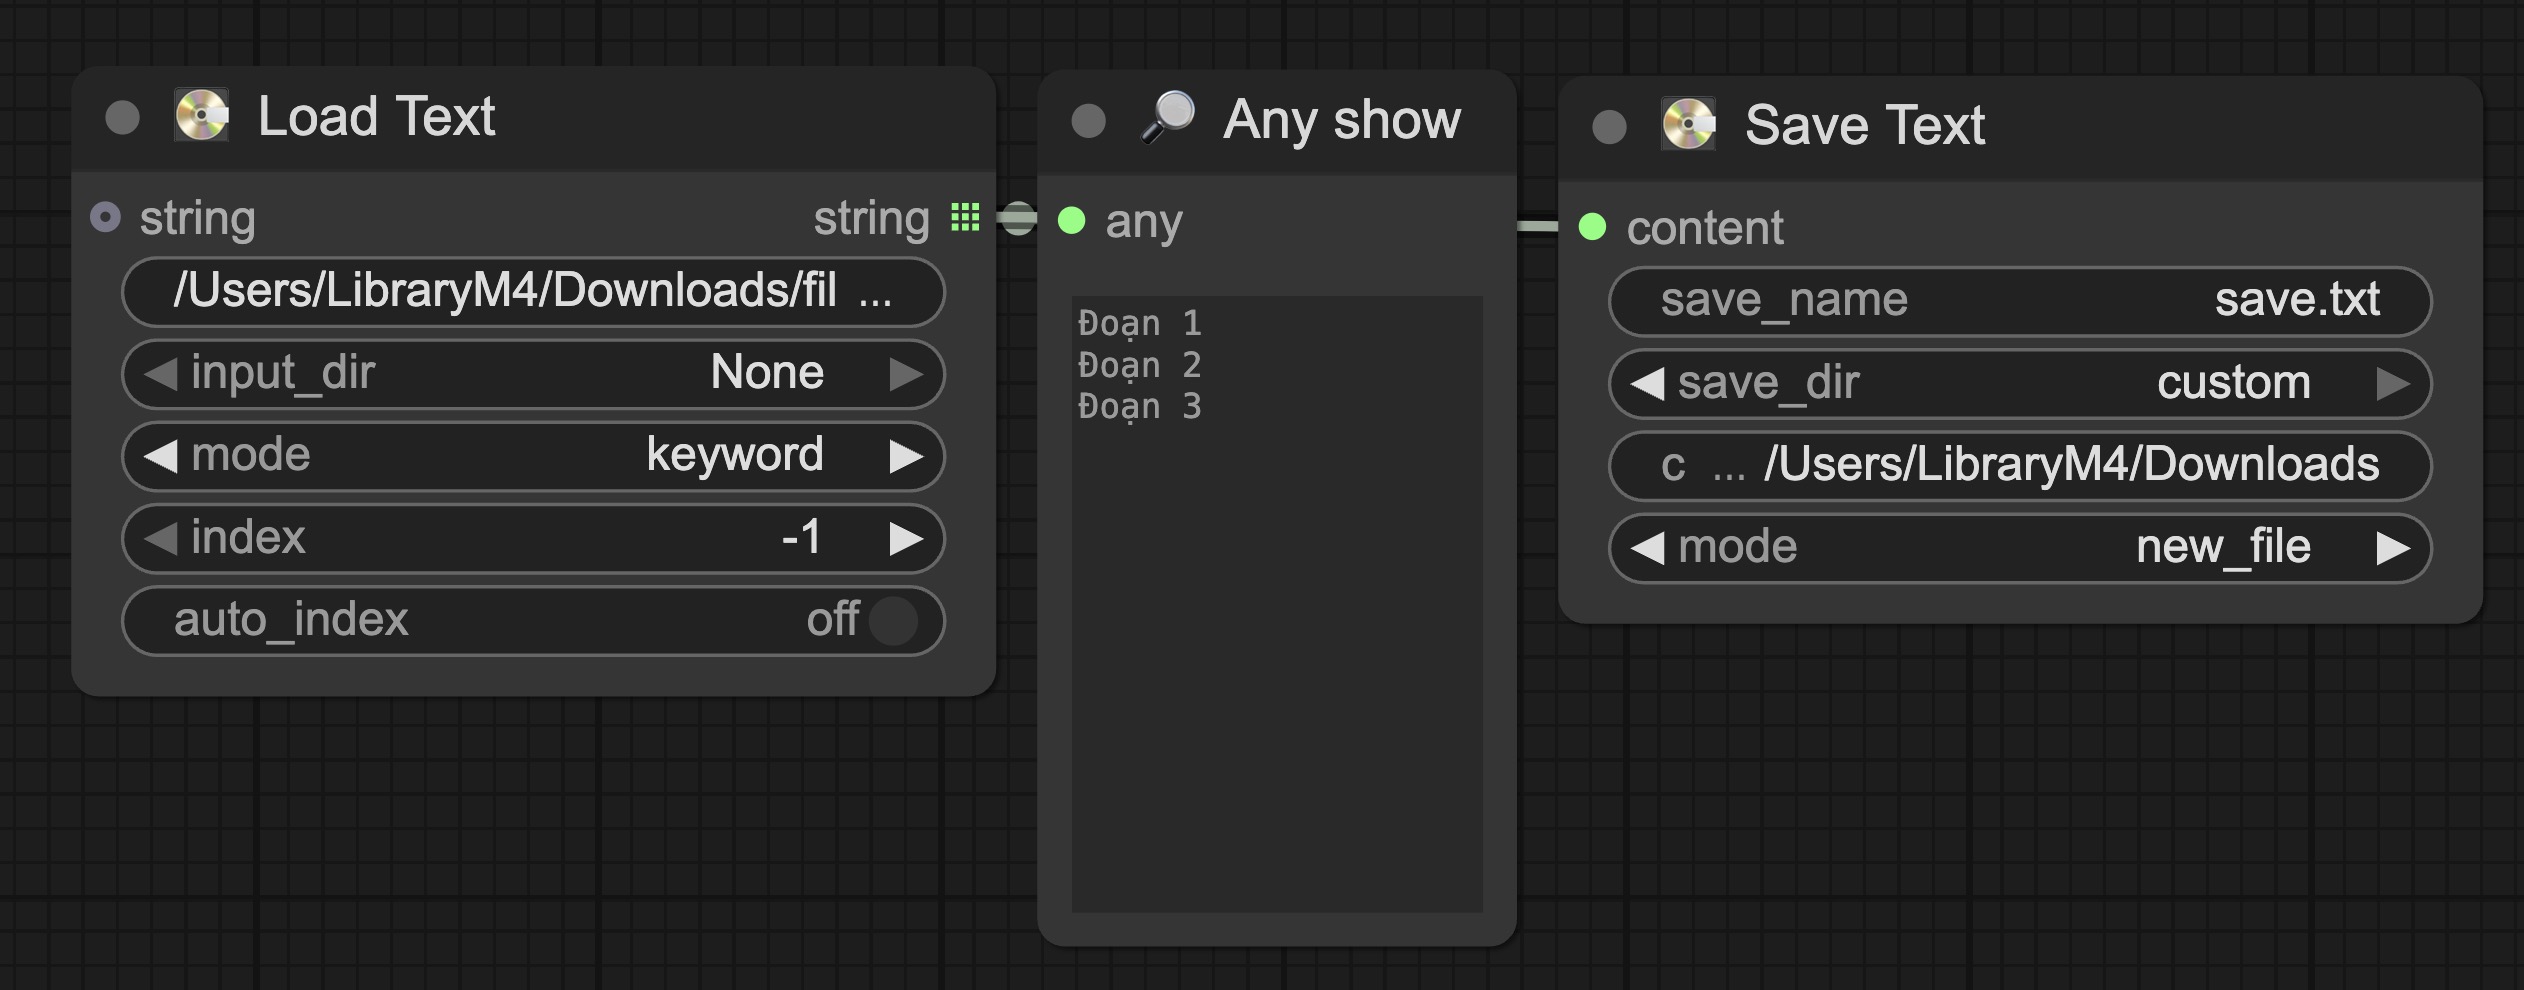
💽 Load Text | 💽 Save Text
- A set of nodes that support handling .txt files, including reading, saving, and editing text files.
- The 💽 Load Text node has three text loading methods in order of priority: external string input, custom .txt path, and .txt files from the input folder.
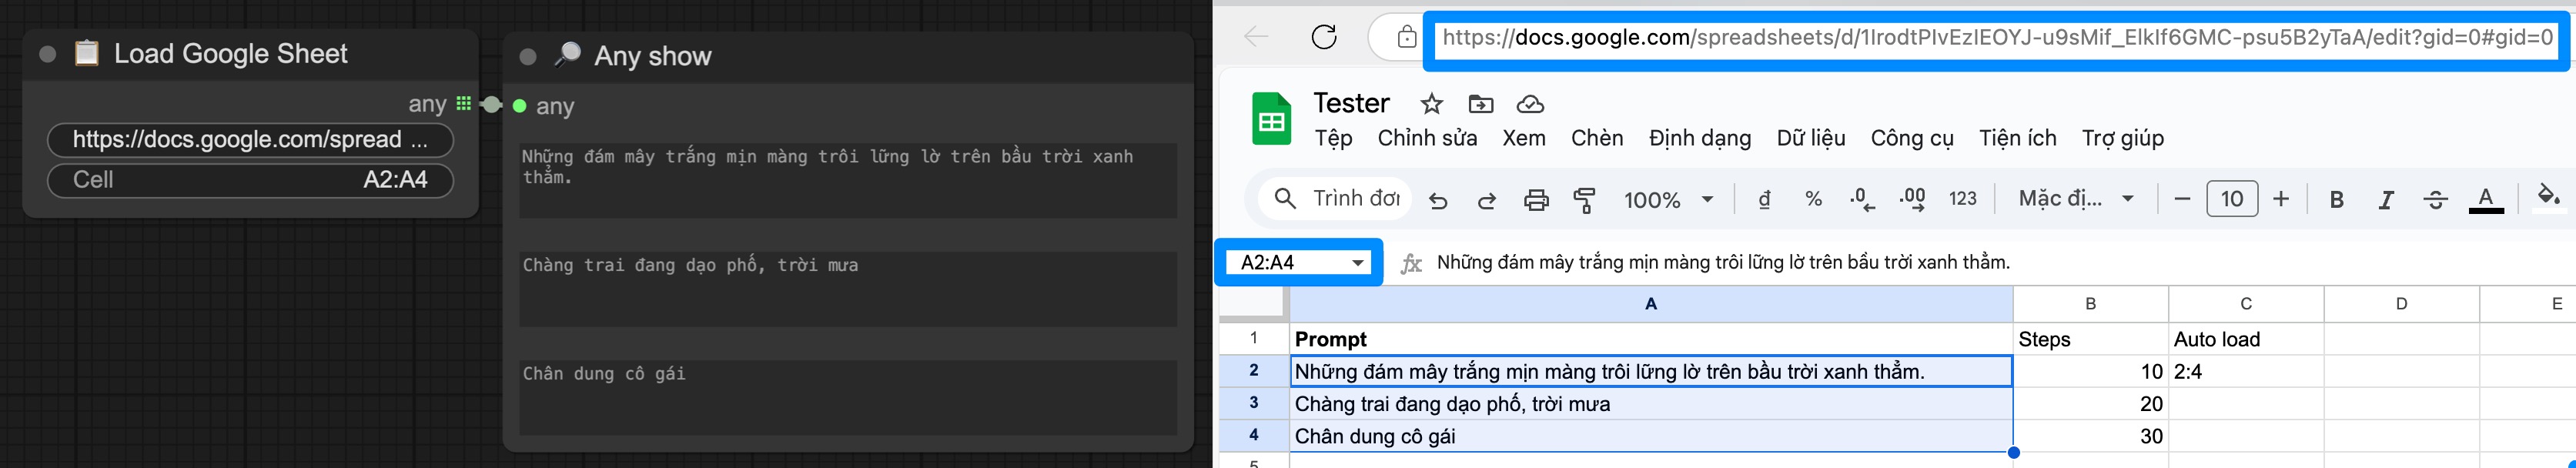
📋 Load Google Sheet
- A node that supports reading data from publicly shared Google Sheets.
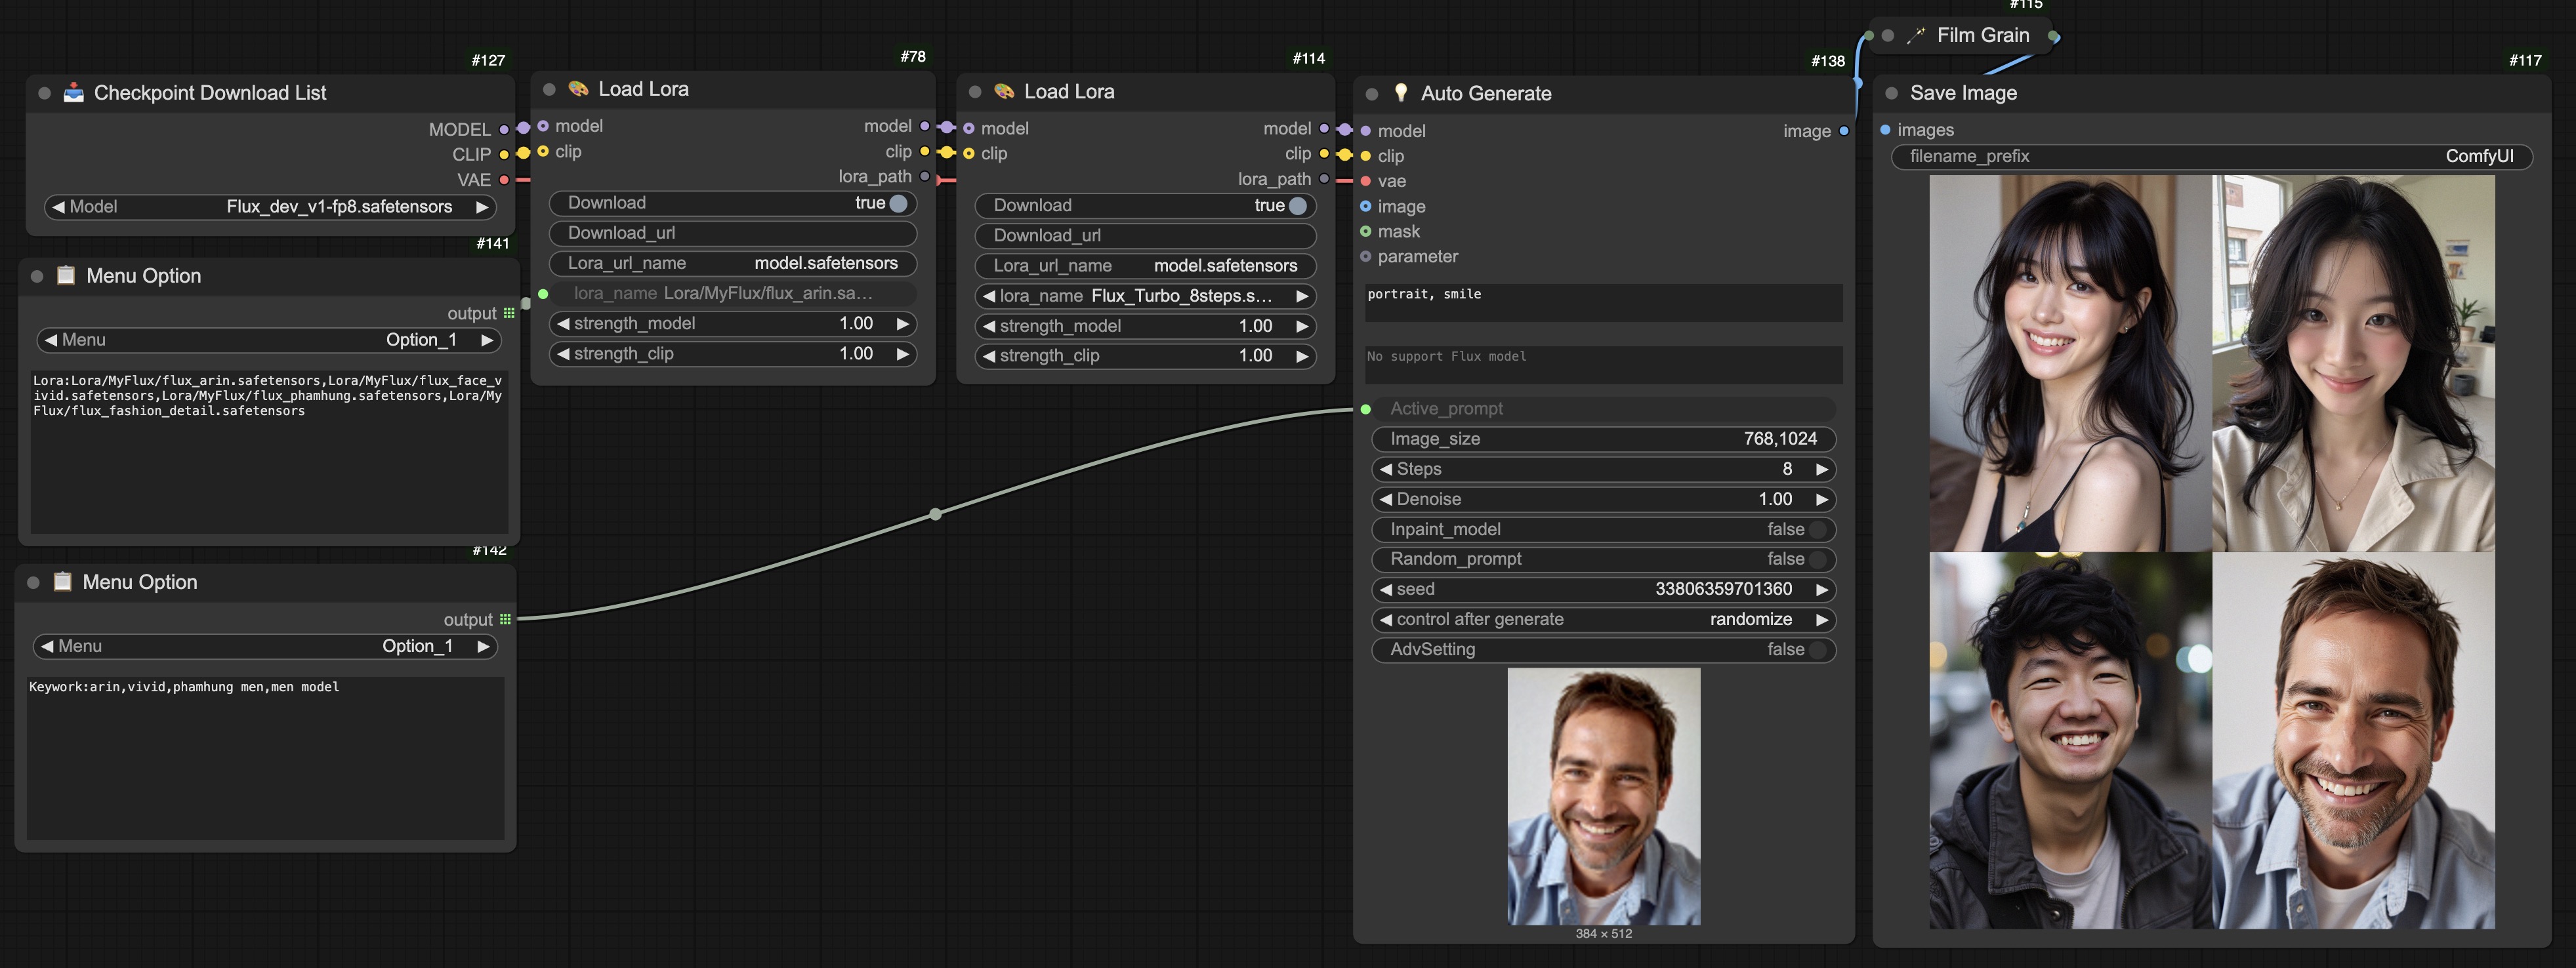
📋 Menu Option | 🔄 Dic Convert
- Nodes that support creating automated options and dynamically changing variables based on input.
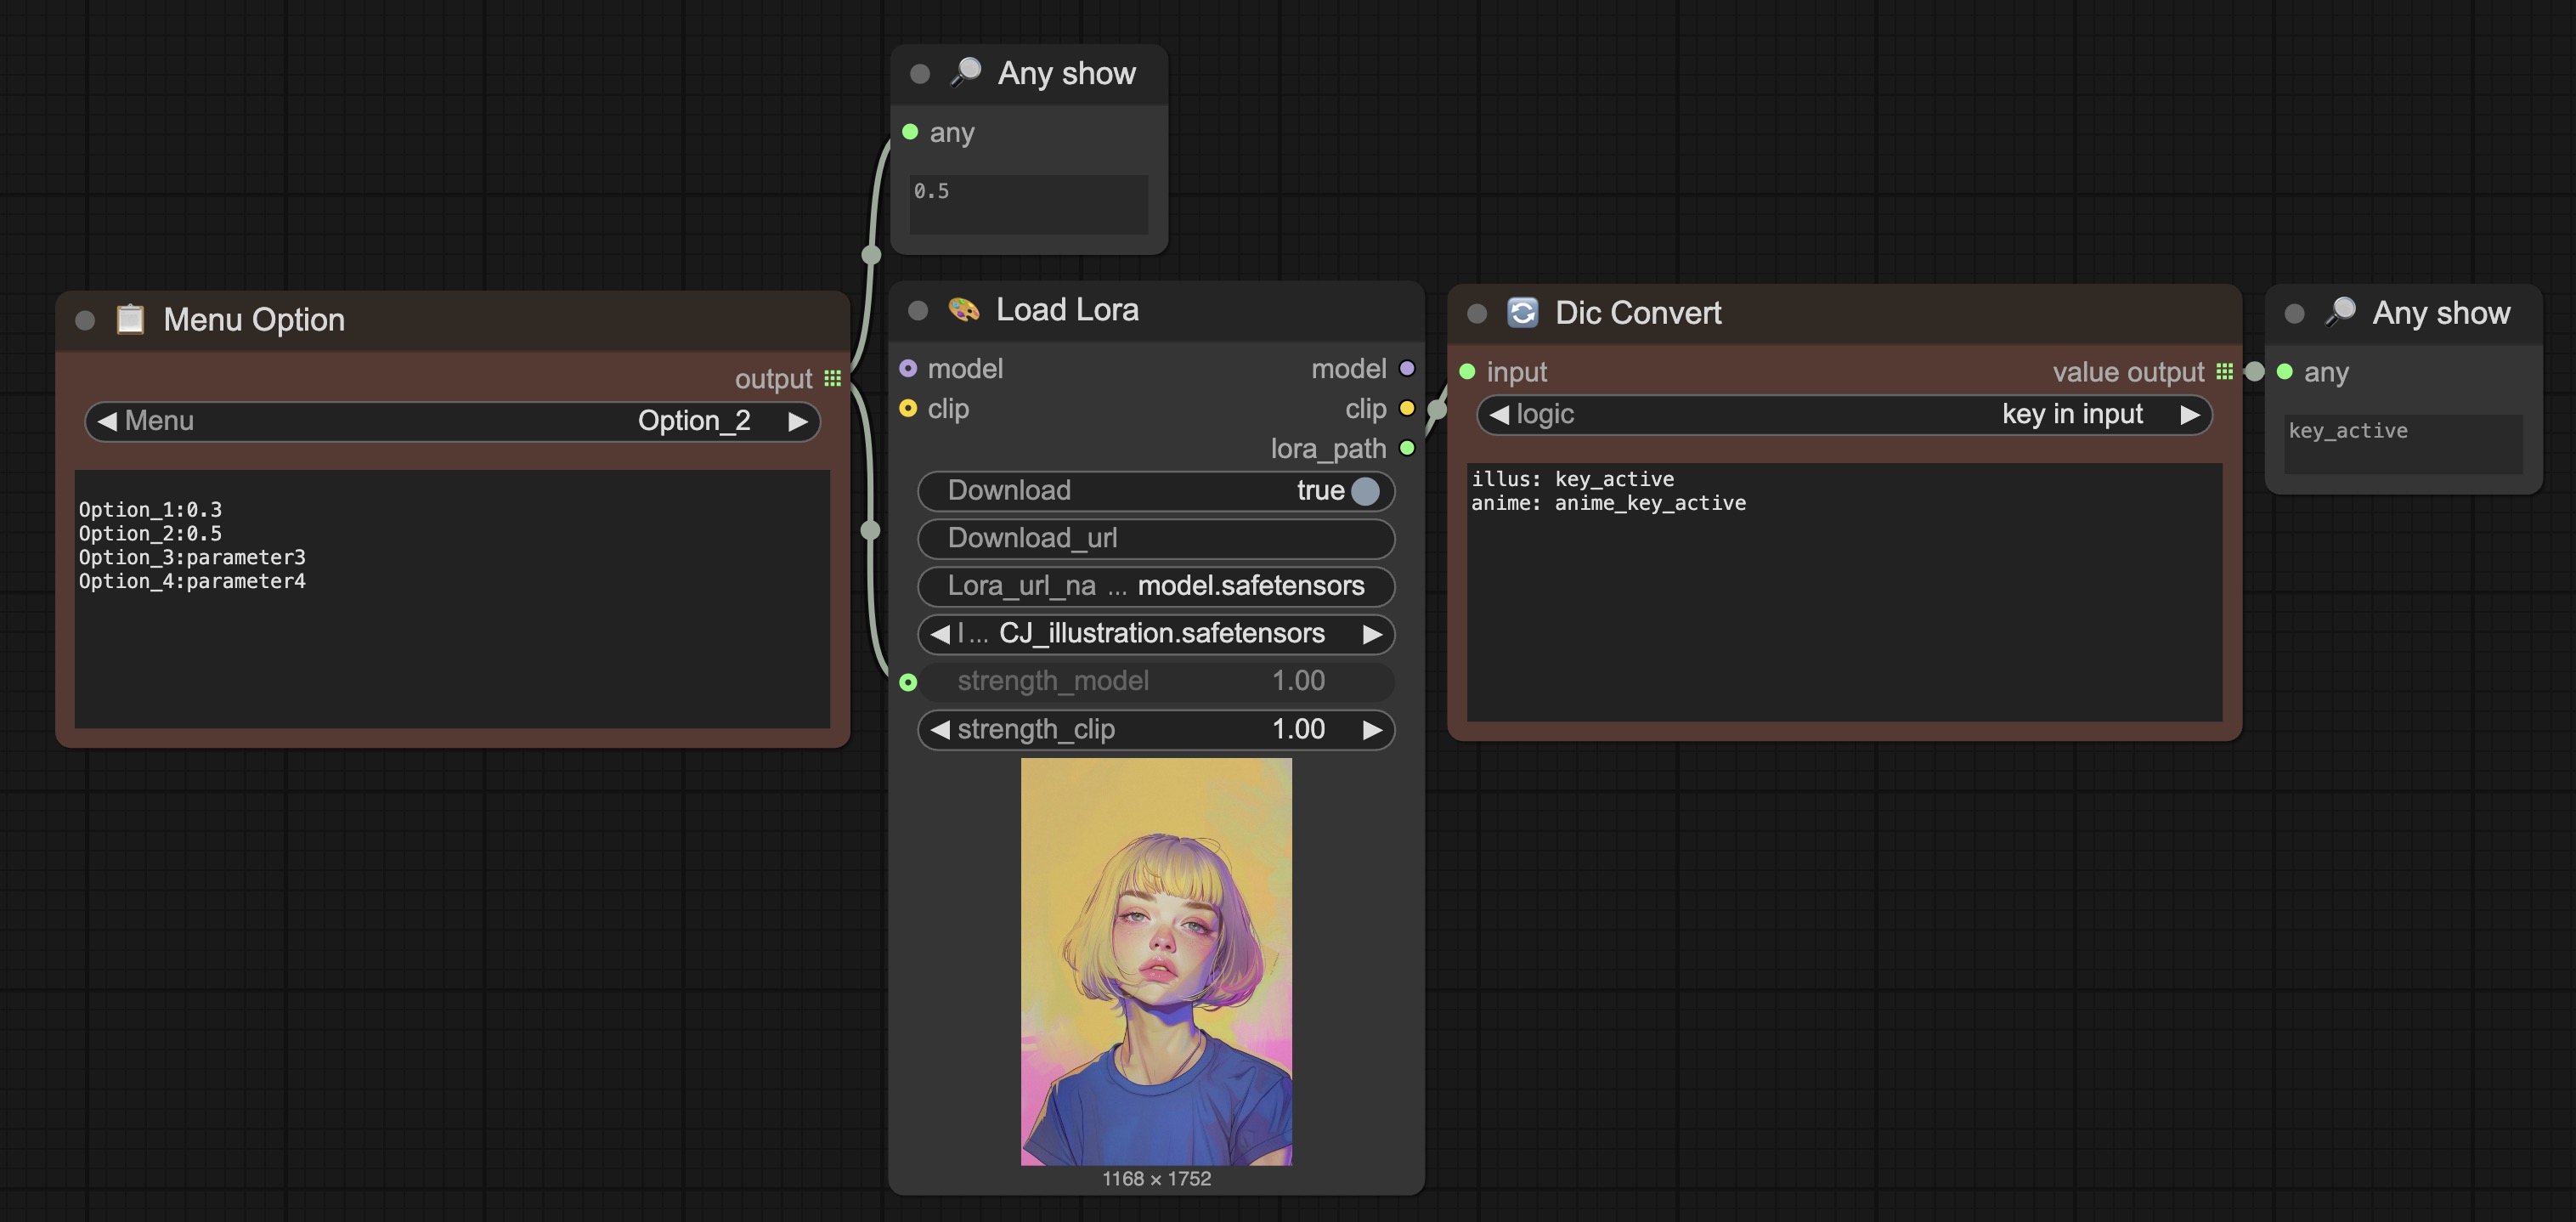
🎲 Random Prompt | 📋 Menu Option Extra | 🎚️ Sliders (x4)
- Quick prompt randomizer plus helper widgets (extra menu option, slider100, slider1, custom int/float slider) to speed up UI prototyping.
Dev
- Run Python Code: inline execution of custom Python functions inside a workflow (supports dict/list unpacking).
- Kontext Reference / Qwen Edit Text Encoder (+ Plus): advanced conditioning/text encoders for reference-driven or Qwen-edit models.
- Save Image Compare + Image Gallery also double as utility nodes for debugging and dataset management.
API
Support the use of AI models through API
- Support the default API setting through the file:
.../SDVN_Custom_node/API_key.json(Rename API_key.json.example and fill API)- Get Gemini API: https://aistudio.google.com/app/apikey
- Get HuggingFace API: https://huggingface.co/settings/tokens
- Get OpenAI API (Chat GPT, Dall-E): https://platform.openai.com/settings/organization/api-keys
- Get Deepseek API: https://platform.deepseek.com/api_keys
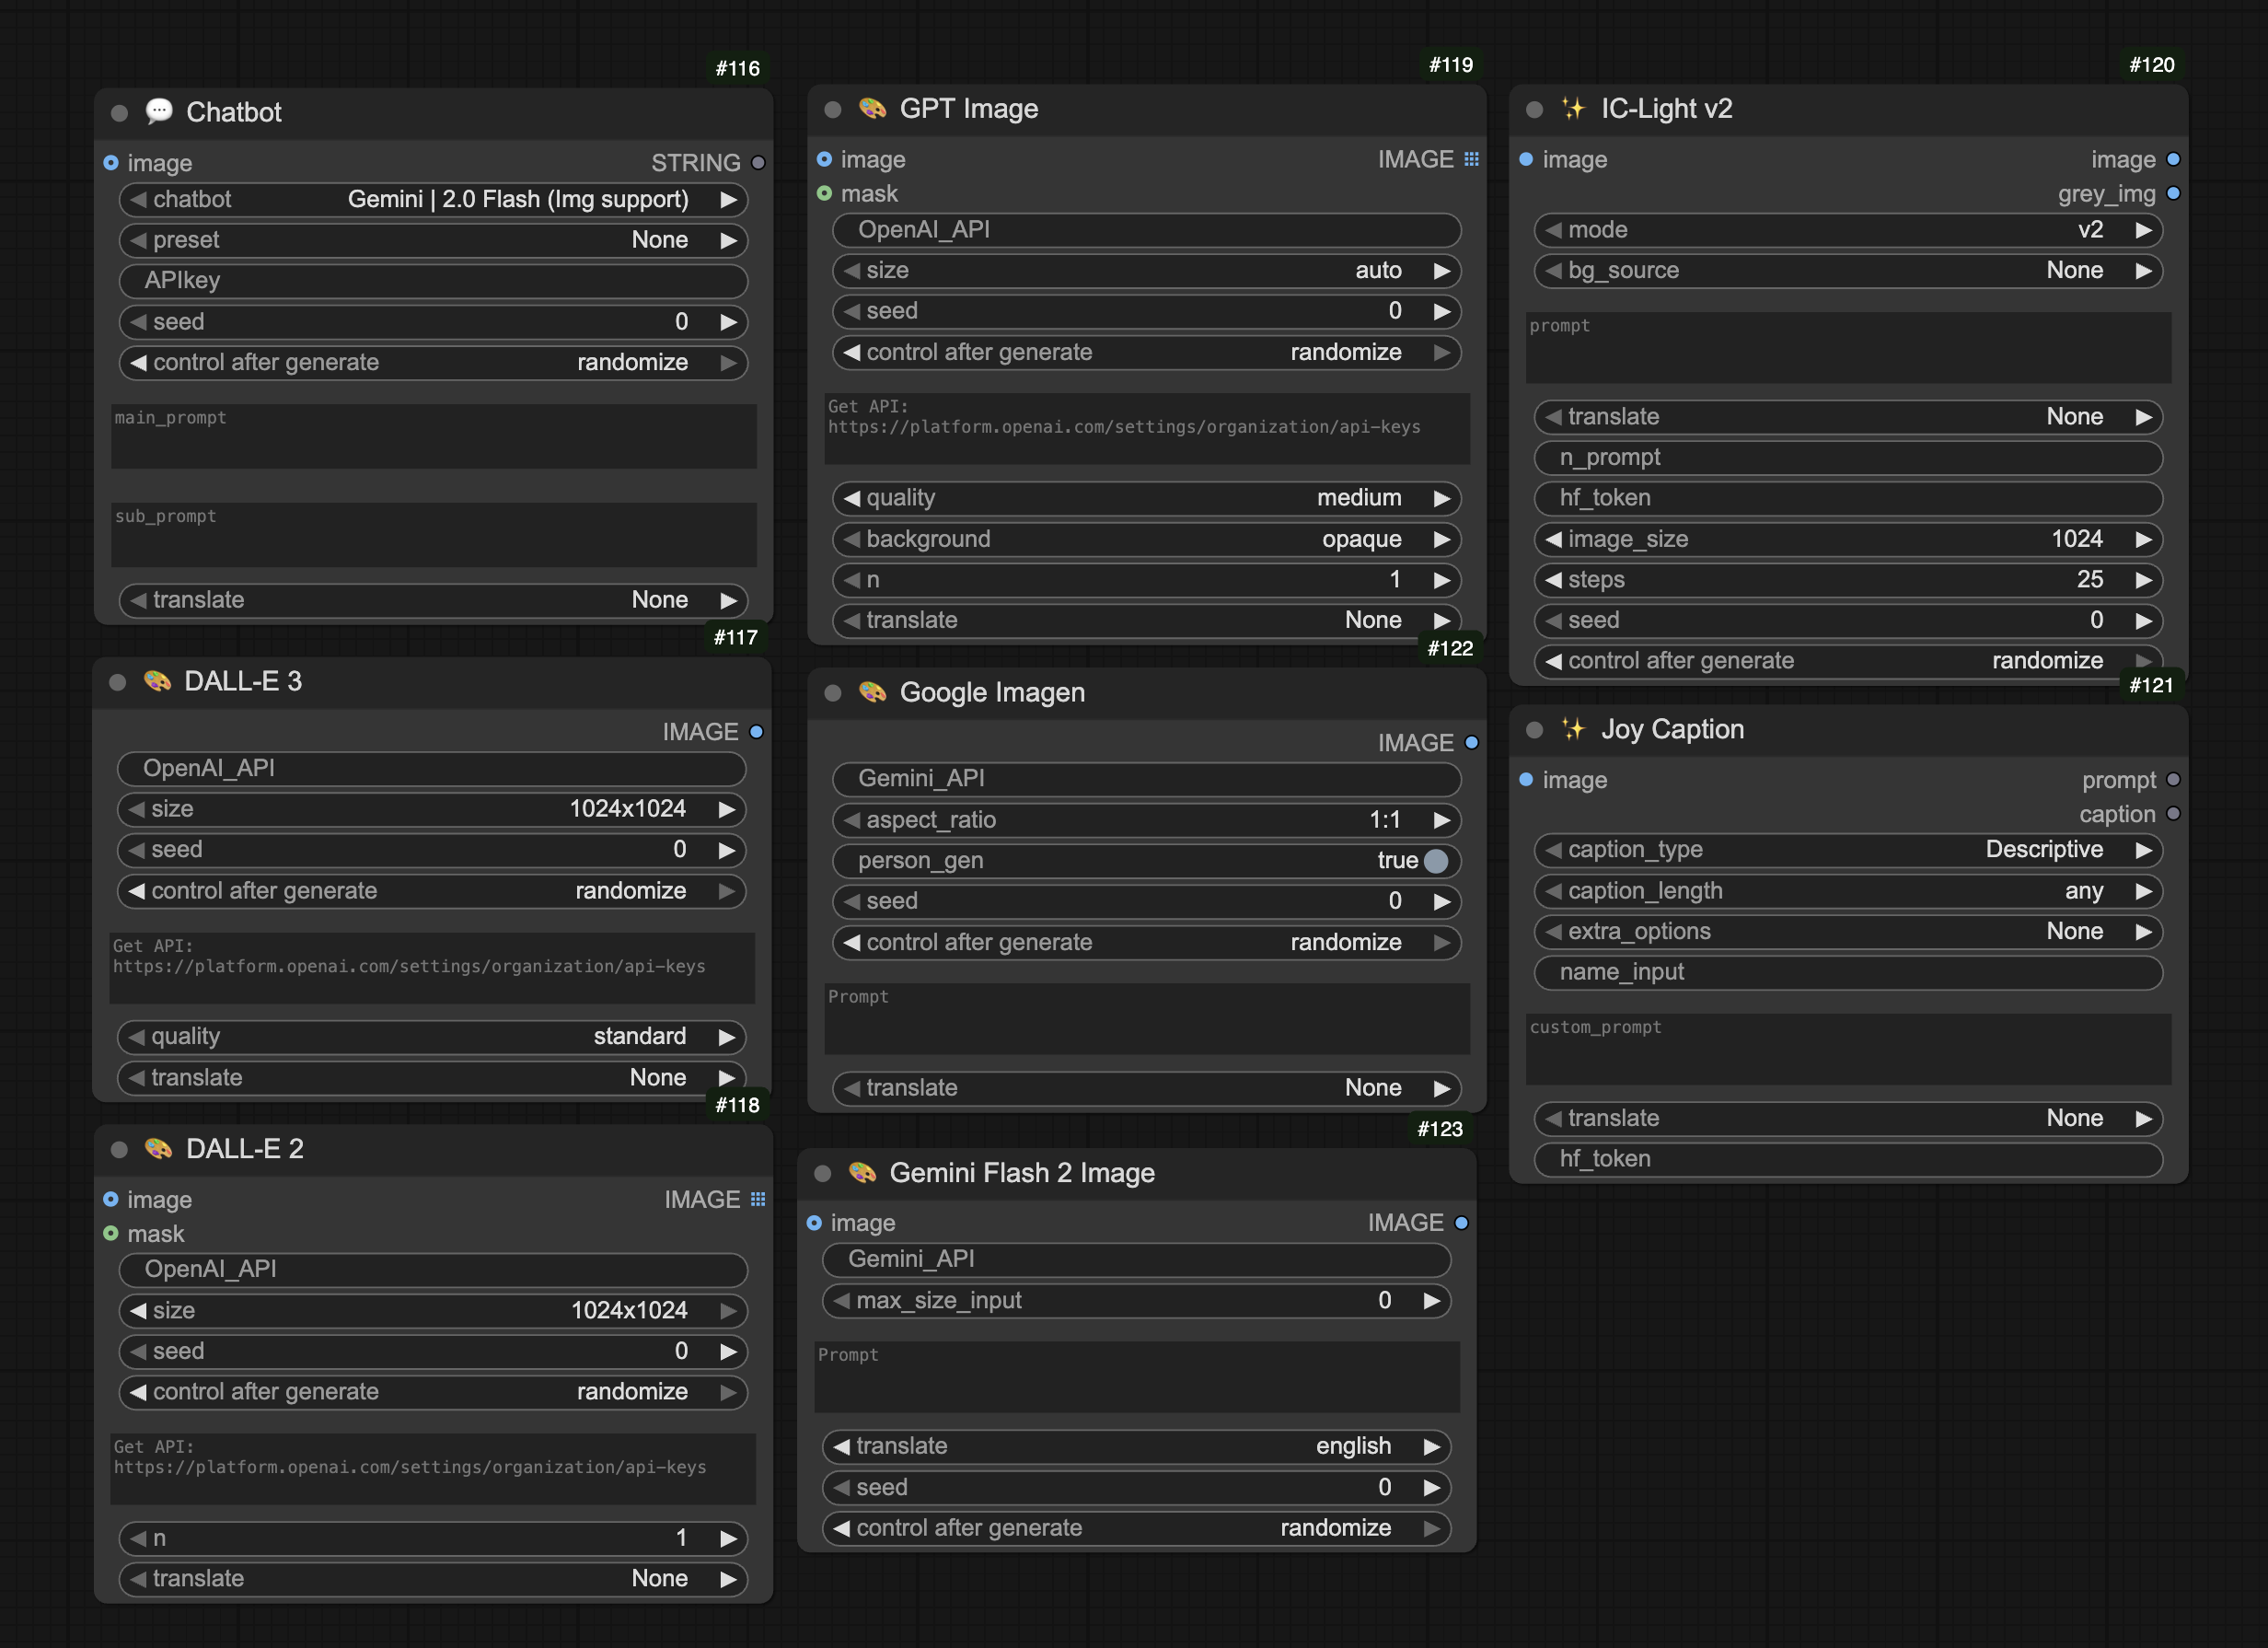
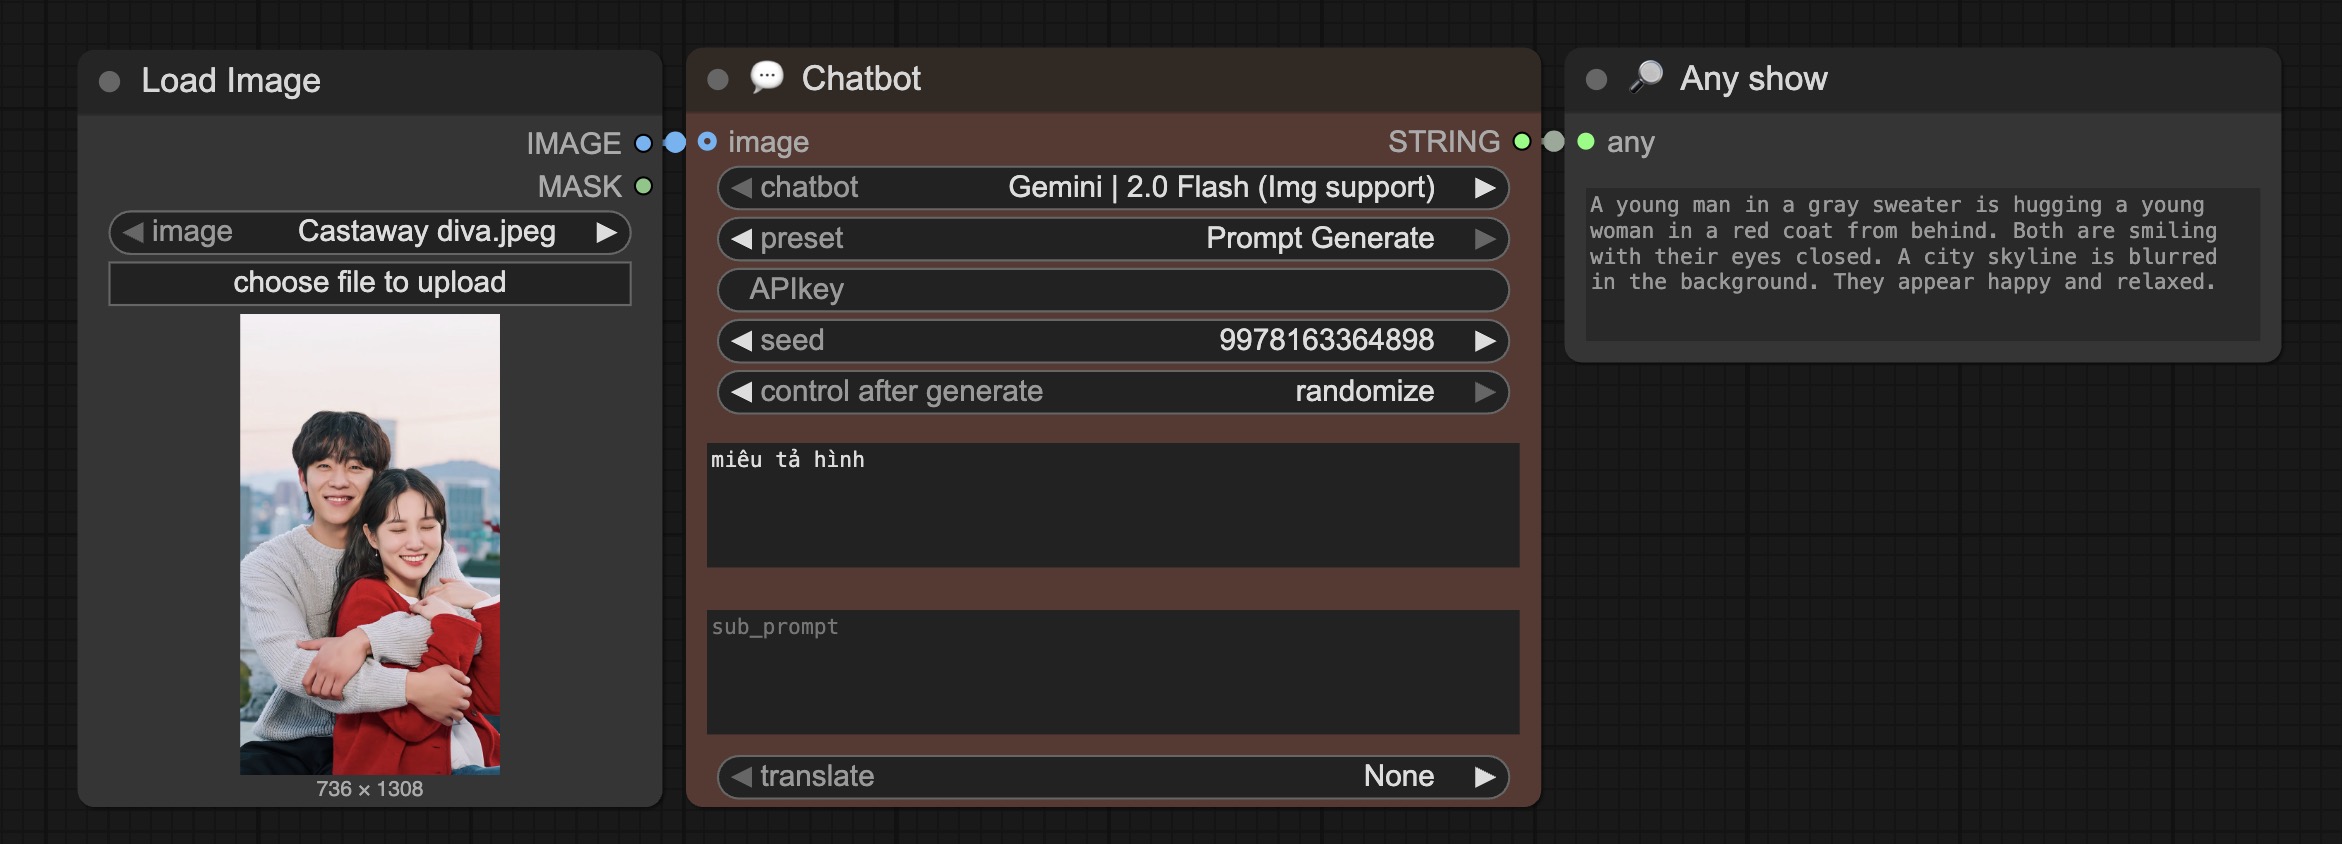
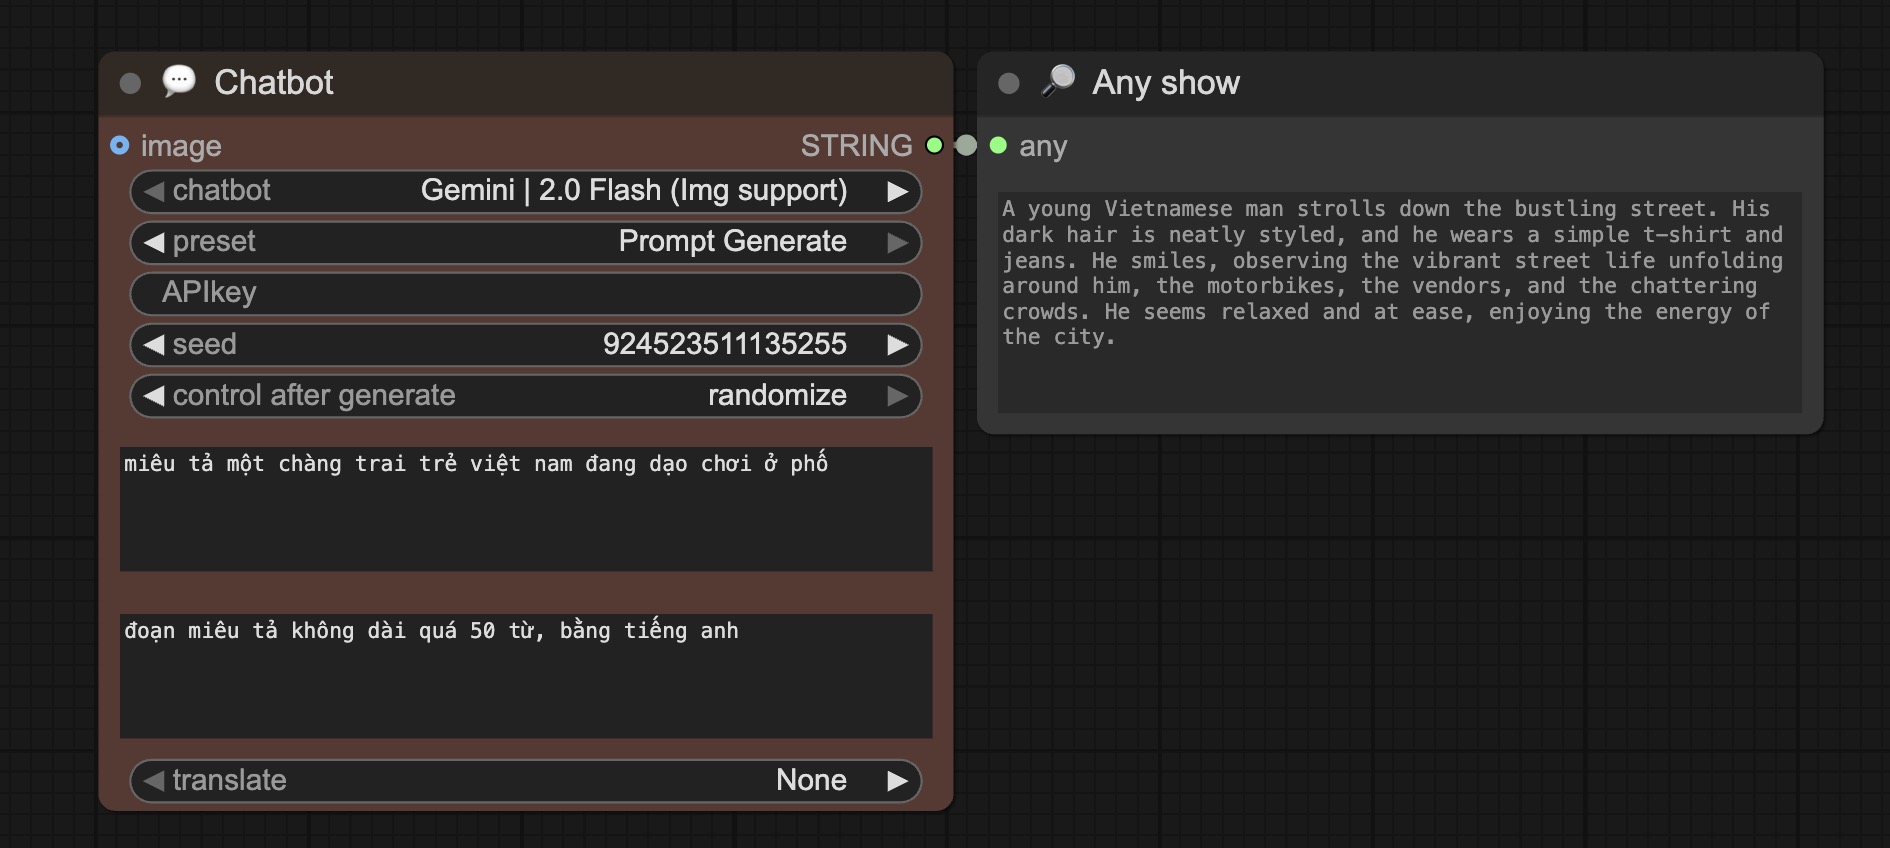
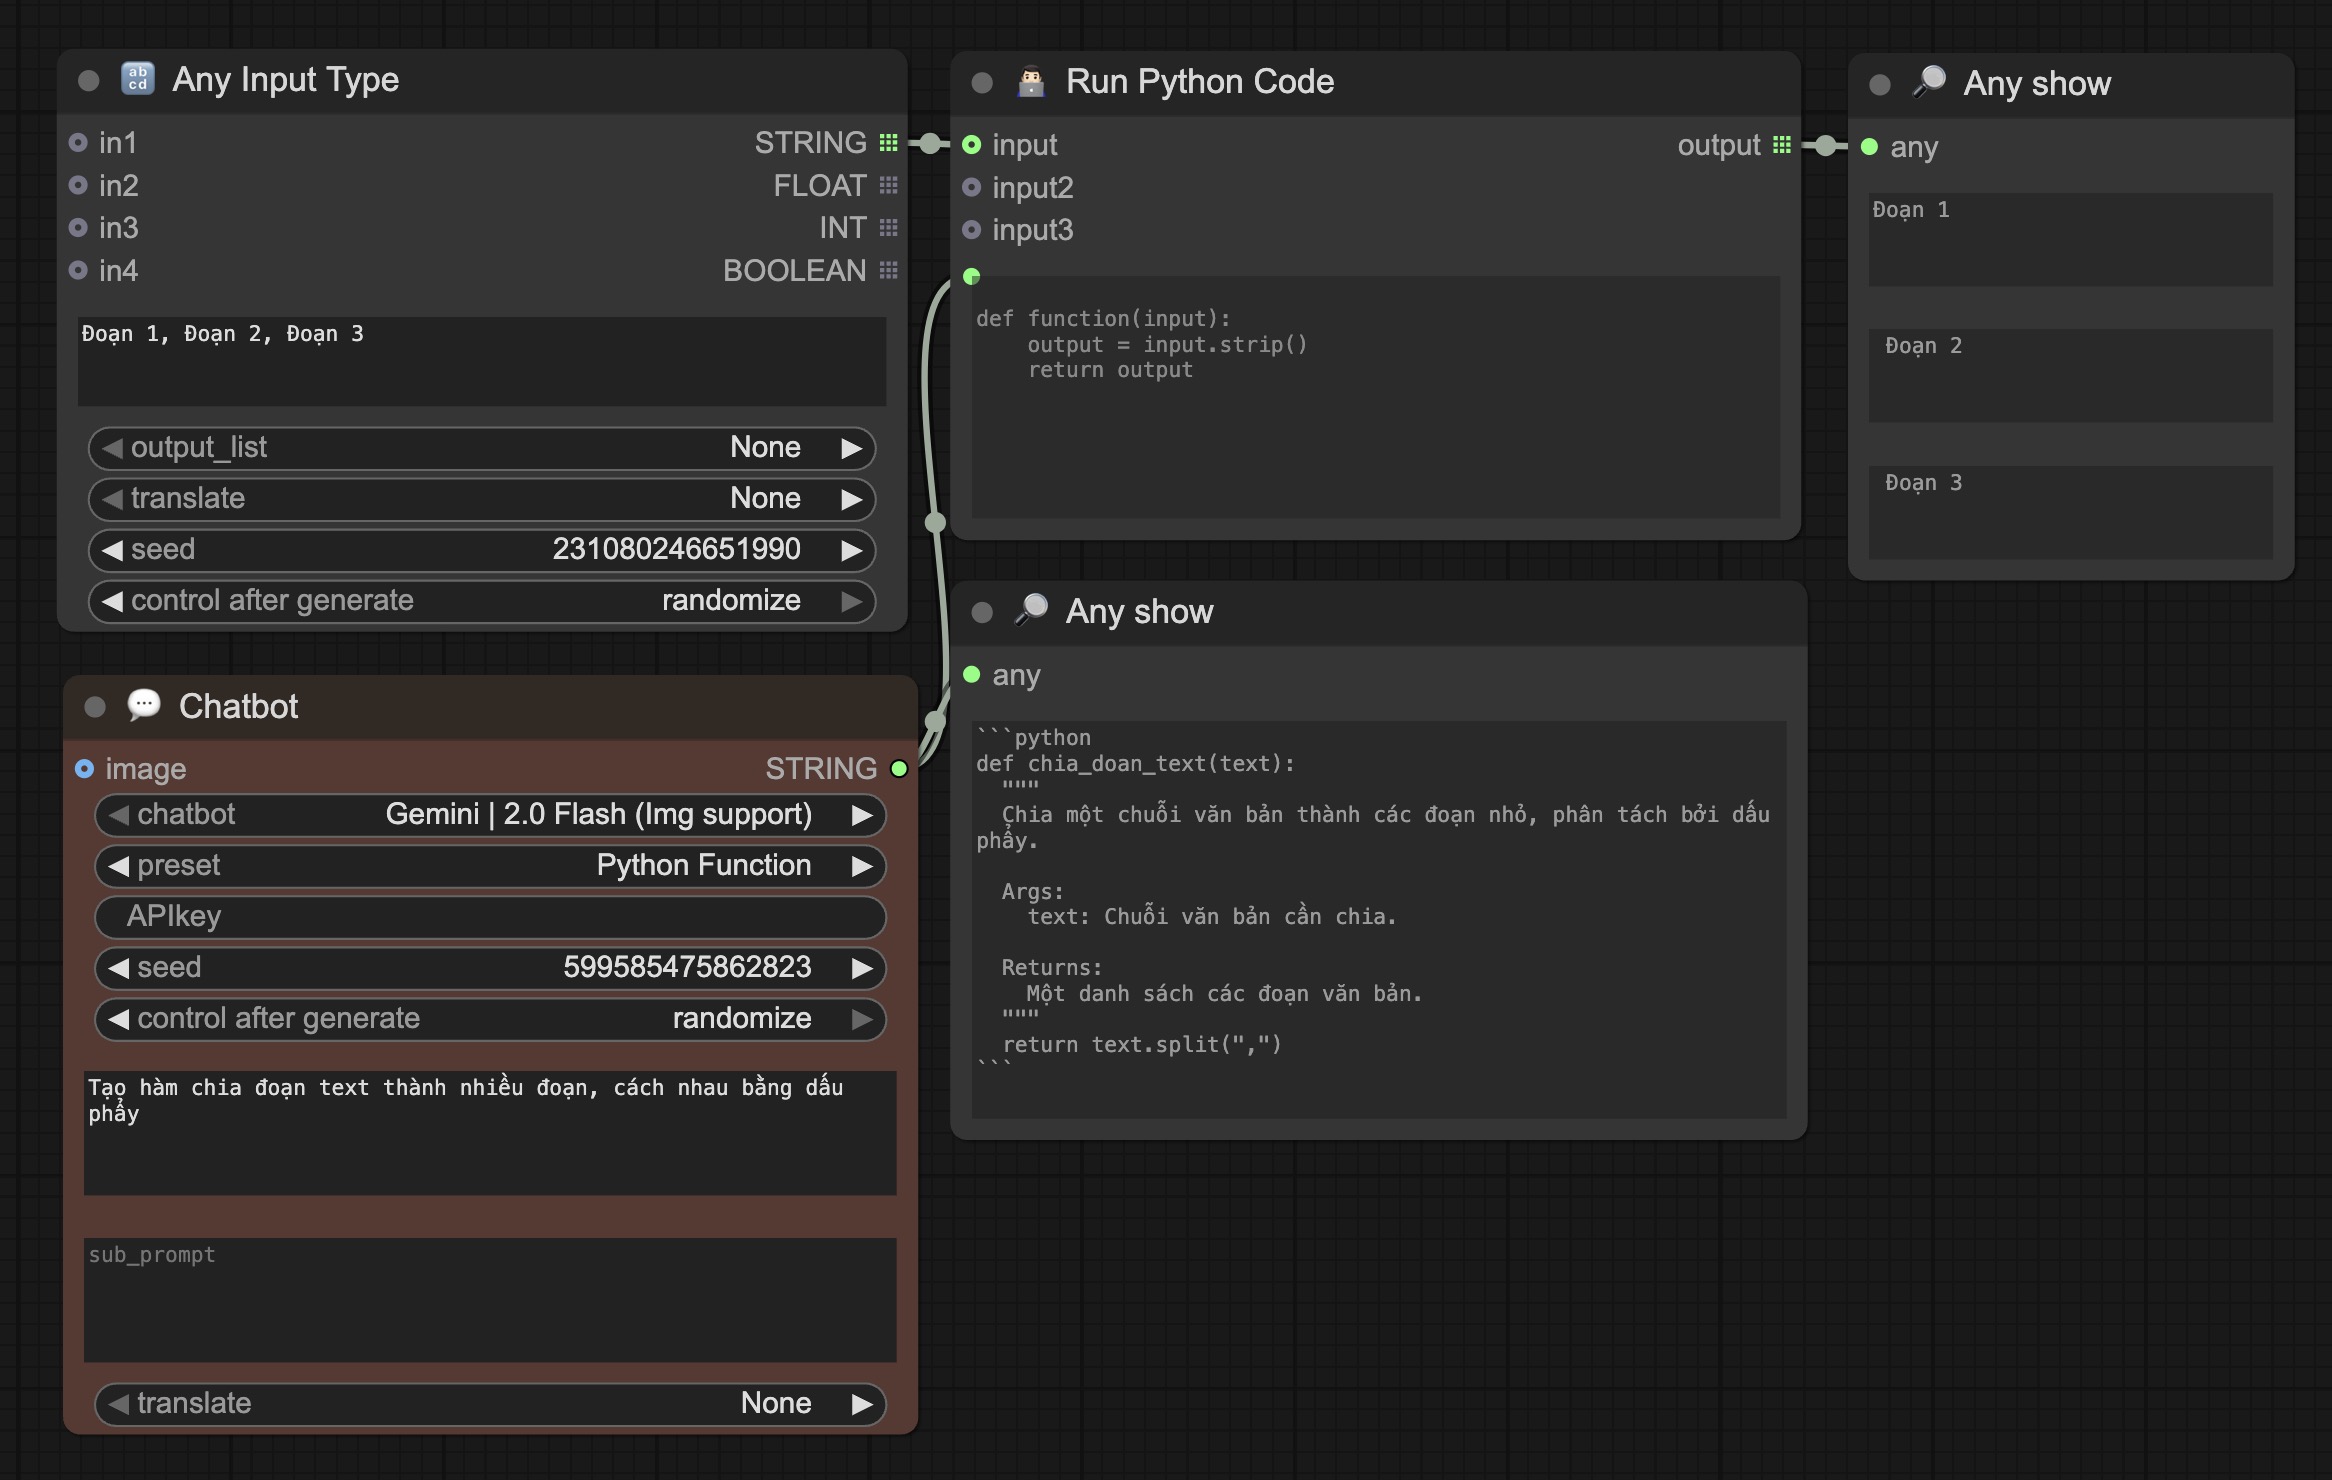
💬 Chatbot
- Image: Suport Gemini, ChatGPT
- Preset: Add history and sample statements in cases of each other
- Support translate and Dynamic prompt
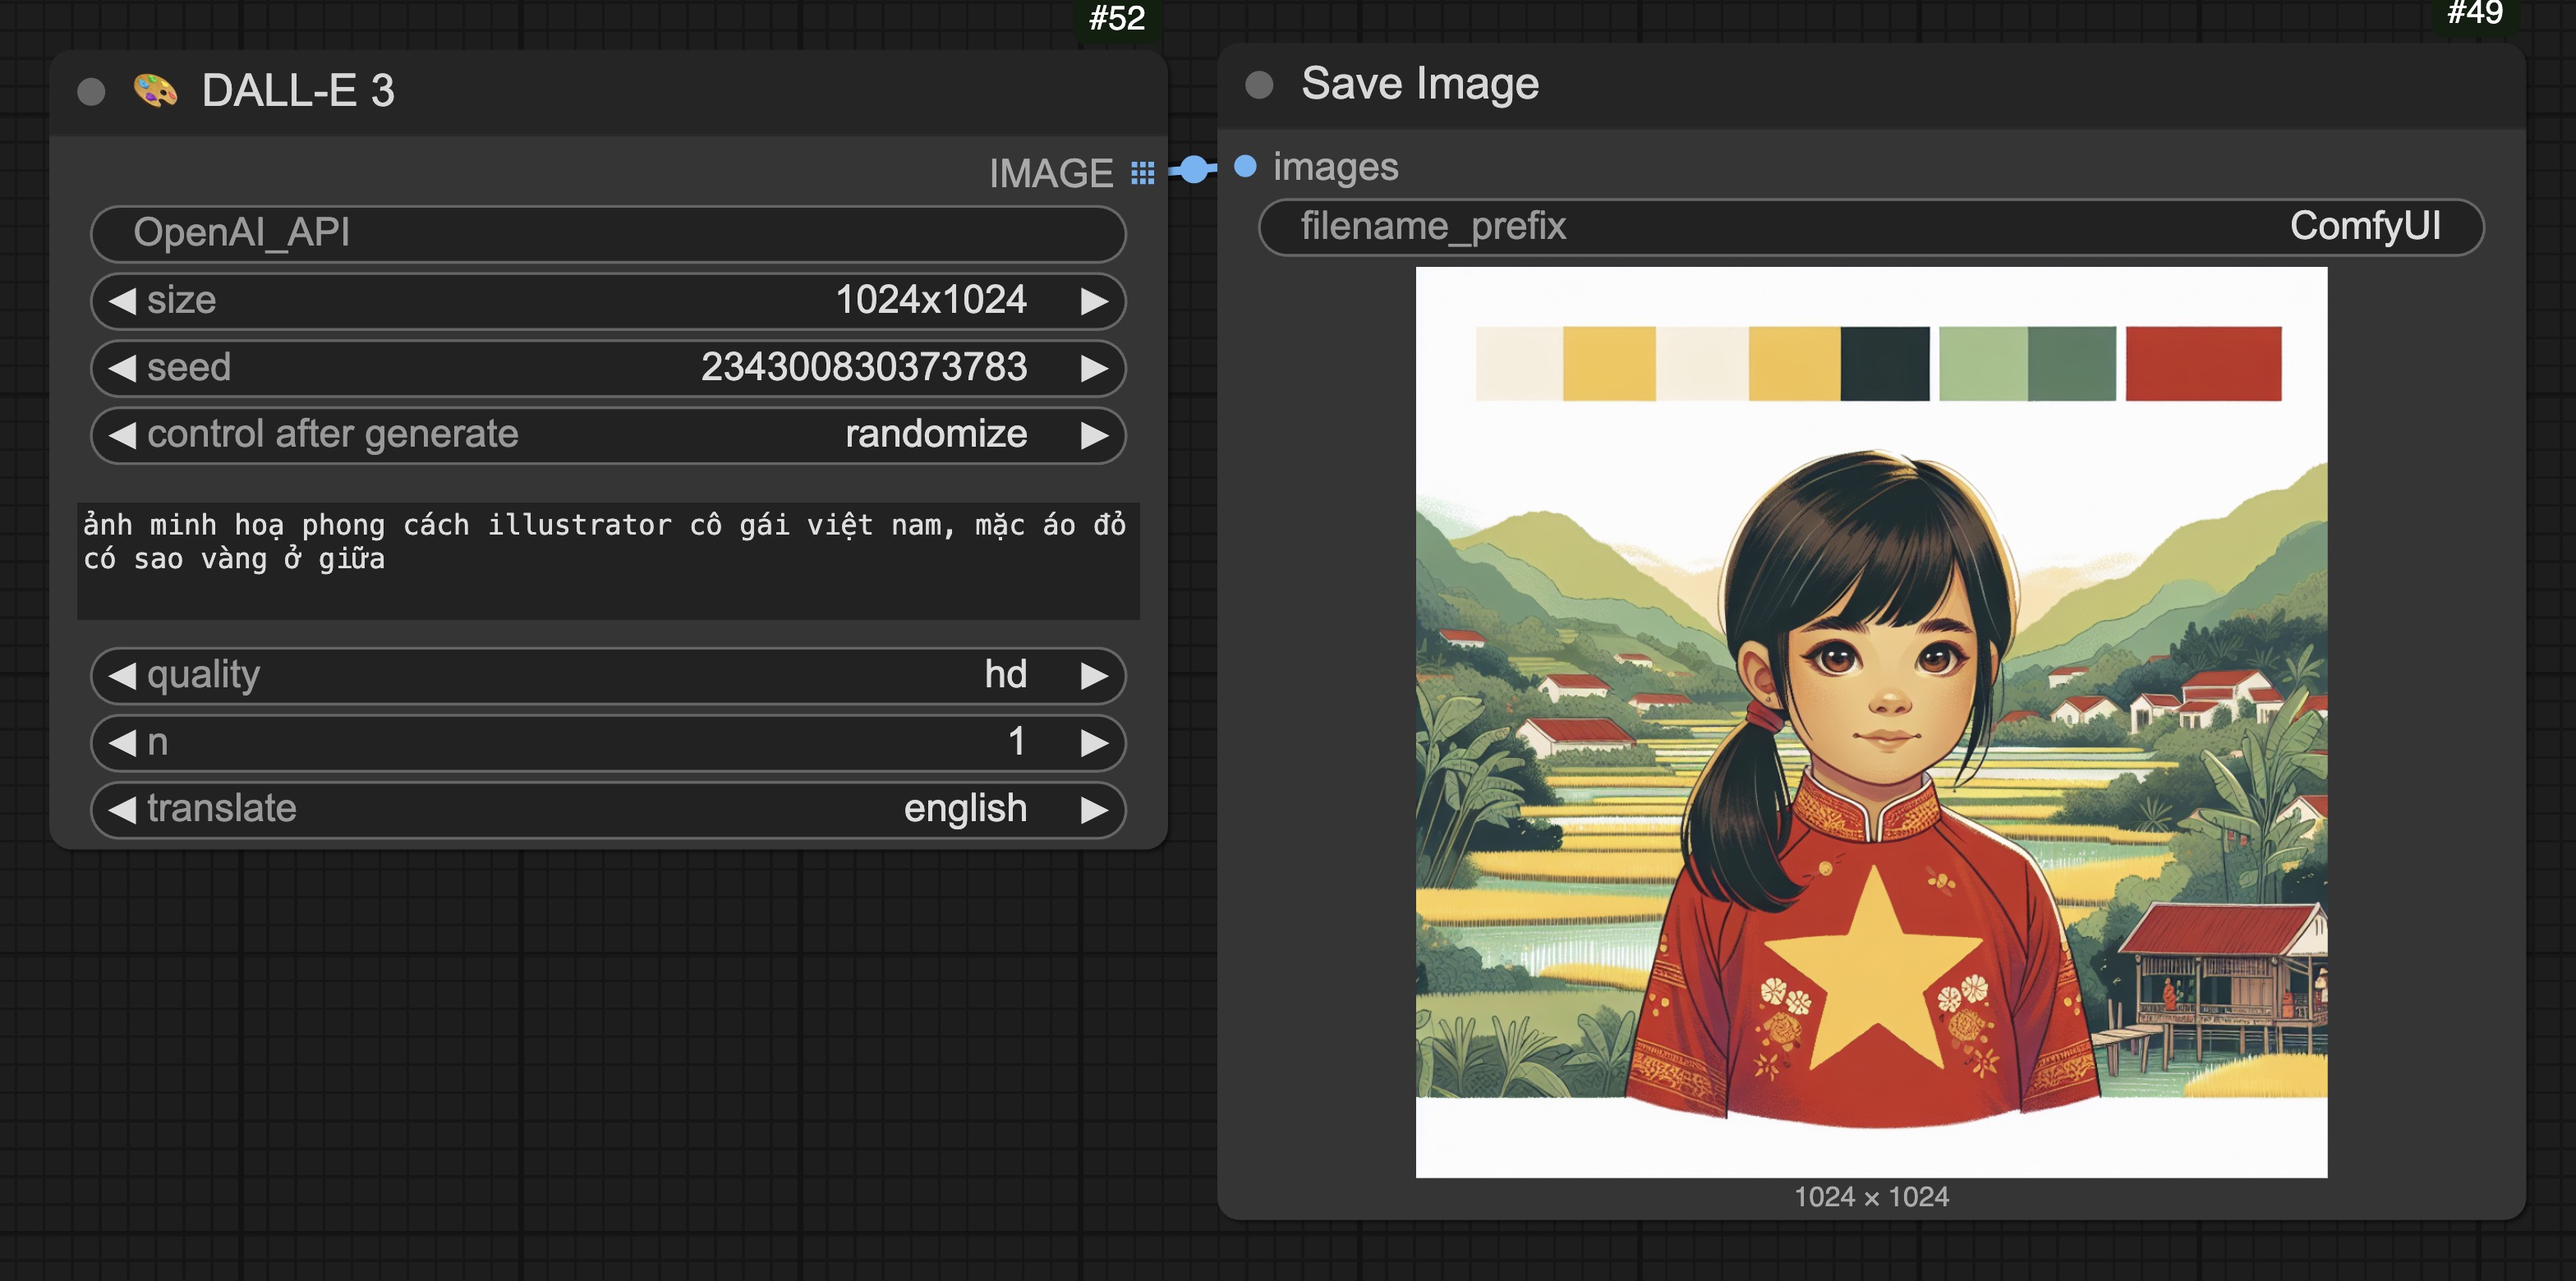
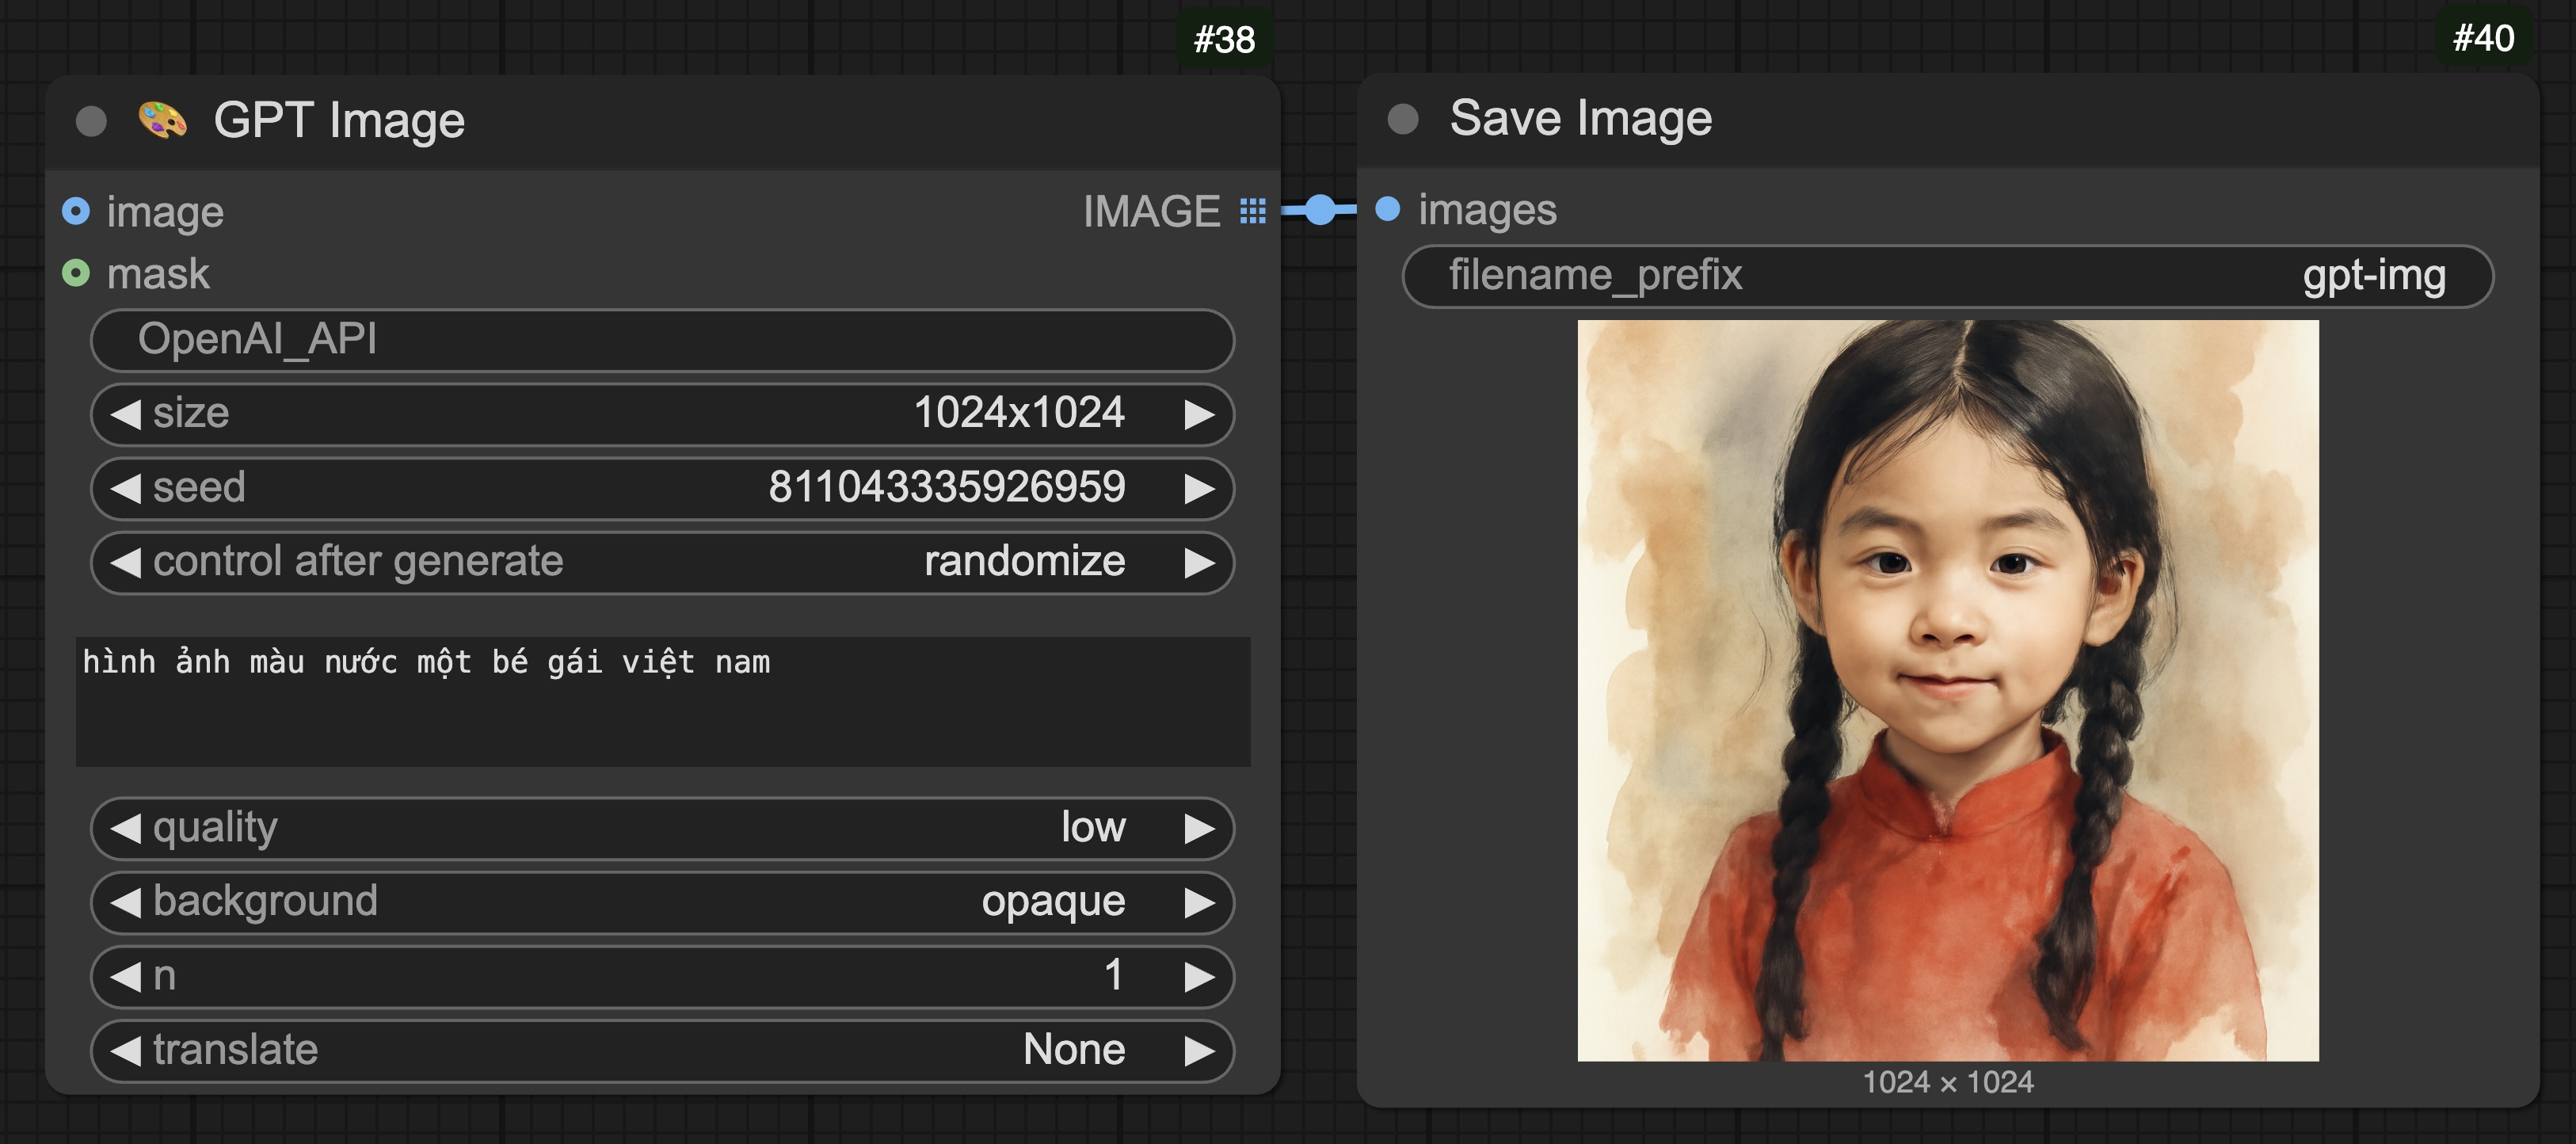
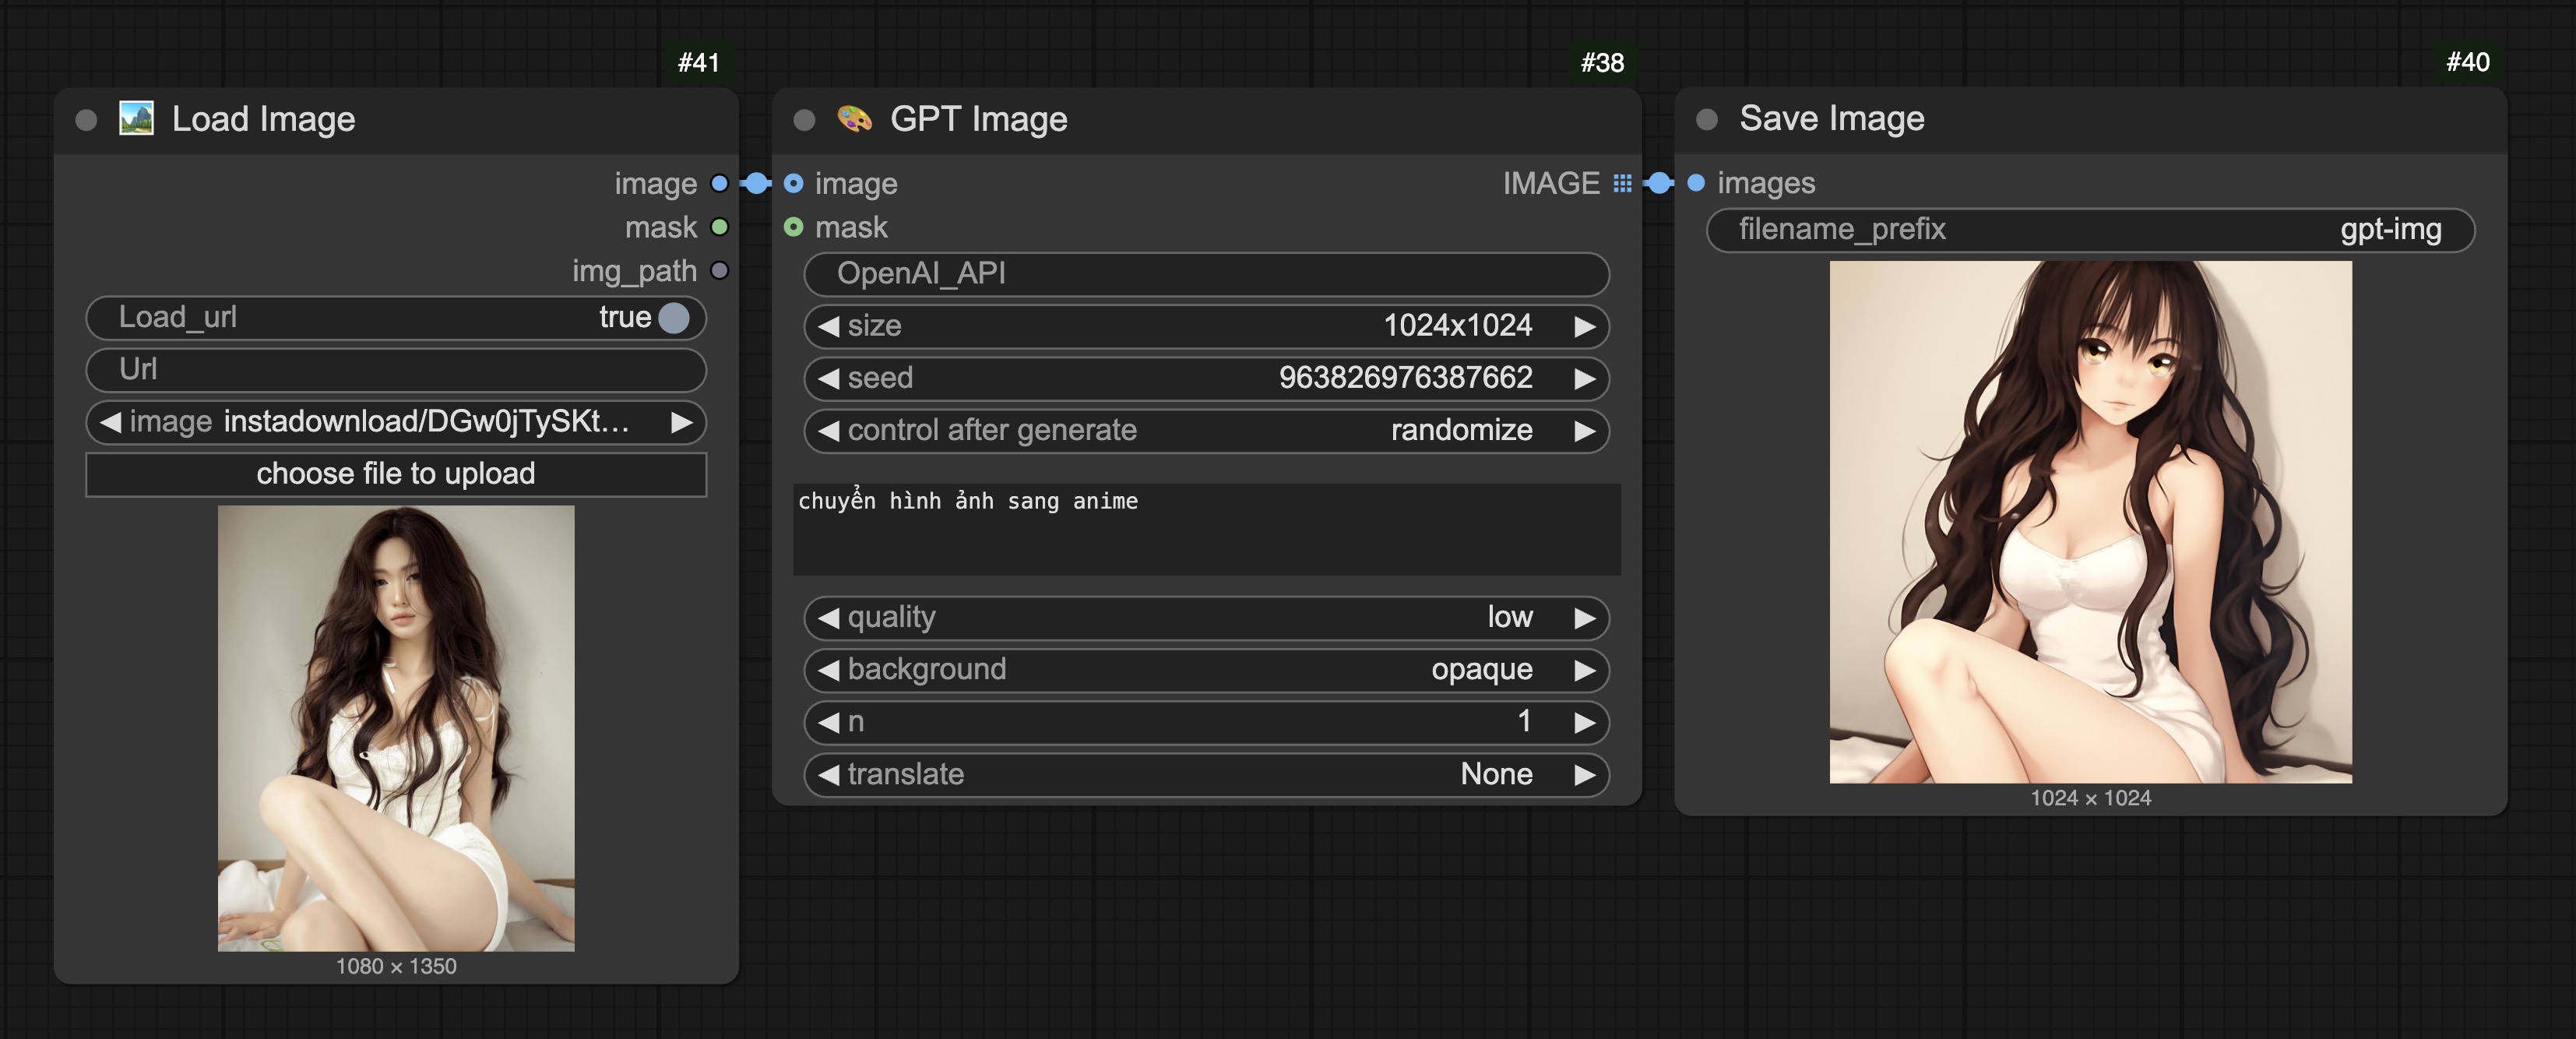
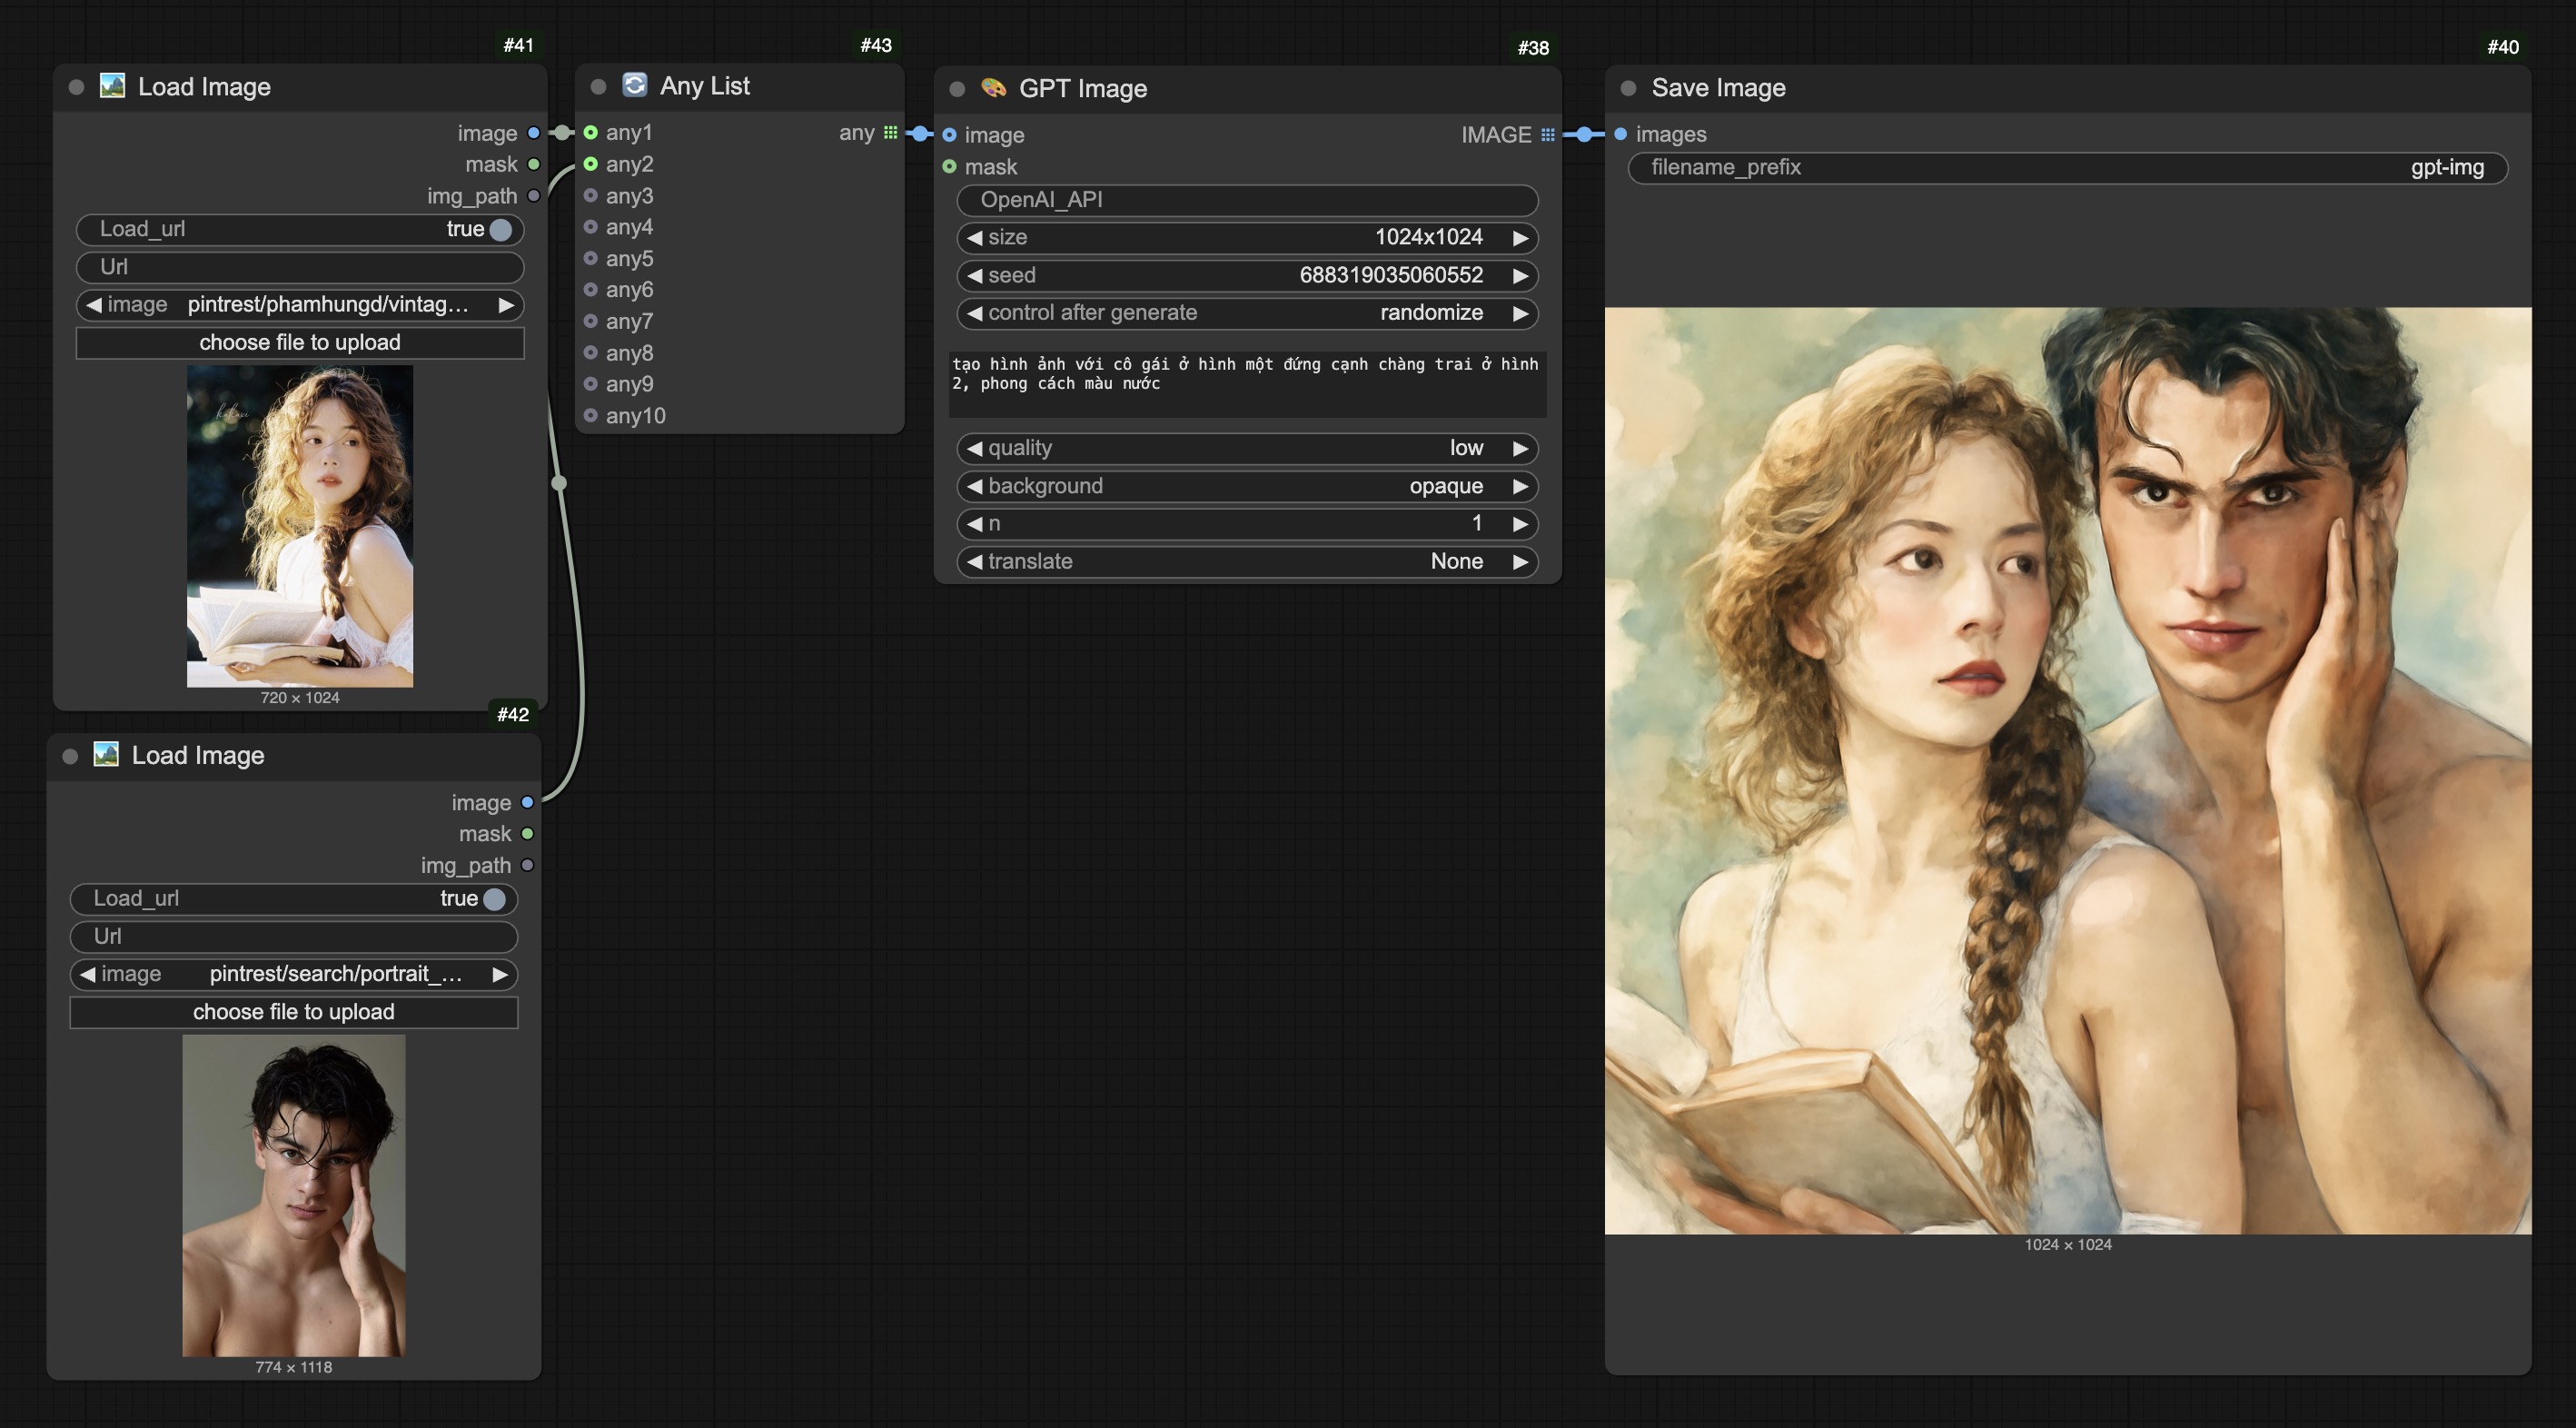
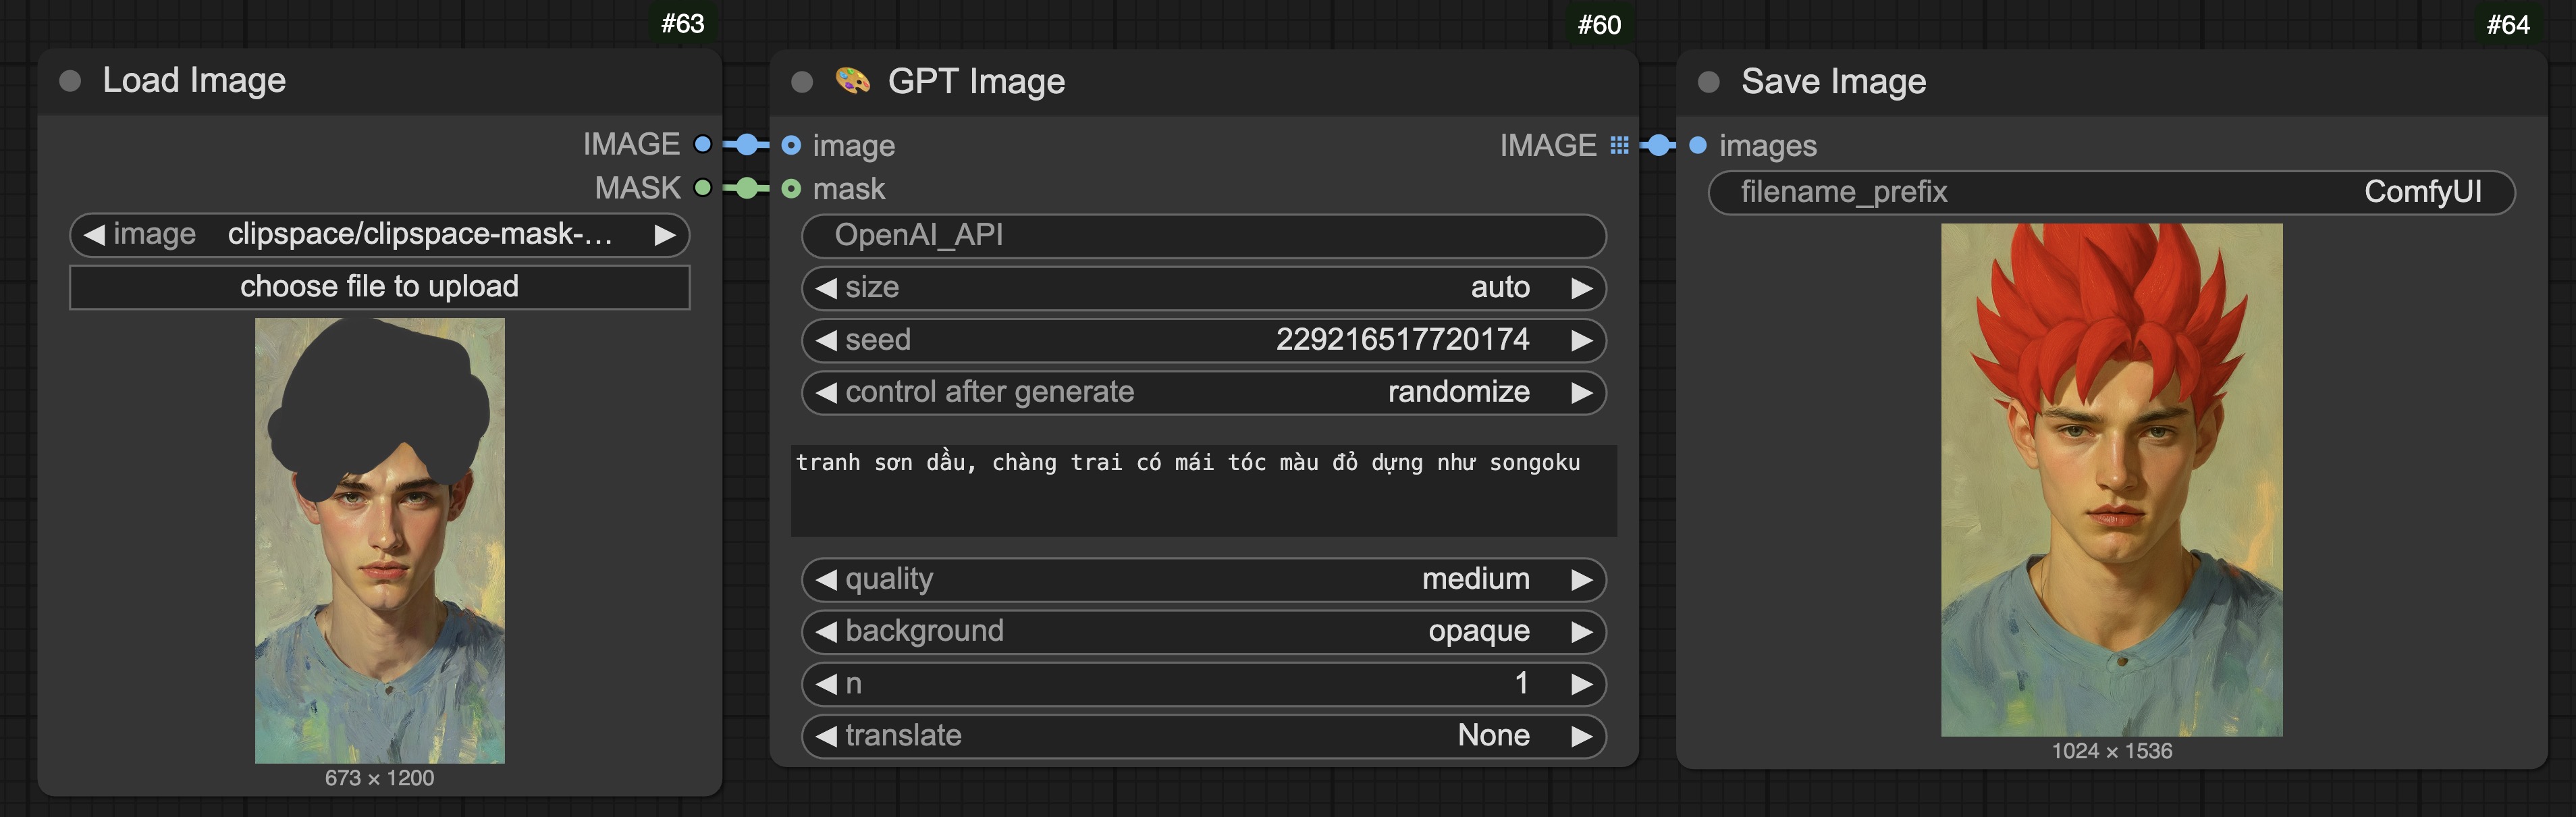
🎨 DALL-E (GPT Image) | 🎨 GPT Image
- Support translate and Dynamic prompt
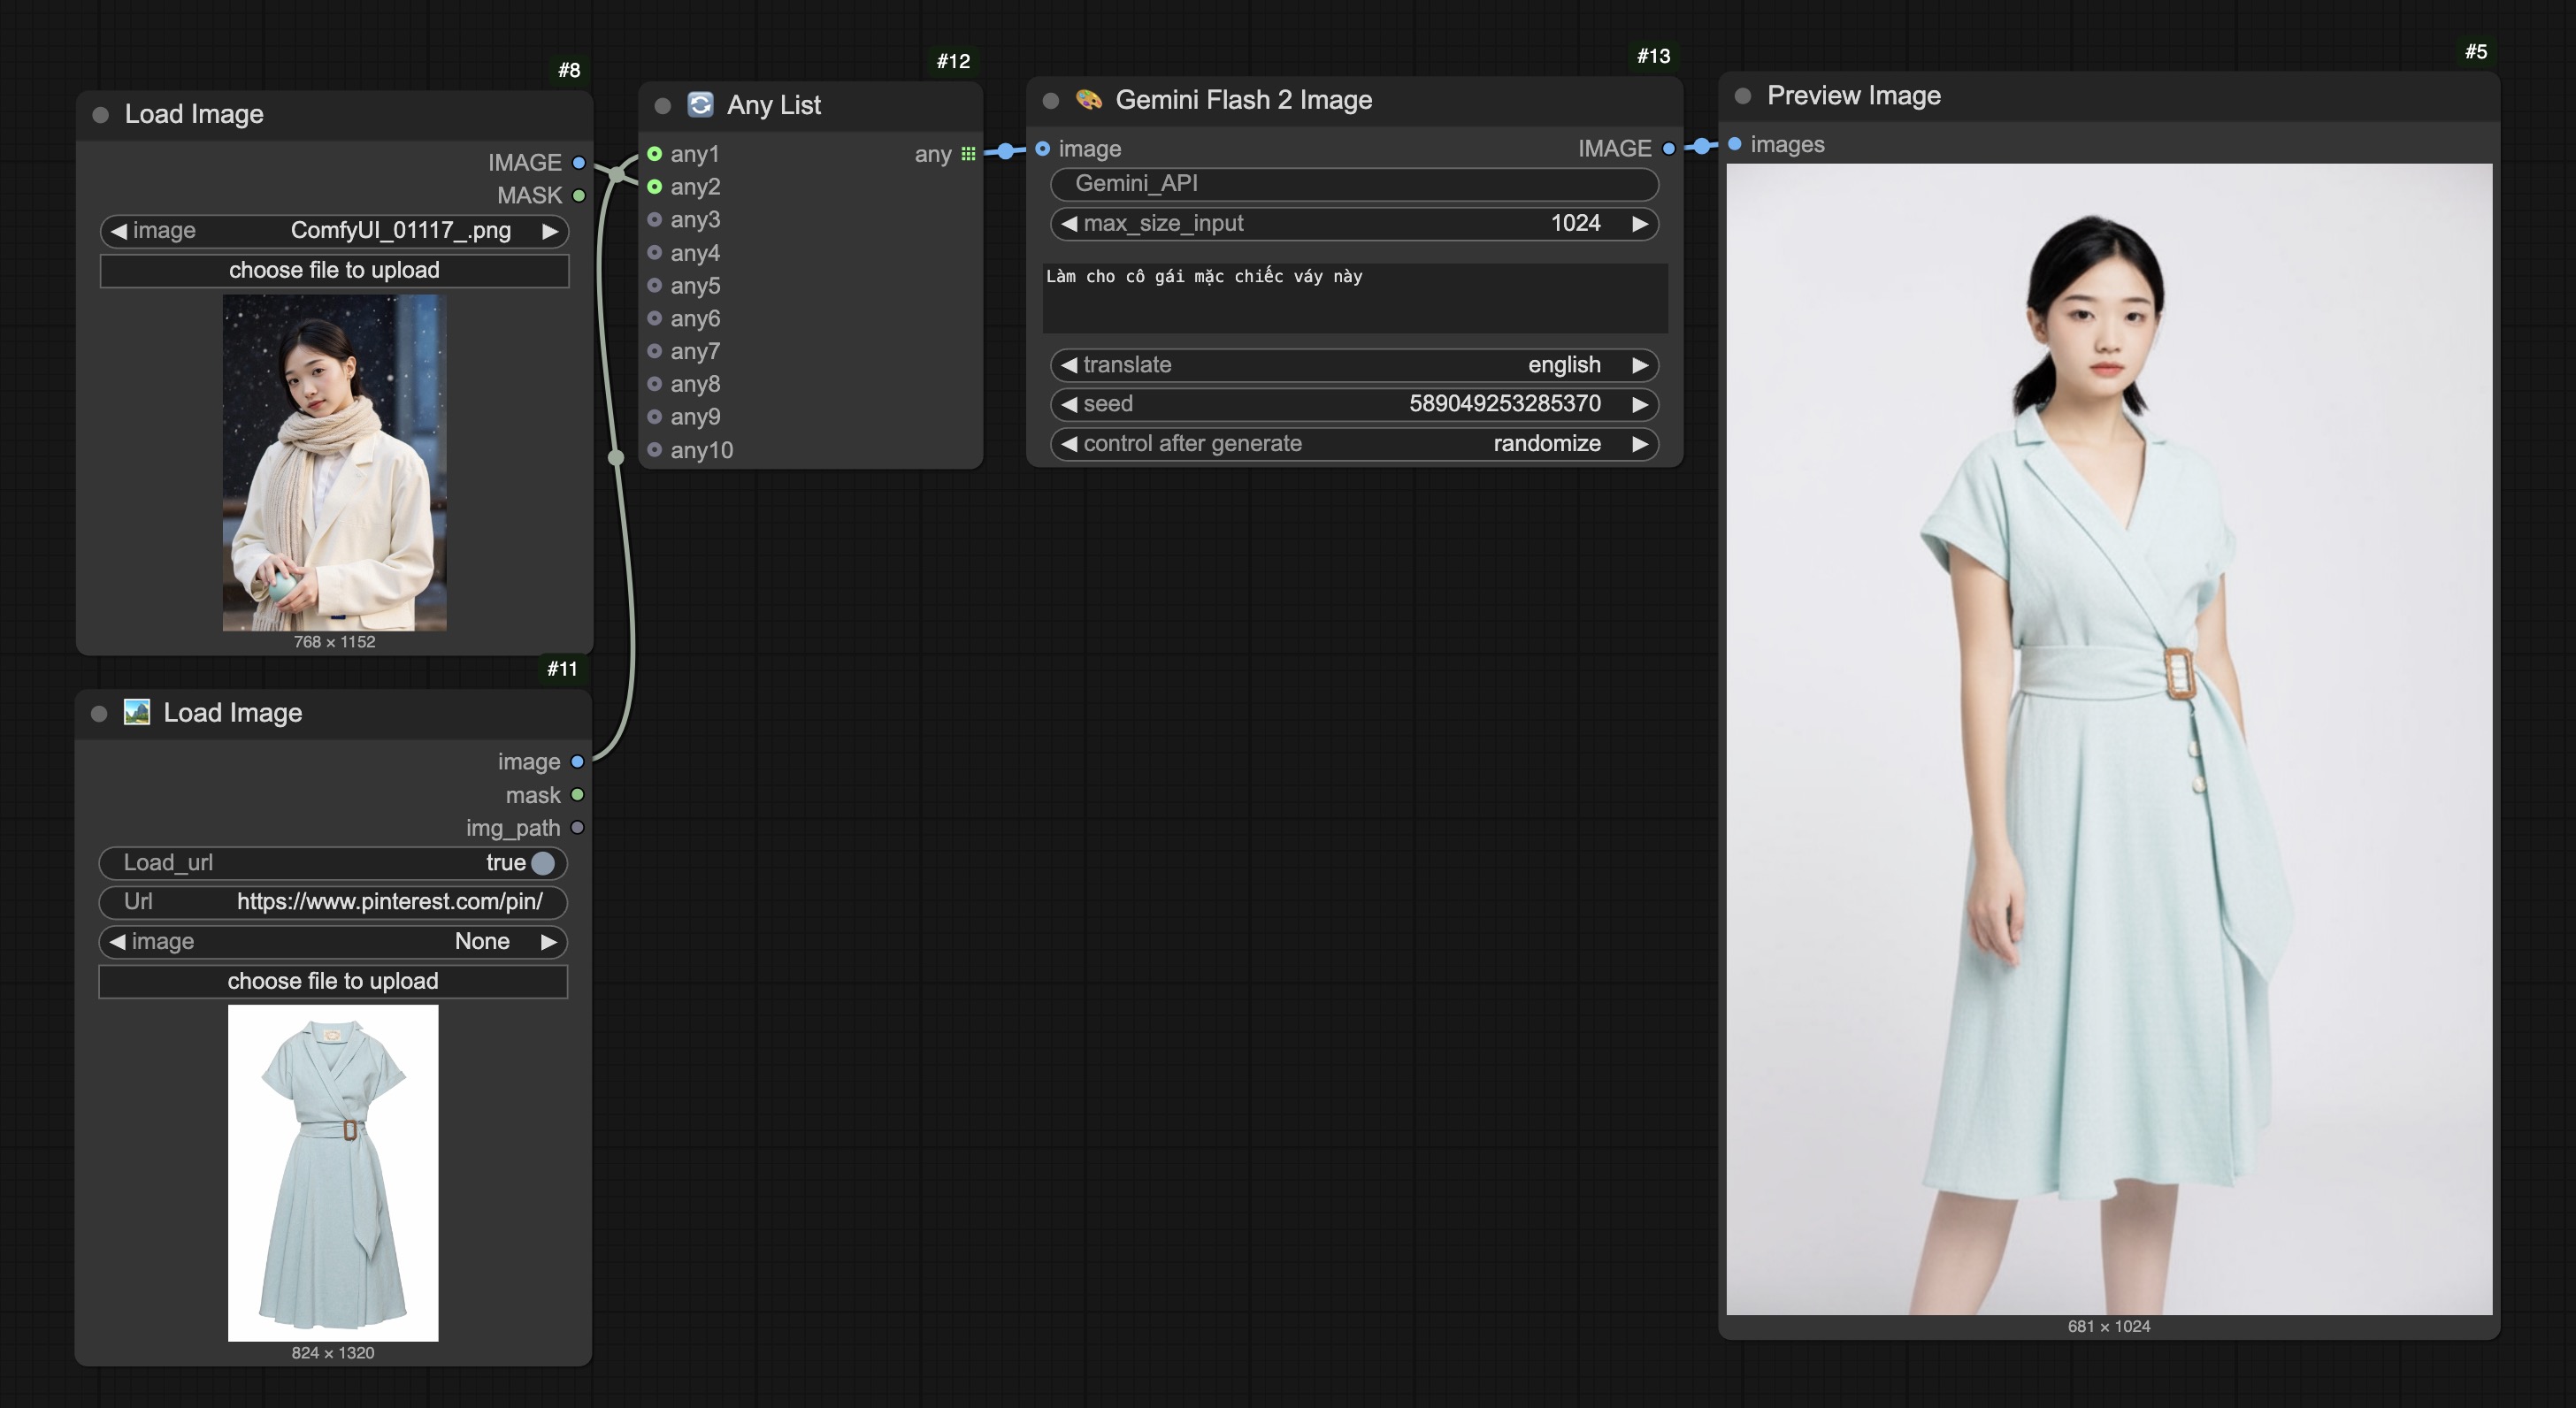
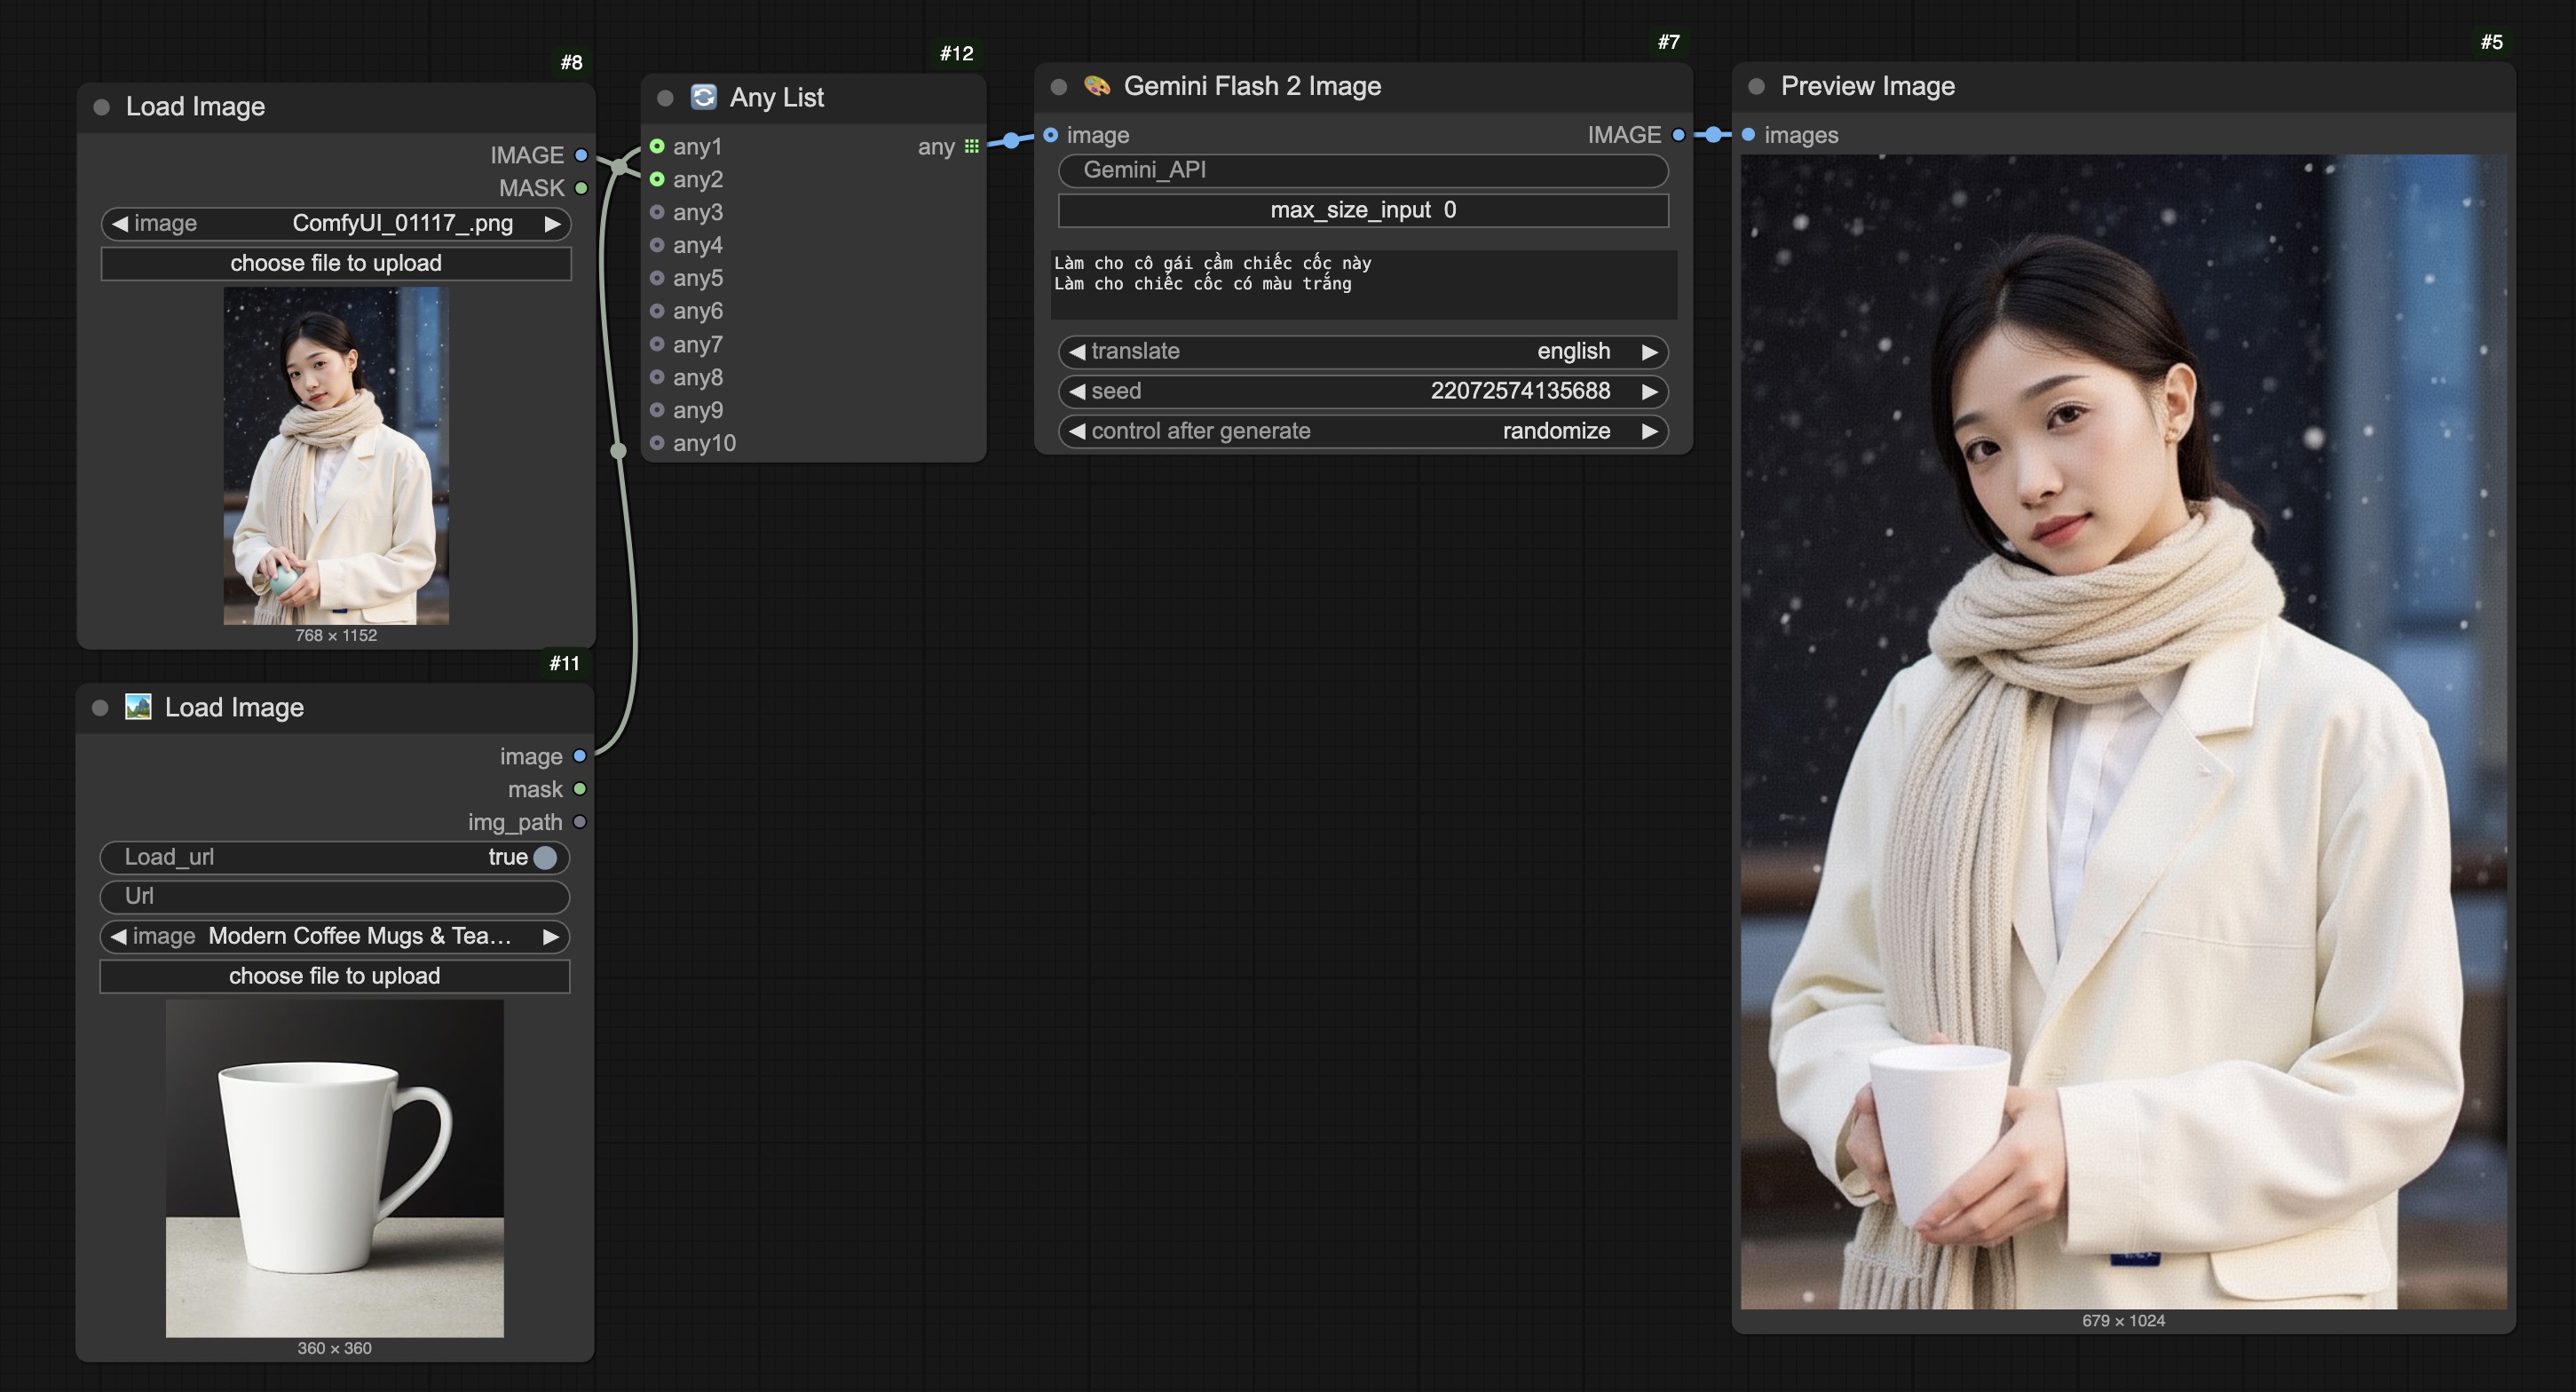
🎨 Gemini Flash 2 Image | 🎨 Google Imagen
- Support translate and Dynamic prompt
- Gemini Flash 2 Image accepts an optional reference image and resizes it to the desired maximum size
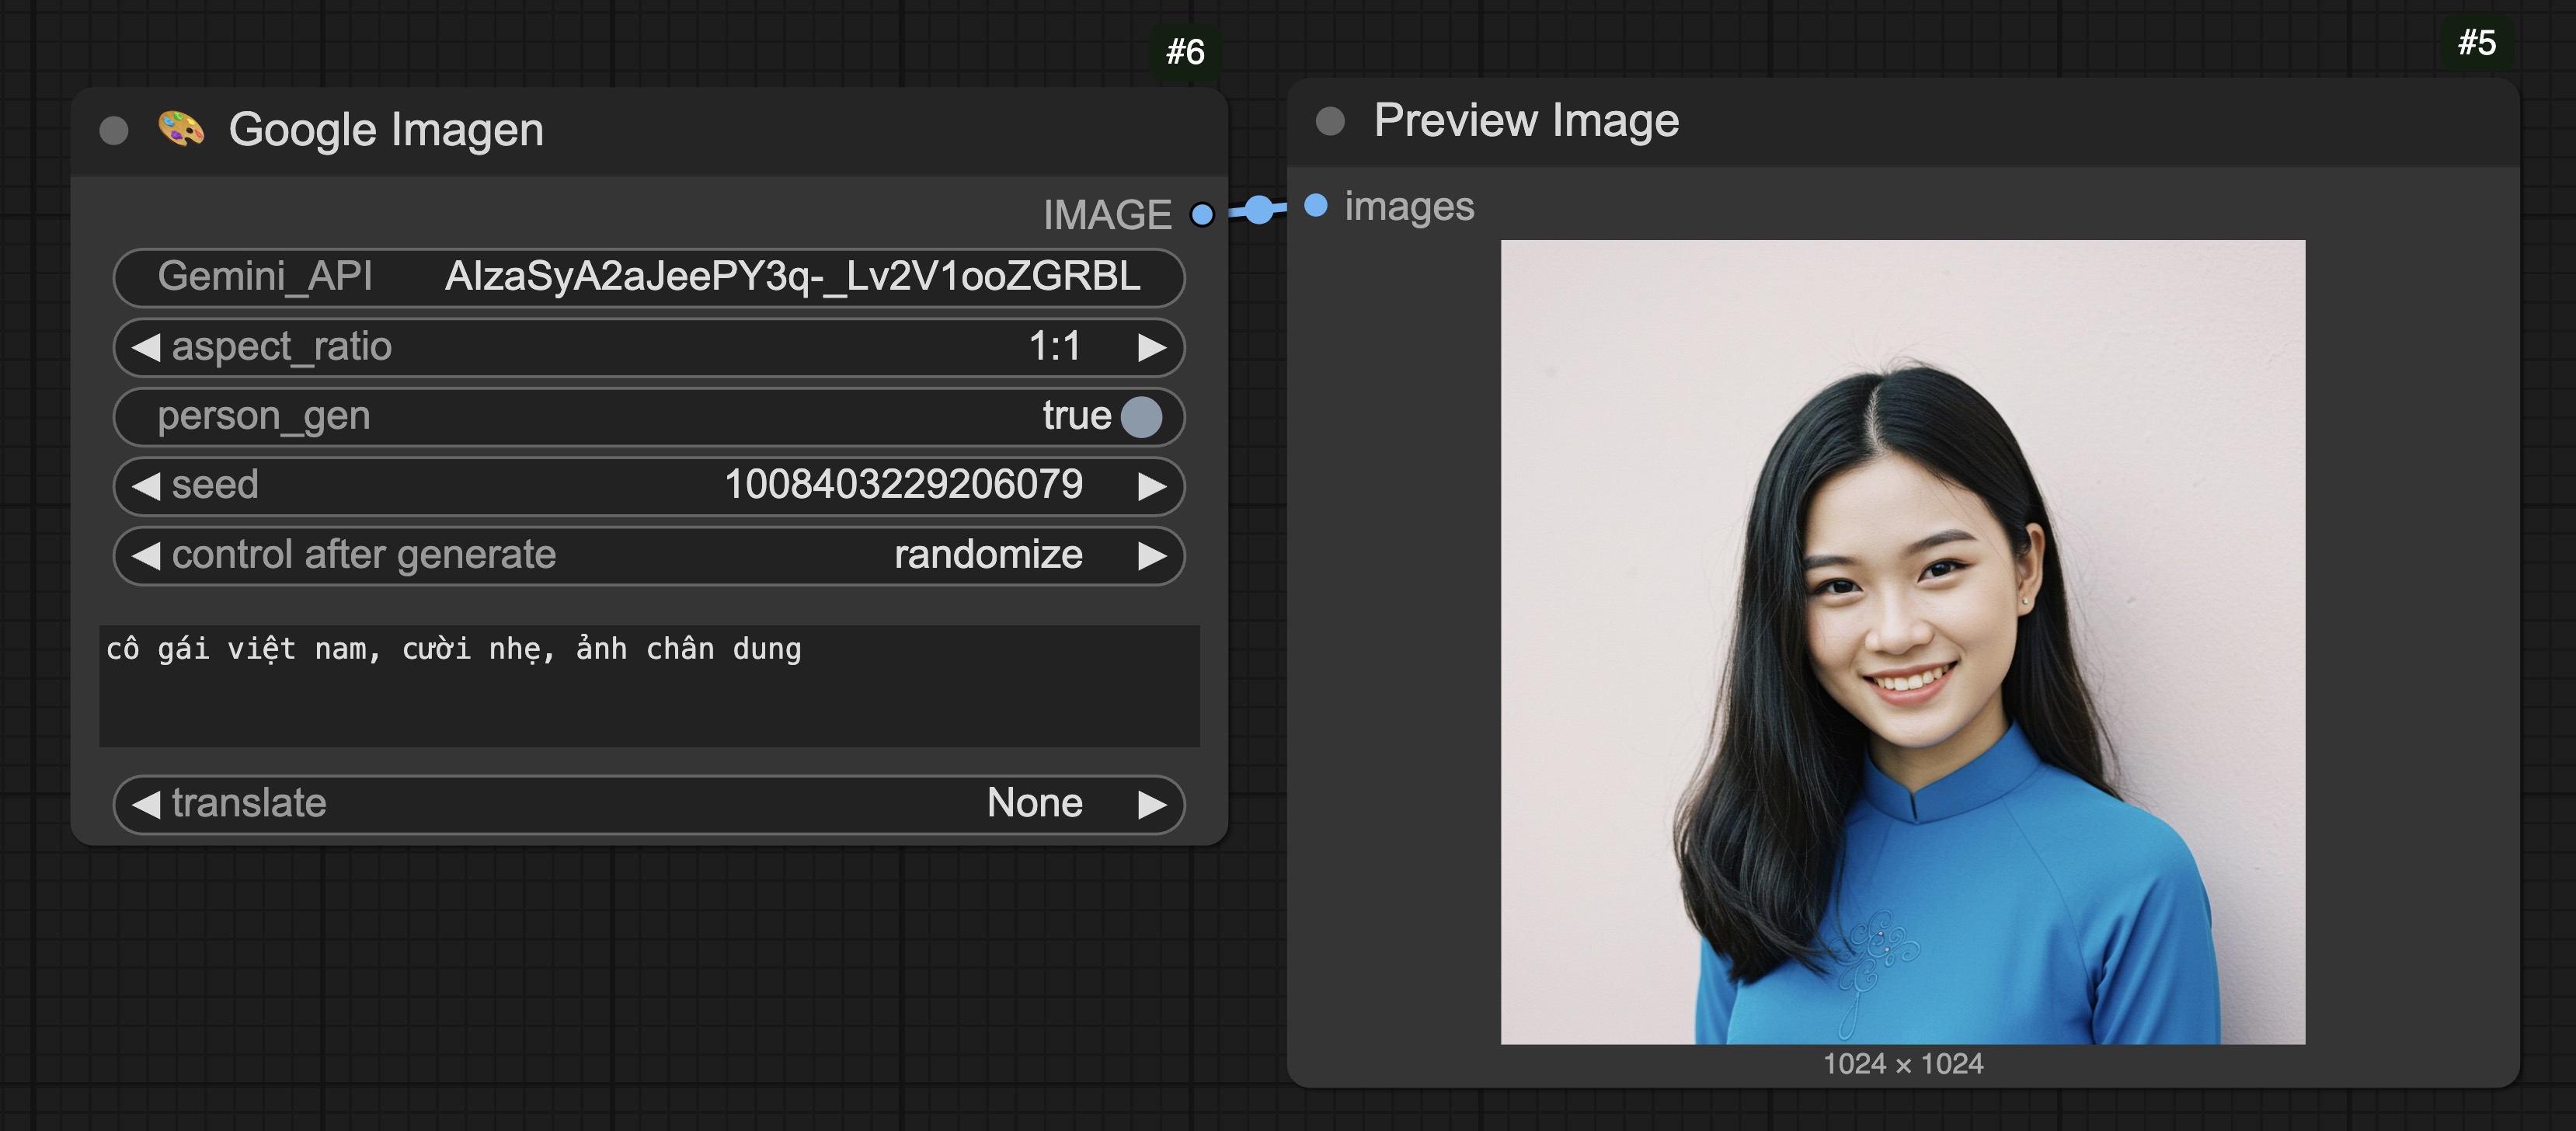
🎨 Gemini 3 Pro Image
- Uses stable
gemini-3-pro-imageto return both an image and accompanying text - Accepts up to 14 reference images; supports aspect ratio and resolution presets
- Translate + Dynamic prompt support, pulls API from
API_key.jsonif not provided
Info check
A set of nodes that support reading image and model metadata, editing model information, and generating illustrative cover images.
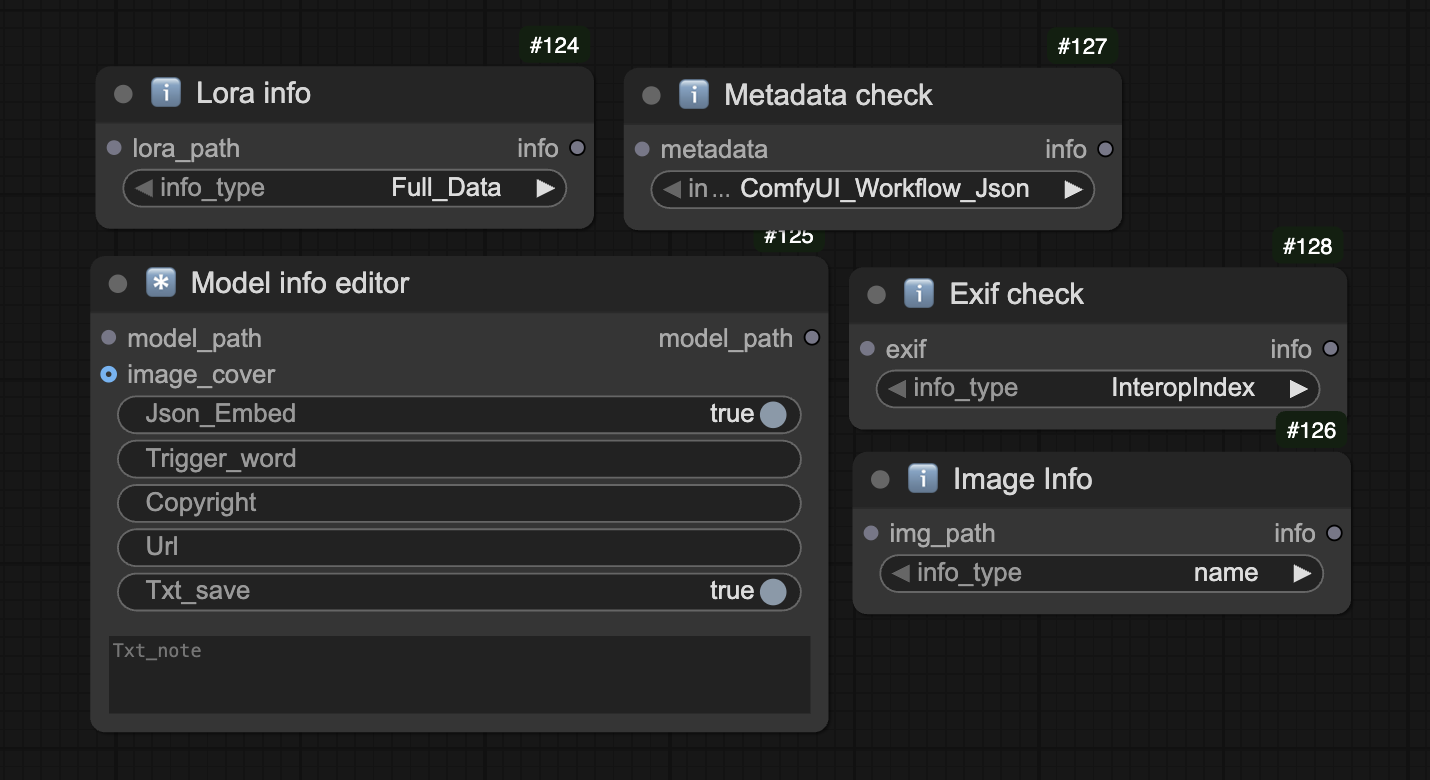
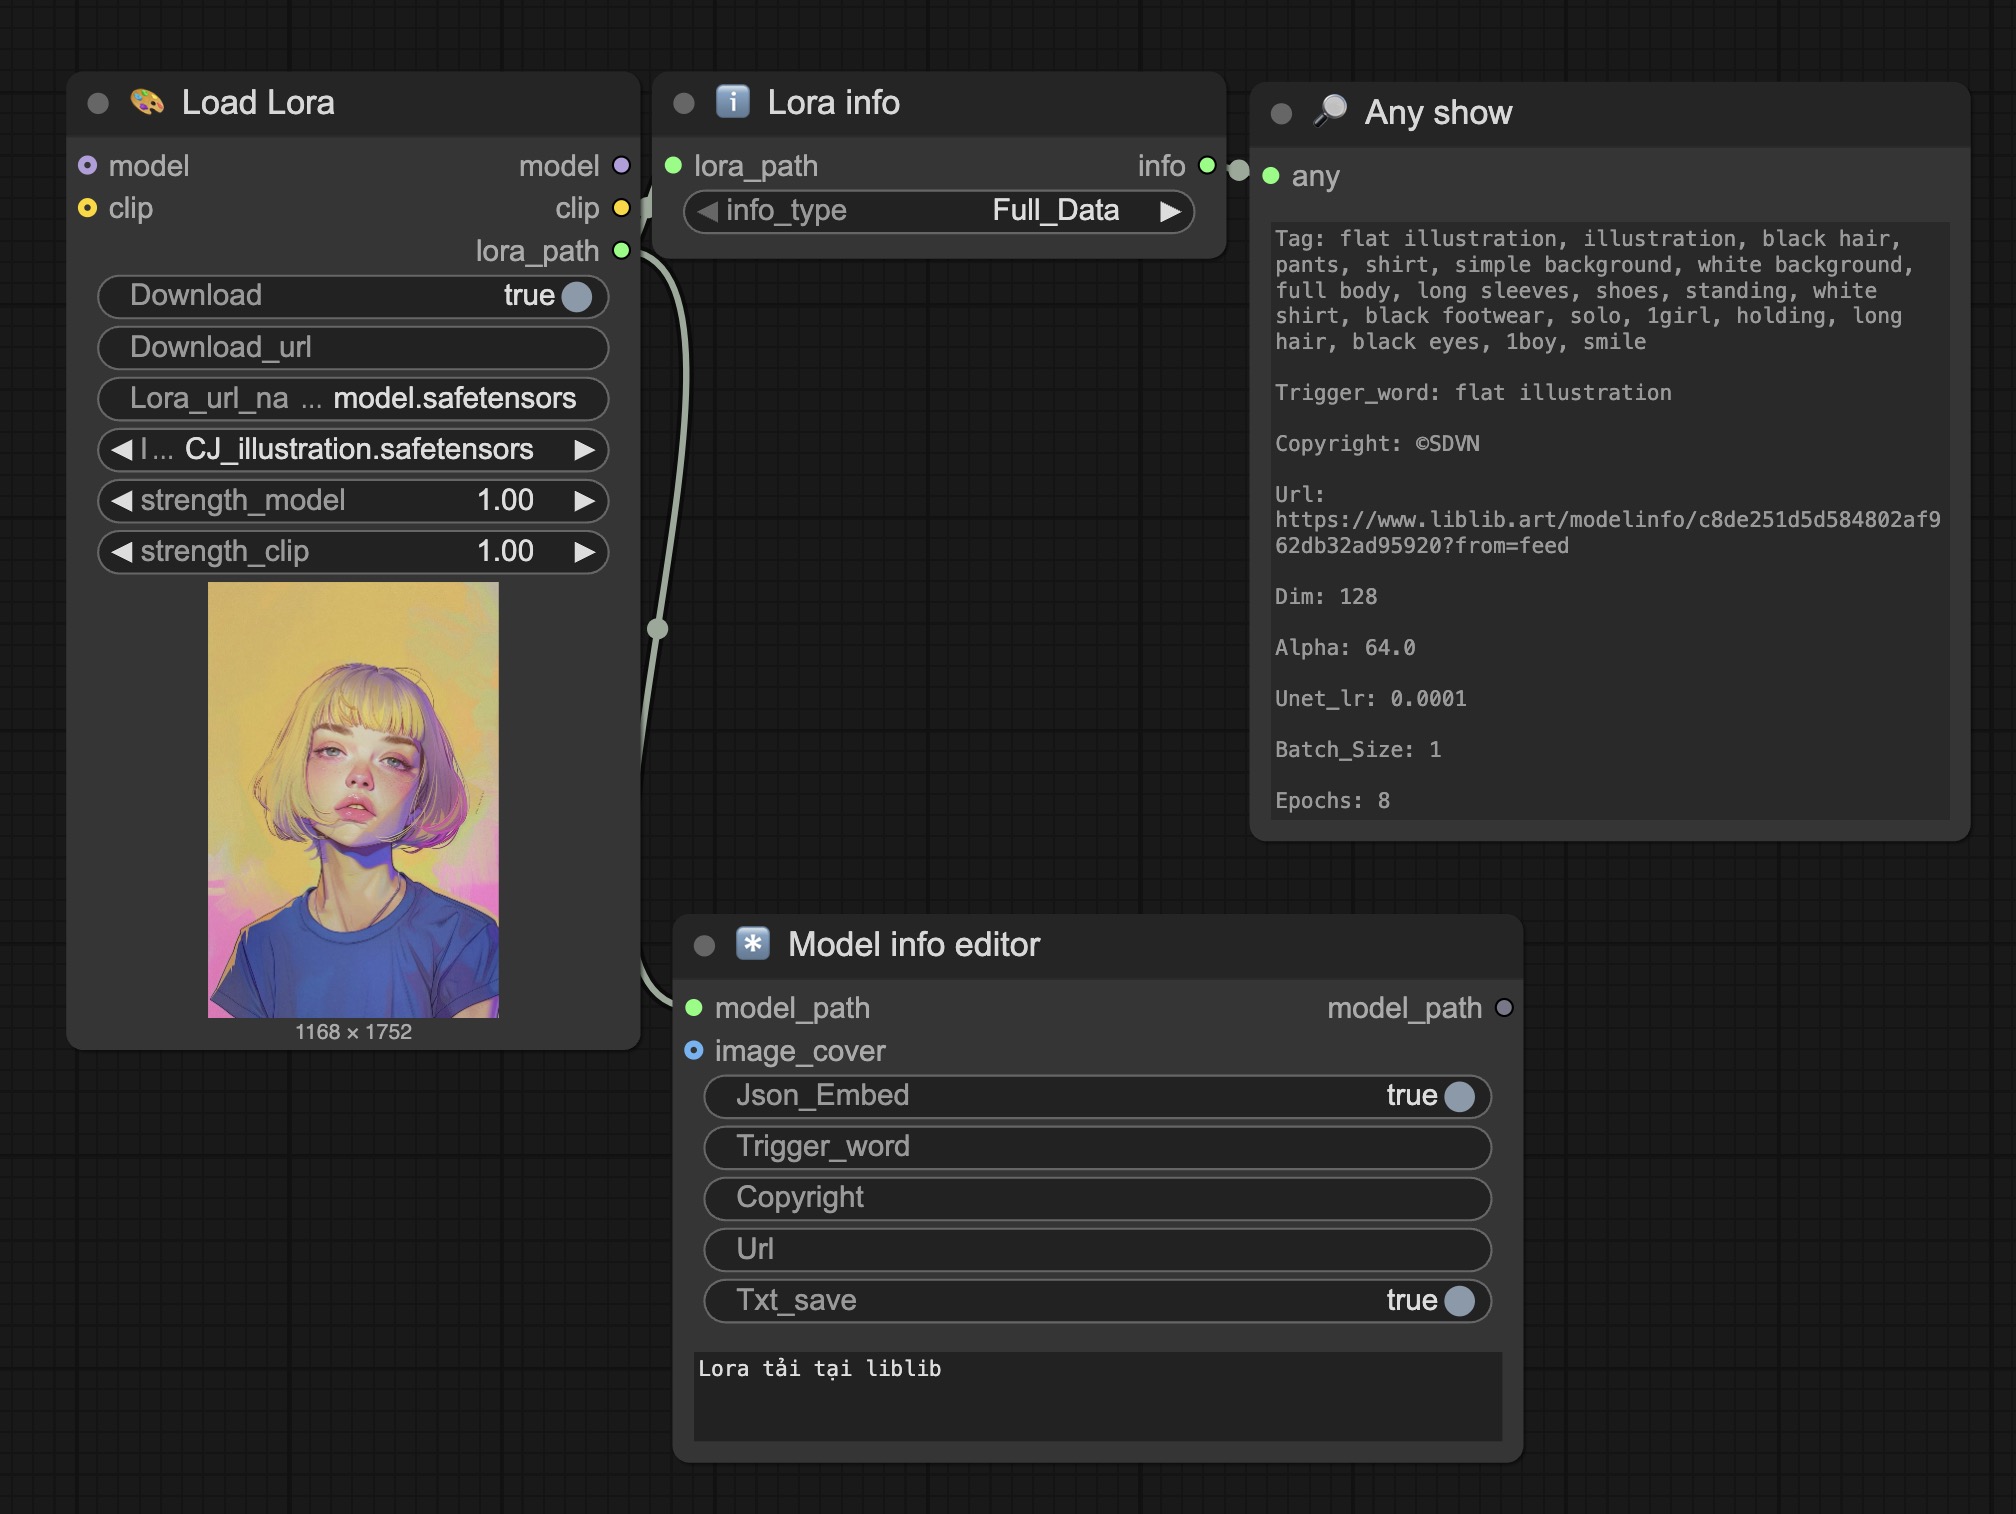
ℹ️ Lora info | Model info editor
Read and display information of LoRA and checkpoint models, as well as edit metadata within these models.
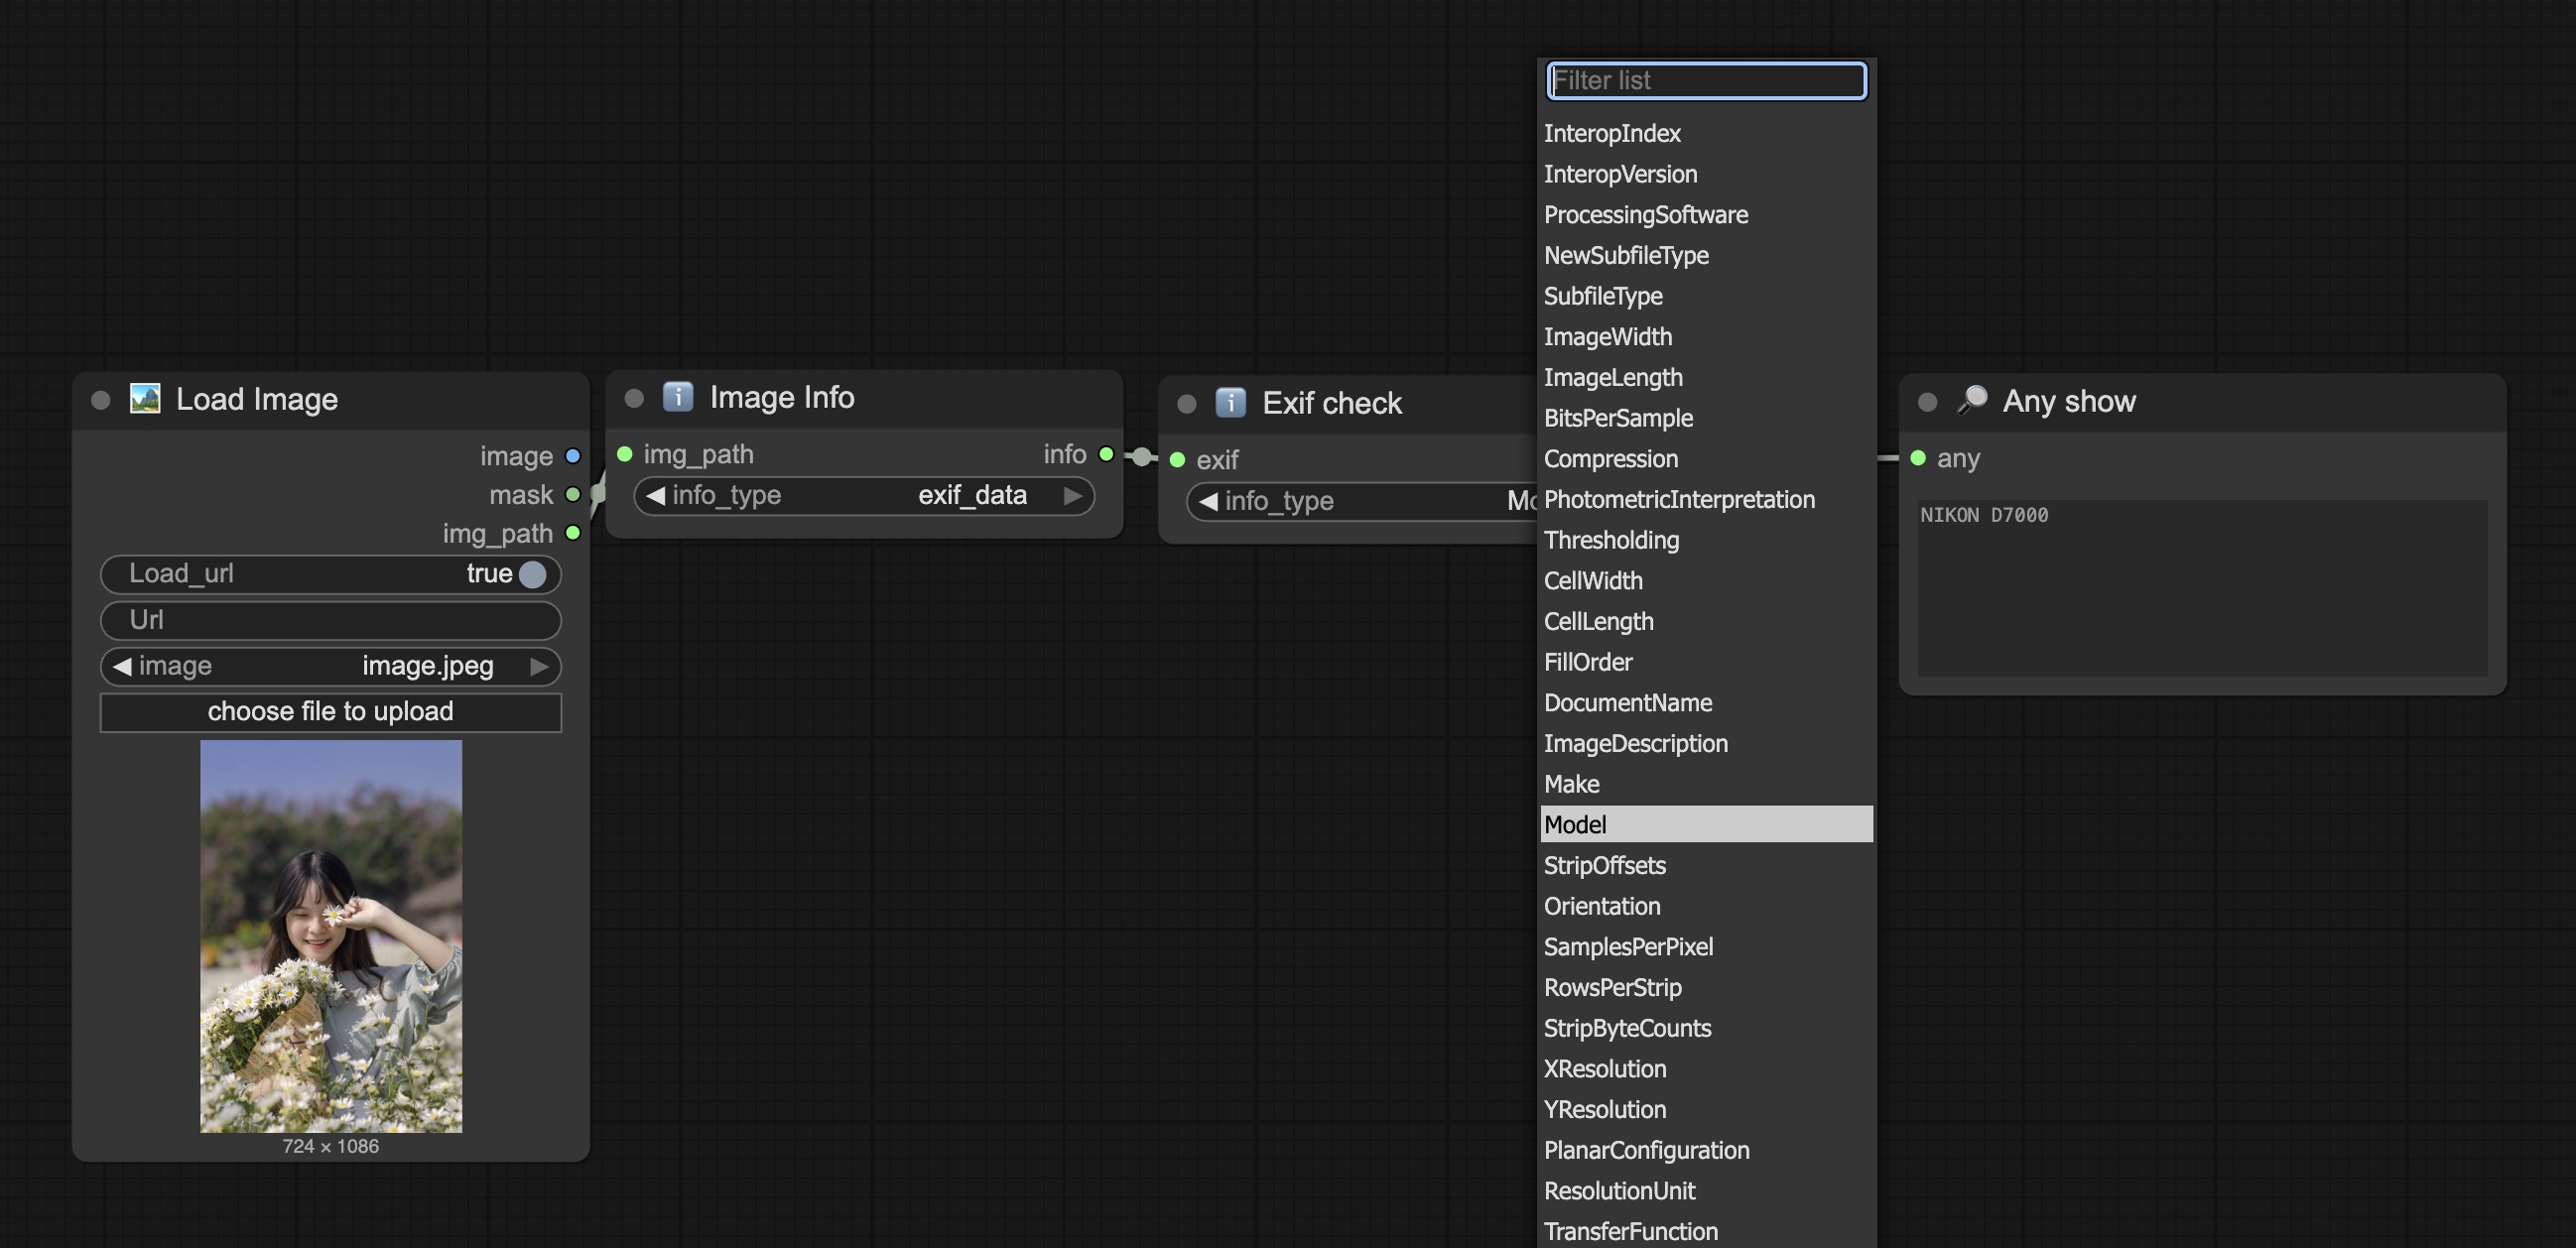
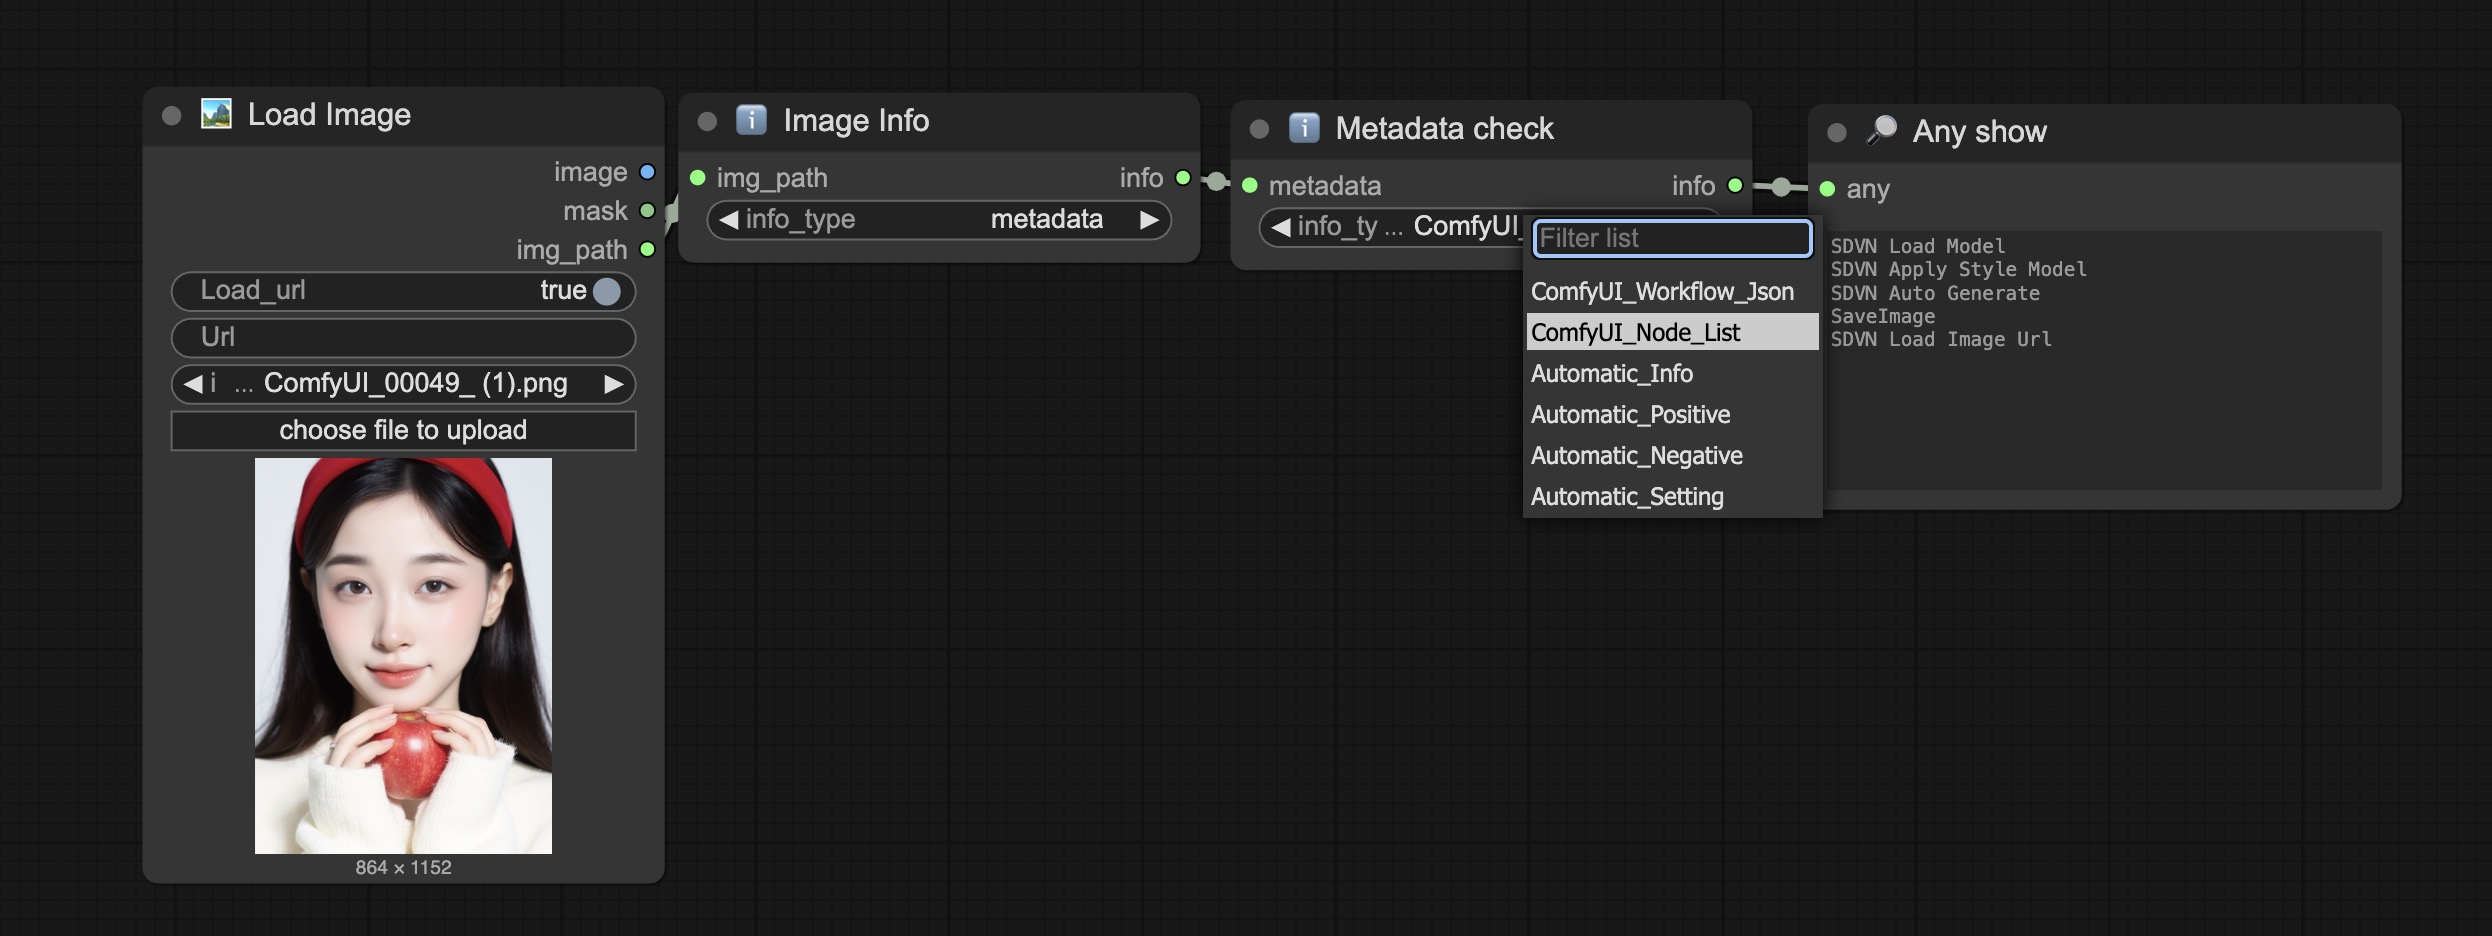
ℹ️ Image Info| ℹ️ Exif check | ℹ️ Metadata check
Nodes that support reading any embedded metadata within images.
Preset
Nodes that help simplify the process of building workflows. Nodes designed around the 💡 Auto Generate node to streamline workflows.
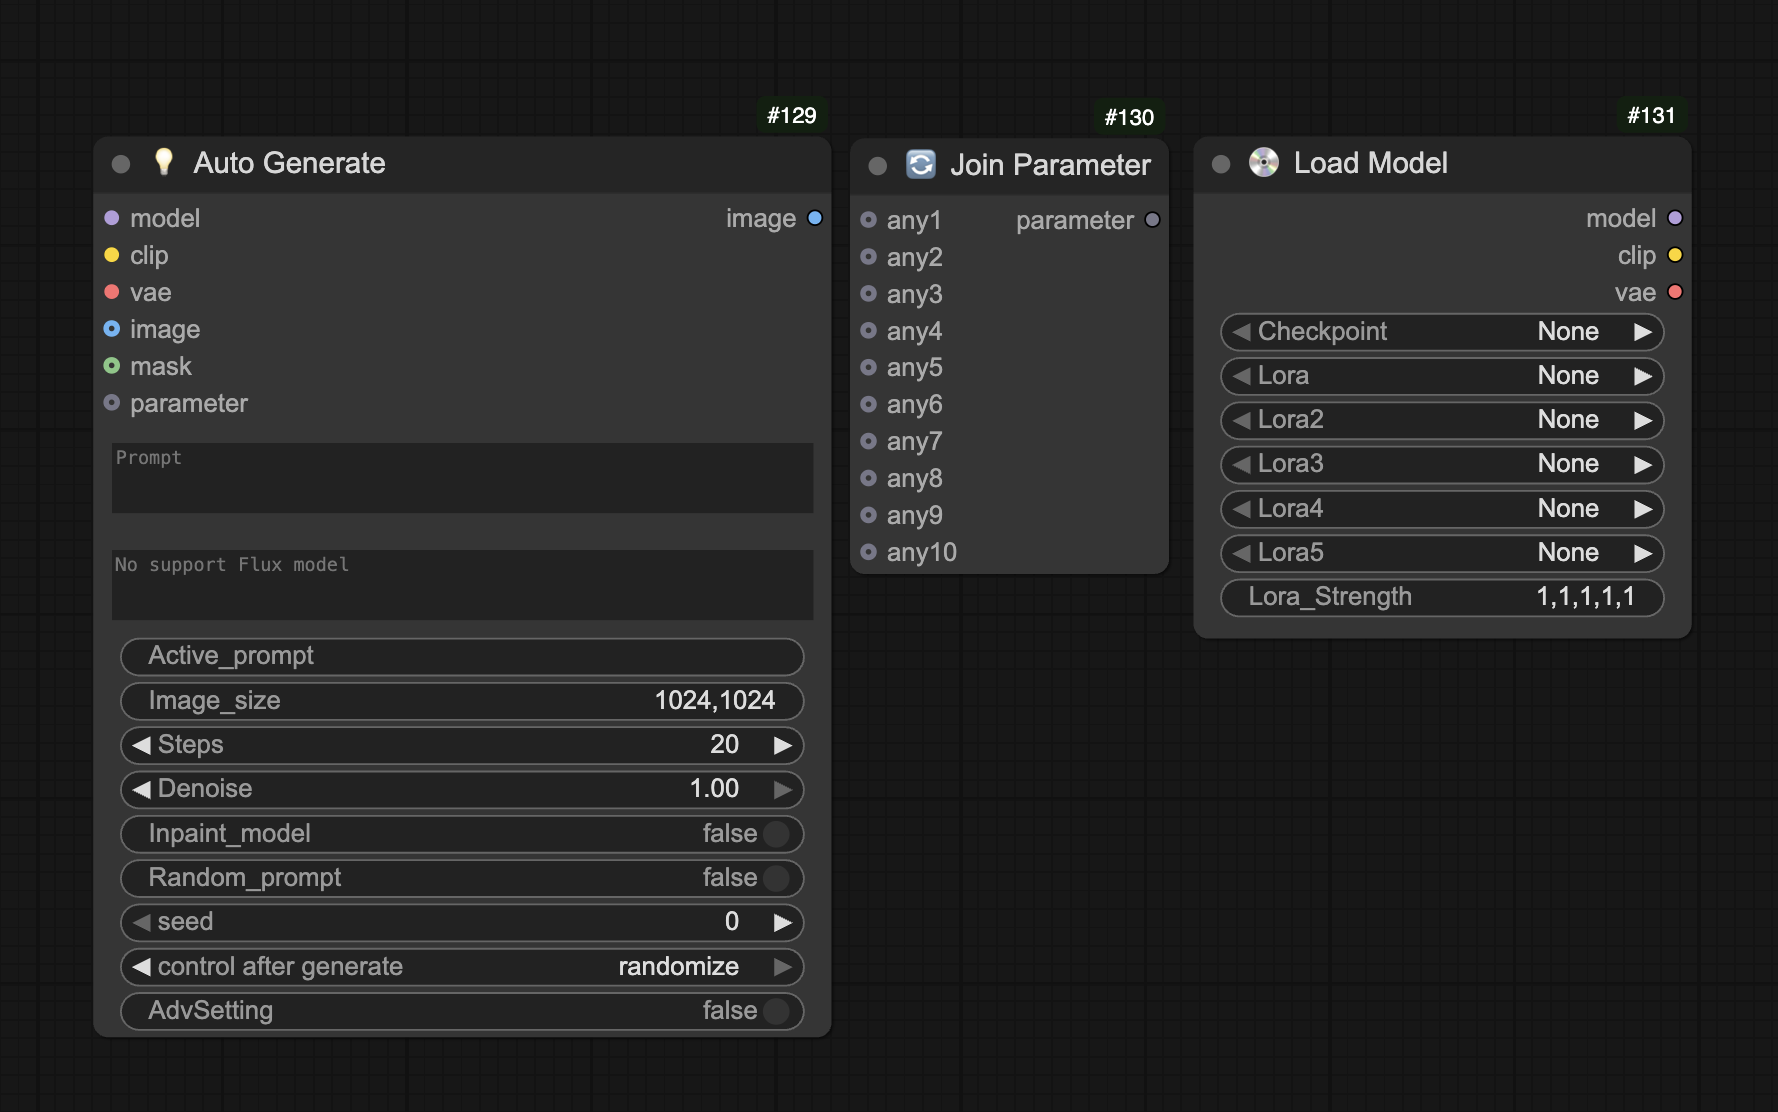
📋 Quick Menu
- Output selected checkpoints, LoRAs and strings in one node.
💿 Load Model
- Load a checkpoint together with up to five LoRAs from saved libraries.
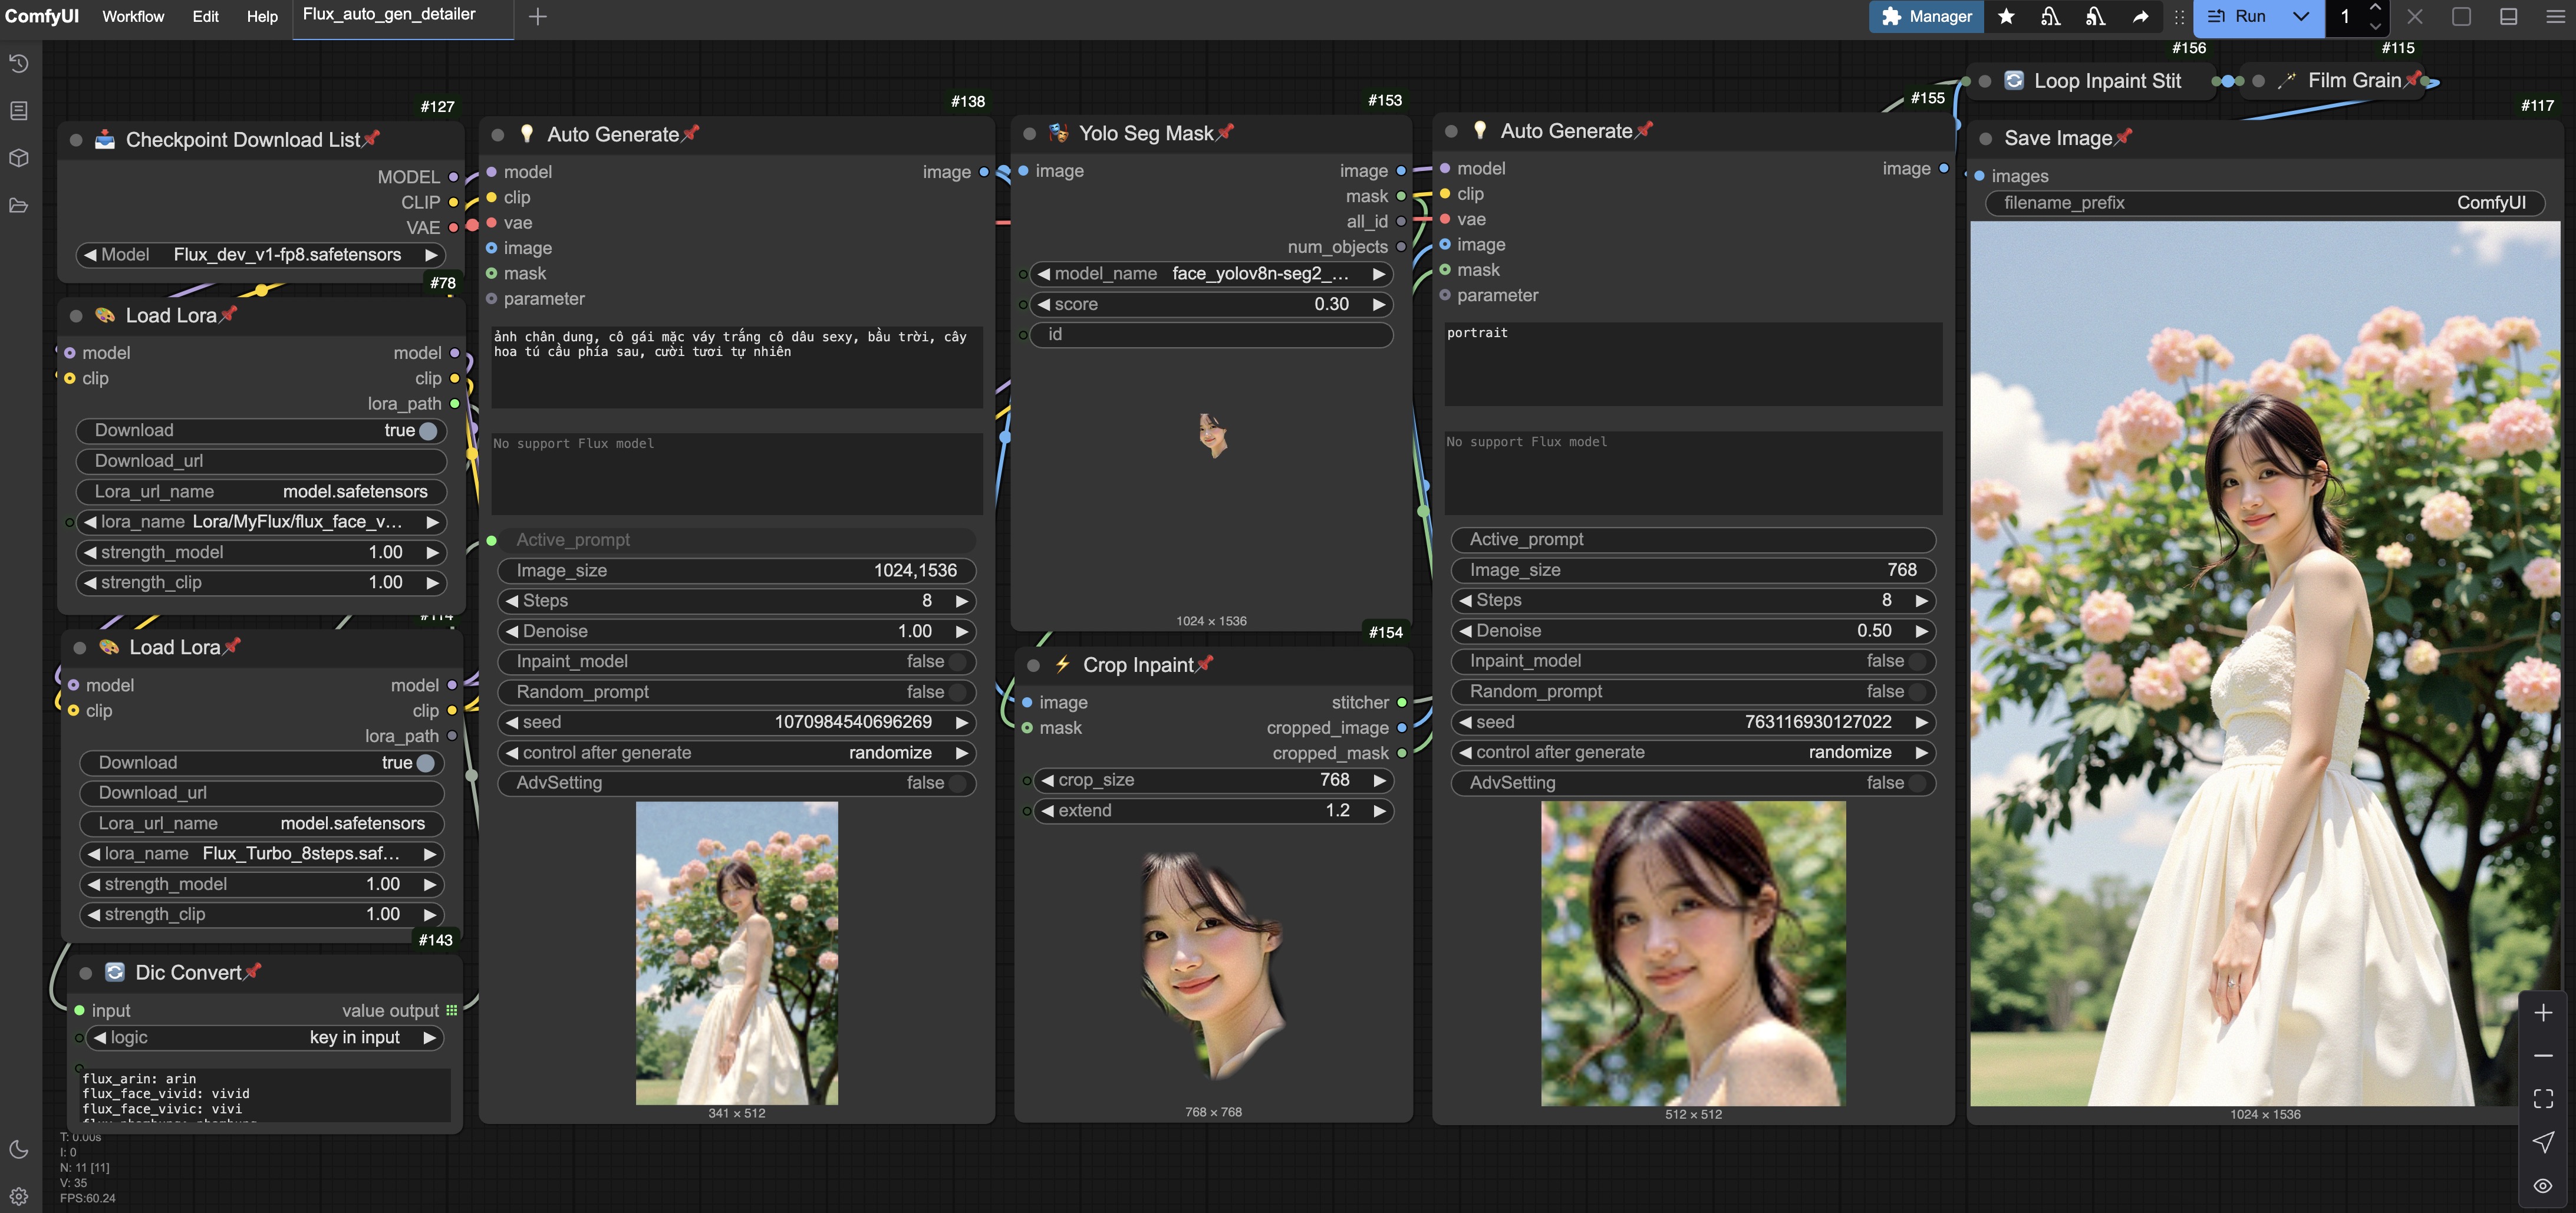
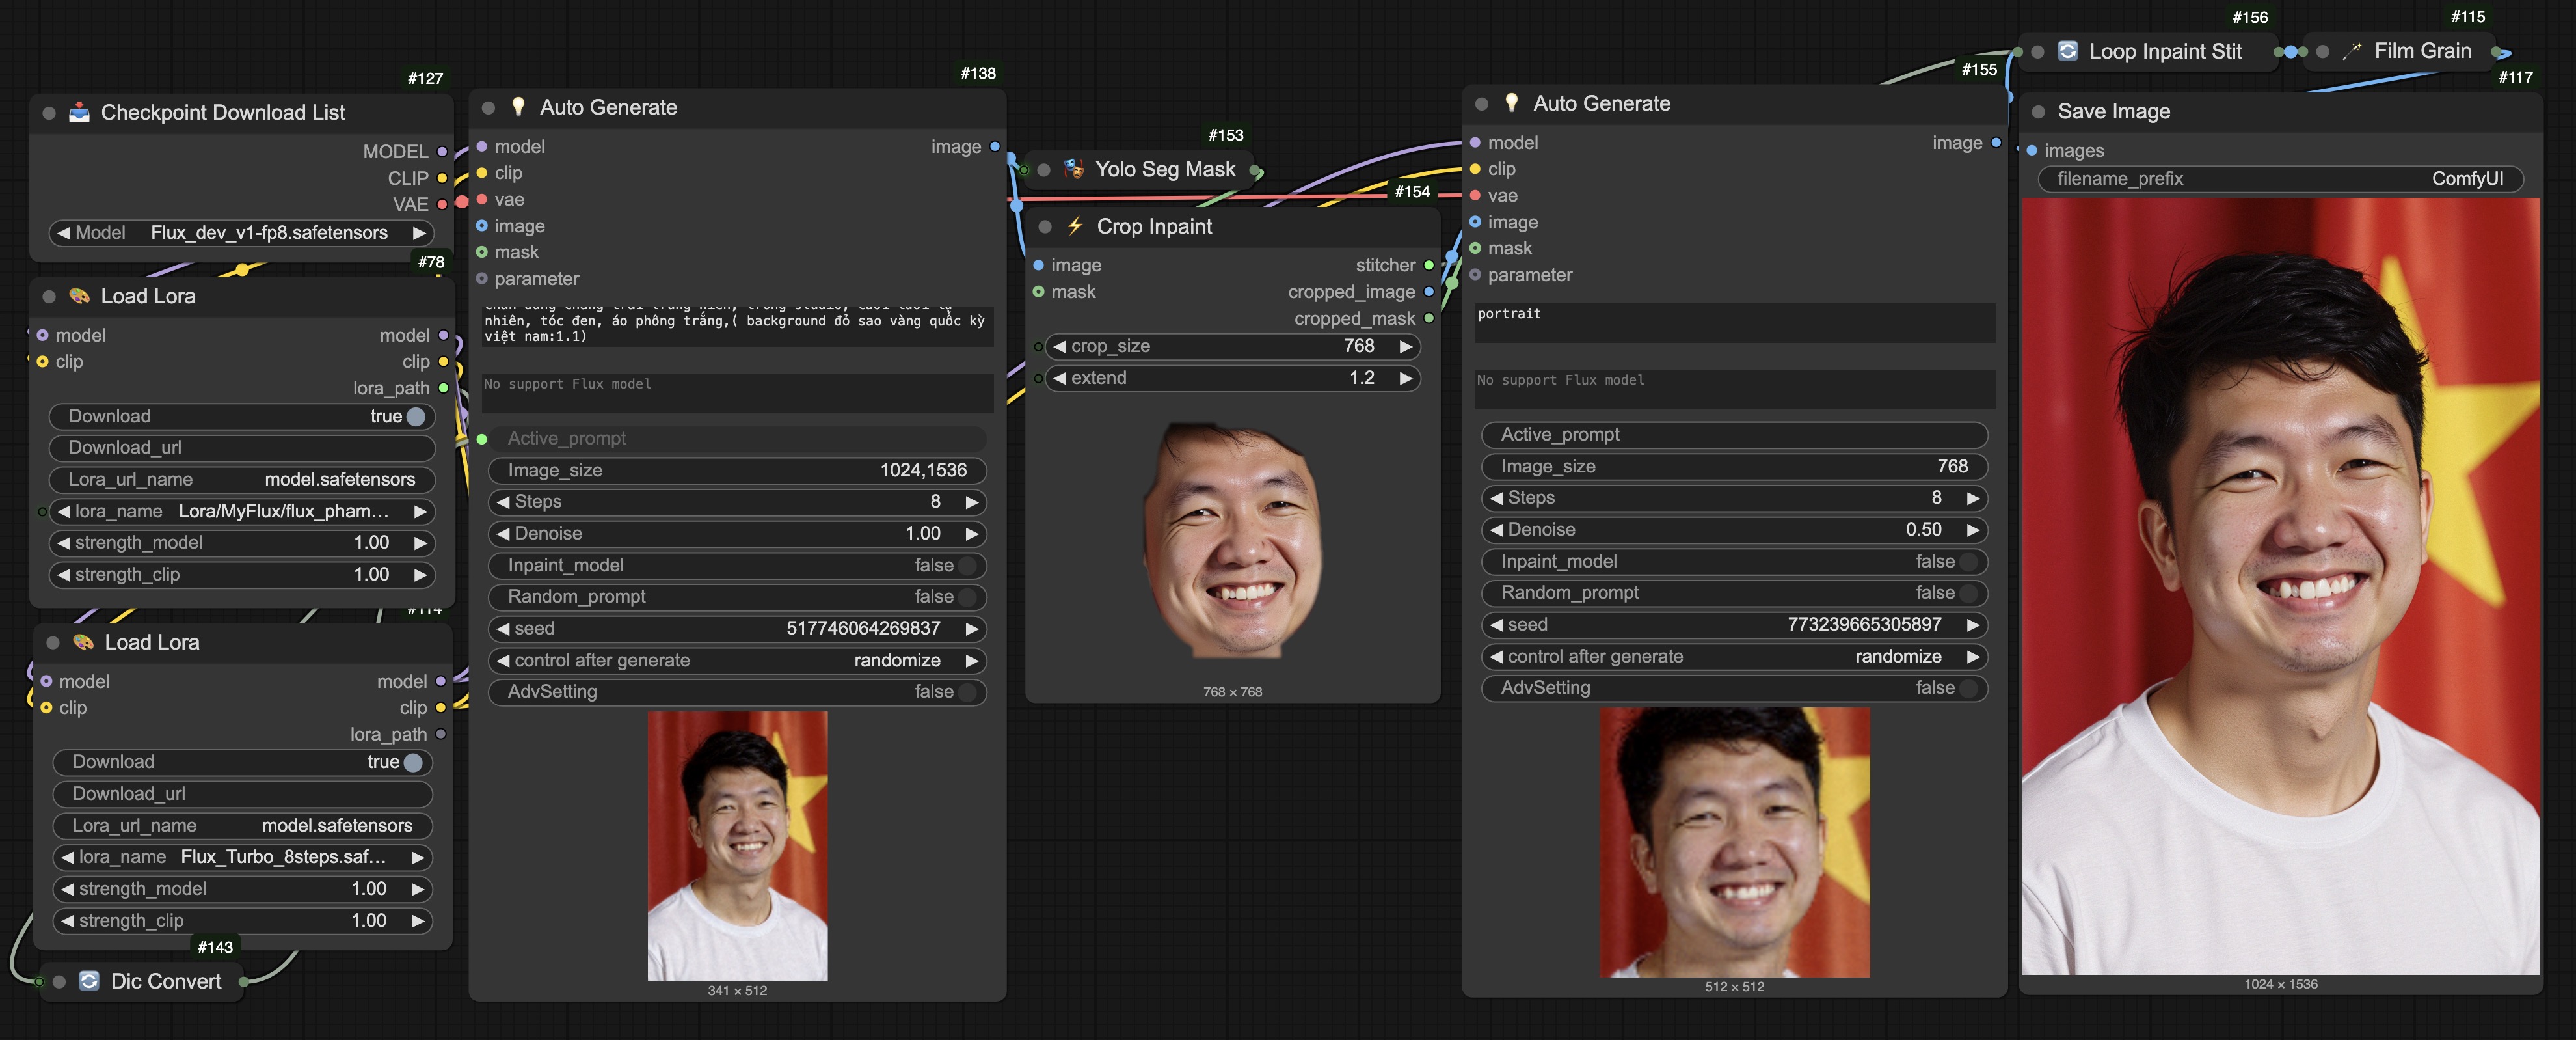
💡 Auto Generate
- The node will automatically generate images and calculate parameters to ensure the generation is as fast and accurate as possible.
- Automatically selects KSampler, Scheduler, and CFG based on the input model (SD15, SDXL, Flux). For SDXL, if steps = 8, parameters will be adjusted according to SDXL Lightning. Users can manually choose KSampler, Scheduler, and CFG via the AdvSetting option.
- Automatically splits image segments and creates an upscale–hires fix workflow based on the model and image generation size. Users can manually select the upscale model via the AdvSetting option.
- Automatically detects the language and translates the Prompt / Negative Prompt into English.
- The prompt and negative prompt sections support dynamic prompts. (When Random_prompt = True and used with a list, the returned results will vary each time).
- Automatically switches to an img2img or inpaint process when an input image or mask is provided. If the input model is an inpaint/fill model, set inpaint_model = True to automatically apply optimal parameters. Image size will automatically adjust to maintain the aspect ratio of the input image.
- Add ControlNet and ApplyStyle settings via parameters using the
🎚️ Controlnet Applyand🌈 Apply Style Modelnodes. Multiple parameters can be added at once by using the🔄 Join Parameternode. - Steps will be automatically recalculated based on the denoise value, using the formula:
Step = Steps × Denoise.
Mask
Nodes that support both basic and advanced mask processing and inpainting.
🎭 Yolo Seg Mask
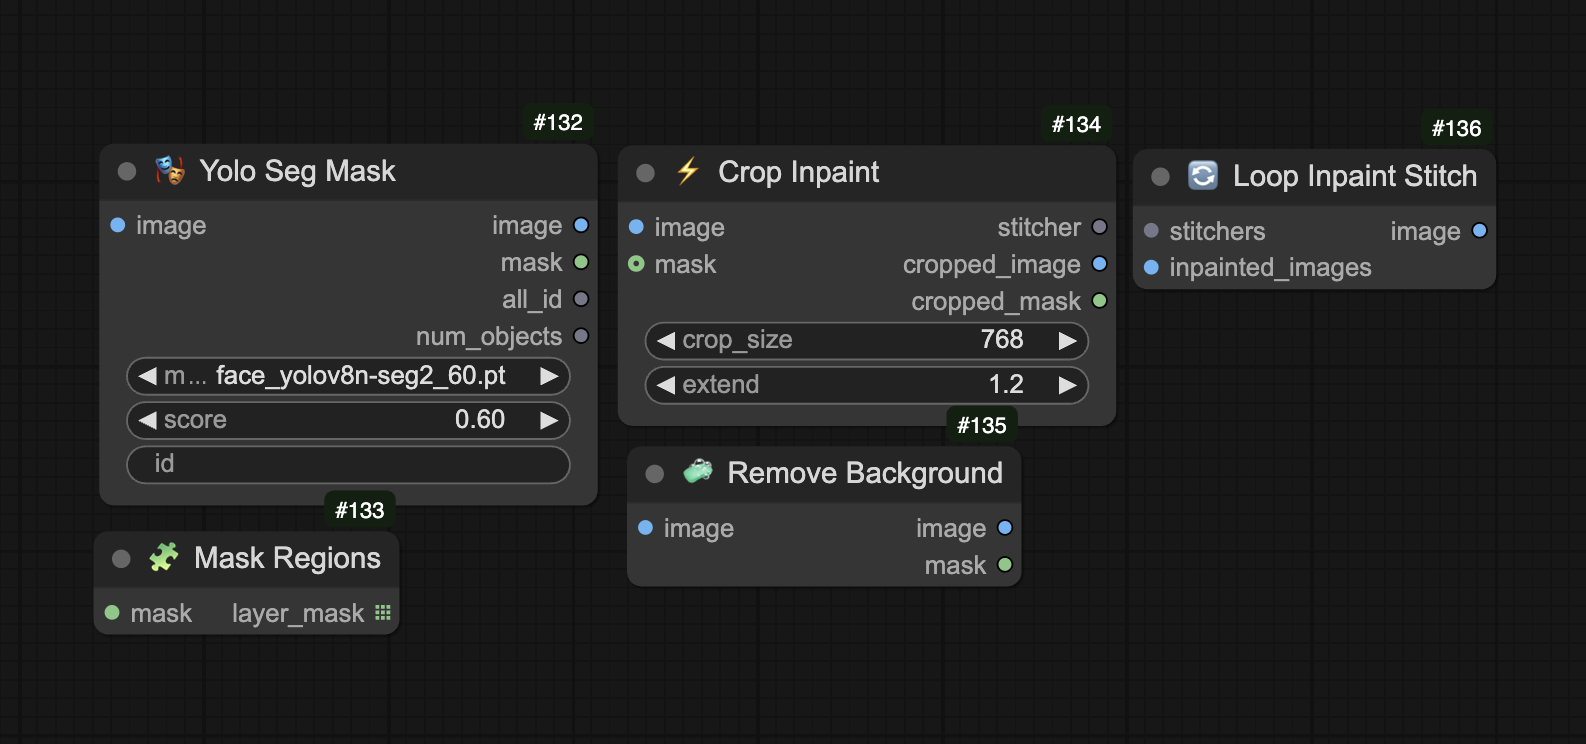
- A node that uses YOLO models to automatically detect masks accurately, quickly, and with minimal GPU usage.
- Supports YOLO26-seg
n/s/m/l/x, downloaded directly from Ultralytics/YOLO26 intomodels/yolo. Existing YOLOv8, YOLO11, and specialized face/hair/skin models remain available with their original download source. Update the existing SDVN requirements to installultralytics==8.4.183, then restart ComfyUI; no separate requirements file is needed. - Accepts RGB/RGBA and image batches, uses ComfyUI's selected device, and requests masks at the original image resolution. Overlapping masks are combined within
[0, 1]. Outputs one annotated image and union mask per input image;num_objectsis the total count across the batch. Detection/pose models still provide annotations and object counts, with an empty mask. - When no masks are found, the empty mask remains 64×64 (one per image). In a mixed batch, empty masks use the original image size so they can share a tensor with detected masks.
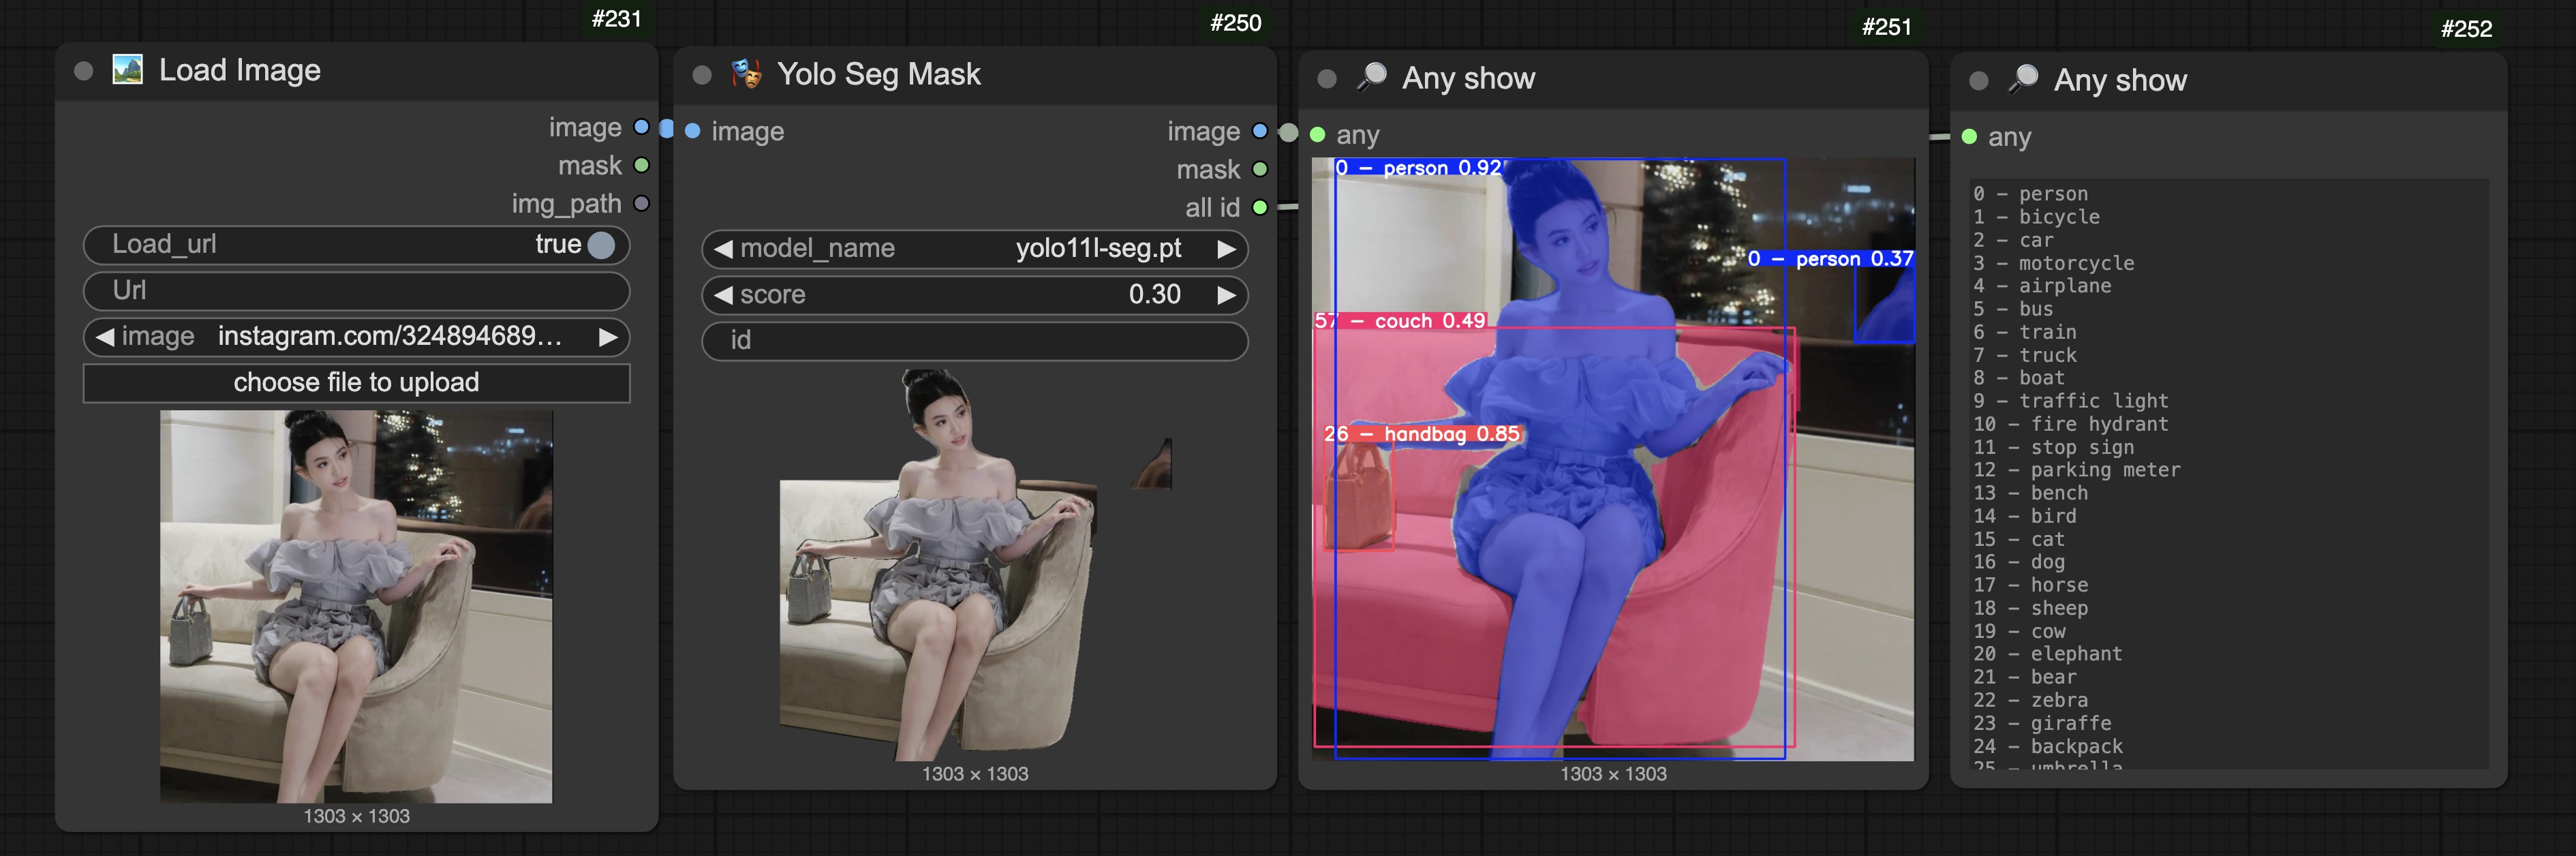
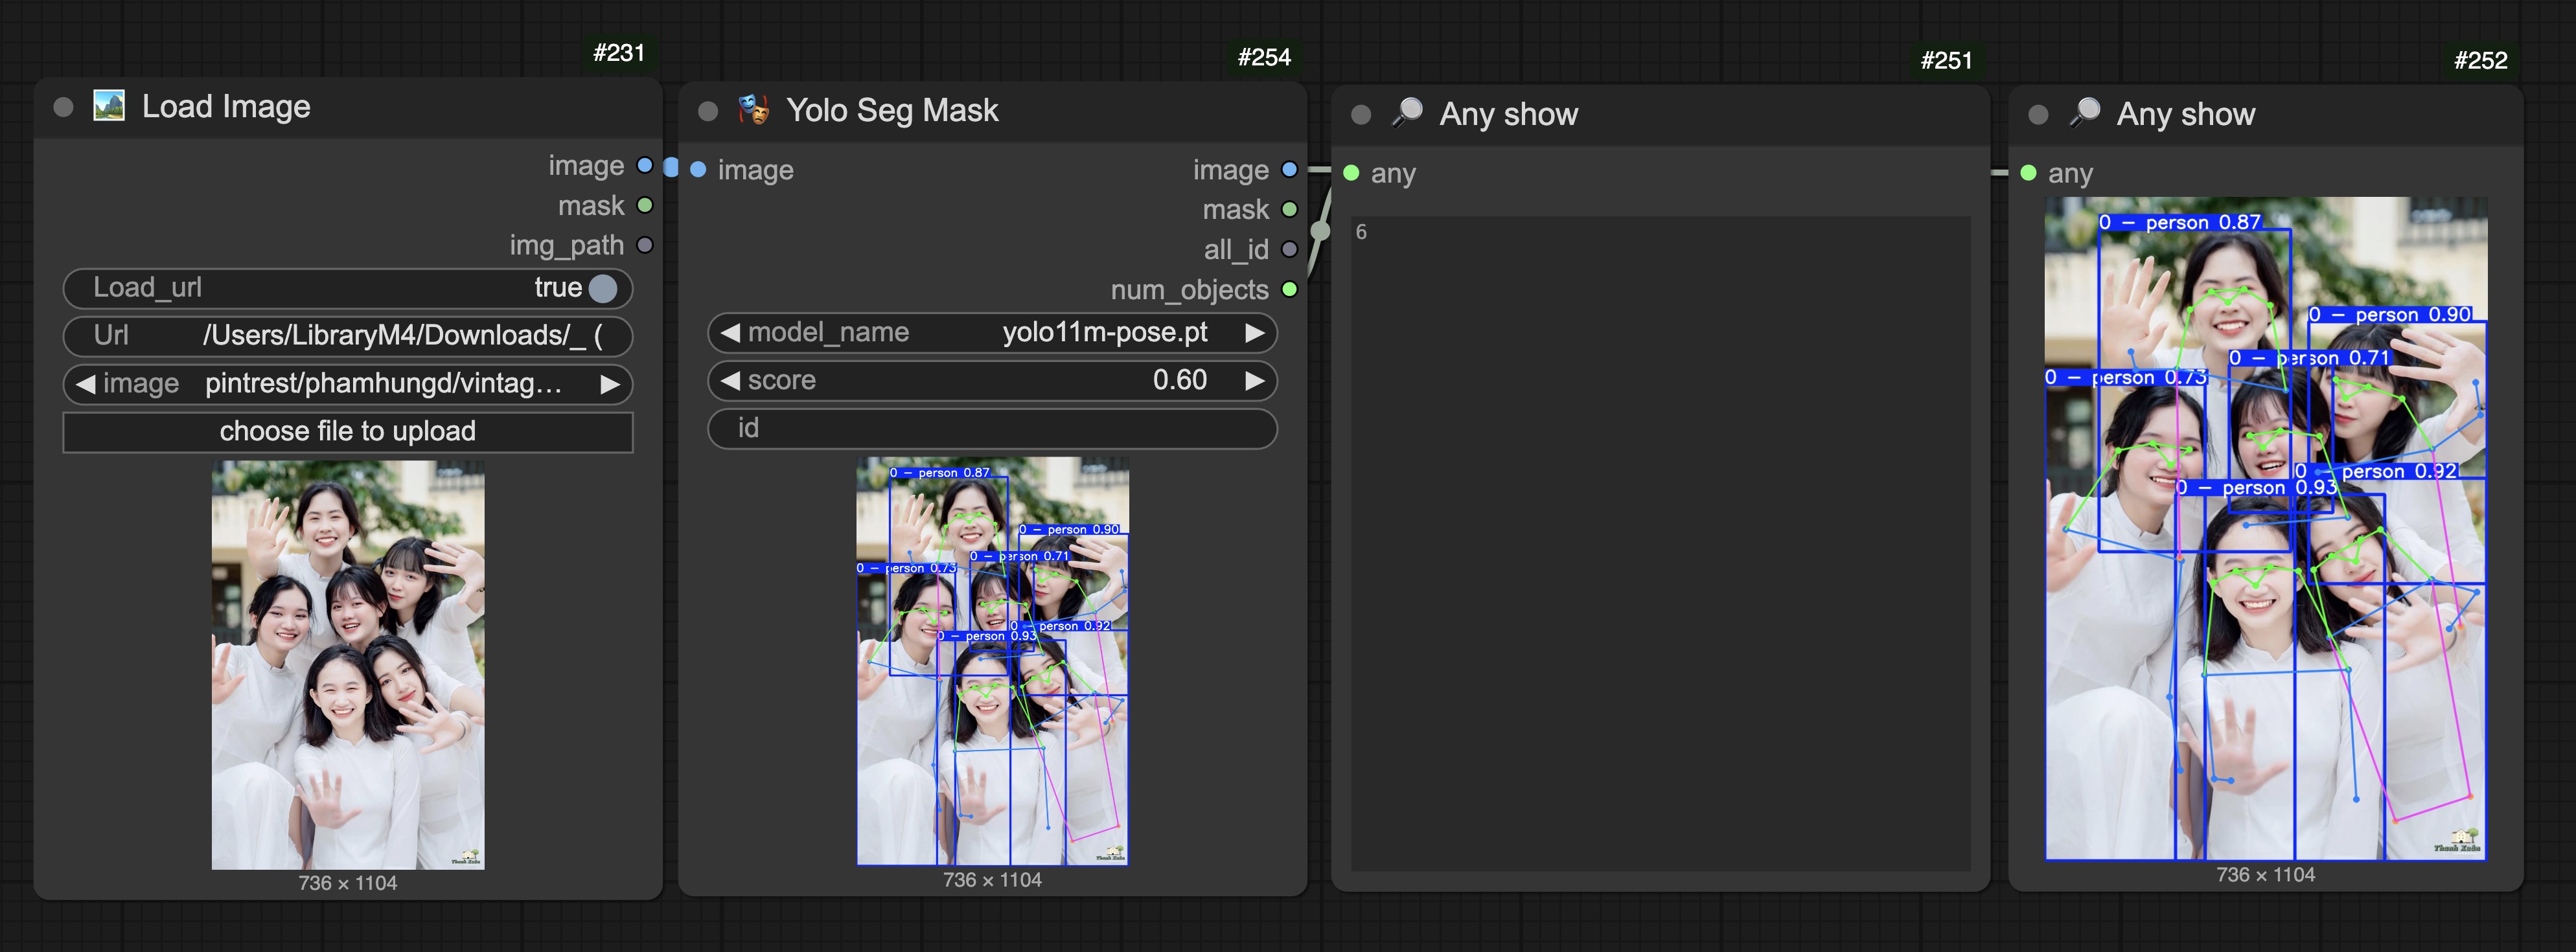
🧩 Mask Regions
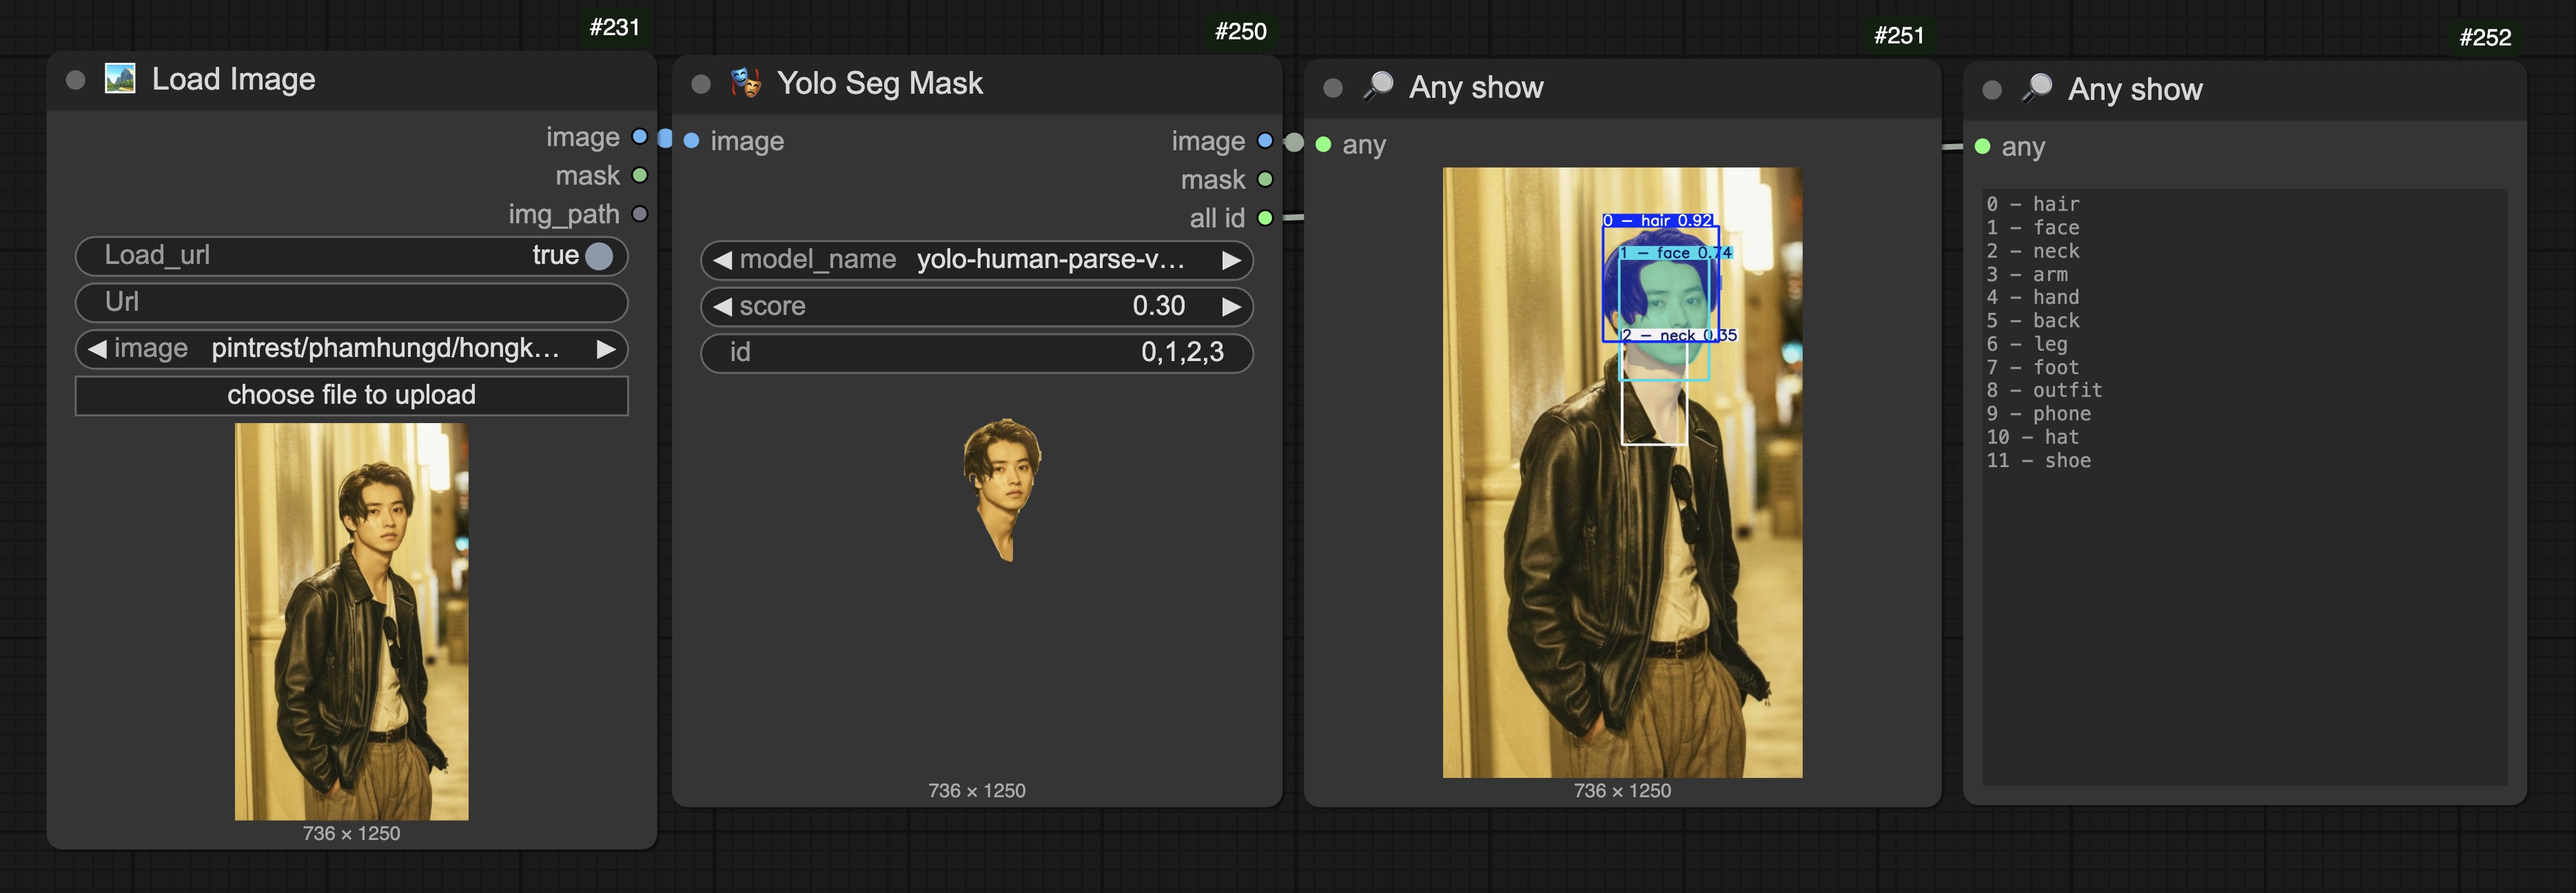
- This node separates distinct masked areas into individual masks, working exceptionally well with the inpaint crop node set.
📏 Get Mask Size
- Returns mask width/height (and latent) to drive dimension-aware workflows.
⚡️ Crop Inpaint | 🔄 Loop Inpaint Stitch
- These 2 nodes include their own crop/stitch implementation inside SDVN, so the external Inpaint-CropAndStitch node set is no longer required.
- Stitch accepts RGB or RGBA inpainted images. For RGBA, alpha multiplies the stitch mask so transparent pixels preserve the original image. The output remains RGB.
- The Loop Inpaint Stitch node is used to iteratively inpaint multiple regions when the input is a list. It stitches the results together and returns a single image, ideal for inpainting multiple areas in one pass.
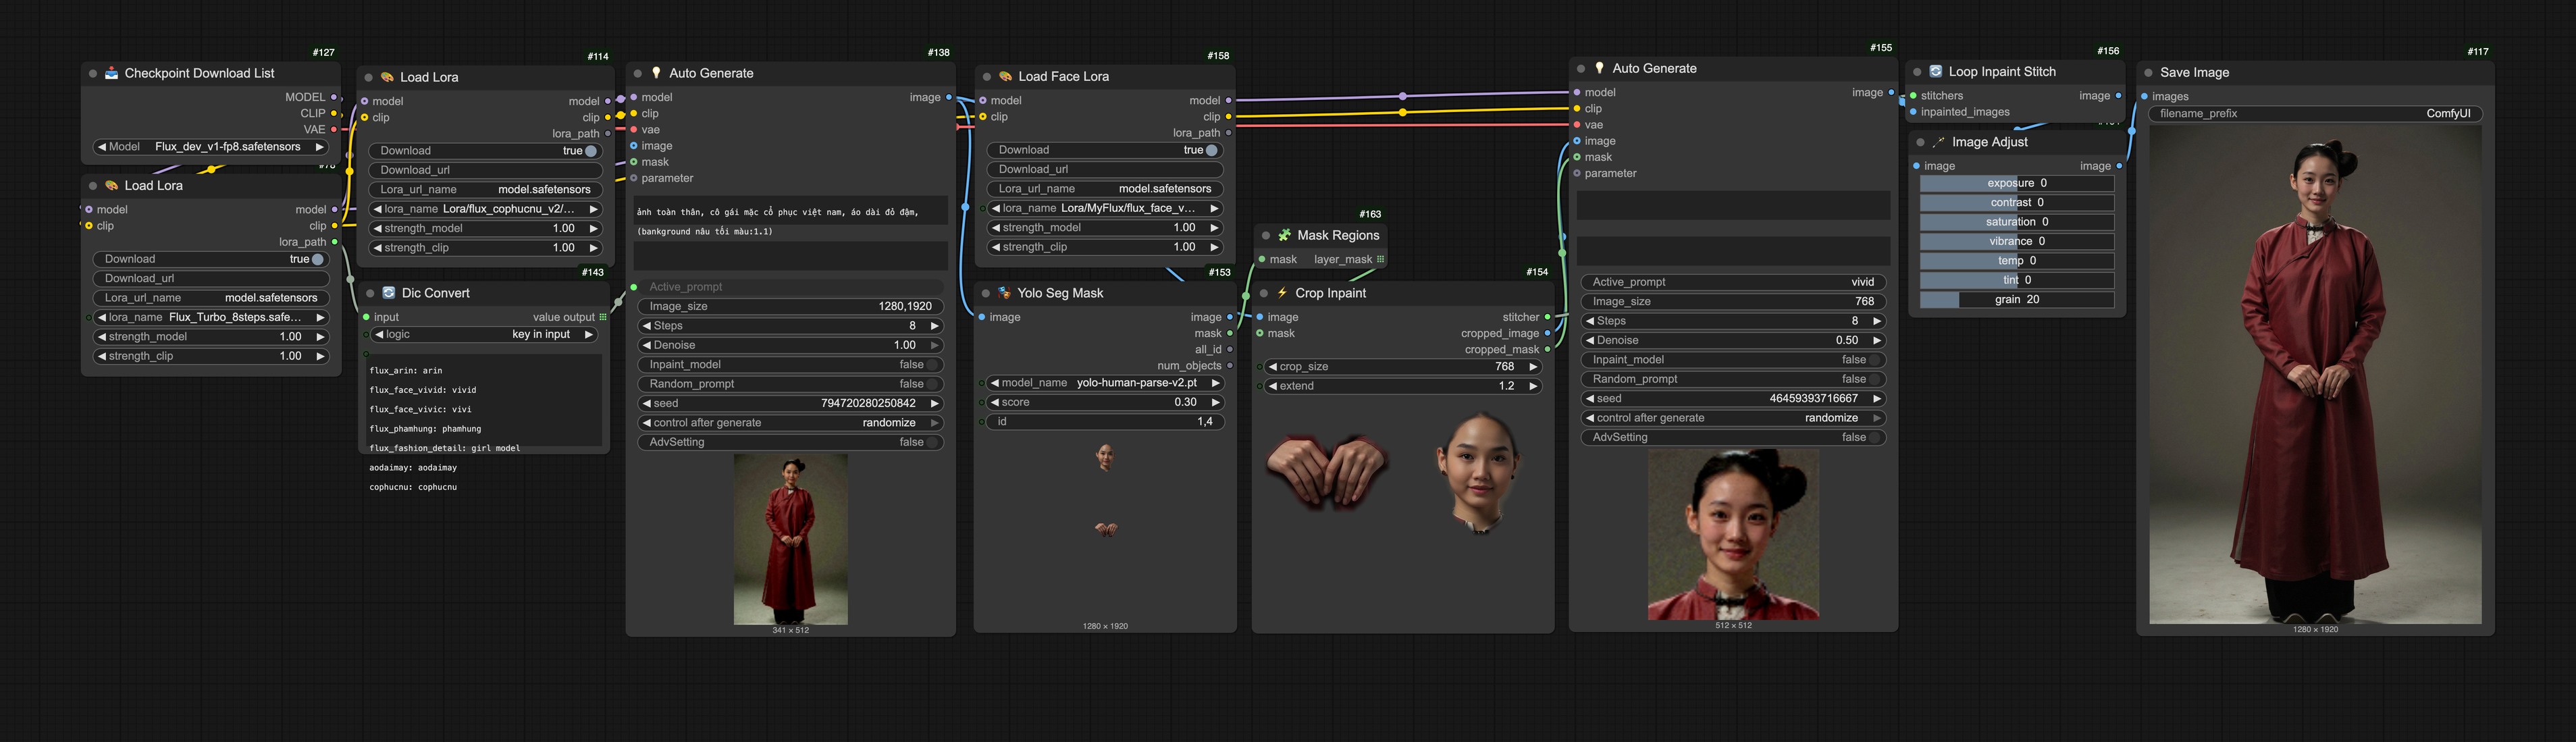
Example
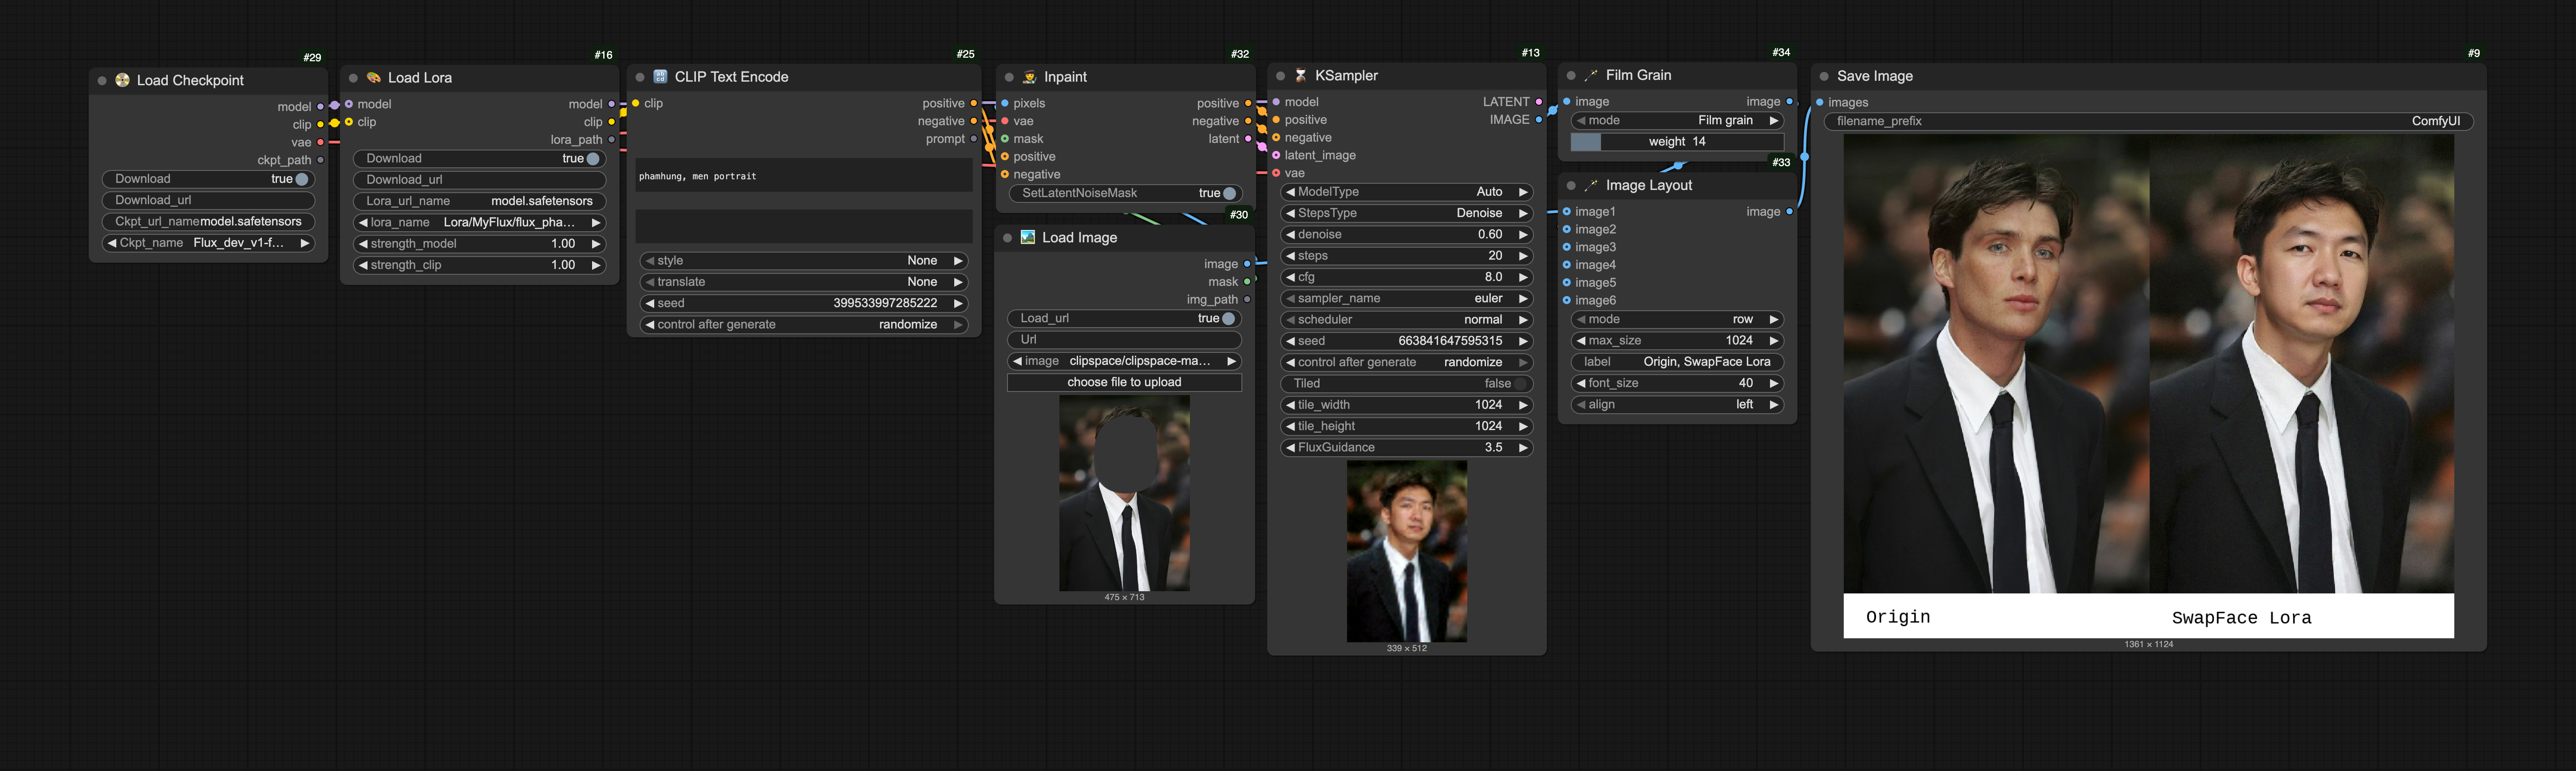
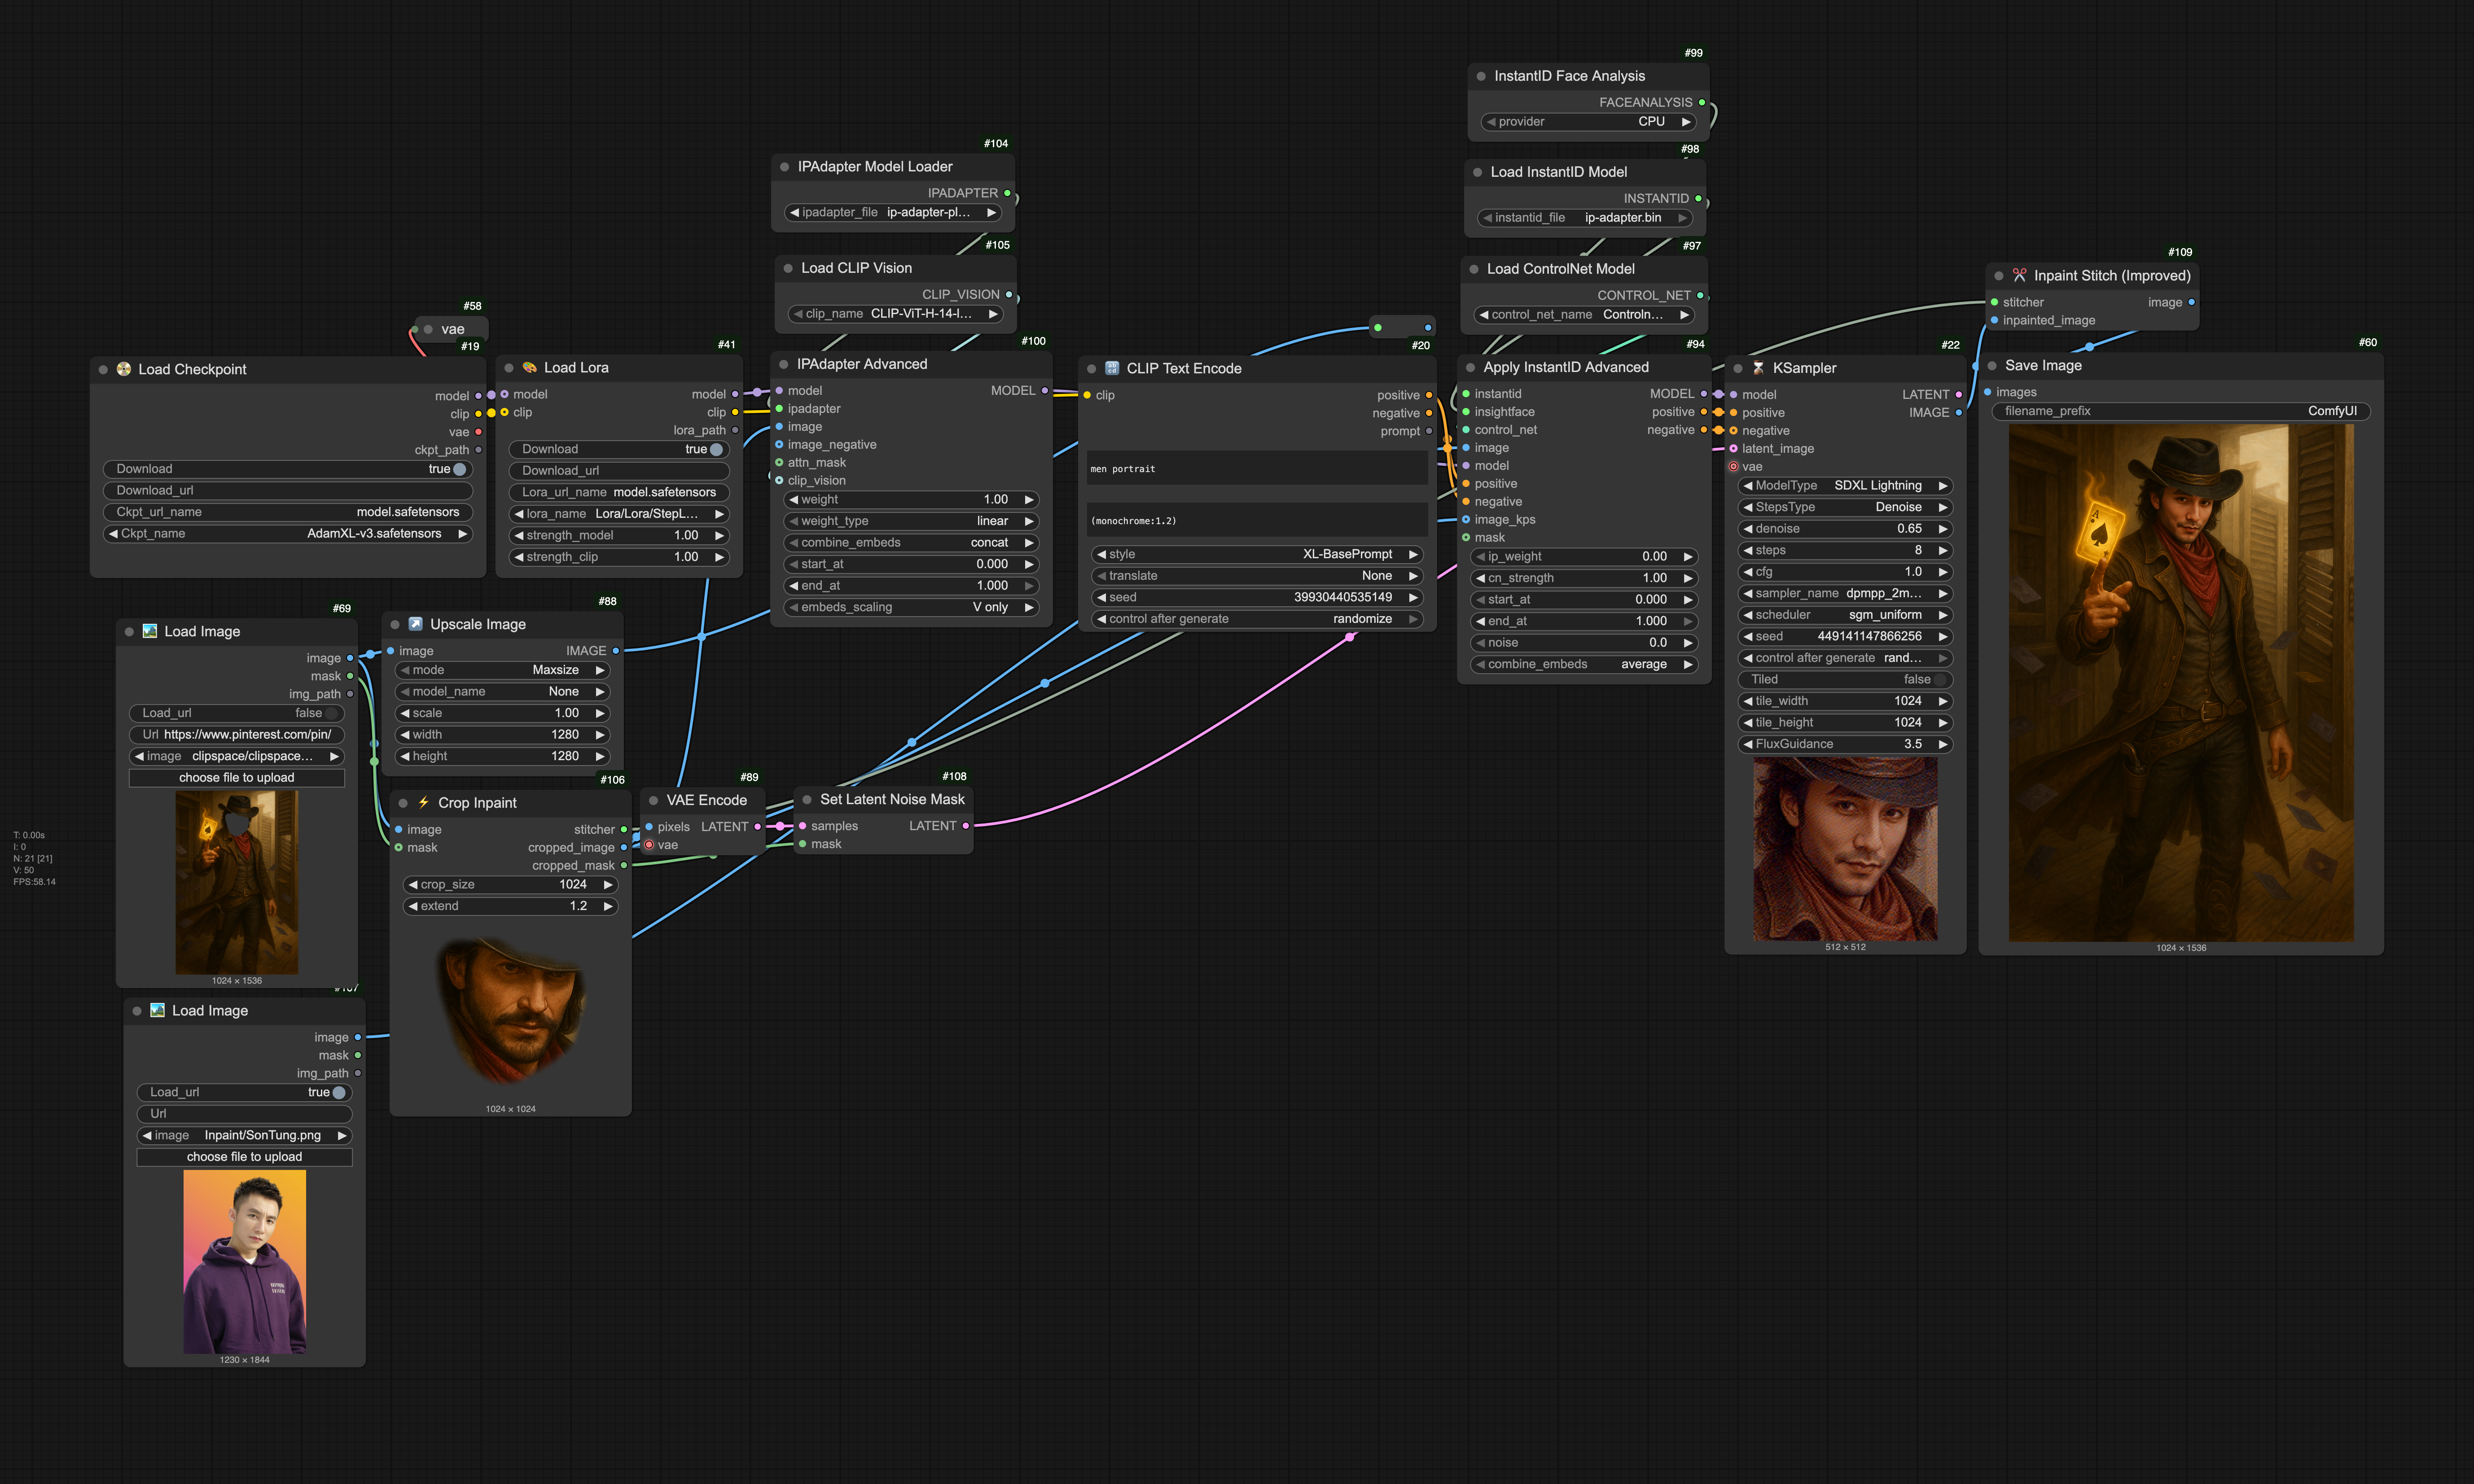
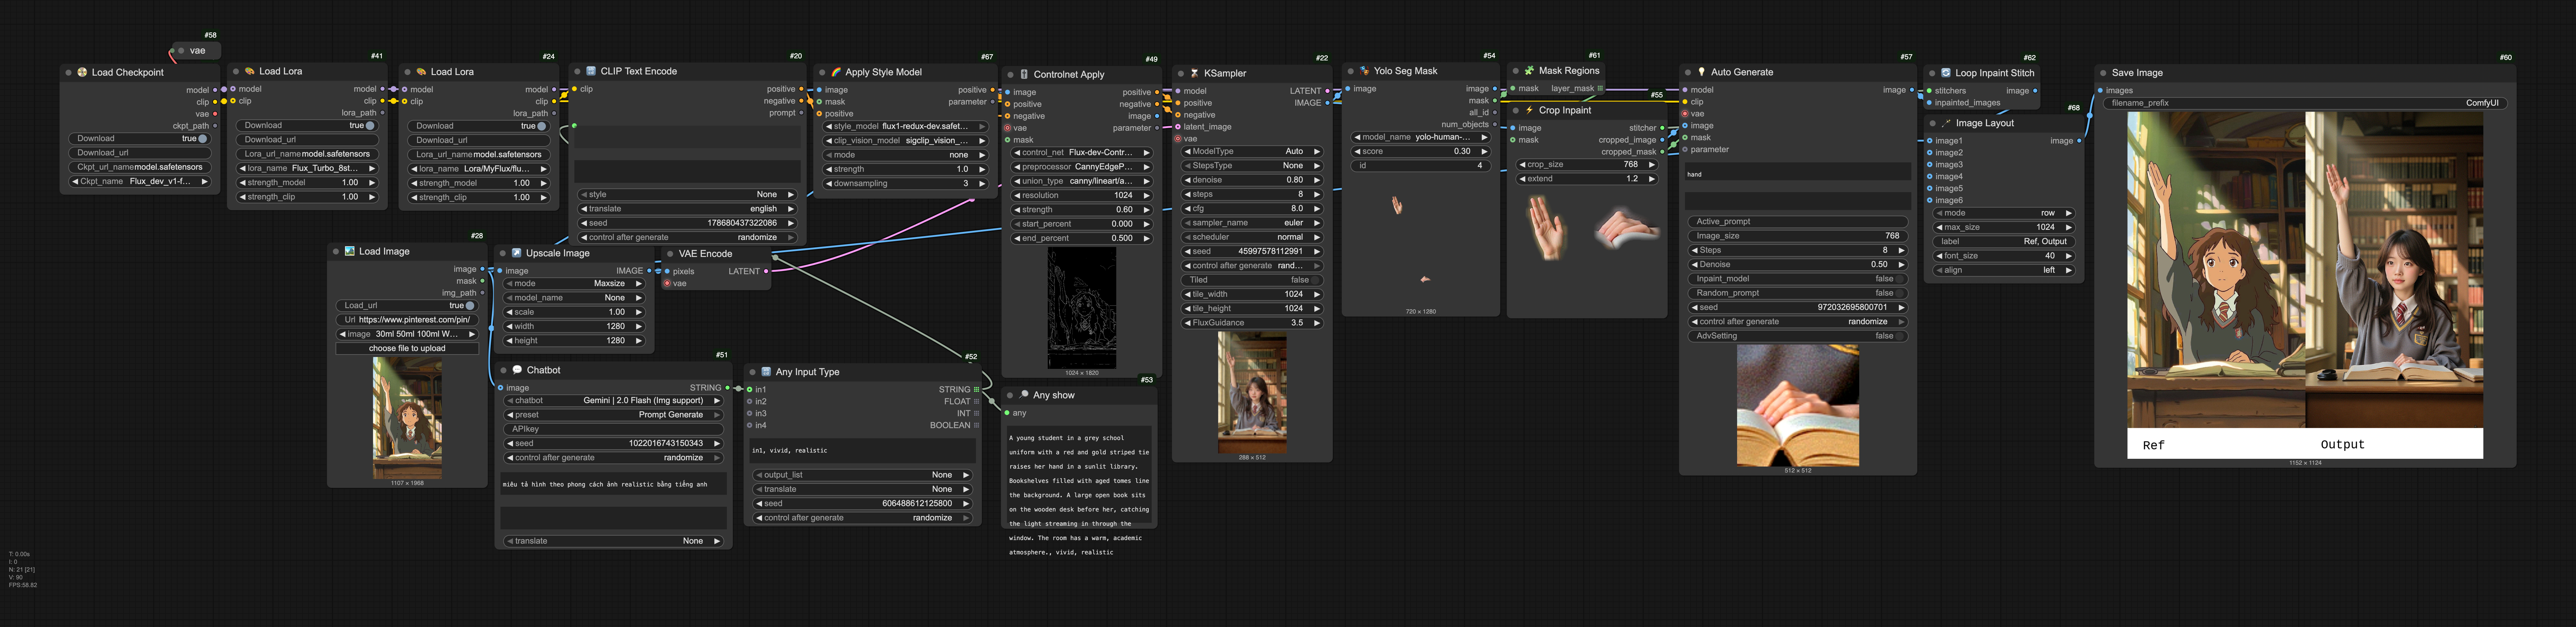
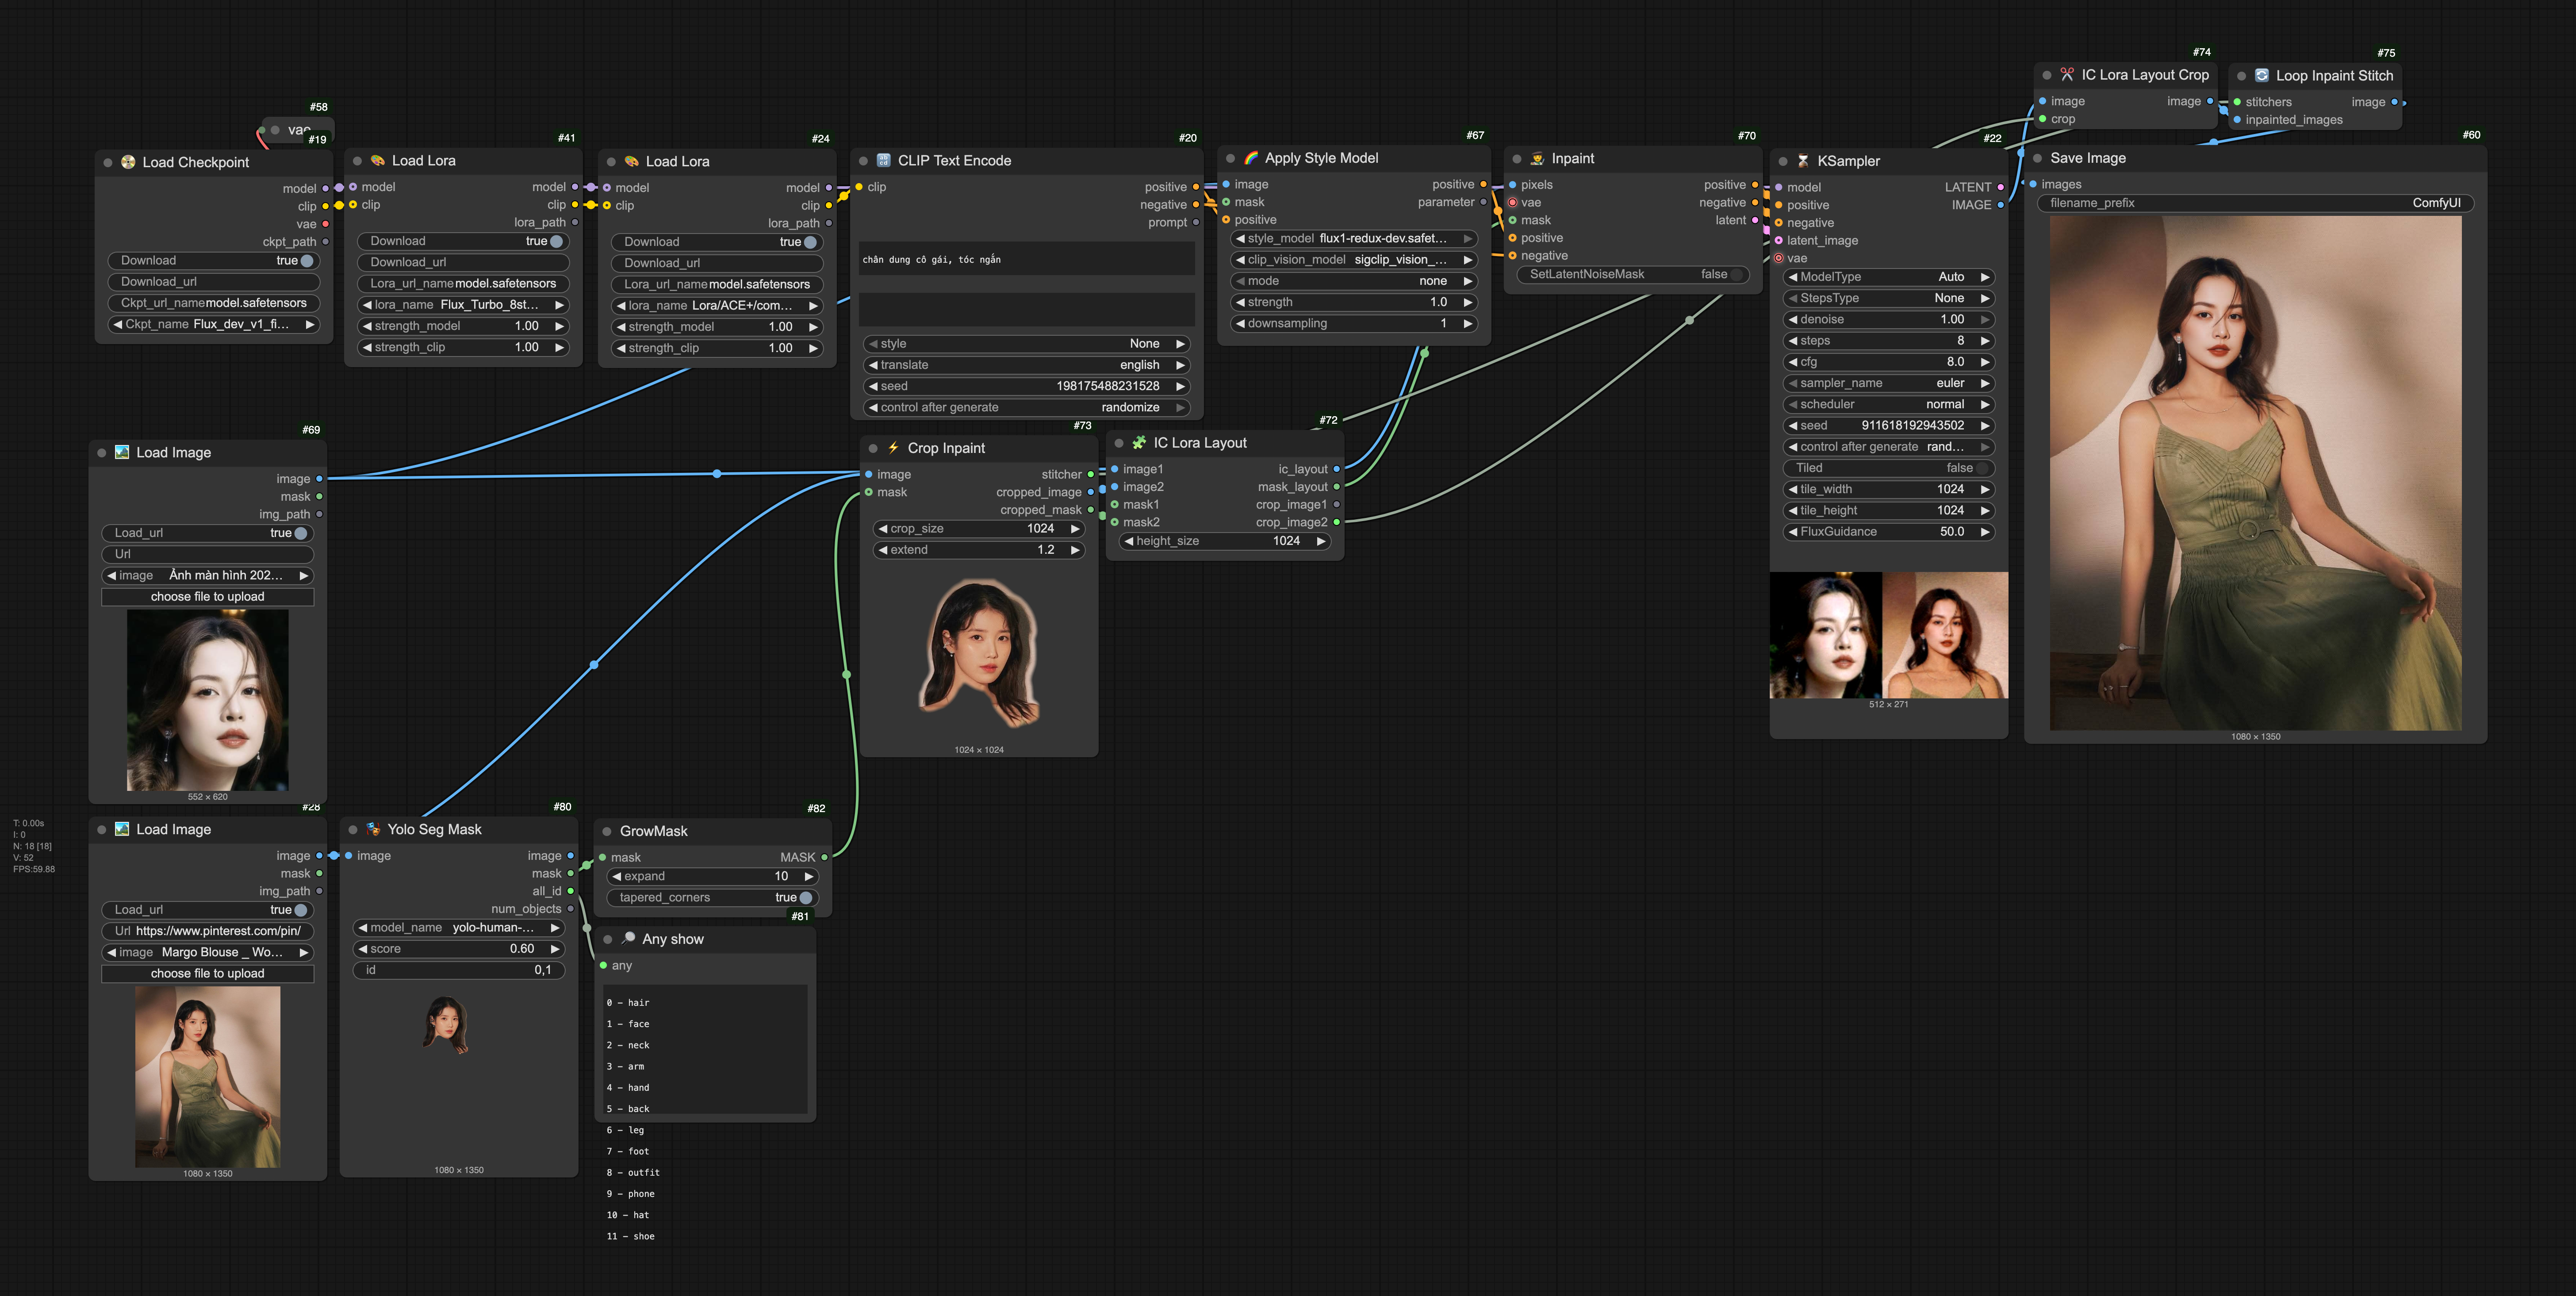
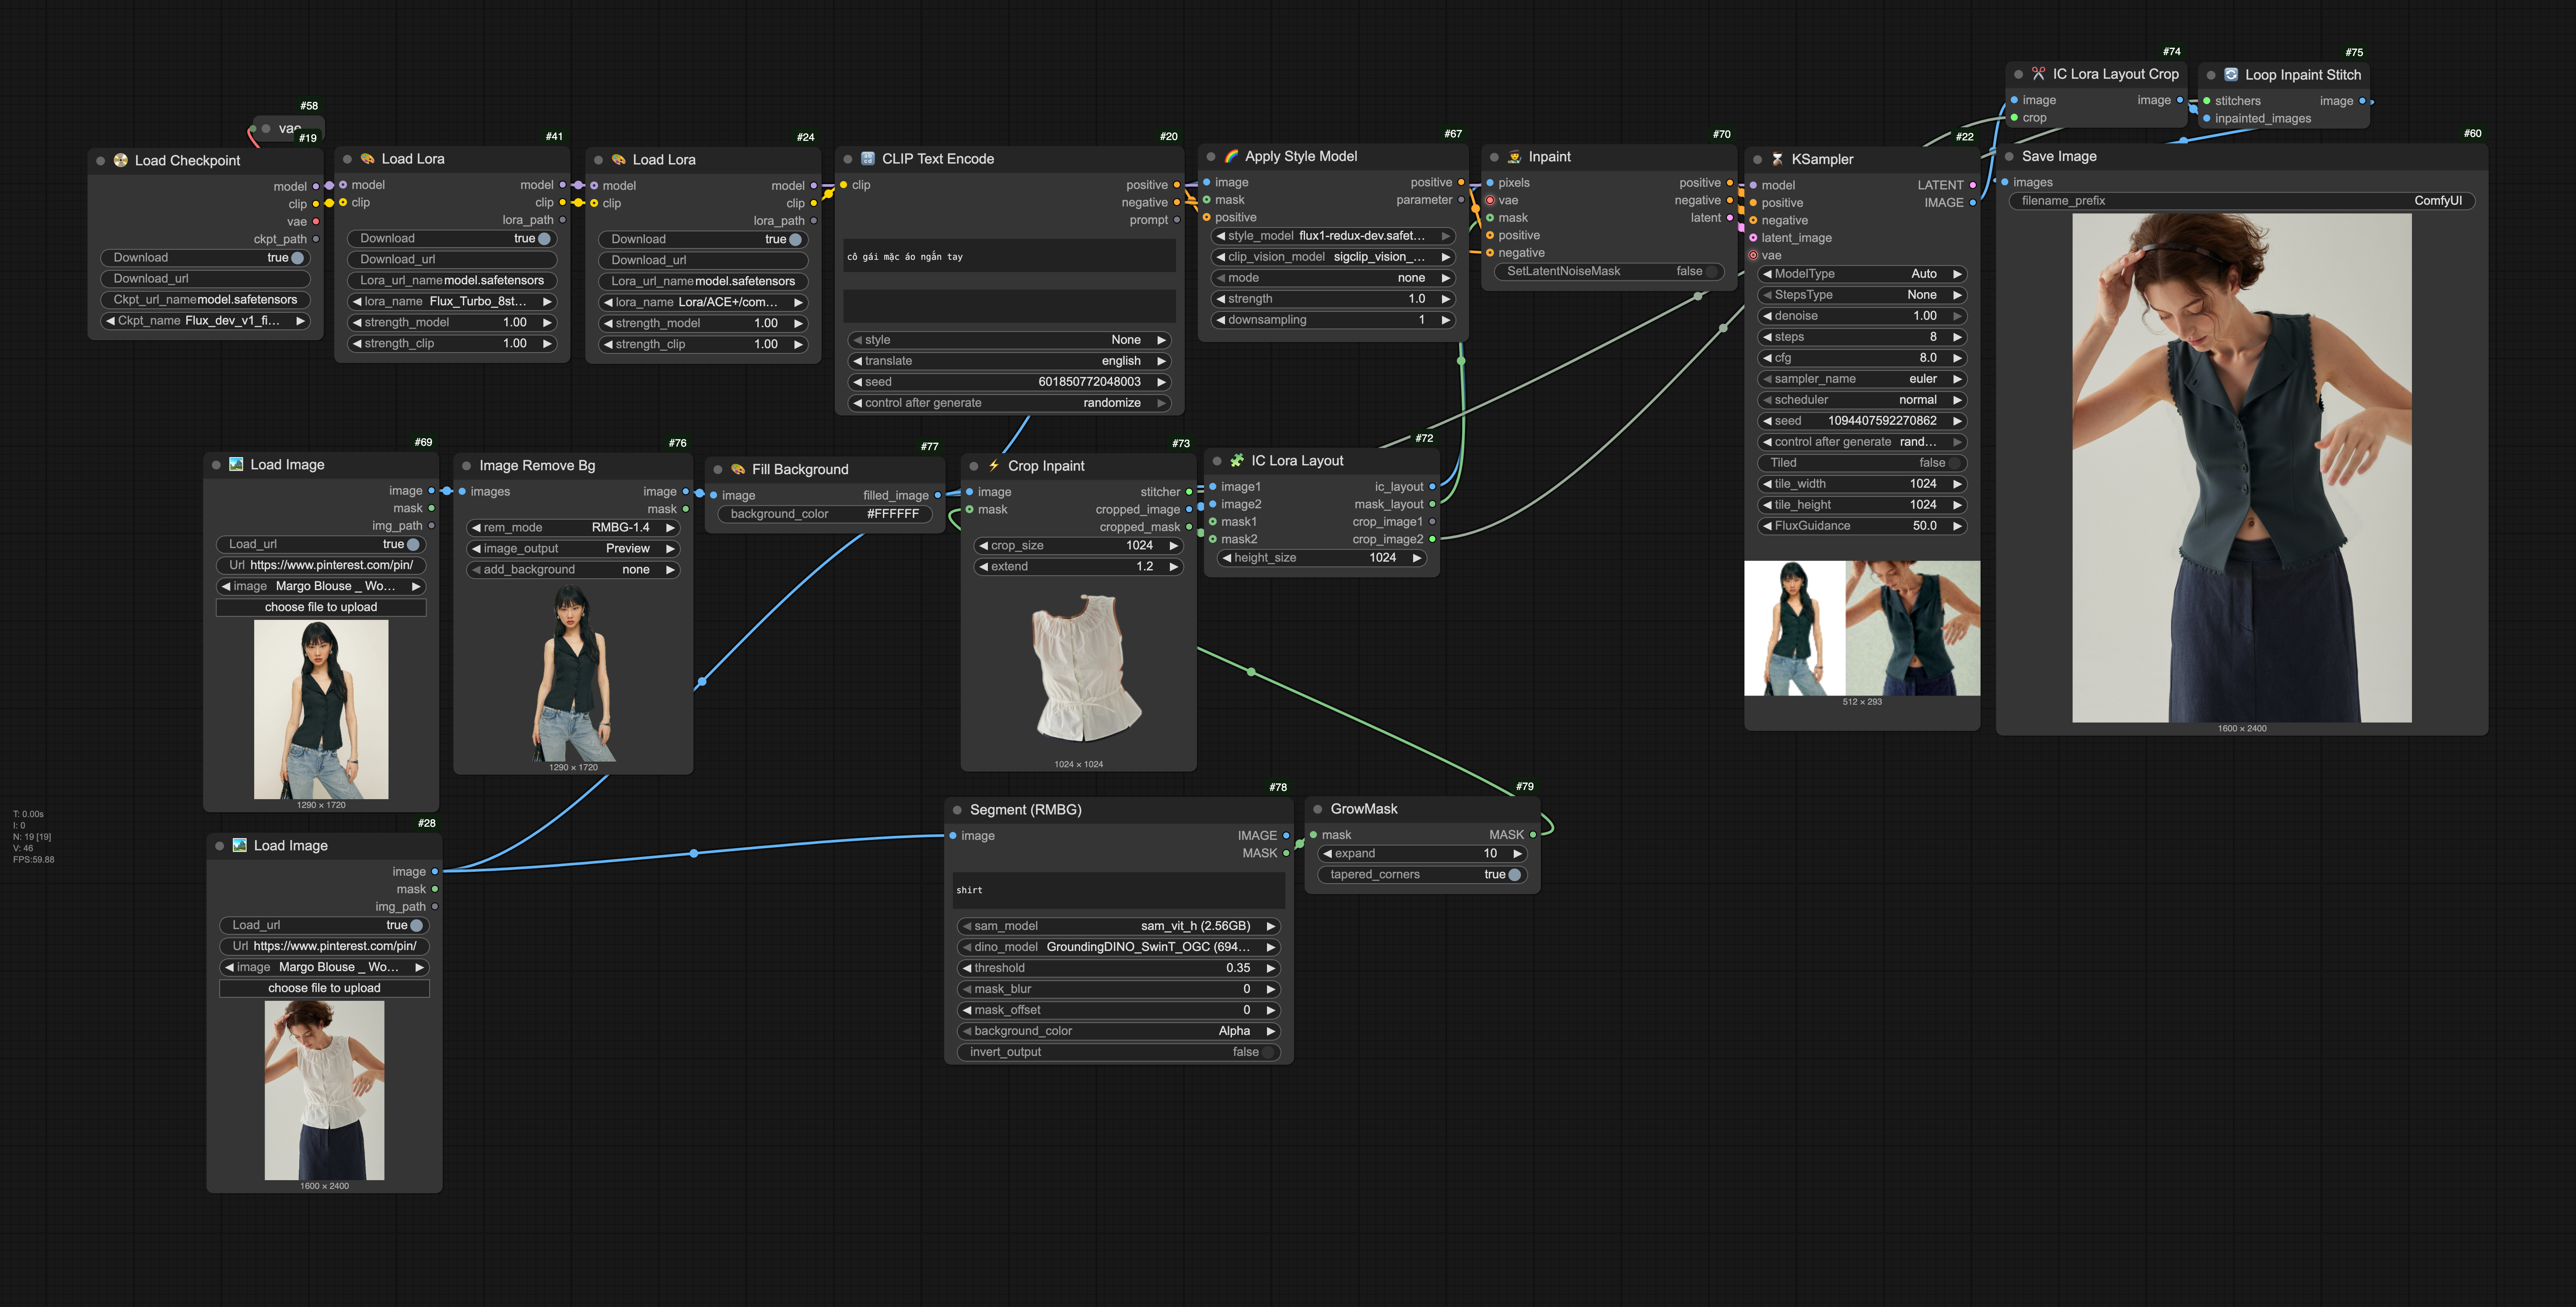
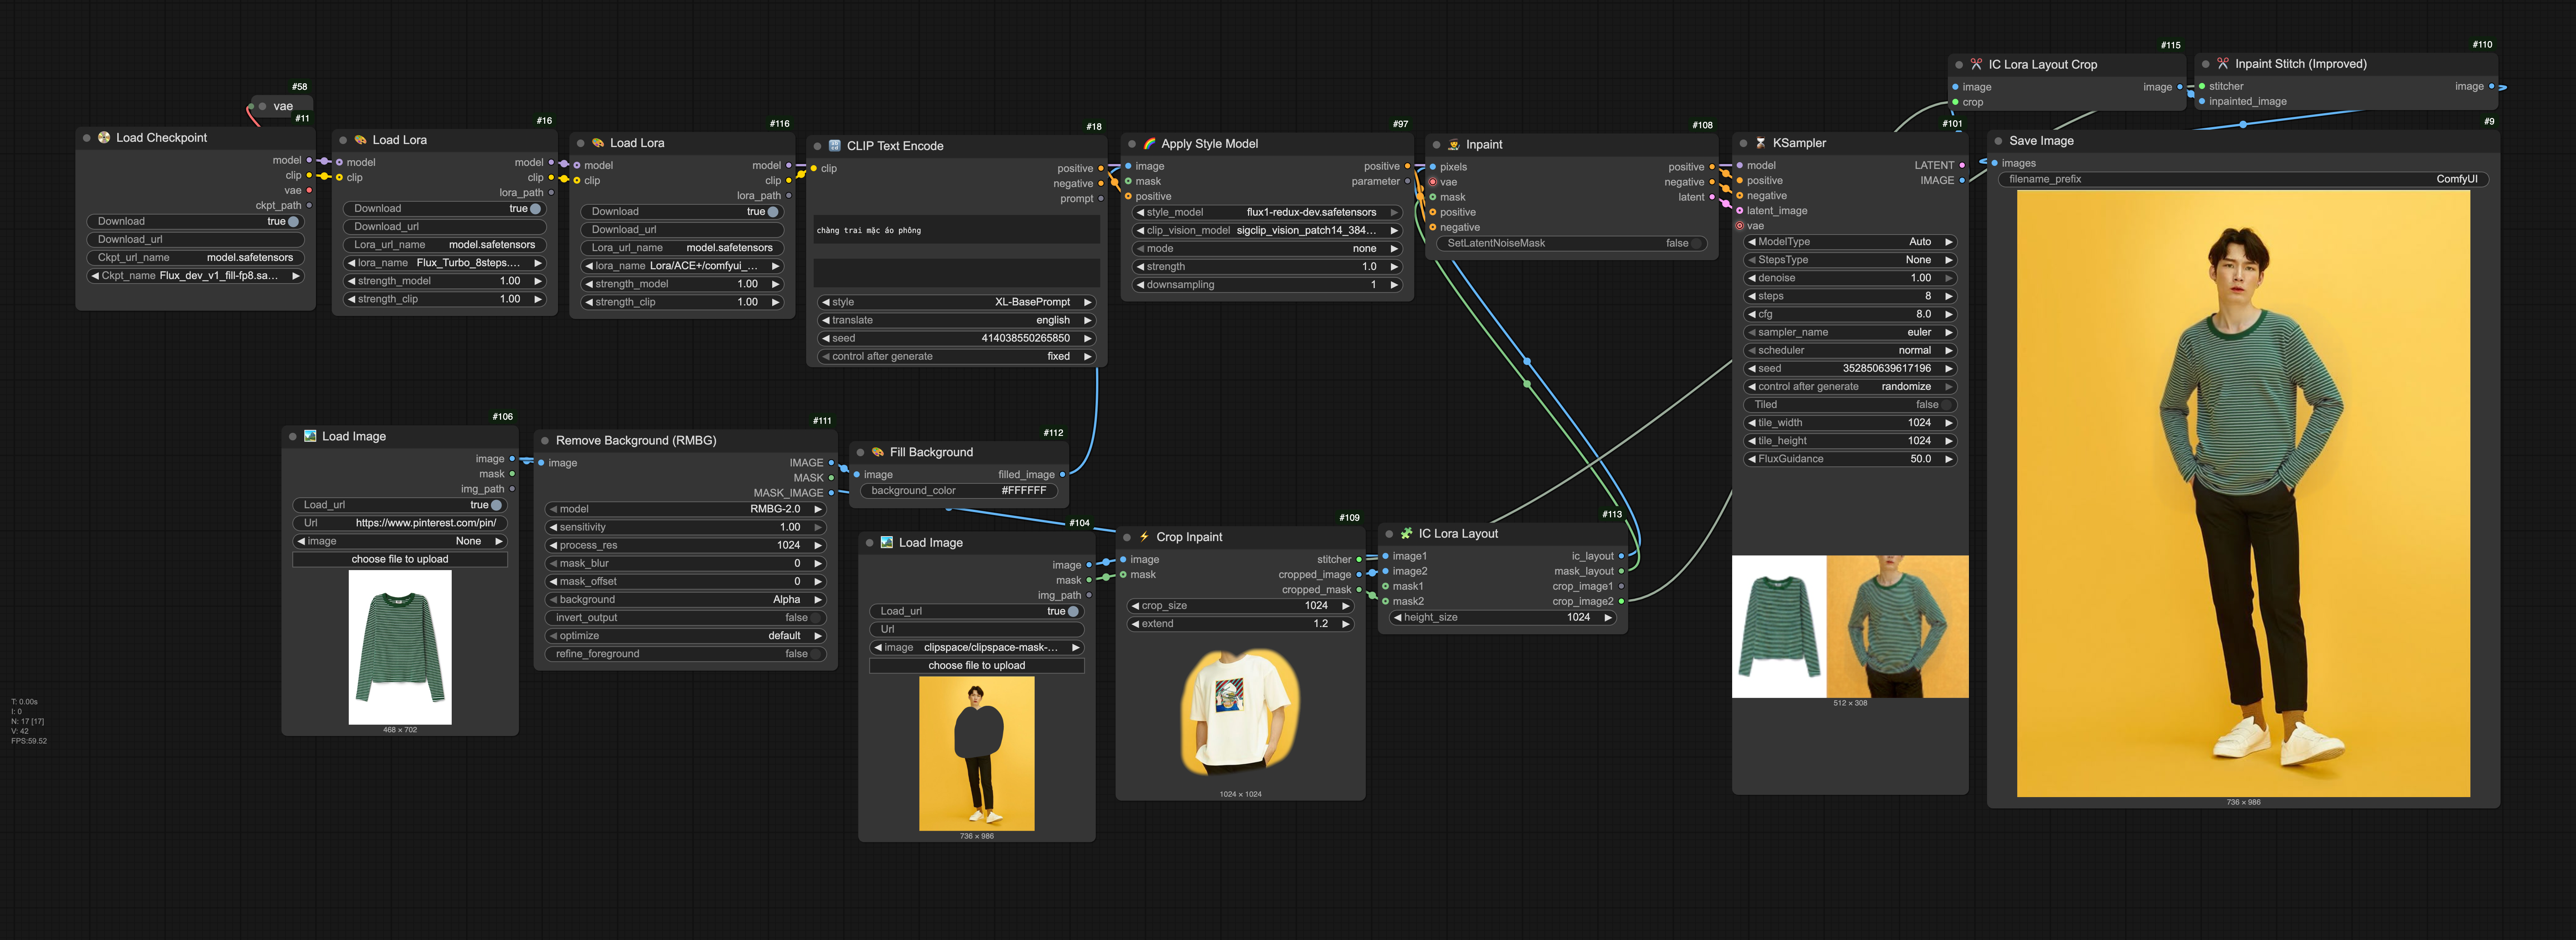
Copyright
Course
Built-in Segment Anything
SDVN SegmentAnything, SDVN SAMModelLoader, SDVN DinoModelLoader, SDVN DinoSAMSegment, SDVN InvertMask, and SDVN IsMaskEmpty are now bundled. Install the SDVN requirements, remove or disable the separate SDVN_Segment_Anything custom node, and restart ComfyUI to avoid duplicate node registrations. Existing workflows and models under models/sams, models/grounding-dino, and models/bert-base-uncased remain supported. The Python segment_anything library is still required. GroundingDINO uses the native BERT forward API with masks adapted for Transformers 4.x and 5.x. SDVN does not force a Transformers upgrade (tested on 4.50.3 and 5.18.0); timm, addict, and yapf are no longer needed.
Sam Segment (SAM 3.1)
SDVN Sam Segment (🧩 Sam Segment) is a separate node with only image, prompt, and threshold inputs. It uses SAM 3.1 directly, with no GroundingDINO, model selector, or text_threshold. SDVN SegmentAnything and SDVN SAMModelLoader keep the seven original SAM/SAM-HQ/MobileSAM models; use Sam Segment for SAM 3.1. SAM 3 and SAM 2.1 are not offered.
The node downloads the public Comfy-Org SAM 3.1 checkpoint (sam3.1_multiplex_fp16.safetensors) into models/sam3 on first execution, without Hugging Face authentication. Existing checkpoint files and extra sam3 paths are reused. It requires ComfyUI's native SAM 3.1 support (SAM3 Detect and SAM31); no additional Python requirements are needed.
Outputs are IMAGE (RGB cutout), MASK (one union mask per image), and a preview. RGB and RGBA inputs are accepted; input alpha is discarded before segmentation. Prompts support comma-separated concepts such as cat, dog, with up to 200 detections per concept by default; use cat:2 to set a limit. Images are processed independently, without video tracking. MPS performance and full checkpoint inference have not been benchmarked here.
Node and API maintenance
- Mask Size measures the union across an image batch, so an empty first mask no longer clears masks for later images in Crop Inpaint or Inpaint. Upscale accepts a zero width or height in Maxsize mode; Scale uses its scale factor even when both size fields are zero. White Balance accepts RGBA while preserving alpha. FP8 export converts floating weights on CPU and preserves integer buffers.
- Dependency checks now inspect installed package versions and platform markers on each startup. The installation marker is written atomically only after dependency installation succeeds. Requirements use
openai>=3.35.1andgoogle-genai==2.12.1/google-auth==2.49.0; update the existing requirements and restart ComfyUI. - GPT Image offers
gpt-image-2.5-sunburstandgpt-image-2.5-flare, including transparent PNG generation/editing, batched references and alpha-mask edits. The old DALL-E node keeps its workflow ID and output type but now uses GPT Image 2.5;standardmaps tomedium,hdtohigh. Existing GPT Image workflows selecting a retired model must select a current model. OpenAI image guide. - Google image nodes use the Interactions API: Nano Banana Lite uses
gemini-3.1-flash-lite-image, Pro usesgemini-3-pro-image, Nano Banana 2 usesgemini-3.1-flash-image, and the new default Nano Banana 2.1 usesgemini-nano-banana-2.1. The old Imagen node now uses Nano Banana 2.1; its people option is expressed as a prompt instruction, not the former Imagen server-side person-generation setting. Nano Banana 2.1 uses at least 1K when 0.5K is selected. Missing images return an error with the API text instead of silently returning a blank image. Google image guide. - Chatbot adds Gemini 3.5 Flash Lite, Gemini 3.8 Flash, DeepSeek Flash and V4 Pro. Existing Gemini 3 Flash and DeepSeek R1 selections route to Gemini 3.8 Flash and DeepSeek Flash respectively. Credential inputs and local key storage are unchanged. API tests use mocked responses and SDK transports; no paid API requests were made.
📝 Florence PromptGen
SDVN Florence PromptGen takes an IMAGE and returns English prompts as a STRING list, one per image in the batch. Uses Florence-2 PromptGen v2.0, with base by default and an optional large model.
- Modes:
Detailed prompt,Short caption,Tags,Caption + tags,Composition, andCaption + tags + composition.OCRtranscribes visible text in its original language. - Defaults to
num_beams=1and 256 output tokens for speed. Try 3 beams for caption quality at the cost of longer generation. - Downloads on first execution to
ComfyUI/models/LLM/Florence-2-{base|large}-PromptGen-v2.0; reuses complete local models and resumes incomplete downloads. No API key, external Florence node pack, or Flash Attention required. - Accepts RGB/RGBA and image batches. Offloads from GPU after generation by default and retains a RAM copy for reuse. Enable
keep_model_loadedto keep it on the device; ComfyUI still manages memory and can unload it when needed. - Requires
transformers>=4.57.6; uses native Florence2 without downloading or executing Python code from the model repository.
Colab dependency compatibility
Gemini SDK 2.12.1 and google-auth==2.49.0 are pinned together to match Colab’s authentication dependency and Google ADK 2.7.1’s google-genai>=2.12.1 requirement while retaining the Interactions image API. The startup dependency checker repairs older incompatible installations. Restart the Colab runtime after updating dependencies if Google libraries were already imported. Registry release 2.10.21 uses a new version number; the publish workflow skips versions already present in the registry.