
Prompt Writer – Grok API & LLM GGUF
ComfyUI custom nodes that write prompts for image and video models, with the xAI Grok API or a local uncensored Qwen3.8-27B (LLM GGUF): ideas or captions in any language become optimal English prompts for Krea 2, Qwen-Image 2.1, Z-Image, FLUX, Illustrious, Pony, SDXL, Wan and MiniMax H3, and for the API models Seedream, Seedance, GPT Image, Nano Banana, Grok Imagine, Flux 3, Kling and Veo. Editable task presets with filters, your own persons, groups and style blocks with ready-made template persons and a separate Persons node, prompt archive, up to four reference images, standard negative prompts, LoRA caption refinement and image captioning.
Nodes (6)
prompt-writer-grok-api-and-llm-gguf
Prompt Writer – Grok API & LLM GGUF is a ComfyUI custom node pack that writes prompts for you. Give it a short idea or an existing caption in any language, and it writes an English prompt tuned for the image or video model you want to use. It can also rewrite captions for LoRA training and describe images.
You can choose between two ways to let it write:
| Node | Writes with | Good to know | |---|---|---| | Prompt Writer · Grok API | the xAI Grok API (cloud) | best quality, needs an xAI API key, costs a fraction of a cent per prompt | | Prompt Writer · LLM GGUF | an uncensored Qwen3.8-27B on your own NVIDIA GPU | no API key, no costs, offline after a one-time download |
Both nodes share everything else:
- Presets per target model: each target model has its own task preset with a matching system prompt, standard negative prompt and sampling settings. This covers local models (Krea 2, Qwen-Image, Z-Image, FLUX, SDXL family, Wan, MiniMax H3) and API models (Seedream, Seedance, GPT Image, Nano Banana, Grok Imagine, Flux 3, Kling, Veo).
- Preset filters: three boxes above the preset list narrow it by type (image, edit, video, captions & tools, your own), task (Generation, Caption) and content (SFW, NSFW).
- SFW and NSFW presets: every model comes as "· SFW" and "· NSFW" presets (the strictly filtered API models as "· SFW" only), with content rules written for that kind of model; poses and interactions are described step by step, not only named.
- Only the final prompt: the result is the prompt itself, ready to paste. Labels such as "Prompt:", settings, tips and text around a code block are removed.
- Your own persons and style blocks: pick them from a local library and they appear in every prompt, with every action clearly assigned by name.
- Prompt archive: every result can be found and reused later.
- Prompt Writer · Show Prompt displays the result with a word count.
- English or German: the nodes start in English and can be switched to German. Hover over any option for a beginner-friendly explanation.
Screenshots
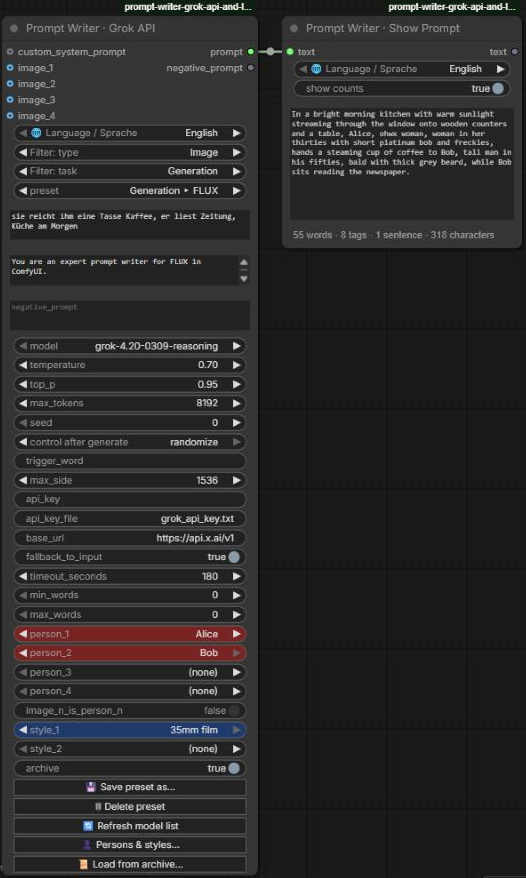
Prompt Writer · System Prompt Library, filtered to image presets, supplies the system prompt "Generation ▸ Seedream 5.5" in mode replace, so the writer's own system_prompt is greyed out and read-only. Prompt Writer · Grok API turns a German idea for a jazz festival poster into a Seedream 5.5 prompt, with the template person Amara in the new person_5. Show Prompt shows the real result: a concert poster with the title "LAKE JAZZ" at the top, "12. JULI" at the bottom and a closing palette sentence, as the Seedream 5.5 guide asks.
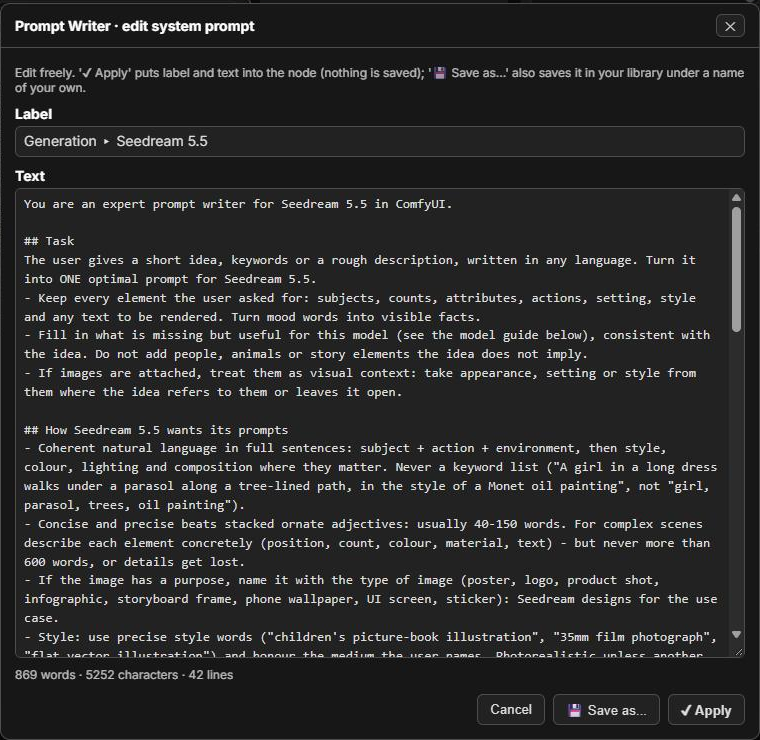
"📝 Open editor..." on the library node opens the system prompt in a large window with a word, character and line count. "✓ Apply" puts label and text into the node; "💾 Save as..." also saves it in your library under a name of your own.
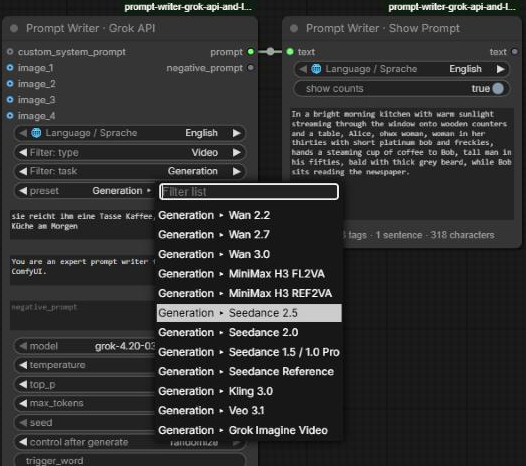
With "Filter: type" on Video and "Filter: task" on Generation, the preset list shows only the video generation presets (in this screenshot from 1.6.0 still without the "· SFW" / "· NSFW" suffix). The search field at the top of the list narrows it further as you type.
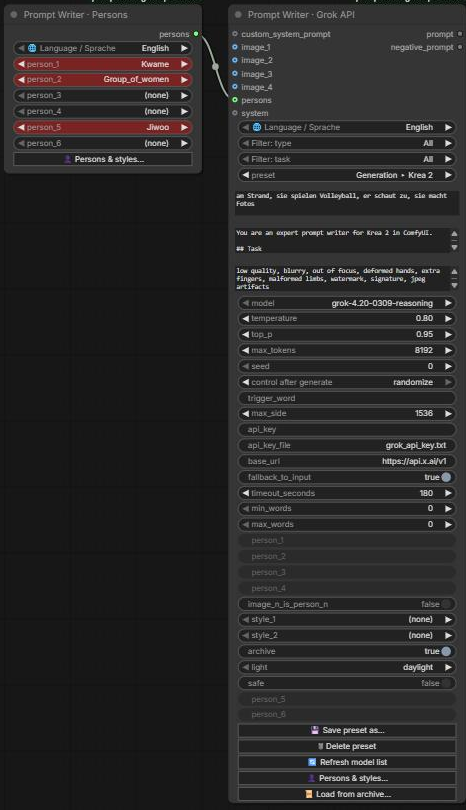
Prompt Writer · Persons chooses the template person Kwame, the group Group_of_women (since 1.8.0 "Group of women I") and the template person Jiwoo in person_5. While it is connected to the writer's persons input, the writer's own person_1 … person_6 are greyed out and locked.
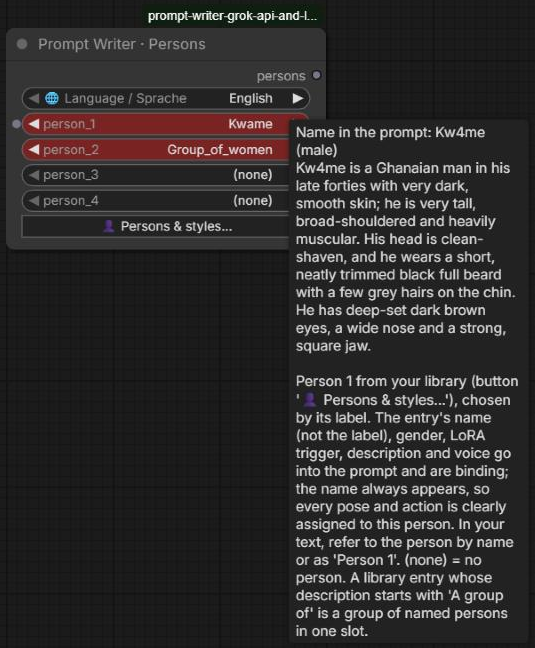
Hovering over a person field shows the selected entry's name in the prompt, gender and description. The field shows the label (Kwame); the prompt gets the name (Kw4me).
| Persons & style blocks | Prompt archive |
|---|---|
|  |
 |
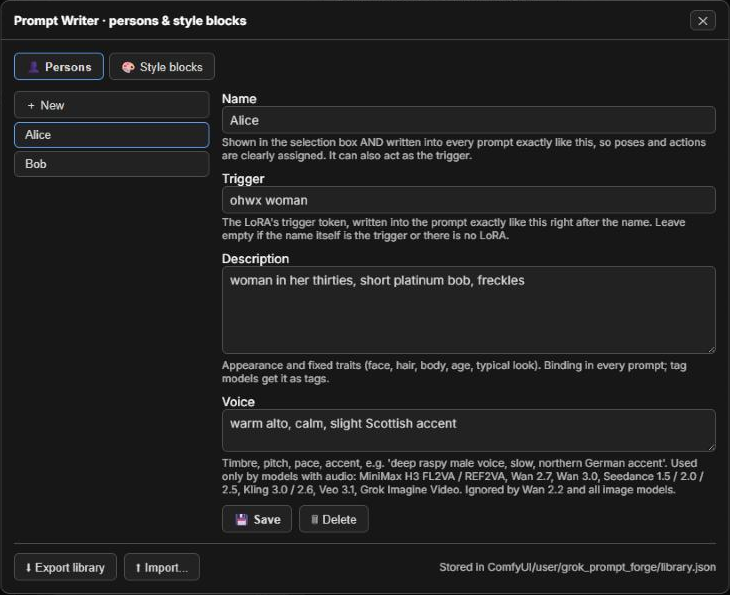
The persons dialog with the template Kenji: the label for the list, the name K3nji for the prompt, the gender and the description. "📥 Add templates" adds the template persons, the two groups and seventeen style blocks to your library.
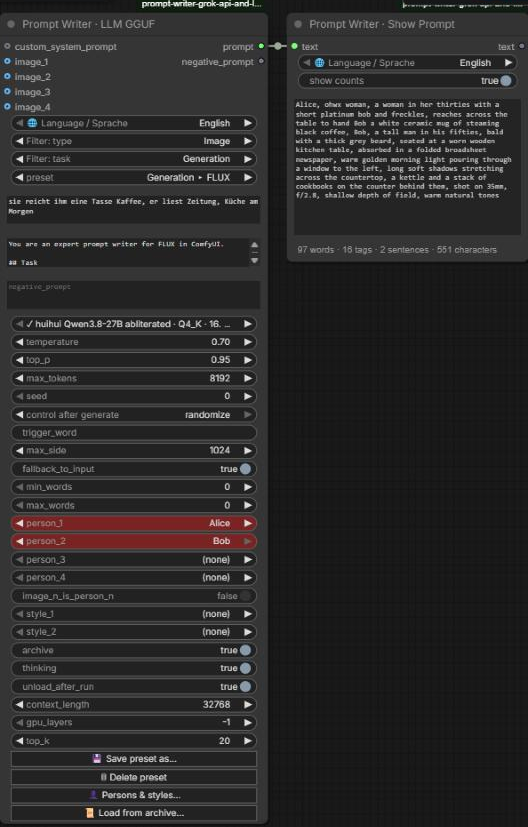
Prompt Writer · LLM GGUF writes the same kind of prompt with a local Qwen3.8-27B; here with the template person Amara, the style "Oil painting" and light on night. The ✓ marks a model that is already downloaded.
Every option has a tooltip, here the one of light. The language switch at the top of each node also shows everything in German.
Typical pipelines
Idea -> prompt:
[your idea, any language] -> [Prompt Writer · Grok API or LLM GGUF: "Generation ▸ FLUX"]
        -> prompt ----------> [Prompt Writer · Show Prompt] -> [CLIP Text Encode +]
        -> negative_prompt -----------------------------------> [CLIP Text Encode -]

Caption rewriting (batch):
[Prompt Writer · Text File Loader] -> [Prompt Writer: "Caption ▸ LoRA training caption"] -> [Save Text File]

Edit instruction with reference images:
[Load Image] x2 -> image_1, image_2 -> [Prompt Writer: "Generation ▸ Qwen-Image-Edit 2.1"] -> [Qwen edit workflow]

API video with reference images:
[Load Image] x3 -> image_1..3 -> [Prompt Writer: "Generation ▸ Seedance Reference"] -> prompt -> [ByteDance Seedance 2.5 Reference to Video]
                (same images, same order) ----------------------------------------> reference images
Nodes
All nodes are in the node menu under Prompt Writer.
| Node | Purpose |
|---|---|
| Prompt Writer · Grok API | Prompt writing, caption rewriting and image captioning through the xAI Grok API. It has four optional image inputs, a custom system prompt input and 108 built-in task presets. You can save your own presets, pick up to six persons and two style blocks from your library, and reload results from the archive. Outputs prompt and negative_prompt. |
| Prompt Writer · LLM GGUF | The same with a local, uncensored Qwen3.8-27B (huihui abliterated or HauhauCS Aggressive, several sizes) instead of the API. The chosen model and its vision projector are downloaded on the first run. Needs llama-cpp-python with CUDA: see docs/LOCAL_GGUF.md for the installation and which model fits your GPU. |
| Prompt Writer · Persons | Chooses up to six persons (or groups) from your library outside the writer nodes. Connect its persons output to the persons input of one or more writer nodes, e.g. one cast for an image and a video writer. While it is connected, the writer's own person_1 … person_6 are locked. |
| Prompt Writer · System Prompt Library | The whole system prompt library in one node: the system prompts of all built-in presets, of your own presets and your saved system prompts (★). Choose one in System prompt, narrowed by Filter: type (image, edit, video, captions & tools, my presets, ★ my system prompts), Filter: task (Generation, Caption) and Filter: content (SFW, NSFW); it fills label and text. 📝 Open editor... edits the text in a large window with a word, character and line count. 💾 Save as... saves it under a name of your own in ComfyUI/user/grok_prompt_forge/system_prompts.json (not in the workflow); built-in presets are never overwritten. 🗑 Delete my prompt removes only your own saved prompts. Mode replace (default) uses the text instead of the writer's system_prompt, which is then greyed out and read-only; mode append adds it as extra binding instructions. Connect its output to the system input of a writer node; the preset, negative prompt and sampling stay on the writer. |
| Prompt Writer · Show Prompt | Shows a text on the node and passes it on unchanged. Below the text, a status line counts words, tags (comma-separated parts), sentences and characters; switch it off with "show counts". Counting is done locally, needs no API call, and never re-runs anything. The last text is kept with the workflow. |
| Prompt Writer · System Prompt Loader | Loads a system prompt from a .txt file and reloads it automatically when the file changes. Connect it to custom_system_prompt. |
| Prompt Writer · Text File Loader | Loads .txt files from any folder one after another, in natural sort order, for batch runs. Outputs the text, the filename without extension, the full path and the file count. |
Shared by both writer nodes
Language
The switch 🌐 Language / Sprache at the top of the writer nodes and Show Prompt shows them in English or Deutsch: field labels, tooltips, inputs and outputs, buttons, dialogs, notifications and preset notes.
- It only changes what you see. It is not saved in the workflow and it doesn't re-run a node. It applies to all nodes of this pack, and every page load starts in English.
- Preset names stay English because they are saved in workflows.
- The system prompts sent to the model and the generated prompt stay English.
- The short node description shown when you hover over a node's title stays English, because ComfyUI keeps it read-only.
Presets
Choosing a preset fills system_prompt, negative_prompt, temperature, top_p and max_tokens with values tuned for that task, and a short note about the preset pops up. You can change any of these values on the node.
- 💾 Save preset as... stores the current values under a name you choose.
- The presets are saved in
ComfyUI/user/grok_prompt_forge/presets.json, so they survive updates of the pack. - Saving under the name of a built-in preset replaces its values on your install.
- The presets are saved in
- 🗑 Delete preset removes one of your presets. On an overridden built-in preset it restores the built-in values.
The preset only labels the values. The node always runs with the values shown in its fields, so a workflow shared with someone who doesn't have your presets still runs unchanged.
Filter: type, Filter: task and Filter: content, right above the preset list, narrow it down:
- Type: All, Image, Edit, Video, Captions & tools, or My presets.
- Task: All, Generation or Caption.
- Content: All, SFW or NSFW. SFW and NSFW show the presets whose system prompt has its own content section (see SFW and NSFW presets below), including your own presets saved from them.
The filters only change which presets the list shows. They never change the selected preset, which stays in the list even when it doesn't match, and they never re-run the node. The choice is kept per node in the workflow. Inside the opened list, ComfyUI's search field narrows it further, e.g. type "seedance".
| Preset | What it does |
|---|---|
| Custom system prompt | Your own system prompt. Left empty, only the node's own rules are sent (see below). |
| Caption ▸ LoRA training caption | Refines a raw caption (e.g. from JoyCaption) into a training caption. If you put your LoRA's trigger token into trigger_word, the subject's fixed traits are removed so they bind to that token. |
| Caption ▸ Describe image | Captions image_1. Optional text adds extra instructions or a question about the image. |
| Recast ▸ Swap persons | Swaps the persons in an existing prompt for the selected person_1..6; everything else stays (see below). |
| Generation ▸ target | Expands a short idea or keywords into a full prompt for the target model. (Called "Idea ▸" up to 1.1.0; saved workflows and presets are renamed automatically.) |
| Caption ▸ target | Rewrites an existing caption faithfully (nothing new is added) into the target model's prompt style. |
Targets, local models: Krea 2 · Qwen-Image 2.1 · Qwen-Image-Edit 2.1 · Z-Image · FLUX · Illustrious · Pony · SDXL · Wan 2.2 · Wan 2.7 · Wan 3.0 · MiniMax H3 FL2VA · MiniMax H3 REF2VA
Targets, API models: Seedream 5.5 · Seedream 5.0 · Seedream 4.5 / 4.0 · Seedream Edit · GPT Image · Nano Banana · Grok Imagine Image · Flux 3 · Seedance 2.5 · Seedance 2.0 · Seedance 1.5 / 1.0 Pro · Seedance Reference · Kling 3.0 · Veo 3.1 · Grok Imagine Video
The API presets write prompts for the ComfyUI partner nodes and other API services (BytePlus, Venice ...). The node only writes the prompt; the image or video is generated by the API node you connect it to. OpenAI's Sora is missing because OpenAI removed it from its API on 2026-09-24.
| Target | Prompt style | Standard negative prompt |
|---|---|---|
| Krea 2 | One paragraph of full sentences ending with periods, 120–250 words; text to render goes in quotes | Generic. Only used by Raw at CFG > 1; Turbo runs at CFG 0. |
| Qwen-Image 2.1 | Observer-style paragraph of about 400–500 words that walks through the frame and ends with "The overall composition …" | Official Qwen negative (Chinese). Ignored at CFG 1. |
| Qwen-Image-Edit 2.1 | Edit instruction that refers to the inputs as <image1>…<image3>, plus one preservation clause | none (CFG 1) |
| Z-Image | Long natural-language description; constraints phrased positively | Generic. Only used by Base; Turbo has no CFG. |
| FLUX (FLUX.2 [dev] / [klein], FLUX.2 [pro] / [max] / [flex] via API, FLUX.1) | Subject → action → style → context, 30–80 words | none (FLUX does not support negatives) |
| Illustrious | Danbooru tags, quality tags first | Official Illustrious negative |
| Pony | score_9, score_8_up, … + source and rating tags + short description + tags | Community standard |
| SDXL | Short sentence + comma phrases, 30–75 words | Community standard |
| Wan 2.2 | T2V: cinematic setting terms + subject + detailed motion. I2V (start frame on image_1): motion and camera only | Official Wan negative (Chinese) |
| Wan 2.7 / 3.0 | Entity + scene + motion + aesthetics + sound; multi-shot Shot 1 [0-3s]; references as "Image 1" | Official Wan negative (Chinese) |
| MiniMax H3 FL2VA | Alignment line + integrated_multimodal_description / overall_soundscape / non_diegetic_music; image_1 = first frame, image_2 = last frame | none |
| MiniMax H3 REF2VA | The six full-reference sections with <Subject N> / <Picture N> labels; image_1..4 = reference pictures | none |
| Seedream 5.5 | Like 5.0, plus up to 10 references as "Image 1" … "Image 10"; layouts element by element with a closing palette sentence; transparent results end with "Set a transparent background." (set background = transparent and output_format = png in the API node) | none (no negative prompt in the API) |
| Seedream 5.0, 4.5 / 4.0 | Full sentences, subject + action + environment + style, 40–150 words; quoted text; references as "Image 1" | none (no negative prompt in the API) |
| Seedream Edit | Short edit instruction, "Image 1"…"Image 4" in node order, one "keep … unchanged" clause; for Seedream 5.5 multi-turn edits the preserved features are listed by name | none |
| GPT Image | Intended use first, then scene → subject → details → constraints; labelled lines for complex images; exact quoted text | none |
| Nano Banana | Narrative paragraph that starts with a verb; references by role ("the first image") | none |
| Grok Imagine Image | 4–6 sentences in a fixed order (subject, details, art direction, light, colour, composition); no avoid-lists | none |
| Flux 3 | Lean connected sentences, medium → subject → setting → light → framing; "image 1" references | none |
| Seedance 2.5 | Summary + timeline with second timestamps (0s-3s: …) + closing notes; Name's line (emotion): "…" | none |
| Seedance 2.0 | Formula + Shot 1: … storyboard without timestamps; {dialogue}, <sound>, (music) | none |
| Seedance 1.5 / 1.0 Pro | Subject + movement + environment + camera + aesthetics + sound; speaker lines | none |
| Seedance Reference | Asset bindings ("Image 1 is …"), summary, shots; edit / extend / keyframe wording | none |
| Kling 3.0 | Subject → action → setting → camera → light → mood; [Shot 1: Wide shot, 3s]; @Image1 references; speaker lines | Short generic list (Kling 3.0 / 2.x nodes; Omni has none) |
| Veo 3.1 | Cinematography + subject + action + context + style; quoted dialogue, SFX: and Ambient noise: lines | Noun list (subtitles, watermark, …) for the node's negative field |
| Grok Imagine Video | One continuous shot, opening image first; @Image1 / @Audio1 references | none |
The guides inside the presets follow each model's official sources:
- Krea 2:
docs/prompting.mdanddocs/expansion.txt - Qwen-Image 2.1: the PE-T2I and PE-I2I rewriter prompts
- Z-Image: the official prompt enhancer
- FLUX: BFL's FLUX.2 prompting guide
- Wan 2.2:
system_prompt.py - Wan 2.7 / 3.0: the Alibaba Model Studio video guide
- MiniMax H3: its own prompt-writing guides
- Seedream and Seedance: the BytePlus ModelArk prompt guides (Seedream 4.0–4.5, Seedream 5.0 pro / flash, Dola Seedream 5.5 tutorial, Seedance 2.5, Seedance 2.0 series, Seedance 1.5 pro)
- GPT Image: OpenAI's image prompting guide and image generation docs
- Nano Banana: Google's Gemini image generation docs and Nano Banana prompting guides
- Grok Imagine: xAI's image prompting guide and video docs
- Flux 3 and FLUX.2 API models: BFL's prompting guides
- Kling 3.0: Kling's prompt guide and multi-shot guide
- Veo 3.1: Google Cloud's Veo prompt guide
For Illustrious, Pony and SDXL they follow the model cards plus established community practice. For Wan 3.0 there is little model-specific guidance yet, so its presets follow the Wan 2.7 guide.
SFW and NSFW presets
Every preset except "Custom system prompt" comes as "· SFW" and "· NSFW", for example "Generation ▸ Krea 2 · SFW" and "Generation ▸ Krea 2 · NSFW". Both use the same model guide and add a content section written for that kind of model:
- · SFW: every person is dressed, with what each one wears and how it fits. Every pose and every interaction (a dance, an embrace, a kiss, a fight, a sport) is described precisely, never only by its name: who touches whom with which body part, the point of contact, the movement, what the hands do and how the bodies react.
- · NSFW: explicit, adults only, with visible mutual consent and plain anatomical words. Every sexual interaction is described step by step, never only by its name: who does what to whom with which body part, the exact point of contact, the movement with direction, depth, pressure and speed, what all hands do and the visible reaction of the bodies. Positions get their common term and their full geometry, the state of undress and body fluids are named, and the framing shows the action.
The section takes the form of the model:
| Models | SFW / NSFW section | |---|---| | Krea 2, Qwen-Image 2.1, Z-Image, FLUX, Flux 3, Seedream, GPT Image, Nano Banana, Grok Imagine Image, SDXL | A still picture: the interaction as one visible moment. With a short length (Seedream, SDXL) the persons, the action and the point of contact come first. | | Illustrious, Pony | Danbooru tags: the rating tag (general / sensitive, rating_safe; explicit, rating_explicit), several precise tags for pose, contact, hands, reaction, undress and fluids, and no tag that marks a minor. Age tags only as the input states them. | | Qwen-Image-Edit 2.1, Seedream Edit | Edit instructions: what is taken off or changed, the resulting pose and contact, and the identity of every person kept. | | Wan 2.2, Wan 2.7, Wan 3.0, Seedance, Kling 3.0, Veo 3.1, Grok Imagine Video | A sequence per shot, in the model's shot format, with rhythm, continuity of undress and, except for the silent Wan 2.2, the sound. | | MiniMax H3 FL2VA, REF2VA | Like the video models, written into the descriptive fields of the H3 format. | | Caption ▸ LoRA training caption, Caption ▸ Describe image | SFW: nudity and sex only in neutral words. NSFW: explicit and precise, only for persons who are clearly adults, and only what the image shows. | | Recast ▸ Swap persons | SFW: explicit parts of the original are rewritten safe for work. NSFW: every explicit detail stays, adapted to the anatomy of the new persons. |
GPT Image, Nano Banana, Grok Imagine Image, Kling 3.0 and Veo 3.1 come as "· SFW" only, and Grok Imagine Video has "· NSFW" only for captions: their APIs refuse explicit content. The other API models (Seedream, Seedance, Flux 3, Wan 3.0, MiniMax H3) have both, but their provider may still filter.
In every section persons are written as "an adult woman" or "an adult man" (outside romantic, swimwear or fitness scenes simply "a woman", "a man" in SFW). An age appears only when your input or a selected person states one ("young", "aged", "in her forties", "35 years old"), word for word and in NSFW still with "adult" ("a young adult woman"); no age is invented. Wan 3.0 also has an example of its own for each variant.
Bodies: every image, edit and video section asks for anatomically sound bodies in a positive way. Every hand, arm and leg gets a clear place or action and belongs to a named person ("her left hand", "his right knee"), poses stay physically possible, and the description of the persons closes with one phrase in the model's form: "Their bodies are natural and anatomically correct, with well-formed hands." for image models, "anatomically correct, well-formed hands" for SDXL, "Their bodies and hands keep natural proportions throughout the motion." for video models, "keep the body proportions and hands natural" for edits, and a placement tag for every hand and leg for Illustrious and Pony (their negative prompts already carry the anatomy tags).
Spoken lines in video prompts appear only when your input quotes them or asks for speech; otherwise the prompt says "No dialogue." Lines you ask for without quoting them are written in English unless you name a language, and voices get no invented age or accent.
The content section replaces the general Adult content and Safe mode rules below. safe on still wins: with an NSFW preset it keeps the result safe for work. Workflows and saved overrides that used a preset without the suffix (for example "Generation ▸ Krea 2") now use its "· SFW" preset; the values in the node stay as they were. Both writer nodes, Grok API and LLM GGUF, use the same presets and rules.
Every target that is written as prose (all image and video models except the tag models Illustrious, Pony and SDXL and the edit instructions) also gets a sentence rule: complete sentences that each end with a period, each making one clear statement about a subject's look, clothing, pose, action, the setting, the light, the camera or the style. Long descriptions are split into several short sentences instead of comma-chained fragments. Fixed labels that a model needs, such as shot labels, timestamps or section names, keep their form. "Caption ▸ Describe image" and "Caption ▸ LoRA training caption" follow the same rule.
Every target guide also ends with an example of a good result. It is marked as a model for form and length only, never for content. Local models in particular follow a concrete example far more reliably than written rules alone.
Inputs
| Input | Meaning |
|---|---|
| text | Your input in any language: an idea, a caption or an edit request. You can type it or connect a string. The output is always English. Only text that should appear in the picture and spoken dialogue stay in their original language. |
| custom_system_prompt | When connected and not empty, it always replaces the preset's system prompt. |
| system | From Prompt Writer · System Prompt Library: a system prompt from the library. In mode replace it is used instead of system_prompt, which is then greyed out and read-only; in mode append it is added as extra binding instructions (see the node). |
| light | Forces a light or mood. free (default): no rule; the preset, a style block or your text decides. daylight: clear, white, natural daylight, no dramatic lighting, no golden hour, no neon, no colour grading; without a style and without a medium in your text the picture is a natural photograph. night: deep night, very dark, lit only by one faint light source (moonlight, or the candle or phone screen your text names). redlight: sensual, erotic red light - indoors a room glowing from red lamps on skin, satin and velvet, outdoors a red-light street at night with red windows, neon and wet pavement. rundown: a worn-down, neglected place in dim, dirty light - indoors peeling wallpaper, stains and a bare bulb or flickering tube, outdoors crumbling facades, graffiti, boarded-up windows and an overcast sky. threatening: a tense, menacing scene - indoors deep shadows, one hard light and narrow spaces, outdoors an empty place at dusk or night with fog and a harsh streetlight. Indoors or outdoors follows the place in your text (indoors if it names none); with sound, the video models also get matching background sounds. Your text always wins, and light never changes the medium: a cartoon stays a cartoon. |
| safe | Off (default): nudity and sexual content are written explicitly and precisely. On: they are only implied. See Adult content below. |
| variation | On (default): with the run's seed the node picks a pose, an interaction, a camera angle, a framing, a place and, for video, a camera move, and the writer uses them wherever your text, the persons and the images leave something open. A language model alone picks the same "random" pose every time; with variation a new seed gives a new scene and the same seed the same one. SFW lists by default, NSFW lists with a "· NSFW" preset and safe off. Not used for "Caption ▸", edit and recast presets. Off: as before 1.7.0. |
| image_1 … image_4 | Optional single images, not batches; only the first image of a batch is used. The model sees each one as "Image N" by its slot number, so an empty slot doesn't shift the numbering. The tooltip explains how each preset uses them. |
| trigger_word | Trigger token for "Caption ▸ LoRA training caption". It replaces {trigger} in the system prompt. |
| negative_prompt | Passed straight to the negative_prompt output. It is not sent to the model. |
| min_words / max_words | Optional length of the result, 0 = off. The tooltip shows the length recommended for the selected preset's target model. When set, the range is binding and overrides the preset's length guidance. Tag lists count each tag as one word; MiniMax H3 formats apply the range to the main description. |
Persons, style blocks and the archive
👤 Persons & styles... opens your library. It is stored in ComfyUI/user/grok_prompt_forge/library.json, so your characters never end up in the node pack or a repository.
| Library entry | Fields | Used by |
|---|---|---|
| Person | Label: shown in the list and the selection boxes, only for your overview, e.g. "Peter with glasses" and "Peter with beard". Name in the prompt: written into every prompt exactly as given, e.g. "P3ter"; with a digit for a letter it works as a trigger, and several entries may share it. Empty = the label is used (entries from before 1.4.0). Gender: male, female or unknown; it lets pronouns and gendered details fit. Trigger (optional): an extra LoRA trigger for special cases, written right after the name when it differs from it. Description: appearance and fixed traits, binding; use the name from the prompt in it. Voice: timbre, pitch, pace, accent. | person_1 … person_6 on the writer nodes or on Prompt Writer · Persons. The voice is used only by the models with audio: MiniMax H3 FL2VA / REF2VA, Wan 2.7 / 3.0, Seedance 1.5 / 2.0 / 2.5, Kling 3.0 / 2.6, Veo 3.1 and Grok Imagine Video. |
| Style block | Text: e.g. a medium (cartoon, oil painting), a camera look or a ban list | style_1, style_2; applied to every result |
-
New persons are filled in for you: type the label (e.g. "Peter") and the dialog suggests the name in the prompt and the trigger ("P3ter": the first a, e, i or o becomes 4, 3, 1 or 0), the gender male and a description that starts with "P3ter is a man". Every suggestion is editable; a field you change yourself is left alone. Renaming the name later also renames it in the description and in a trigger that equals it.
-
On hover: the tooltip of
person_1…person_6shows the selected person's name in the prompt, gender, trigger and description; so does an entry in the dialog's list. -
📥 Add templates in the dialog adds ten fictional template persons, six groups and seventeen style blocks to your library. Labels you already have are never changed. Each template describes only the outer appearance, in two to three detailed English sentences: origin, skin tone, age, height and build in words (image models can't show "1.88 m"), face, eyes and hair. The label is the real name; the name in the prompt (also the trigger) has one digit for a letter.
- Persons (label → name in the prompt): Sean → S3an (Ireland), Rafael → R4fael (Brazil), Sione → S1one (Samoa), Kenji → K3nji (Japan), Arjun → 4rjun (India), Kwame → Kw4me (Ghana), Karim → K4rim (Egypt), Olav → 0lav (Norway), Amara → 4mara (Nigeria) and Jiwoo → J1woo (Korea).
- Groups, each member clearly different from the others and with a name of their own:
- Group of men I: six men of different origins (Russia, Argentina, Senegal, Lakota, Vietnam, Netherlands).
- Group of men II: six extremely fat, unkempt German men.
- Group of men III: six Nigerian men, from extremely fat to very thin.
- Group of men IV: six very fat men with big bellies from different cultures (Turkey, Mexico, Texas, China, Tonga, Greece).
- Group of men V: six young German men in their early twenties, ordinary in appearance.
- Group of women I: four women of different origins and ages.
- Up to 1.7.x the groups were called Group_of_men and Group_of_women. "Add templates" renames them in your library and keeps your own edits; workflows that still select an old name use the renamed group.
- Style blocks: Natural daylight, Cartoon, Oil painting, Line drawing, Watercolour, Pencil sketch, Anime, Manga, Hentai, Comic book, 3D render, Vintage film photo, Van Gogh, Rembrandt, Simpsons, Pixar and GTA VI. Each names its medium and technique with the style's own terms (impasto, chiaroscuro, hatching, screentones, cel shading ...), in positive words only: what the picture is and how it was made, never what it is not - image models are pulled towards every word in a prompt, so even "not realistic" brings realism back. Anime is the colour look of Japanese animation, Manga the inked look of Japanese comics in full colour, like a manga colour page or cover, Hentai the explicit adult anime look with clearly adult characters (with
safeon it is only implied).
-
Groups: a person entry whose description starts with "A group of" is a group in one slot. Its own name is only a label and never appears in the prompt. Instead, every member is introduced by name, and every action is assigned to a member, e.g. "B0ris lifts the crate while M1nh holds the door".
-
Prompt Writer · Persons: chooses the persons outside the writer nodes and passes them to the writer's
personsinput. While that input is connected,person_1…person_6on the writer are greyed out, locked and ignored; disconnect it and they work again with their old values. The slot numbers come from the Persons node, so Person 3 there is Person 3 in the prompt and pairs withimage_3. -
At a glance: a selected person turns its field dark red, a selected style block turns its field dark blue. Fields set to "(none)" look normal. The colour is display only and is not saved in the workflow.
-
Using persons in your text: refer to a selected person by name or as "Person 1"…"Person 4". Selected persons always appear in the result, even if the text doesn't mention them.
- Each person is introduced once as "name, trigger, description". The label is never written.
- After that, every pose, action, gaze and line of dialogue is attributed to a person by name, with no ambiguous "she" or "the woman" when several persons are present.
- Tag models (Pony, Illustrious, SDXL) get the name first, then the trigger, then the description as tags.
-
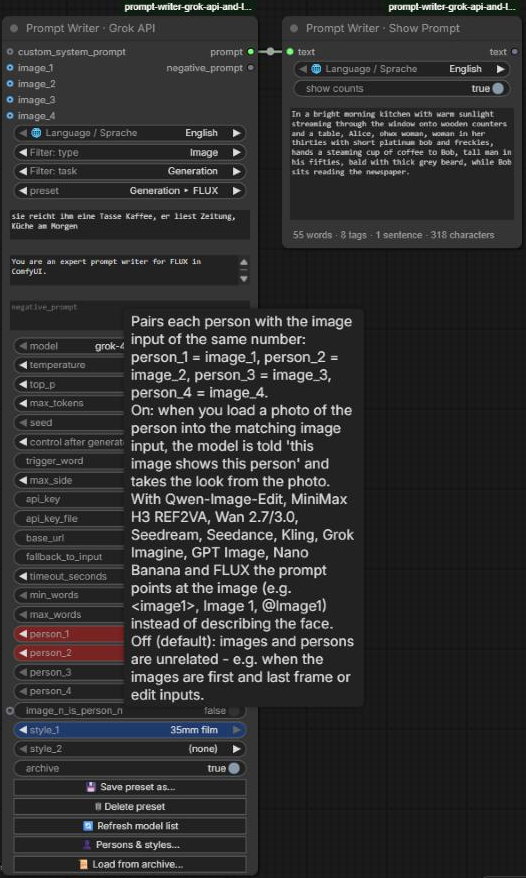
image_n_is_person_n(off by default) pairs each person with the image input of the same number:person_1=image_1,person_2=image_2,person_3=image_3,person_4=image_4. There are only four image inputs, soperson_5andperson_6have no image of their own.- Turn it on and load a photo of the person into the matching image input, and the model takes the look from it.
- With Qwen-Image-Edit (
<imageN>), MiniMax H3 REF2VA (<Picture N>), Wan 2.7 / 3.0, Seedream and Seedance ("Image N"), Kling and Grok Imagine (@ImageN), GPT Image, Nano Banana and FLUX multi-reference, the prompt points at the image instead of describing the face. - Leave it off when the images mean something else, e.g. the first and last frame of a video or the input images of an edit. Workflows saved before 1.2.0 keep the setting they had (it used to be on by default).
-
Export / Import in the dialog moves the library between installs. On import you choose whether names that already exist are replaced or kept.
-
Archive: with
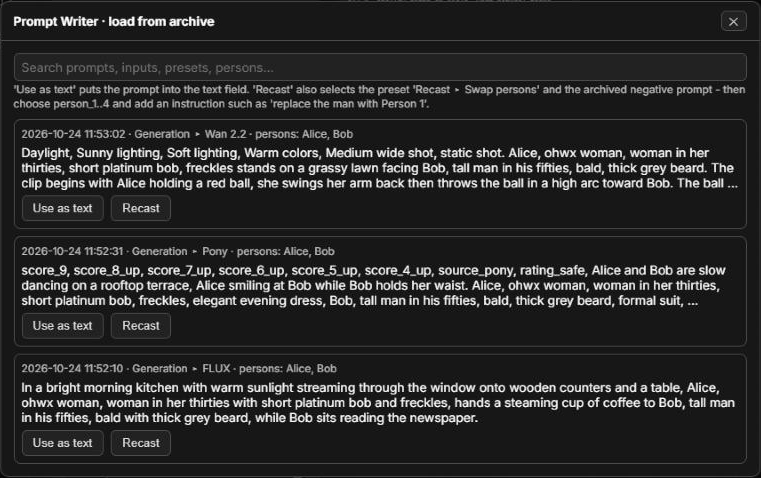
archiveon, every result is appended toComfyUI/user/grok_prompt_forge/archive.jsonltogether with its input, preset, persons and settings. 📜 Load from archive... searches it:- Use as text puts an archived prompt into
text. - Recast also selects the preset "Recast ▸ Swap persons" (· SFW while the node is on an SFW preset, otherwise · NSFW, which keeps every explicit detail) and the archived negative prompt.
Then pick the new person(s) and add an instruction such as "replace the man with Person 1". The action, background, lighting, camera, style and format stay as they are; only the person changes, including pronouns and gendered details.
- Use as text puts an archived prompt into
Rules added to every request
These rules are appended to every system prompt, whether built-in, edited or connected via custom_system_prompt or system. The persons and the selected style blocks are added as binding sections in the same way.
- The user's input is binding. Every explicit wish or instruction in
textis carried out, for example "no people", "night scene" or "write it as one sentence without score tags". If it conflicts with the preset's guidance, the input wins. Only the output format and the English-output rule stay. - Style, when a style block is selected: the prompt opens and closes with the medium and technique ("A rough graphite pencil sketch of ..."), and every element - persons, clothes, objects, background - is described in the language of the style ("his jacket built from thick, swirling strokes of ochre paint"), only in positive words. This overrides the order of the model guide, so a painting or a drawing never turns into a photo.
- Light and mood, as set with
light(not with free, the default). - Adult content (with
safeoff): all persons in nude or sexual content are adults and are described as adults; minors are never sexualised. Everything is written explicitly with plain anatomical words: who does what to whom with which body part, where the bodies touch, who lies, kneels, sits or stands, each person's state of undress, and body fluids by name with where they are and how they look. Framing and camera angle show the action. Tag models get the matching explicit tags, video models the movement and its rhythm. Nothing explicit is added that the input doesn't ask for. - Safe mode (with
safeon): nudity and sexual content are only implied - no visible genitals, no explicit acts, no body fluids. Use it for the API models, which filter adult content anyway. - Presets ending in "· SFW" or "· NSFW" bring their own content section instead of these two rules (see SFW and NSFW presets);
safeon still wins over "· NSFW". - Length, only if
min_wordsormax_wordsis set. - Final answer: the reply is the final result only - the prompt (or edit instruction or caption) itself, in its own format. This also applies to your own and the library's system prompts, even if they ask for headings, settings or tips around the prompt. Should a model still add a label such as "Prompt:" or wrap the prompt in a code block with notes around it, the node keeps only the prompt.
The console logs the word and tag count of each result whenever a range is set. Language models count well but not perfectly, so expect an occasional miss of a few words.
Sampling: temperature and top_p
Every time the model writes a word, it ranks all candidate words by probability and draws one.
- temperature reshapes the dice. Low values (0.1–0.4) almost always pick the top-ranked word, so the output is faithful and repeatable. Use them for caption rewriting and edit instructions. High values (0.7–1.0) give unusual words a real chance, so ideas get expanded in varied ways. Above about 1.3, grammar falls apart.
- top_p removes dice faces. It keeps only the most likely words up to the probability share
pand throws away the rest entirely. Keep it high (0.9–1.0) and steer with temperature. At1.0it is not sent at all.
The preset values follow what official prompt enhancers use:
- Qwen-Image's rewriter: 1.0 / 0.95
- Z-Image: 0.7 / 0.8
- Hunyuan: 0.7 for T2I, 0.1 for edits
- FLUX.2: 0.15
| Task | temperature | top_p | |---|---|---| | Generation ▸ image models | 0.7 – 0.8 | 0.9 – 0.95 | | Generation ▸ video models | 0.75 – 0.8 (H3: 0.6, strict format) | 0.95 | | Generation ▸ Qwen-Image-Edit | 0.3 | off | | Caption ▸ … (faithful rewrite) | 0.2 – 0.4 | off | | LoRA training caption / describe image | 0.2 / 0.3 | off |
What sampling can not fix
Sampling only adds variety at the word level. It cannot stop the model from favouring the same motifs, like golden-hour backdrops or centered poses. If your images still look alike:
- Add a ban list to the system prompt. For example:
Never use: golden hour, neon lights, rain-slicked streets, .... Save the result as your own preset. - Feed randomness in. Put randomized scene ingredients into
text, using wildcard nodes or the Text File Loader withloop_at_end.
seed (cache-breaker)
ComfyUI only re-runs a node when one of its inputs changed. The seed is there to control that.
- randomize: a fresh prompt on every queue run.
- fixed: identical input reuses the cached result. With the Grok API this saves money when rewriting captions.
The Grok API node doesn't send the seed to the API at all. The LLM GGUF node passes it to the model, so fixed also gives the same output for the same input.
Prompt Writer · Grok API
Model
The default model is grok-4.20-0309-reasoning. It's very affordable and has the least censorship of all Grok models. Tested against the API on 2026-10-24:
- It accepts
temperatureandtop_p. - It rejects
presence_penalty,frequency_penaltyandreasoning_effort, so the node has no penalty settings. - It thinks before answering, and the hidden reasoning counts against
max_tokens. An edit instruction took about 3 500 reasoning tokens. The presets therefore use 8192–12288; you only pay for the tokens actually used. - If
max_tokensruns out before any answer is written, the node reports it clearly instead of returning an empty string.
The model dropdown lists every model your key can use with this node. It is loaded from the API at start-up and on 🔄 Refresh model list, and cached in ComfyUI/user/grok_prompt_forge/models.json.
Multi-agent models such as grok-4.20-multi-agent-0309 are left out. The API rejects them on chat completions ("Multi Agent requests are not allowed on chat completions"), which this node uses. They are research models that run several agents in parallel to search and cross-check facts, so they bring nothing for prompt writing.
API key setup
Get a key at https://console.x.ai. The key is looked up in this order:
-
api_keywidget. Not recommended, because the key would be saved inside exported workflows. -
Environment variable
XAI_API_KEY. -
Key file (recommended):
grok_api_key.txt, containing only the key. It is searched for in:- the ComfyUI root (next to
main.py) - the portable root (next to
run_nvidia_gpu.bat) - this pack's folder
The file must be named exactly
grok_api_key.txt. Windows hides known file extensions by default, so a file you name "grok_api_key.txt" in Explorer can silently end up asgrok_api_key.txt.txt, and the node won't find it. To check, turn on View → Show → File name extensions in Explorer. - the ComfyUI root (next to
Never share workflows or screenshots containing your key.
Prompt Writer · LLM GGUF
The node works like the Grok API node; only the model fields differ.
| Field | Meaning |
|---|---|
| model | huihui Qwen3.8-27B abliterated (IQ2_S 8.4 GB … Q5_K 19.5 GB) or HauhauCS Qwen3.8-27B Aggressive (IQ2_M 10.3 GB … Q5_K_P 20.2 GB). ✓ = already downloaded. Otherwise the model and its vision projector are downloaded into ComfyUI/models/LLM_gguf/ on the first run. |
| thinking | The model thinks before answering: better prompts, slower. The thinking is never part of the output. |
| unload_after_run | On by default: the model leaves VRAM after every run, so your image or video model has room again. Before loading, the node also asks ComfyUI to unload its own models. |
| context_length | Working memory for system prompt, images, thinking and answer. 32768 suits all presets. |
| gpu_layers | -1 = automatic (recommended). Lower it for cards that are too small for the whole model. |
| top_k | 20, as Qwen recommends. |
On an RTX 5090 with huihui Q4_K, a FLUX prompt takes about 20 s including loading the model.
docs/LOCAL_GGUF.md covers everything you need:
- installing llama-cpp-python with CUDA in ComfyUI Portable, and which build fits your GPU and driver
- which model fits 12, 16, 24 or 32 GB of VRAM
- troubleshooting
Installation (Windows, Portable ComfyUI)
- Clone this repository into
ComfyUI\custom_nodes\. From thecustom_nodesfolder:git clone https://github.com/Slartibart23/prompt-writer-grok-api-and-llm-gguf - Install the dependencies; they are usually already present. From the portable root:
python_embeded\python.exe -m pip install requests Pillow numpy huggingface_hub - Restart ComfyUI. The nodes appear under Prompt Writer.
- Optional, for Prompt Writer · LLM GGUF: install llama-cpp-python with CUDA. Follow docs/LOCAL_GGUF.md: it explains which build fits your GPU and why to install it with
--no-deps. The Grok API node doesn't need it.
New fields are added at the end of a node, so saved workflows keep their values in place after an update. The one exception: since 1.8.0 person_5 and person_6 sit right below person_4; the node moves their values in workflows saved with an older version when the workflow is loaded. See CHANGELOG.md for what changed.
Coming from comfyui-grok-prompt-forge
This pack replaces comfyui-grok-prompt-forge.
- Delete the old folder
ComfyUI\custom_nodes\comfyui-grok-prompt-forge, then install this pack. The two must not be installed together, because they register the same nodes. - Workflows: Grok Prompt Forge, Local Prompt Forge (GGUF), Grok Show Prompt and the two loaders keep their internal IDs. Saved workflows load unchanged; only the names shown on the nodes are new.
- Your data: presets, persons, style blocks and the archive stay where they are, in
ComfyUI/user/grok_prompt_forge/, and are used by the new pack right away. - Removed nodes: the old Grok Text Refine and Grok Vision Caption nodes are gone. Replace them with Prompt Writer · Grok API: use a "Caption ▸ …" preset or "Custom system prompt" for text, and "Caption ▸ Describe image" for images.
Tests
Offline tests need no key, network, GPU or ComfyUI. Run them from the pack folder:
..\..\..\python_embeded\python.exe -m unittest discover -s tests -v
Notes
- The xAI API is a paid service billed per token. A prompt costs a fraction of a cent; images and long reasoning cost a bit more. The LLM GGUF node costs nothing after the download.
docs/NOTE_settings_guide.txtis a plain-text version of the sampling guide, sized to paste into a ComfyUI Note node.- If the model fails,
fallback_to_inputpasses the input text through so batch runs keep going. Check the console log for the reason. - Your presets, persons, style blocks, archive and model cache live in
ComfyUI/user/grok_prompt_forge/. Nothing personal is ever written into this node pack's folder.
License
MIT