
Eric_Krea2
Self-contained ComfyUI custom nodes for Krea 2 (Raw/Turbo): text-to-image, multi-stage high-res, Control-LoRA, style reference, inpaint/outpaint, edits, NAG/NegPiP negative guidance, native quantized compute, DeGrid, LoRA stack/search, recipe presets, and a parameter-sweep system for characterising checkpoints, samplers and LoRAs.
Nodes (39)
One LoRA, three strengths — steer composition in Stage 1, detail in Stage 3
The Krea 2 loader with a save button and a box of spare parts
Depth and pose control for Krea 2, and it's a LoRA, not a second model
A free 2x resolution boost that costs zero sampling time
Swap Krea 2's 'plastic skin' VAE for natural grain — without upscaling
Remove the 2-pixel lattice before you sharpen it into fabric
What's actually inside that LoRA, before you trust it
Recolor, restyle and re-pose Krea 2 images with a sentence
Eight steps and done — the simple Krea 2 text-to-image node
Resize the picture before it exists — no VAE round-trip, no detail loss
The escape hatch that hands Krea 2 latents to the rest of ComfyUI
The one node that decides whether Krea 2 runs fast or melts your GPU
Type 'moody forest, cinematic' and get a paragraph Krea 2 can actually work with
Stitch the whole recipe into one string, so your PNG remembers everything
The ten-slot LoRA stack where every slot knows which stage it's on
The node that makes Krea 2 Raw sing at 4k — three stages, every knob exposed
Same three-stage engine, now with a save button and a sweep input
Real negatives on Turbo, without paying for CFG
Inpaint and outpaint where the pixels you keep actually stay put
The one node that guarantees the rest of the image didn't move
The prompt builder that writes the way Krea 2 actually wants
The pixel-level edit path — but only if you've got the right LoRA loaded
Tell the Ultra node what size the image should be — or let the source image tell it
Save the latent, not the pretty picture — when debugging needs receipts
Re-run yesterday's exact image — settings, LoRAs, and all
Where sampler tuning actually happens — per-stage sigma curves with a live preview
Borrow the palette, not the picture — no LoRA training
It won't pick your favourite — it'll tell you why it picked the other one
One queue item, a whole grid of samplers and schedules
Turn a sweep winner into a saved preset before it gets away
The reset button for your LoRA stack
Reclaim VRAM without restarting ComfyUI
A 2× decoder that's secretly a quality pass
Decode to pixels — and why you might swap the VAE first
The img2img entry ticket
Prompt from a picture — the way Krea 2 was trained to take it
Eric_Krea2
Self-contained ComfyUI custom nodes for Krea 2 - Krea AI's open-weight, from-scratch image model (single-stream MMDiT, flow matching, Qwen3-VL conditioning). Includes text-to-image, progressive multi-stage high-res generation, a 2× upscale-decode trick, natural-language prompt tooling, and an image-to-image suite (control, style, inpaint/outpaint, instruction edits) plus negative guidance that works on Turbo.
No dependency on any other node pack.
Why Eric_Krea2 - key advantages
-
Real diffusers model, not a reimplementation. Loads the genuine Hugging Face
Krea2Pipelinecomponents (single-stream MMDiT, flow matching, Qwen3-VL conditioning) straight from weights, so you inherit upstream behaviour, fixes and the correct trained prompt templates. Sampling runs on this pack's own flow-matching solvers in the same shifted sigma space as the pipeline (euler+linear+ fixed shift reproduces the official sampler). -
Easy, honest multi-stage high-res. Up to 3 progressive stages in one node, with per-stage samplers, schedules, guidance and re-noise windows, plus an on-node resolution-chain readout so you always see the real S1→S2→S3→decode sizes.
-
First-class img2img. A VAE Encode node feeds an
init_latentinput; denoise strength is just the stage's re-noise step window - no separate float to guess. -
Reference-image style/content grounding (Vision Prompt). Ground conditioning in 1-3 reference images through Krea2's own Qwen3-VL vision path - a "prompt from a picture" effect (semantic style/content grounding, not pixel editing) with no training and none of the silently-discarded-reference pitfalls of the common community pattern. Composes freely with img2img for structure + content on separate channels.
-
Presets everywhere. Named JSON presets per section (loader / LoRA / Ultra / sigmas) with a ★ Save button, a Merge Settings node, and Settings-from-Image for one-click reproduction of a saved image's recipe.
-
LoRA with per-stage settings + presets. Apply / unload / diagnose plus a Multi-LoRA Stack - both with per-stage weights (S1/S2/S3), so a LoRA can steer composition harder than final detail (or vice-versa) within a single multi-stage run, and both with named-preset save/load (★ Save) for one-click recall.
-
Reference-latent edit pathway. With an edit-trained LoRA loaded, a Reference Latents node feeds VAE-encoded reference images through the ai-toolkit "index_timestep_zero" method - real pixel/structure conditioning (distinct from Vision Prompt's semantic grounding), reimplemented against our diffusers transformer.
-
Custom flow-matching samplers, no external solver.
euler,res_2m,res_2s,deis_3m,abnorsett_3m,abnorsett_4m,lawson4_4s,etdrk4_4s,er_sde,rk6_7s,lcmand thelcm_hybrid/lcm_hybrid2hybrids, selectable per stage, with built-in schedules, your own saved sigma curves anddetail_biascontrol. See docs/SAMPLERS.md. -
A sweep system for characterising checkpoints. One Sweep Plan node runs grids or hand-written lists of samplers, schedules, steps, curves, LoRAs, prompts and seeds, and writes contact sheets, spreadsheets and per-cell PNGs that reproduce exactly. See docs/SWEEPS.md.
-
Two high-res strategies for two checkpoints. Turbo → fast 4k via the 2× upscale-decode; Raw → controlled multi-stage re-denoise - plus optional downsample "quality-pass" VAE modes that are usually cleaner than the Wan 2.1 VAE at the same size.
-
A full image-to-image suite on one node. Control-LoRA ("ControlNet" depth/pose), training-free style transfer, inpaint/outpaint with the AnyPaint adapter, and instruction/identity editing with the Krea 2 Identity Edit LoRA - each a small builder node that plugs into a socket on Multi-Stage Ultra, with per-stage strengths, so the same multi-stage high-res engine serves every task.
-
Negative prompts that work on Turbo. NAG (Normalized Attention Guidance) and NegPiP (
(phrase:-1)in the prompt) give a distilled checkpoint real negatives at guidance 0 - no second CFG pass. -
Native quantized compute. Run INT8-ConvRot / MXFP8 / NVFP4 / fp8 checkpoints on their own tensor-core kernels instead of dequantizing to bf16: ~1.45x faster and ~12 GB less VRAM at 3 MP, LoRAs included. Opt-in; bf16 stays the default.
-
Correctness first. A same-seed A/B found and fixed a diffusers
flash_varlenbug that silently dropped the bottom rows of every Krea 2 image (the "bottom band"); model switches no longer leave the previous model resident in VRAM.
Latest changes (v1.7.0, November 2026)
- Docs reorganised. This README is now the overview; the deep material lives in docs/. The full change history moved to docs/WHATS_NEW.md.
- New node: Eric Krea2 Hybrid Sigma Handoff - hybrid handoff by sigma instead of step count,
an SDE band per stage, and the churn form (
rfis now the default). - Checkpoint sweeps: new Eric Krea2 Sweep Checkpoints node - compare several Turbo checkpoints in one sweep folder and one report.
- Trajectory probe, LoRA picks by creator / one pick per prompt /
#randomword options in the Sweep Plan, and anegpip_negativefield on the Negative Guidance node. - Sweeps: a full guide to hand-written
comboscells in docs/SWEEPS.md. - The wet effect - what causes it and how to control it.
Requirements
These nodes drive the genuine Hugging Face Krea2Pipeline directly (see
key advantages); the only hard requirement is a
diffusers/transformers build new enough to expose it.
-
A diffusers build that includes
Krea2Pipeline(merged after0.39.0.dev0):python_embeded\python.exe -m pip install --upgrade --force-reinstall --no-deps git+https://github.com/huggingface/diffusers.gitThe version string stays
0.39.0.dev0, so--force-reinstallis required to pull the newer commit. -
A
transformersnew enough to provideQwen3VLModel. -
Krea 2 weights in diffusers layout (e.g.
H:\Training\Krea-2-RawandH:\Training\Krea-2-Turbo). -
Optional, recommended on Blackwell: FlashAttention and/or SageAttention for the faster
attention_backendpaths. Kernel bench on an RTX PRO 5000 (sm120, Krea 2 shapes, 2026-10-08): flash-attn 2 = baseline; SageAttention 2sageattn(int8 QK, fp8 PV) 1.6-1.8x faster per attention call with ~4% relative error (cos 0.9992); its Triton varlen kernel (whatattention_backend=sagepicks first) only 1.13-1.17x; xformers and cuDNN SDPA = flash. The dense kernel is thesage_fp8choice (last in the list). End to end on Turbo, 8 steps: -4-6% step time at 1.5 MP, -9-12% at 3 MP, -19% at 8.4 MP (10.2 -> 8.3 s/step). Images are equally clean (text, skin, frost detail checked at 1:1) but not seed-identical to flash - the small per-call error steers the trajectory, so the same seed gives a sibling image, sometimes a different framing. Edit / NAG / ref_boost runs still use flash for their split attention. -
Optional: the spacepxl Wan 2× upscale VAE (auto-downloaded on first use).
-
Optional:
flash-attn(2.8+) - also used by the edit / NAG / ref_boost attention core (falls back to an exact but slower math path without it). -
Optional: ComfyUI's
comfy_kitchen(ships with recent ComfyUI) - needed for MXFP8 / NVFP4 / W4A4 / W4A8 / W6A8 checkpoints and forcompute = native. -
Optional, per feature: Control-LoRA, AnyPaint and Identity Edit LoRA weights (see each section).
Example workflow
A single, multi-purpose graph lives in workflows/. Drag
example-workflow.png onto the ComfyUI canvas (the graph is embedded in the
PNG metadata) to load the whole pipeline at once - loaders, txt2img, img2img,
Vision Prompt, per-stage sampling, and the metadata-aware save. Flip parts on/off
with group bypass (Ctrl+B) instead of juggling separate workflows. See
workflows/README.md for the group-by-group breakdown.
Nodes
Core generation
| Node | Does |
|------|------|
| Eric Krea2 Loader | Loads Krea2Pipeline (Raw or Turbo), applies attention_backend, caches in VRAM. Auto-detects is_distilled. Preset dropdown. |
| Eric Krea2 Generate | Text-to-image. Emits IMAGE + a chainable KREA2_LATENT. auto_settings picks 8/0 for Turbo, 28/4.5 for Raw. |
| Eric Krea2 Multi-Stage Ultra (res) | Up to 3-stage progressive high-res with the custom RES/DEIS samplers, per-stage schedules, img2img init_latent, an optional ref_latents edit input, and width/height overrides. Sockets for control, style, paint, edit and negative guidance; degrid for the VAE lattice. Best on Raw for multi-stage re-denoise. |
| Eric Krea2 Multi-Stage Ultra V2 (presets) | Preset-driven variant of the Ultra node - serialises every widget (incl. sigmas, width/height) into one reproducible recipe. |
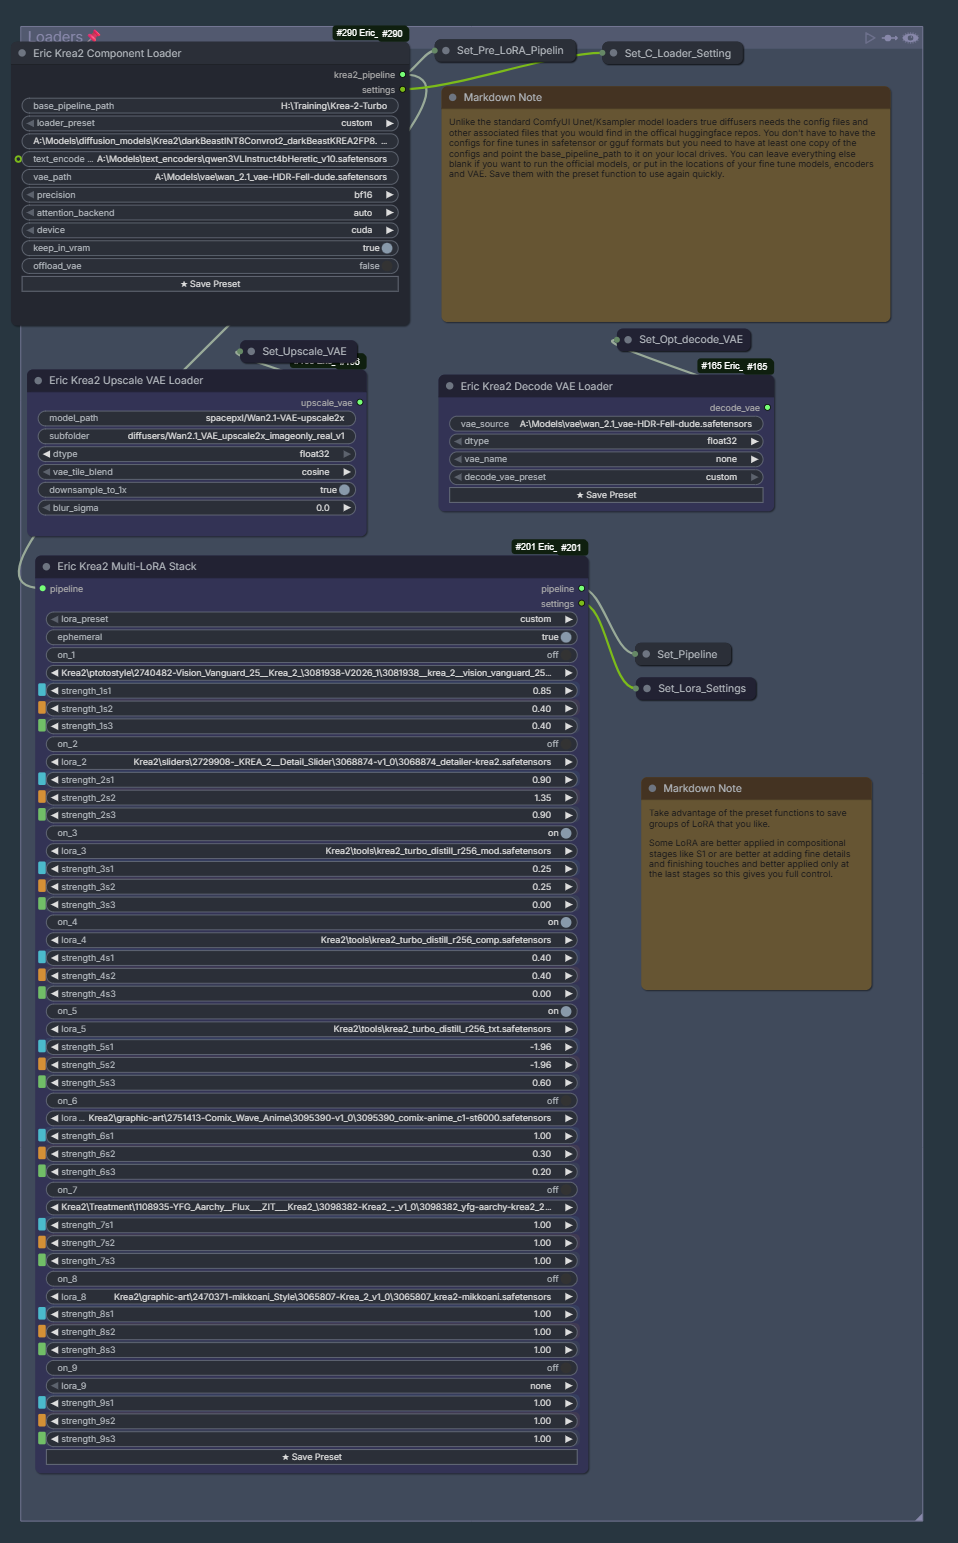
The loader group - the Component Loader (with loader_preset), the Upscale and Decode VAE loaders, and the growable Multi-LoRA Stack with per-stage strengths. Each carries its own ★ Save Preset button.
Sampling & scheduling
| Node | Does |
|------|------|
| Eric Krea2 Sigmas | Per-stage schedule overrides (S1/S2/S3): curve, detail_bias, Beta α/β. Emits a KREA2_SIGMAS bundle the Ultra nodes fold in. |
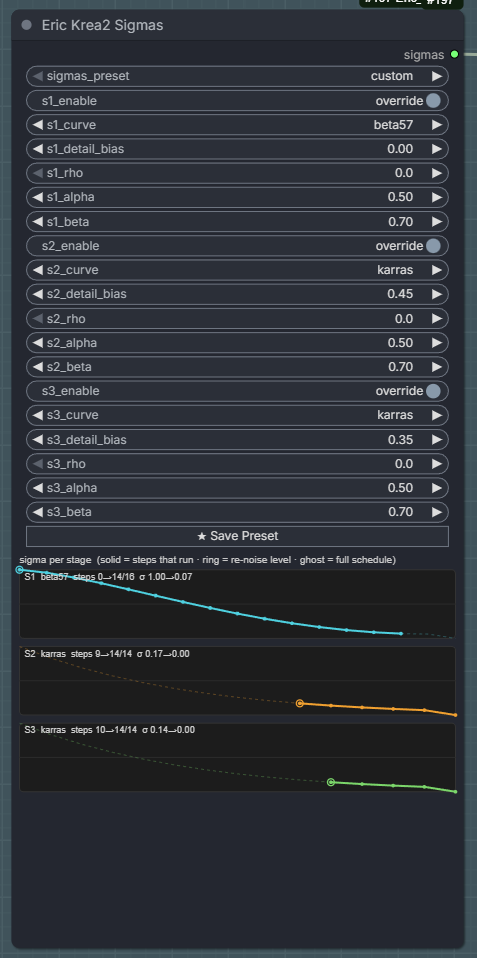
The Sigmas node: per-stage curve / detail_bias / Beta α-β overrides with a live sigma preview per stage (solid = steps that run, ring = re-noise level, ghost = full schedule).
Samplers (per stage, on the Ultra node): euler, res_2m, res_2s, deis_3m,
abnorsett_3m, abnorsett_4m, lawson4_4s, etdrk4_4s, er_sde,
rk6_7s, lcm, lcm_hybrid, lcm_hybrid2.
Schedules: linear, balanced, karras, beta57, beta,
bong_tangent, exponential, linear_quadratic, simple
(= ComfyUI's uniform-in-sigma scheduler; alias of linear here).
See Samplers & schedules.
Sweeping & characterization
- Eric Krea2 Sweep Plan - builds a
KREA2_SWEEPplan (grid axes or JSON-lines combos, stage scoping, quick-screen mode, output folder, hard combo cap, LoRA bake-offs / stacks with random picks,run_notes). Wire into Ultra V2'ssweepinput. - Eric Krea2 Sweep Checkpoints - tick several Turbo checkpoints in a check-box list and wire it into the Sweep Plan: every cell runs on each one, into one folder and one report (docs/SWEEPS.md).
- Eric Krea2 Sweep → Preset - promotes any cell of a finished sweep's
manifest into
ultra_presets.json, tagged with the checkpoint name. See Parameter sweeps.
img2img, resolution & latents
| Node | Does |
|------|------|
| Eric Krea2 VAE Encode | Encodes an IMAGE → KREA2_LATENT (the img2img primitive). |
| Eric Krea2 Reference Latents (Edit) | VAE-encodes 1-3 reference images → KREA2_REF_LATENTS for the Ultra (res) node's ref_latents input (ai-toolkit "index_timestep_zero" edit method). Needs an edit-trained LoRA - without one the base model does not ignore the reference tokens, they corrupt the image into a blocky mosaic. See Reference Latents. |
| Eric Krea2 Resolution | Size from aspect_ratio + megapixels or a source image → width/height/dims + a blank KREA2_LATENT (noise or zeros). |
| Eric Krea2 Latent Resize | Resize a KREA2_LATENT in latent space (bislerp, no VAE round-trip): scale / dimensions / megapixels. |
| Eric Krea2 Latent → ComfyUI LATENT | Bridge a KREA2_LATENT to a stock ComfyUI LATENT. |
Image-to-image: control, style, paint & edit
Each builds a bundle for one socket on Multi-Stage Ultra (all sockets were appended - saved workflows are untouched). Nothing loads or runs in these nodes; Ultra installs the runtime for one generation and removes it afterwards (cancel-safe).
| Node | Ultra socket | Does |
|------|--------------|------|
| Eric Krea2 Control (Depth/Pose ControlNet-LoRA) | control | Control image + Control-LoRA checkpoint + per-stage strengths (S1 1.0 / S2 0.5 / S3 0). See Control. |
| Eric Krea2 Style Reference (training-free) | style | Style image + recommended / custom preset + per-stage multipliers (S1 only by default). See Style Reference. |
| Eric Krea2 Paint (inpaint / outpaint) | paint | Source + mask and/or outpaint padding, adapter (anypaint / outpaint / none), per-stage restore + adapter switches. Outputs the bundle, a vlm_image for Vision Prompt, a canvas preview and the generated mask. See Inpaint / outpaint. |
| Eric Krea2 Paint Composite | - | Optional pixel-exact paste-back of the source outside the mask with a feathered edge. |
| Eric Krea2 Edit | edit | Source image (+ optional second reference), edit instruction, fit_mode, ref_boost / ref_boost_a (+ mask), grounding_px, size_from, ground_negative. See Edits. |
| Eric Krea2 Negative Guidance | guidance | NAG (own negative text, phi / tau / alpha, stages, sigma window) and NegPiP (mode, strength, block range, text-fusion option). See Negative guidance. |
Which sockets combine (one run):
| | control | style | paint | edit | guidance | ref_latents | |---|---|---|---|---|---|---| | control | - | yes | yes | yes | yes | yes* | | style | yes | - | no | no | skipped | no | | paint | yes | no | - | no | skipped | no | | edit | yes | no | no | - | yes | no | | guidance | yes | skipped | skipped | yes | - | skipped | | ref_latents | yes* | no | no | no | skipped | - |
"no" raises a clear error (both wrap the transformer forward); "skipped" runs the other one and prints that guidance was ignored.
Control with edit or ref_latents: the control hint is applied to the target image tokens only; reference tokens bypass the Control-LoRA (before 2026-10-08 control was silently dropped whenever reference tokens were present). *control + ref_latents is verified to apply control on every step; a full visual run with the edit LoRA at 1.5 MP spilled VRAM on a 48 GB card shared with displays, so try 1 MP first.
Decode
| Node | Does |
|------|------|
| Eric Krea2 Upscale VAE Loader | Loads the spacepxl Wan 2× upscale decoder → UPSCALE_VAE. Optional downsample_to_1x + blur_sigma: decode at 2× then Lanczos-downsample back to native size - a supersampling-style quality pass instead of a literal resolution gain. Travels with the loaded VAE into every consumer (see Upscale VAE: modes & precedence). |
| Eric Krea2 Decode VAE Loader | Loads a plain decode VAE. |
| Eric Krea2 Upscale Decode (2×) | Decodes a KREA2_LATENT via the upscale VAE (no re-denoise). Resolution and any downsample/blur are whatever the loaded UPSCALE_VAE was configured with. |
| Eric Krea2 VAE Decode | Plain 1× decode of a KREA2_LATENT. |
| Eric Krea2 DeGrid (VAE grid remover) | Removes the VAE's 2-pixel lattice from any image (auto-calibrated notch, untouched when clean) + removed-grid preview and report. Both decode nodes also gained a degrid toggle. See DeGrid. |
Presets, LoRA & utilities
| Node | Does |
|------|------|
| Eric Krea2 Merge Settings | Merges section recipe strings into one KREA2_SETTINGS (dicts updated, lora lists concatenated). |
| Eric Krea2 Settings from Image | Reads an image's embedded generation settings back into a KREA2_SETTINGS recipe. |
| Eric Krea2 Component Loader | Loads pipeline components (base folder + optional single-file transformer / VAE / text encoder) with a preset dropdown. Reads bf16, GGUF, fp8, INT8, INT8-ConvRot, MXFP8, NVFP4, ConvRot-W4A4, W4A8, W6A8 (formats); compute = bf16 or native quantized kernels (native compute); VAE tiling controls. |
| Eric Krea2 Apply LoRA / Unload LoRA / Diagnose LoRA | Apply, cleanly remove, and inspect LoRA adapters on the cached pipeline. Apply LoRA supports per-stage weights (per_stage_weights + weight_s1/weight_s2/weight_s3) so a LoRA's strength can differ across S1/S2/S3 in a multi-stage run, plus a preset dropdown (apply_lora_preset + ★ Save). |
| Eric Krea2 Multi-LoRA Stack | Stack several LoRAs in one growable node - each slot has per-stage weights (strength_Ns1/s2/s3 for S1/S2/S3) and an on/off toggle, plus a shared ephemeral switch and a preset dropdown (lora_preset + ★ Save). Unused rows auto-hide until needed. Click the middle of a LoRA dropdown for the 🔍 search popup (also on Apply / Diagnose LoRA); optional suggestions socket for the LoRA Suggester. |
| Eric Krea2 Prompt LoRA Tags | Reads <lora:name:weight> tags out of a prompt, outputs the prompt without them plus a LoRA list for the Multi-LoRA Stack's suggestions socket (with trigger words). See Prompt LoRA tags. |
| Eric Krea2 Unload Models | Free VRAM on demand. |
| Eric Krea2 Save Latent (debug) | Save/inspect a packed latent for debugging. |
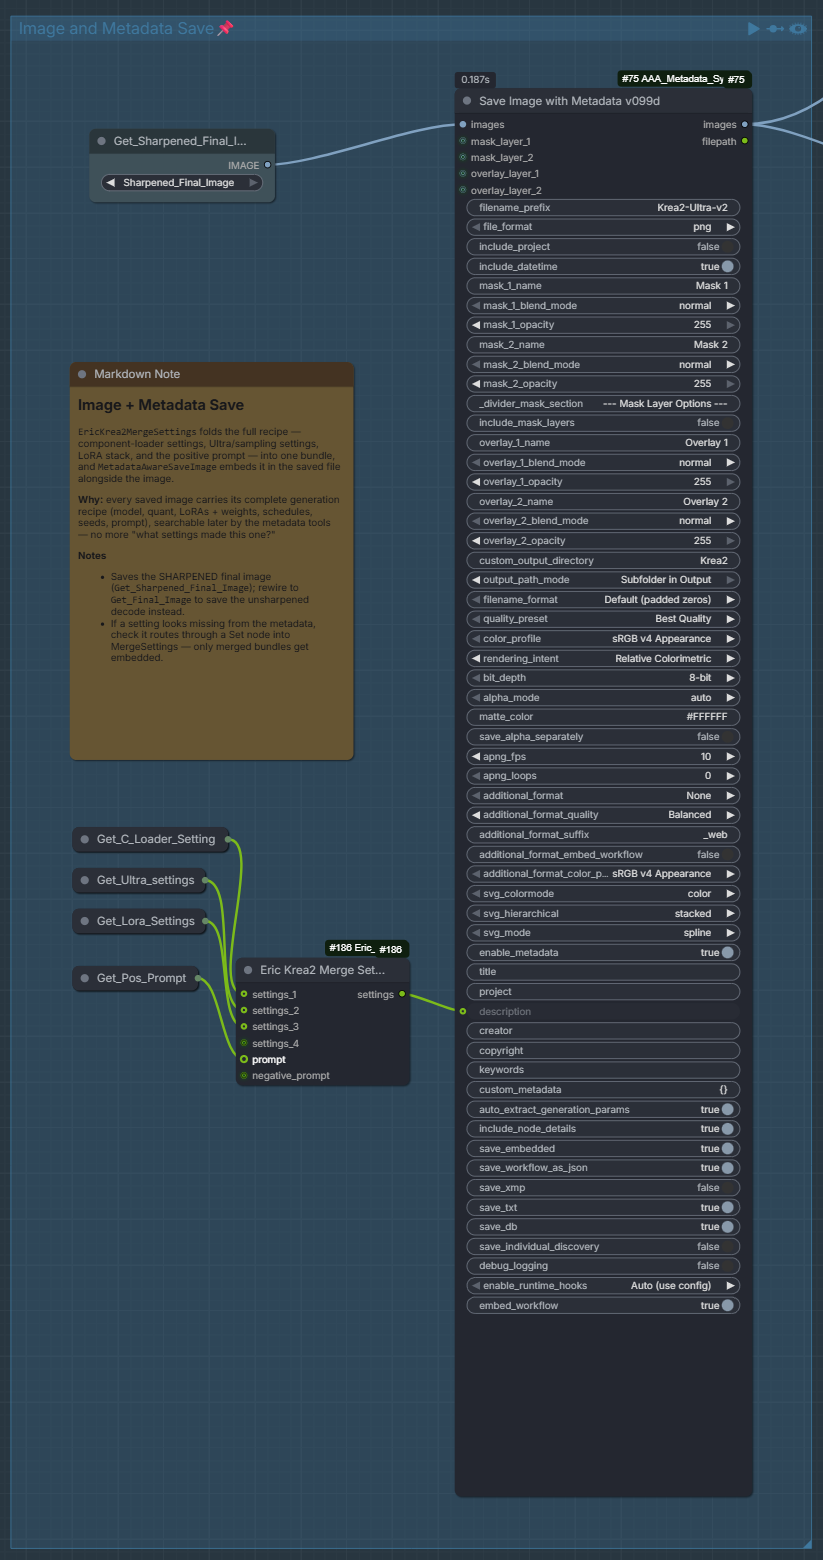
Reproducibility: Merge Settings folds the loader + Ultra + LoRA + prompt recipes into one bundle that gets embedded in the saved PNG - readable back later via Settings from Image.
Prompting
| Node | Does |
|------|------|
| Eric Krea2 Prompt | Assembles structured fields into a dense, comma-joined natural-language prompt; quotes text-to-render. |
| Eric Krea2 Magic Prompt | Expands a short prompt via a local LLM (LM Studio / Ollama / any OpenAI-compatible endpoint). |
| Eric Krea2 Vision Prompt | Grounds conditioning in 1-3 reference images via Krea2's own Qwen3-VL vision path, using Krea2's trained descriptor template (not the generic Qwen-Image-Edit template). Emits KREA2_CONDITIONING → Ultra's prompt_conditioning input. See Vision Prompt below. |
The wet effect (glossy skin, over-pronounced texture)
Krea 2 Turbo's best-known artifact. Skin looks wet, oily or glossy; sweat beads, droplets and wet ground appear that nobody asked for, sometimes skin that looks smeared with jam. The same over-development hits other fine texture too: pores, freckles, and speckle on walls and other smooth surfaces get pushed too far. It is worst on close-up portraits, depends on the image, and varies between fine-tuned checkpoints.
Why it happens. Fine-tuner Alel_AI (Kreamania) attributes it to the Turbo base learning, late in training, to tie skin to a glossy look, which then spreads through the attention layers. Our own working explanation - consistent with what we see but not proven - is over-development: Turbo is distilled to finish in few steps, and every solver step or noise injection beyond what the image needs keeps sharpening fine, high-frequency texture at low sigma. On skin that reads as specular highlights. Both point to the same rule: don't over-develop.
What makes it worse (field observations, Nov 2026):
- Shift mu too low for the image size.
distilled_shift = fixed, or a low manual mu, keeps mu at 1.15, which suits images up to about 2 MP. At 3 MP and above it leaves too many steps at low sigma, where fine texture gets overworked: lots of detail, and the wet look far more often. - More steps than the image needs to resolve - with every sampler and schedule, at every stage.
- The lcm hybrids at middling splits. It is usually better when the lcm part is very short (about 2 of 8 steps) or long (about 5 of 8) - see the lcm hybrids.
- Steep sigma curves on a Stage 2 refine.
- Close-ups of faces, and some fine-tunes more than others.
What helps, roughly cheapest first:
- Match shift mu to the size -
distilled_shift = resolution, the default since v1.7. In a mu sweep (Nov 2026, NAG and NegPiP off) the visually best Stage 1 mu was ~1.3 at 2 MP, 1.75 at 3 MP and ~2.1 at 4 MP, which is whatresolutioncomputes (1.30 / 1.71 / 2.13). For a refine stage the best was a little lower: 2.1 for a 4.5 MP Stage 2, whereresolutiongives 2.33 - set it withdistilled_shift = manual. Going below these is a deliberate trade: more crunch and detail, and more of the wet look. Euler on Stage 1 ignores mu. - Stop at the step count where the image resolves. Sweep
stepsper sampler rather than assuming more is better (docs/SWEEPS.md). - Adjust the hybrid split (
s1_hybrid_steps, or the Hybrid Sigma Handoff node) and use a gentler curve on Stage 2. - NAG - the most effective fix in our testing, at its default settings. On the Negative
Guidance node put the wet concepts in
nag_negative, e.g.wet skin, glossy skin, oily sheen, sweat, water droplets, dripping. Costs about +23% per step. - NegPiP - the same idea through
negpip_negative, at almost no cost. Use different concepts from NAG; the same concept in both over-suppresses. - A wetness slider LoRA at negative strength.
- Counter-words in the prompt (Alel_AI's approach): describe the surface you want - matte skin, dry complexion, natural skin texture, soft diffuse lighting, non-glossy, powdery finish.
Prompt weights do nothing here. Krea 2's conditioning has no prompt weighting, so
(matte skin:1.3) is not a weight in these nodes: with NegPiP on, positive-weight groups are
stripped (with a console warning); with it off, the brackets and number reach the text encoder as
plain text. Write the words plainly.
Settings for NAG and NegPiP: docs/NEGATIVE_GUIDANCE.md.
Documentation
| Page | What's in it |
|---|---|
| docs/SWEEPS.md | Sweep guide: setting up a sweep, LoRA picks, hand-written combos cells, reading the results |
| docs/SWEEPS_REFERENCE.md | Full sweep reference: every field, scoring, auto-pick, folder scoring, presets |
| docs/SAMPLERS.md | Samplers and schedules, warm-up and accuracy, trajectory vs churn, the lcm hybrids, the pairing guide, SDE band and churn form, field-tested recipes |
| docs/HIGH_RES.md | The two high-res strategies, upscale VAE modes, inter-stage renorm, turbo guidance and the negative prompt |
| docs/IMAGE_TO_IMAGE.md | img2img, Vision Prompt, reference latents, Control-LoRA, style reference, inpaint/outpaint, edits |
| docs/NEGATIVE_GUIDANCE.md | NAG and NegPiP on Turbo, and how to tune them |
| docs/LORAS.md | LoRA search and suggestions, prompt LoRA tags, trigger words on base vs fine-tunes |
| docs/MODELS_AND_QUANT.md | Native quantized compute, the checkpoint formats the loader reads, DeGrid |
| docs/WHATS_NEW.md | The full change history by month |
Notes
- Raw vs Turbo: Raw is the undistilled base - train LoRAs on Raw, run on Turbo. Raw is the right choice for multi-stage re-denoise; Turbo for the fast decode path.
- Shared VAE: Krea 2 uses
AutoencoderKLQwenImage(16-channel, f8), identical to Qwen-Image and Wan2.1 - which is why the spacepxl 2× decoder is a drop-in. - Prompting: Krea 2 wants natural language (not JSON/tags). Long, dense
visual/material/camera descriptions work best; quote words to render as text.
For best expander fidelity, download Krea's
expansion.txtand point the Magic Prompt node'ssystem_prompt_pathat it. - Attention is mask-safe (Oct 2026). diffusers'
flash_varlenbackend assumes the valid keys are a prefix; Krea 2 pads text in the middle of[text | image], so withattention_backend=autoevery generation attended to padding and dropped the bottom image rows (the bottom bandcrop_bottomwas hiding, plus weaker prompt adherence). All Krea 2 attention now drops padded keys explicitly before the kernel - same speed as before, matches SDPA. Existing seeds render slightly differently (correctly to the edge);crop_bottomis no longer needed - it now defaults to 0 andcrop_overgento off, and the shipped Ultra presets were reset to match (saved workflows keep whatever they stored). Side effect worth knowing: the old path diluted every prompt with ~400 padding tokens, so the prompt (and text-side LoRAs) now act at full strength - same image quality, noticeably stronger prompt / style adherence (e.g. a style that implies nudes now gets them more often). For A/B comparisons,set ERIC_KREA2_MASK_SAFE=0before ComfyUI starts restores the old behaviour (console prints a DIAGNOSTIC line; usecrop_bottom). - Prompt length: 507 tokens max. Krea 2 encodes a fixed 512-token text budget (5 go to the
chat template); diffusers cuts anything longer silently. The Ultra now prints
prompt: N/507 tokensevery run and a warning with the dropped words when a prompt overflows - keep LLM-expanded prompts under ~380 English words. (Vision Prompt checks its own budget and errors instead.) Trigger words are protected: withadd_triggerson (LoRA / Multi-LoRA Stack, and sweep cells), the merge counts tokens and, when prompt + triggers would overflow, shortens the prompt body (sentences just before the last one go first) so the triggers are never the part that is cut. A trigger only counts as already present on a whole-word match (rustis not inrusted). - VRAM on model switches (Oct 2026). LoRA / LoRA-stack / Unload-LoRA outputs and older loader outputs kept in ComfyUI's cache used to pin the previous model, and a reference cycle kept a released pipeline alive until the next model was already loading - both caused out-of-memory on checkpoint switches (48 GB cards). Fixed; if a released pipeline ever survives, the loader logs who still references it.
- LoKr files from ai-toolkit (Oct 2026). Krea 2 LoKr / LoHa LoRAs saved with the
original model's key names (
diffusion_model.blocks.N.attn.wq...) used to load with 0 modules applied, so the LoRA silently did nothing. They are now remapped, injected with the file's own Kronecker factor, and scaled by ComfyUI's LoKr rule (full w1/w2 = strength). - Text encoder offload. For style and edit runs on cards under 64 GB with guidance off, the prompt is encoded once and the Qwen3-VL encoder parks on the CPU for the run (restored after).
- Presets and your own files. Each node's preset dropdown reads
<section>_presets.jsonin the pack folder (loader_,lora_,ultra_,sigmas_,sweep_,cond_). On first start the pack creates any missing file from the shipped starters indefaults/- the ★ sigma curves EXP1-EXP7 and the OPT set, and two loader examples - and never overwrites a file that exists. The loader examples use placeholder paths: select one, pointbase_pipeline_pathat your Krea 2 Turbo diffusers folder (andtransformer_pathat a fine-tune file, or leave it blank for the base), then ★ Save Preset under your own name. Your sigma, sweep and loader preset files are yours: they are not tracked by git, so updating the pack never touches them.
Credits & licenses
- Krea 2 by Krea AI - weights under the Krea 2 Community License. https://github.com/krea-ai/krea-2
- Upscale VAE: spacepxl/Wan2.1-VAE-upscale2x (Apache-2.0). https://huggingface.co/spacepxl/Wan2.1-VAE-upscale2x
- Samplers: the RES and DEIS solvers are independent re-implementations of the published algorithms - RES (arXiv:2308.02157) and DEIS (arXiv:2204.13902) - specialised to rectified flow. Sampler/schedule choices were informed by the RES4LYF community; no RES4LYF or k-diffusion code is imported.
- Vision Prompt: informed by ethanfel/ComfyUI-Krea2TextEncoder,
which first identified that Krea2's Qwen3-VL text encoder can be vision-grounded
and that the community pattern of reusing
TextEncodeQwenImageEditPlusfor this wastes a silently-discarded reference latent and uses the wrong prompt template. This is an independent implementation built directly against the installed diffusers/transformers source, not a port of that node's code. - Reference Latents (edit): the "index_timestep_zero" reference method is credited
to ostris / ai-toolkit (the Krea2 edit-LoRA training recipe) and
ostris/ComfyUI-Krea2-Ostris-Edit for the ComfyUI-core
implementation. This is an independent diffusers-side reimplementation verified
line-by-line against the installed
transformer_krea2.py, not a port. - Control-LoRA: mechanism from Tanmay Patil's
Krea-2-controlnet reference pipeline
(weights
Patil/Krea-2-depth-controlnet) and the facok/comfyui-krea2-controlnet port; reimplemented for the diffusers transformer. - Style Reference: mechanism ported from nkxx188/ComfyUI-Krea2-StyleTransfer (MIT, (c) 2026 jieg9341-lab).
- Inpaint / outpaint: yijunwang2's Krea 2 AnyPaint / Outpaint functional adapters (pipeline code Apache-2.0); isolated kv_cache reference attention: ostris / ai-toolkit.
- Edits: lbouaraba/comfyui-krea2edit v1.2.5 and krea2edit-trainer (Apache-2.0) - the fit geometry and ref_boost are ported; weights conradlocke/krea2-identity-edit (Krea 2 Community License).
- NAG: Normalized Attention Guidance by Dar-Yen Chen (ChenDarYen/ComfyUI-NAG, MIT); Krea 2 placement after iljung1106/ComfyUI-Krea2-NAG (MIT).
- NegPiP: the idea is hako-mikan's sd-webui-negpip; this is a clean reimplementation - no code from the AGPL Krea 2 NegPiP port was used.
- DeGrid: notch-filter core ported from lunaaispace-eng/ComfyUI-DeGrid (Apache-2.0).
- Native quantized compute / kitchen formats: ComfyUI's
comfy_kitchenkernels and layouts. - Nodes: Eric Hiss (GitHub: EricRollei).
These nodes are an independent implementation; no code is copied from Krea or spacepxl repos. Where a mechanism was ported from a permissively licensed project (Apache-2.0 / MIT, listed above), the module header carries the attribution.