
comfyui_hyperflow_int8_nodes
Unofficial ComfyUI loader for HyperFlow H3 Flash INT8 checkpoints (fl2va and ref2va) on ComfyUI's native INT8 convrot kernels. Needs the official ComfyUI-HyperFlow-Flash pack.
Nodes (1)
comfyui_hyperflow_int8_nodes
Run HyperFlow H3 Flash in ComfyUI on ComfyUI's own INT8 kernels: text, image and reference to video with synchronized stereo audio, in 6 steps. Weights: BennyDaBall/HyperFlow-H3-Flash-INT8-ComfyUI.
Speed
One RTX 5090, 1344 x 768, 124 frames (5.2 s) with audio, 6 steps, mean of 5 seeds, queue to saved MP4:
| Setup | Time per clip | vs stock H3 |
|---|---:|---:|
| This pack + the INT8 checkpoints | 46.1 s | 3.0x faster |
| This pack + ComfyUI's Model Sparse Attention node | about 38 s | 3.7x faster |
| Official HyperFlow Q4_K_M GGUF + official nodes | 66.0 s | 2.1x faster |
| Stock MiniMax H3, 20 steps | 139.1 s | 1x |
Video Rebirth publishes 99 s for the official Q4_K_M GGUF setup on an RTX 5090. Peak VRAM with this pack was 24.2 GB.
What you get
- HyperFlow INT8 Loader, a ComfyUI node that runs both HyperFlow checkpoints:
fl2va(text, first frame, first and last frame) andref2va(reference images). - The converted INT8 checkpoints on Hugging Face, ready for
ComfyUI/models/diffusion_models/. - Five ready-to-run workflows in
example_workflows/, also under Workflow > Browse Templates: text to video, text to video with sparse attention, first frame, first and last frame, and reference to video.
Quick start
- Install this pack and the official ComfyUI-HyperFlow-Flash pack (see Install).
- Download a checkpoint from Hugging Face plus the text encoder and VAEs from Comfy-Org/MiniMax-H3 (see Model files).
- Open a template from Workflow > Browse Templates and queue it.
Examples
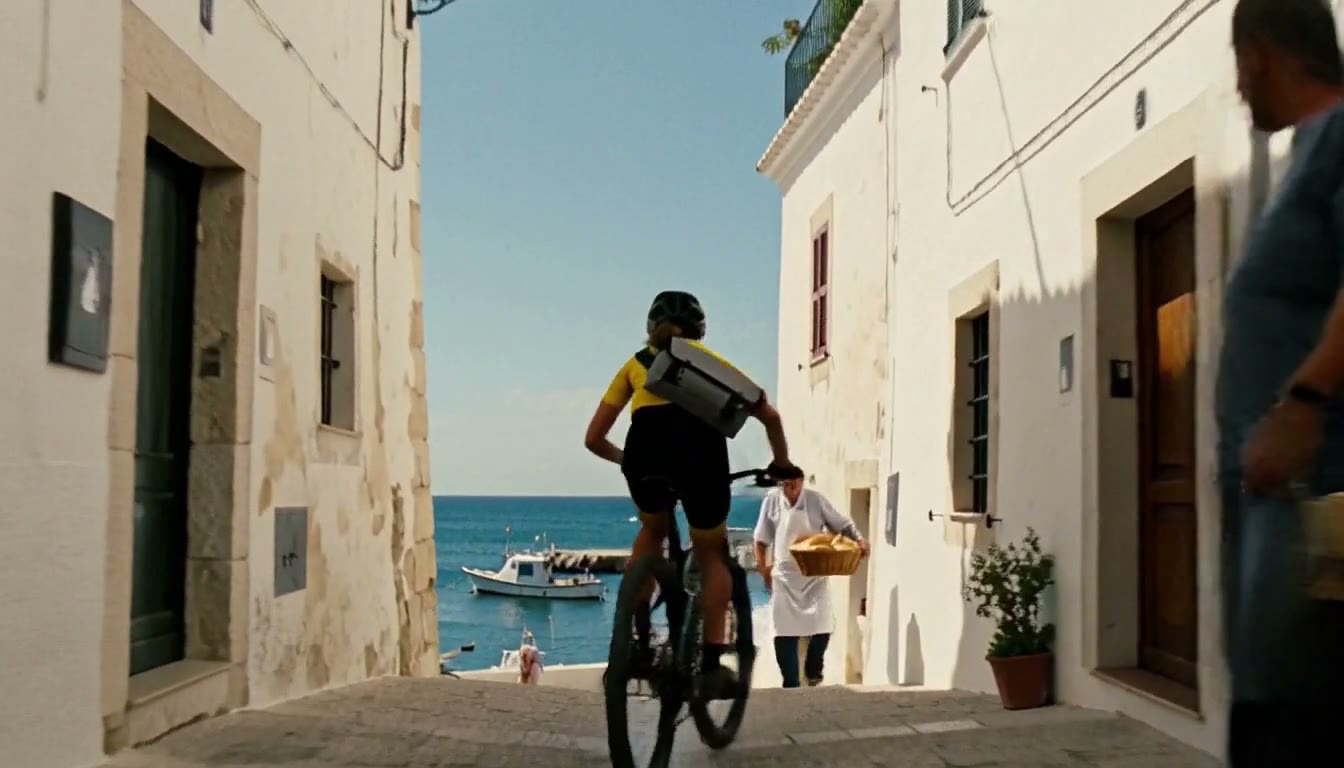
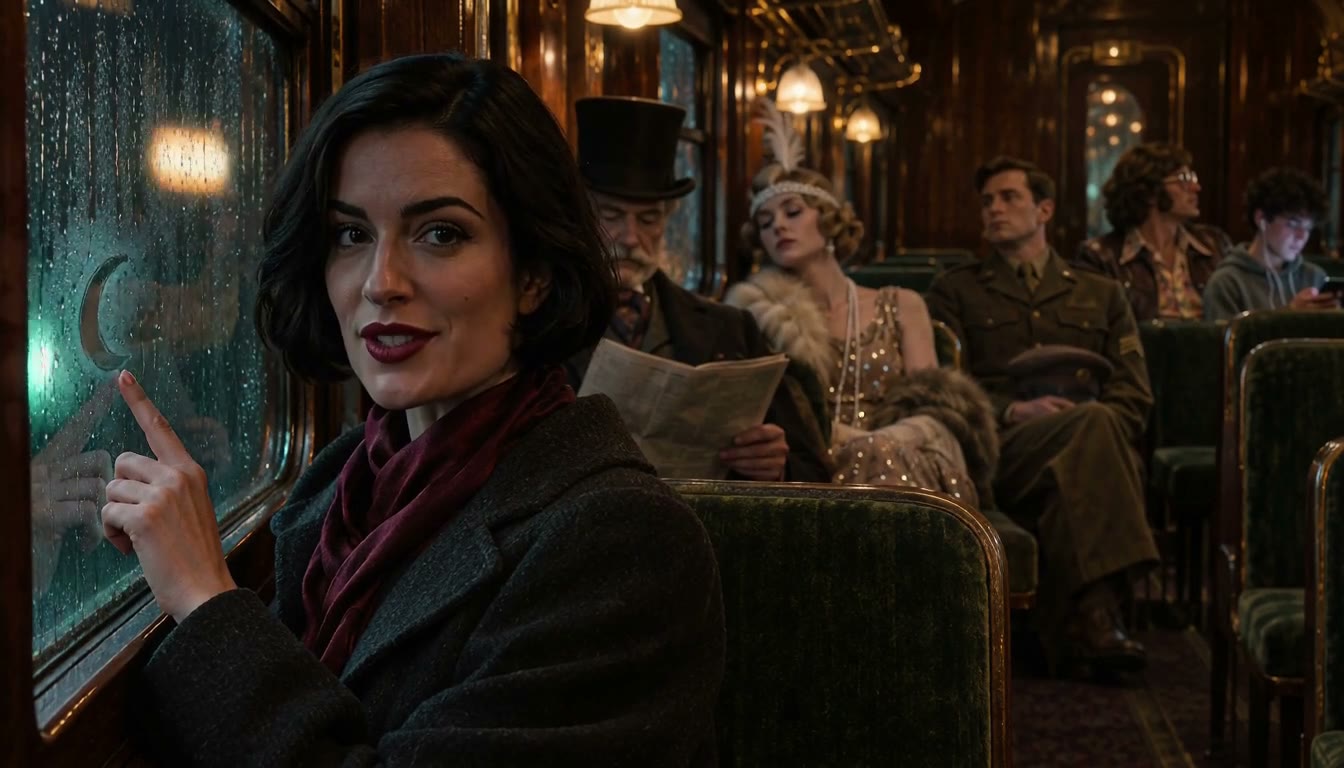
AI-generated with this pack and the INT8 checkpoints, one run each, seed 42. Click for the video on Hugging Face.
Text to video (fl2va, 10 s)
First frame to video (fl2va, 10 s): a night train full of passengers from different eras
Reference to video (ref2va): a character, a scooter and a harbor square into one shot
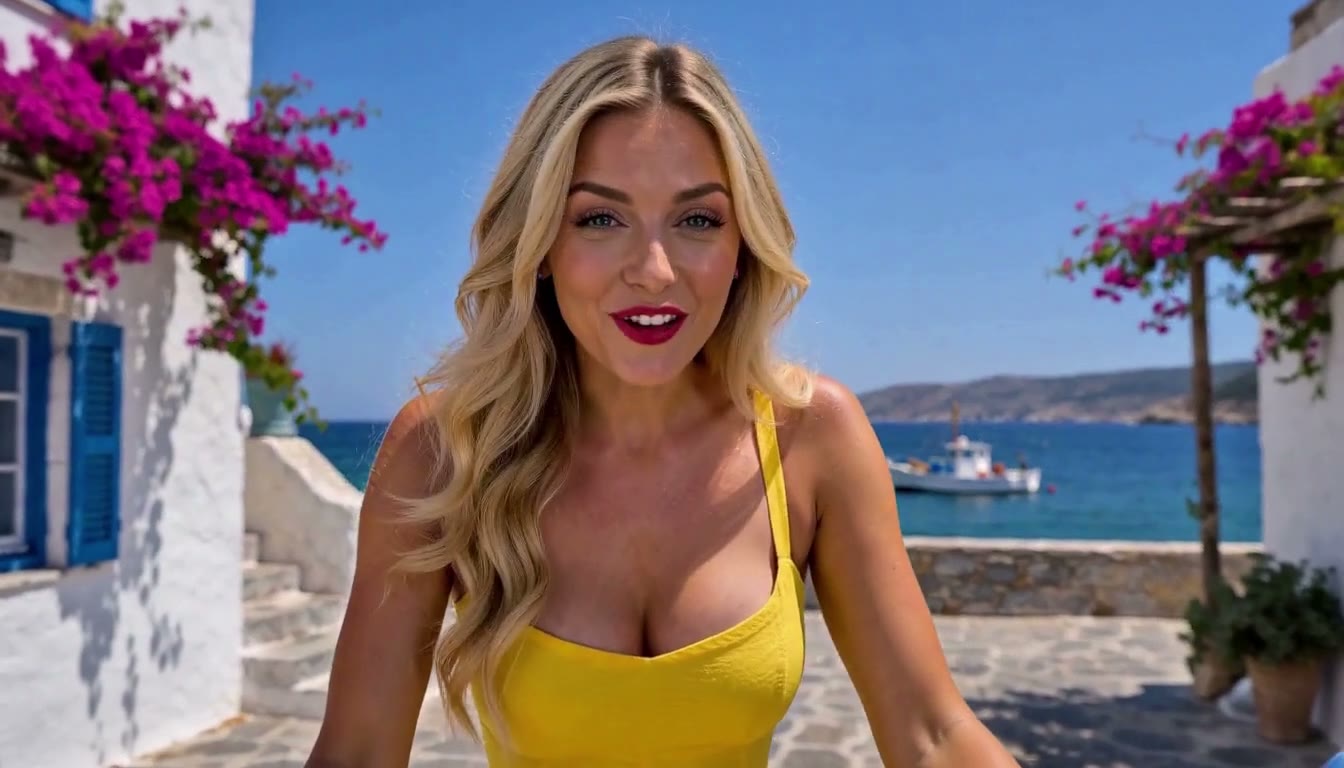
Prompts and reference images are on the model page.
Requirements
- A ComfyUI build with native MiniMax-H3 support and the
int8_tensorwise+convrotquantized ops (the comfy_kitchen INT8 kernels, torch cu130). - The official ComfyUI-HyperFlow-Flash pack, installed
next to this one. This pack imports its
model_patch.py, and the templates use itsHyperFlow Sigmasnode. - About 16 GB of VRAM for the weights, which stay resident, plus activations. Peak VRAM was 24.2 GB at 1344 x 768, 124 frames on an RTX 5090.
Install
ComfyUI-Manager and the Comfy registry
Install from ComfyUI-Manager (search for HyperFlow INT8) or with:
comfy node install comfyui-hyperflow-int8-nodes
Install the official ComfyUI-HyperFlow-Flash pack the
same way (comfyui-hyperflow-flash), then restart ComfyUI.
git clone
cd ComfyUI/custom_nodes
git clone https://github.com/Video-Rebirth/ComfyUI-HyperFlow-Flash
git clone https://github.com/BennyDaBall930/comfyui_hyperflow_int8_nodes
pip install -r ComfyUI-HyperFlow-Flash/requirements.txt
Use the python of your ComfyUI install for pip, then restart ComfyUI.
Model files
| Folder in ComfyUI/models/ | File | Download |
|---|---|---|
| diffusion_models/ | minimax_h3_fl2va_hyperflow_flash_int8_convrot.safetensors (15.9 GB) | BennyDaBall/HyperFlow-H3-Flash-INT8-ComfyUI |
| diffusion_models/ | minimax_h3_ref2va_hyperflow_flash_int8_convrot.safetensors (16.3 GB) | BennyDaBall/HyperFlow-H3-Flash-INT8-ComfyUI |
| text_encoders/ | qwen3vl_32b_minimax_h3_nvfp4_awq.safetensors | Comfy-Org/MiniMax-H3 |
| vae/ | minimax_h3_video_vae_fp16.safetensors, minimax_h3_audio_vae_fp32.safetensors | Comfy-Org/MiniMax-H3 |
fl2va covers text, first frame, and first and last frame to video. ref2va covers reference images to video. You
only need the variant you use.
hf download BennyDaBall/HyperFlow-H3-Flash-INT8-ComfyUI minimax_h3_fl2va_hyperflow_flash_int8_convrot.safetensors \
  --local-dir ComfyUI/models/diffusion_models
Usage
Open a template from Workflow > Browse Templates, under this pack's folder name (comfyui_hyperflow_int8_nodes
after a git clone). The templates are the official HyperFlow templates with the GGUF loader replaced by
HyperFlow INT8 Loader:
| Template | Task | Model file |
|---|---|---|
| hyperflow_int8_t2v | text to video | fl2va |
| hyperflow_int8_t2v_sparse | text to video with ComfyUI's Model Sparse Attention node | fl2va |
| hyperflow_int8_i2v | first frame to video | fl2va |
| hyperflow_int8_flf2v | first and last frame to video | fl2va |
| hyperflow_int8_ref2v | reference images to video | ref2va |
API-format versions are in the model repo
under workflows/api/. Apart from the loader, the sampling settings match the official
templates: HyperFlow Sigmas (4, 6 or 8 steps, 6 by default), euler, CFG 1, no negative prompt, 1344 x 768. The
two text-to-video templates default to 243 frames (10.1 s at 24 fps); the others default to 124 frames (5.2 s).
To switch an existing API-format graph to this loader, replace its model loader node:
"1": {
  "class_type": "HyperFlowINT8Loader",
  "inputs": {
    "unet_name": "minimax_h3_fl2va_hyperflow_flash_int8_convrot.safetensors",
    "patcher": "legacy"
  }
}
Loader inputs
| Input | Values | Notes |
|---|---|---|
| unet_name | any .safetensors in diffusion_models or unet | a converted file; the loader reads the variant, block count and low-rank layout from it |
| patcher | legacy (default, recommended), auto (experimental) | legacy is the classic ModelPatcher, as the official GGUF loader uses. auto is what UNETLoader gets (DynamicVRAM when ComfyUI enables it). On an RTX 5090, auto held VRAM at the card limit and slowed down across consecutive runs. |
Sparse attention
hyperflow_int8_t2v_sparse places ComfyUI's core Model Sparse Attention node between the loader and the guider:
method sol-attn, tau 1.25, start_percent 0.39, end_percent 1.0, dense blocks 0, 1, 45, 46. Bypass the node
(Ctrl+B) to run dense attention.
How it works
HyperFlow H3 Flash ships its own INT8 transformers (fl2va_int8_convrot/ and ref2va_int8_convrot/ in
VideoRebirthAI/hyperflow-h3-flash). They are W8A8 with a
rotated input, the same scheme as ComfyUI's native int8_tensorwise + convrot. This pack converts them once to
ComfyUI's MiniMax-H3 layout, copying the INT8 codes and scales bit for bit, and loads the result on ComfyUI's own
INT8 kernels.
The pack is the HyperFlow INT8 Loader node (loader.py) and five workflow templates in example_workflows/.
| Piece | Source |
|---|---|
| Model detection, MiniMax-H3 blocks, INT8 weight loading and GEMMs, attention, sampler | ComfyUI core, unchanged |
| Low-rank linears, split q/k/v, SwiGLU MLP for low-rank blocks, two-time (t, r) embedder | Official ComfyUI-HyperFlow-Flash/model_patch.py, imported unchanged |
| 4, 6 or 8-step schedule | Official HyperFlow Sigmas node |
| HyperFlow INT8 Loader node | This pack (loader.py) |
| The converted checkpoints | Hugging Face, converted once from Video Rebirth's INT8 files |
The stock MiniMax-H3 forward has no input for HyperFlow's step endpoint r, so the stock UNETLoader cannot run
these checkpoints on its own.
Memory
The weights stay resident in VRAM:
| Part | Size |
|---|---|
| INT8 linears | 11.6 GB |
| Low-rank factors, bf16 | 2.6 GB (fl2va) or 3.0 GB (ref2va) |
| Text refiner, bf16 | 1.5 GB |
Per token, the block linears cost 11.6 G INT8 MACs plus 1.3 G (fl2va) or 1.5 G (ref2va) bf16 MACs. The stock
50-block dense INT8 MiniMax-H3 costs 19.3 G INT8 MACs.
The checkpoints
The files on Hugging Face are Video Rebirth's own INT8 checkpoints in ComfyUI's layout. The INT8 codes and scales are copied bit for bit, so nothing is requantized: tensors are renamed, the dropped blocks are left out, q/k/v are fused and the low-rank factors stay bf16. Every INT8 module and low-rank pair is bit-identical to the source, and every unquantized tensor is bit-exact against the official Q8_0 GGUF; the model page has the full receipts.
Credits
- Video Rebirth for HyperFlow H3 Flash, its INT8 checkpoints and the
official ComfyUI-HyperFlow-Flash pack, whose
model_patch.pythis pack imports. - MiniMax for MiniMax H3, the base model.
- ComfyUI and Comfy Org for native MiniMax-H3 support, the INT8
convrotops and kernels, the Model Sparse Attention node, and the Comfy-Org/MiniMax-H3 text encoder and VAE files.
License
This project is not affiliated with Video Rebirth, MiniMax or Comfy Org.
- Code: GPL-3.0 (see
LICENSE), because it imports the GPL-3.0 ComfyUI-HyperFlow-Flash pack. - Weights: not included in this repository. HyperFlow H3 Flash and its conversions are Model Derivatives of MiniMax H3 under the MiniMax H3 Community License Agreement. That agreement restricts territory (the EU, UK, South Korea and the US need prior authorization from MiniMax) and requires AI-generated content to be disclosed as such.
Powered by MiniMax H3.