
ComfyUI-TRELLIS2-HiCache
Training-free TRELLIS.2 image-to-3D acceleration: forecast the flow-matching velocity on skipped DiT steps (HiCache Hermite / HiCache++ DMD, via hicache-pp) across the sparse-structure and shape-SLaT stages (texture optional). ~2x faster, near-lossless. Pairs with visualbruno/ComfyUI-Trellis2.
ComfyUI-TRELLIS2-HiCache
<p> <a href="https://github.com/Archerkattri/ComfyUI-TRELLIS2-HiCache/releases"><img alt="Release" src="https://img.shields.io/github/v/release/Archerkattri/ComfyUI-TRELLIS2-HiCache?color=1f6feb"></a> <a href="https://registry.comfy.org/nodes/comfyui-trellis2-hicache"><img alt="Comfy installs" src="https://img.shields.io/badge/dynamic/json?url=https%3A%2F%2Fapi.comfy.org%2Fnodes%2Fcomfyui-trellis2-hicache&query=%24.downloads&label=comfy%20installs&color=4b8bbe"></a> <a href="https://registry.comfy.org/publishers/archerkattri/nodes/comfyui-trellis2-hicache"><img alt="Comfy Registry" src="https://img.shields.io/badge/Comfy%20Registry-comfyui--trellis2--hicache-4b8bbe"></a> <a href="LICENSE"><img alt="License" src="https://img.shields.io/github/license/Archerkattri/ComfyUI-TRELLIS2-HiCache?color=0d9488"></a> </p>Training-free acceleration for TRELLIS.2 image-to-3D in ComfyUI. It forecasts
the flow-matching velocity on skipped DiT steps instead of running the
transformer, across TRELLIS.2's sparse-structure and shape-SLaT stages (texture
stage optional), via the hicache-pp
library.
Pairs with visualbruno/ComfyUI-Trellis2
(the TRELLIS2PIPELINE type). The TRELLIS v1 sibling is
ComfyUI-TRELLIS-HiCache.
Runtime path
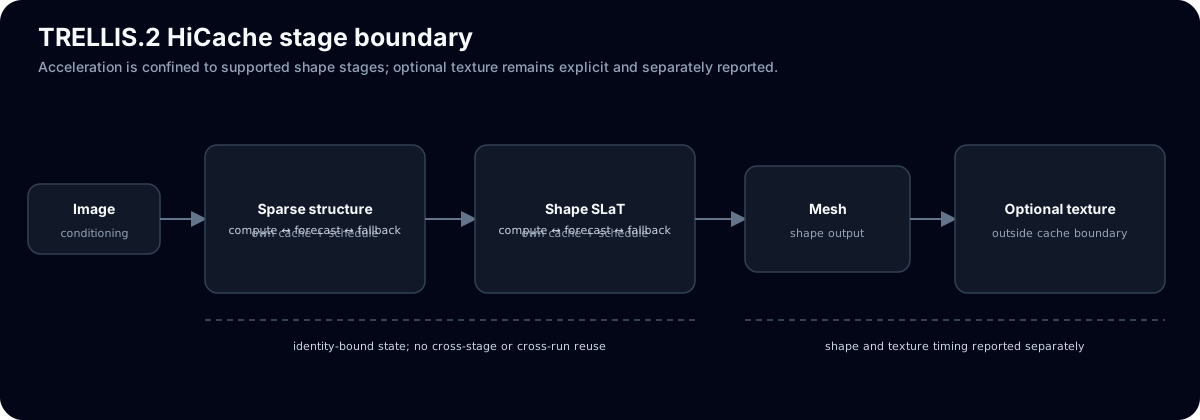
TRELLIS.2 shape stages keep separate schedule and cache identities. Unsupported texture paths remain outside the accelerated boundary and are reported explicitly.
What it does
TRELLIS.2 samples each stage with a flow-Euler loop that calls a DiT once (or twice, under classifier-free guidance) per step. TRELLIS.2 HiCache Accelerate replaces the flow DiTs with a wrapper that runs the transformer on a schedule and forecasts the velocity on the steps in between:
hermite-- HiCache (dual-scaled physicist's Hermite polynomial, arXiv:2508.16984).dmd-- HiCache++ (Dynamic Mode Decomposition / Prony exponential basis).auto-- holdout-selected per step.
TRELLIS.2 has five flow DiTs (sparse_structure, shape_slat at 512/1024,
tex_slat at 512/1024); stages selects which to accelerate (both = shape
generation, the default; all adds texture). Two TRELLIS-specific details are
handled correctly: the timestep schedule runs 1 -> 0 (run boundaries are
detected by direction reversal, not a fixed threshold), and classifier-free
guidance issues the conditional and unconditional forwards separately inside a
guidance interval, so the patch keeps two parallel forecast states. The SLaT
stages return sparse tensors whose active-voxel layout is fixed during a run, so
the forecast runs on .feats and the sparse tensor is rebuilt from the last
computed step.
Historical measured result (not reproduced by this CPU gate)
The following table is README-reported evidence from an earlier RTX 5090 run; it is not a current-commit or release claim. Re-run the GPU gate below with a fixed input, seed, checkpoint, and synchronized timing before using these figures.
Setup: TRELLIS.2-4B, 512 pipeline, interval=2, shape stages.
| metric | value | |---|---| | speedup | 1.9x | | Chamfer vs stock (mesh verts) | 0.0107 (near-lossless) | | SS / shape-SLaT skips | 9 / 9 of ~22 DiT calls each |
interval=2 is the default. Chamfer is the symmetric mean nearest-neighbour
distance between the stock and accelerated mesh vertices; higher intervals trade
fidelity for more speed.
Install
cd ComfyUI/custom_nodes
git clone https://github.com/Archerkattri/ComfyUI-TRELLIS2-HiCache
pip install "hicache-pp>=1.2.1"
Use
(TRELLIS2 loader) -> TRELLIS.2 HiCache Accelerate -> (TRELLIS2 sampler)
Set enabled = Off to bypass and restore the stock DiTs. The node never mutates
the pipeline it is given (copy-on-patch).
First-result acceptance checklist
Use a fixed input and record the visualbruno wrapper, checkpoint, resolution, node commit, seed, method, interval, stages, and torch/CUDA versions. Treat a run as accepted only after these checks:
- Run a baseline with
enabled = Offand retain the stock output and forward counts. - Run the same input and seed with acceleration enabled. Inspect each selected
model patch's
run_id,stage_id, latestbranch_id, and detachedtelemetryfor actual full/forecast, method, and fallback counts. Integrations that know job/CFG identity may passhicache_run_idandhicache_branch_id; those markers are consumed before the DiT call. - Cover 512, 1024/cascade, shape-only, both stages, and texture separately. For every SLaT/texture path, confirm skipped outputs remain sparse tensors with their expected active layout.
- Exercise a fresh run (including cancellation/retry) with the same initial timestep and a new run ID; confirm a first full decision and no reused state, template, or texture branch.
- Compare baseline and accelerated outputs and retain raw per-run telemetry. GPU timing/quality and a clean visualbruno workflow import are separate gates; this CPU package check makes no speed or quality claim.
Validation
tests/test_patch.py unit-tests the patch logic with a dummy DiT (no ComfyUI, no
GPU). tests/validate_gpu.py is the future end-to-end GPU check (loads a real
TRELLIS.2-4B pipeline, applies the patch, compares geometry and wall-clock
against stock); it is not run by this CPU packet. No accepted visualbruno
workflow JSON/template is present in the checkout, so an invented graph is not
included.
Apache-2.0.
Current release status
The current adapter includes the shared HiCache++ runtime bridge, explicit cache identity, timing and fallback accounting. Its CPU contract suite passes 22 tests. Real TRELLIS2 model/CUDA workflow and output-quality comparisons remain unmeasured.